試験の準備方法-検証するCertified-Data-Engineer-Professional試験番号試験-正確的なCertified-Data-Engineer-Professional復習内容

なぜみんなが順調にDatabricksのCertified-Data-Engineer-Professional試験に合格できることに対する好奇心がありますか。DatabricksのCertified-Data-Engineer-Professional試験に合格したいんですか。実は、彼らが試験に合格したコツは我々JPNTestの提供するDatabricksのCertified-Data-Engineer-Professional試験ソフトを利用したんです。豊富の問題集、専門的な研究と購入の後の一年間の無料更新、ソフトで復習して、自分の能力の高めを感じられます。DatabricksのCertified-Data-Engineer-Professional試験に合格することができます。
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Analyze errors and remediate failed job runs
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
|
| Topic 2: Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Use Change Data Feed to address streaming table limitations and improve latency
- 3. Understand deletion vectors and liquid clustering
|
| Topic 3: Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
|
| Topic 4: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- Building and Testing ETL Pipelines
- 1. Develop unit and integration tests for data processing code
- 2. Configure environments, dependencies, memory, and retry behavior
- 3. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 4. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 5. Compare streaming tables and materialized views
- 6. Use APPLY CHANGES APIs for change data capture
- 7. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 8. Use control flow operators in pipeline components
|
| Topic 5: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest data from message buses and cloud storage
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Topic 6: Monitoring and Alerting | - Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
- Monitoring
- 1. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 2. Use system tables for resource, cost, audit, and workload monitoring
- 3. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 4. Use Query Profiler and Spark UI to monitor workloads
|
| Topic 7: Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Understand Liquid Clustering versus partitioning and Z-Ordering
- 2. Design and implement scalable data models using Delta Lake
- 3. Optimize data layout using Liquid Clustering
|
| Topic 8: Ensuring Data Security and Compliance | - Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use row filters and column masks for sensitive data
- 3. Use ACLs to secure workspace objects and enforce least privilege
- Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
|
| Topic 9: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure Databricks-to-Databricks Sharing
- 3. Configure sharing with external platforms using the open sharing protocol
|
| Topic 10: Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
>> Certified-Data-Engineer-Professional試験番号 <<
Certified-Data-Engineer-Professional復習内容 & Certified-Data-Engineer-Professional問題数
DatabricksのCertified-Data-Engineer-Professional認定試験に合格するのは簡単なことではありませんか。JPNTestのDatabricksのCertified-Data-Engineer-Professional試験トレーニング資料を選ぶなら、一回で認定試験に合格するの可能性は高いです。JPNTestのDatabricksのCertified-Data-Engineer-Professional試験トレーニング資料は豊富な経験を持っているIT業種の専門家が長年の研究を通じて、作成したものです。その権威性が高いと言えます。JPNTestを選ぶなら、絶対に後悔させません。
Databricks Certified Data Engineer Professional 認定 Certified-Data-Engineer-Professional 試験問題 (Q163-Q168):
質問 # 163
A data engineer is using the AUTO CDC API in Lakeflow Spark Declarative Pipeline to propagate deletions from a source table (orders_source) to a target table (orders_target). The source has Change Data Feed (CDF) enabled, but some delete events arrive out of order due to upstream delays. How does the AUTO CDC API internally ensure deletions are applied correctly despite out-of-order events?
- A. It runs VACUUM on the target table to purge conflicting records.
- B. It ignores deletions if they arrive after updates for the same key.
- C. It uses sequence_by to order events and retains tombstones for deleted rows until older sequences are processed.
- D. It manually sorts incoming events by timestamp before applying changes.
正解:C
解説:
AUTO CDC uses the sequence_by column to deterministically order change events for each key.
Delete operations create tombstones that are retained until all earlier sequence values have been processed, ensuring that out-of-order delete events are still applied correctly and consistently in the target table.
質問 # 164
A Delta Lake table in the Lakehouse named customer_parsams is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
Immediately after each update succeeds, the data engineer team would like to determine the difference between the new version and the previous of the table. Given the current implementation, which method can be used?
- A. Execute a query to calculate the difference between the new version and the previous version using Delta Lake's built-in versioning and time travel functionality.
- B. Execute DESCRIBE HISTORY customer_churn_params to obtain the full operation metrics for the update, including a log of all records that have been added or modified.
- C. Parse the Delta Lake transaction log to identify all newly written data files.
- D. Parse the Spark event logs to identify those rows that were updated, inserted, or deleted.
正解:A
解説:
Delta Lake provides built-in versioning and time travel capabilities, allowing users to query previous snapshots of a table. This feature is particularly useful for understanding changes between different versions of the table. In this scenario, where the table is overwritten nightly, you can use Delta Lake's time travel feature to execute a query comparing the latest version of the table (the current state) with its previous version. This approach effectively identifies the differences (such as new, updated, or deleted records) between the two versions. The other options do not provide a straightforward or efficient way to directly compare different versions of a Delta Lake table.
質問 # 165
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block:
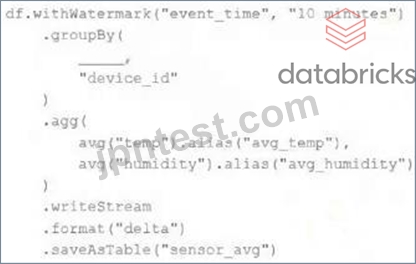
Choose the response that correctly fills in the blank within the code block to complete this task.
- A. window("event_time", "5 minutes").alias("time")
- B. to_interval("event_time", "5 minutes").alias("time")
- C. lag("event_time", "10 minutes").alias("time")
- D. window("event_time", "10 minutes").alias("time")
- E. "event_time"
正解:A
解説:
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1 second. In this case, the window duration is "5 minutes", which means each window will cover a non-overlapping five- minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window. The alias function is used to rename the struct column as "time".
質問 # 166
A data engineer is designing a system to process batch patient encounter data stored in an S3 bucket, creating a Delta table (patient_encounters) with columns encounter_id, patient_id, encounter_date, diagnosis_code, and treatment_cost. The table is queried frequently by patient_id and encounter_date, requiring fast performance. Fine-grained access controls must be enforced. The engineer wants to minimize maintenance and boost performance. How should the data engineer create the patient_encounters table?
- A. Create a managed table in Unity Catalog. Configure Unity Catalog permissions for access controls, and rely on predictive optimization to enhance query performance and simplify maintenance.
- B. Create a managed table in Unity Catalog. Configure Unity Catalog permissions for access controls, schedule jobs to run OPTIMIZE and VACUUM commands daily to achieve best performance.
- C. Create a managed table in Hive Metastore. Configure Hive Metastore permissions for access controls, and rely on predictive optimization to enhance query performance and simplify maintenance.
- D. Create an external table in Unity Catalog, specifying an S3 location for the data files. Enable predictive optimization through table properties, and configure Unity Catalog permissions for access controls.
正解:A
解説:
Databricks documentation specifies that Unity Catalog managed tables are the preferred choice for secure, low-maintenance Delta Lake architectures. Managed tables provide full lifecycle management, including metadata, file storage, and access control integration with Unity Catalog.
Fine-grained permissions can be enforced at the column and row level through built-in Unity Catalog governance.
Additionally, Predictive Optimization (Auto Optimize + Auto Compaction) automatically manages file sizes, metadata pruning, and layout optimization, eliminating the need for manual maintenance such as scheduling OPTIMIZE or VACUUM.
External tables (A) require manual path management, and Hive Metastore tables (D) do not support Unity Catalog access policies. Therefore, creating a managed Unity Catalog table with predictive optimization provides both the security and performance benefits needed, making B the correct solution.
質問 # 167
When monitoring a complex workload, being able to see the query plan is critical to understanding what the workload is doing. Where can the visualization of the query plan be found?
- A. In the Query Profiler, under Query Source
- B. In the Spark UI, under the SQL/DataFrame tab
- C. In the Query Profiler, under the Stages tab
- D. In the Spart UI, under the Jobs tab
正解:B
解説:
The Spark UI provides detailed visibility into how queries are executed. The SQL/DataFrame tab displays the logical and physical query plans, allowing engineers to visualize execution details and understand how the workload is processed across stages and operators.
質問 # 168
......
Databricks Certified-Data-Engineer-Professional資格認定はIT技術領域に従事する人に必要があります。我々社のDatabricks Certified-Data-Engineer-Professional試験練習問題はあなたに試験うま合格できるのを支援します。あなたの取得したDatabricks Certified-Data-Engineer-Professional資格認定は、仕事中に核心技術知識を同僚に認可されるし、あなたの技術信頼度を増強できます。
Certified-Data-Engineer-Professional復習内容: https://www.jpntest.com/shiken/Certified-Data-Engineer-Professional-mondaishu
- Databricks Certified-Data-Engineer-Professional認定試験に対する効率のあがる勉強法 💡 ウェブサイト“ www.xhs1991.com ”から{ Certified-Data-Engineer-Professional }を開いて検索し、無料でダウンロードしてくださいCertified-Data-Engineer-Professional模擬練習
- Certified-Data-Engineer-Professional試験番号|Databricks Certified Data Engineer Professional最適に合格 ⏏ 【 www.goshiken.com 】で使える無料オンライン版《 Certified-Data-Engineer-Professional 》 の試験問題Certified-Data-Engineer-Professional復習範囲
- Certified-Data-Engineer-Professional試験番号|Databricks Certified Data Engineer Professional最適に合格 🕧 ⮆ www.passtest.jp ⮄で⮆ Certified-Data-Engineer-Professional ⮄を検索して、無料でダウンロードしてくださいCertified-Data-Engineer-Professional模擬練習
- Certified-Data-Engineer-Professional資格講座 🎼 Certified-Data-Engineer-Professional赤本合格率 🦁 Certified-Data-Engineer-Professional赤本合格率 🍂 ☀ www.goshiken.com ️☀️で▶ Certified-Data-Engineer-Professional ◀を検索して、無料で簡単にダウンロードできますCertified-Data-Engineer-Professional復習範囲
- Certified-Data-Engineer-Professional復習範囲 🅰 Certified-Data-Engineer-Professional受験料過去問 🧳 Certified-Data-Engineer-Professional復習範囲 👓 検索するだけで➤ www.jpexam.com ⮘から⇛ Certified-Data-Engineer-Professional ⇚を無料でダウンロードCertified-Data-Engineer-Professional受験準備
- 試験の準備方法-効率的なCertified-Data-Engineer-Professional試験番号試験-ユニークなCertified-Data-Engineer-Professional復習内容 🎁 ⏩ Certified-Data-Engineer-Professional ⏪を無料でダウンロード“ www.goshiken.com ”で検索するだけCertified-Data-Engineer-Professional資格講座
- 素晴らしいCertified-Data-Engineer-Professional|権威のあるCertified-Data-Engineer-Professional試験番号試験|試験の準備方法Databricks Certified Data Engineer Professional復習内容 🔐 ➤ www.goshiken.com ⮘にて限定無料の▶ Certified-Data-Engineer-Professional ◀問題集をダウンロードせよCertified-Data-Engineer-Professionalシュミレーション問題集
- Certified-Data-Engineer-Professional試験概要 🥑 Certified-Data-Engineer-Professional受験料過去問 🥕 Certified-Data-Engineer-Professional受験料過去問 🌃 「 Certified-Data-Engineer-Professional 」の試験問題は“ www.goshiken.com ”で無料配信中Certified-Data-Engineer-Professional模擬練習
- Certified-Data-Engineer-Professional試験概要 🌻 Certified-Data-Engineer-Professional技術試験 📨 Certified-Data-Engineer-Professional復習過去問 🏟 “ www.xhs1991.com ”には無料の⏩ Certified-Data-Engineer-Professional ⏪問題集がありますCertified-Data-Engineer-Professional的中問題集
- Certified-Data-Engineer-Professional技術試験 📳 Certified-Data-Engineer-Professional模擬練習 💻 Certified-Data-Engineer-Professional模擬体験 🍾 最新⏩ Certified-Data-Engineer-Professional ⏪問題集ファイルは▛ www.goshiken.com ▟にて検索Certified-Data-Engineer-Professional受験資格
- 効果的なCertified-Data-Engineer-Professional試験番号試験-試験の準備方法-ユニークなCertified-Data-Engineer-Professional復習内容 👶 ⇛ www.shikenpass.com ⇚から簡単に☀ Certified-Data-Engineer-Professional ️☀️を無料でダウンロードできますCertified-Data-Engineer-Professional日本語版
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, telegra.ph, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes