権威のあるDP-700合格体験談 &合格スムーズDP-700出題内容 |検証するDP-700日本語版Implementing Data Engineering Solutions Using Microsoft Fabric

P.S.TopexamがGoogle Driveで共有している無料の2026 Microsoft DP-700ダンプ:https://drive.google.com/open?id=1TcE-rznm8up2HbGeWp1UNSQGXw0CqCL3
ユーザーに多くの不必要なトラブルを保存するために、オンライン学習プラットフォームのDP-700研究質問の研究と開発を完了しました。ユーザーはダウンロードしてインストールする必要はなく、デジタルデバイスにブラウザーがあれば必要です。 DP-700テストガイドのオンライン操作。この種の学習方法は、特にDP-700認定を取得するペースが速いときに、ユーザーにとって非常に便利です。 DP-700トレーニング資料を使用すると、DP-700学習資料のすべての操作を完全に適用できます。
Microsoft DP-700 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - 分析ソリューションの監視と最適化:このセクションでは、Microsoft Fabric の分析ソリューションのさまざまなコンポーネントを監視するデータアナリストのスキルを評価します。データの取り込み、変換プロセス、セマンティックモデルの更新を追跡し、エラー解決のためのアラートを設定することに重点が置かれます。評価対象となるスキルの一つは、分析ワークフローにおけるパフォーマンスのボトルネックを特定することです。
|
| トピック 2 | - データの取り込みと変換:このセクションでは、データエンジニアのスキル、特にデータ読み込みパターンの設計と実装能力を評価します。特に、多次元モデルへの読み込みのためのデータ準備、バッチおよびストリーミングデータの取り込み処理、そして様々な手法を用いたデータ変換能力に重点が置かれます。評価対象となるスキルの一つは、データ品質を確保するために適切な変換手法を適用することです。
|
| トピック 3 | - 分析ソリューションの実装と管理:このセクションでは、Microsoft Fabric における様々なワークスペース設定の構成に関する Microsoft データアナリストのスキルを評価します。Spark やドメインワークスペースの構成を含む Microsoft Fabric ワークスペースの設定、ライフサイクル管理とバージョン管理の実装に重点が置かれます。評価対象となるスキルの一つに、分析ソリューションのデプロイメントパイプラインの作成があります。
|
>> DP-700合格体験談 <<
DP-700試験の準備方法|検証するDP-700合格体験談試験|一番優秀なImplementing Data Engineering Solutions Using Microsoft Fabric出題内容
Topexamは多くの人に便利を与えるとともに、多くの人の夢が実現させるサイトでございます。もし君はまだIT試験で心配すれば、私達TopexamのDP-700問題集を選んでください。Topexamは長年の研究をわたって研ITの認証試験に関する品質が高く、範囲は広い教育資料が開発しました。それは確かに君のDP-700試験に役に立つとみられます。
Microsoft Implementing Data Engineering Solutions Using Microsoft Fabric 認定 DP-700 試験問題 (Q132-Q137):
質問 # 132
You need to recommend a solution to resolve the MAR1 connectivity issues. The solution must minimize development effort. What should you recommend?
- A. Configure Fault tolerance for the Copy data activity.
- B. Configure retries for the Copy data activity.
- C. Call a notebook from the data pipeline.
- D. Add a ForEach activity to the data pipeline.
正解:B
質問 # 133
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a KQL database that contains two tables named Stream and Reference. Stream contains streaming data in the following format.
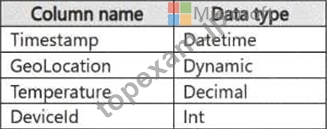
Reference contains reference data in the following format.
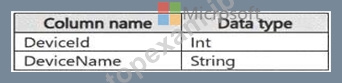
Both tables contain millions of rows.
You have the following KQL queryset.
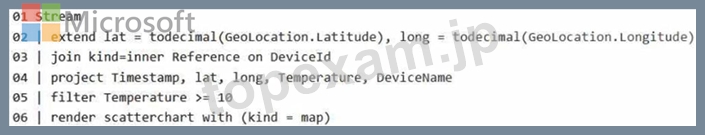
You need to reduce how long it takes to run the KQL queryset.
Solution: You change the join type to kind=outer.
Does this meet the goal?
正解:A
解説:
An outer join will include unmatched rows from both tables, increasing the dataset size and processing time.
It does not improve query performance.
質問 # 134
You have a Fabric notebook named Notebook1 that has been executing successfully for the last week.
During the last run, Notebook1executed nine jobs.
You need to view the jobs in a timeline chart.
What should you use?
- A. Real-Time hub
- B. Spark History Server
- C. the run series from the details of the application run
- D. Monitoring hub
- E. the job history from the application run
正解:B
解説:
The run series from the details of the application run is the most detailed and relevant feature for visualizing job execution in a timeline format, making it the correct choice for this scenario. It provides an intuitive way to analyze job execution patterns and improve the efficiency of the notebook.
質問 # 135
You plan to process the following three datasets by using Fabric:
* Dataset1: This dataset will be added to Fabric and will have a unique primary key between the source and the destination. The unique primary key will be an integer and will start from 1 and have an increment of 1.
* Dataset2: This dataset contains semi-structured data that uses bulk data transfer. The dataset must be handled in one process between the source and the destination. The data transformation process will include the use of custom visuals to understand and work with the dataset in development mode.
* Dataset3. This dataset is in a takehouse. The data will be bulk loaded. The data transformation process will include row-based windowing functions during the loading process.
You need to identify which type of item to use for the datasets. The solution must minimize development effort and use built-in functionality, when possible. What should you identify for each dataset? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
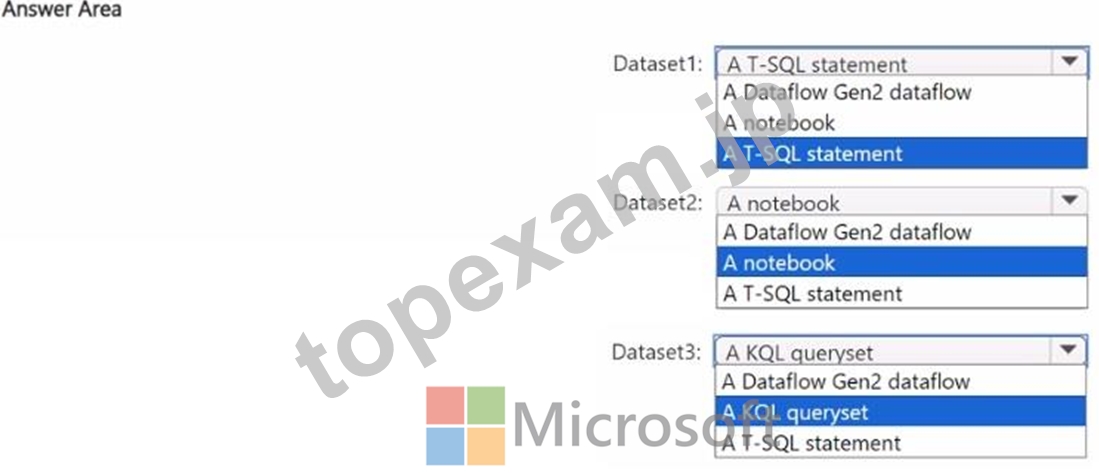
正解:
解説:
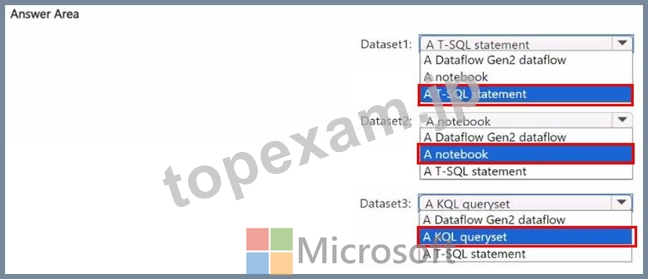
質問 # 136
You have Fabric workspace that contains eventhouse named Eventhouse1.
In Eventhouse1, you plan to create a table named EventStreamData in a KQL database. The table will contain data based on the following sample.
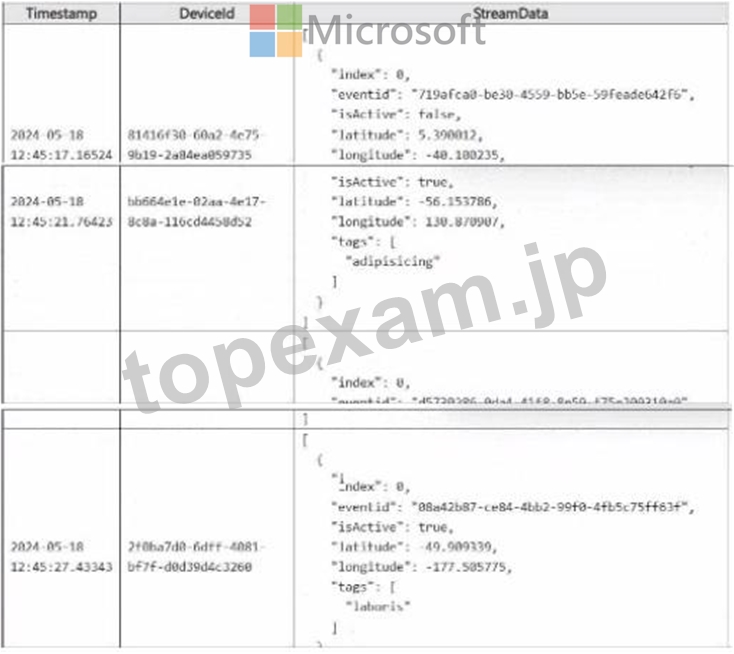
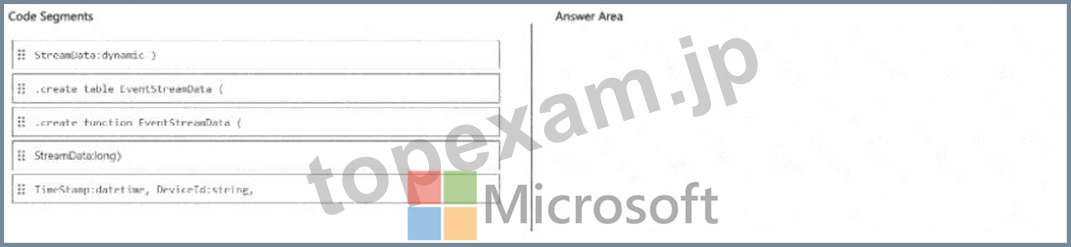
正解:
解説:
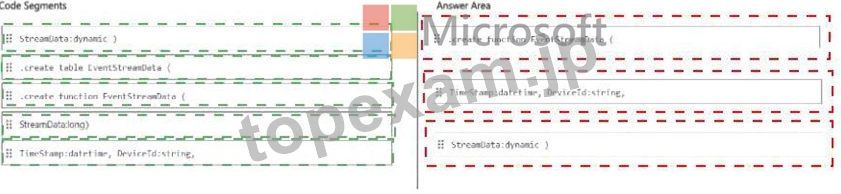
Explanation:
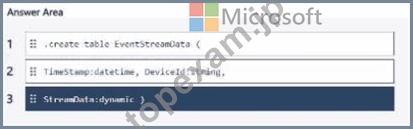
質問 # 137
......
MicrosoftのDP-700の試験の資料やほかのトレーニング資料を提供しているサイトがたくさんありますが、MicrosoftのDP-700の認証試験の高品質の資料を提供しているユニークなサイトはTopexamです。Topexamのガイダンスとヘルプを通して、初めにMicrosoftのDP-700「Implementing Data Engineering Solutions Using Microsoft Fabric」の認証を受けるあなたは、気楽に試験に合格すことができます。Topexamが提供した問題と解答は現代の活力がみなぎる情報技術専門家が豊富な知識と実践経験を活かして研究した成果で、あなたが将来IT分野でより高いレベルに達することに助けを差し上げます。
DP-700出題内容: https://www.topexam.jp/DP-700_shiken.html
- 真実的なDP-700合格体験談 - 合格スムーズDP-700出題内容 | 素敵なDP-700日本語版 🧷 ウェブサイト➠ www.passtest.jp 🠰を開き、➤ DP-700 ⮘を検索して無料でダウンロードしてくださいDP-700一発合格
- DP-700試験対策 👾 DP-700テスト難易度 🧄 DP-700受験対策解説集 👌 《 www.goshiken.com 》サイトにて最新【 DP-700 】問題集をダウンロードDP-700受験対策解説集
- Microsoft DP-700合格体験談: Implementing Data Engineering Solutions Using Microsoft Fabric - www.goshiken.com 有効なオファー 出題内容 🐞 [ www.goshiken.com ]にて限定無料の{ DP-700 }問題集をダウンロードせよDP-700テスト難易度
- 高品質DP-700合格体験談 - 資格試験のリーダー - コンプリートMicrosoft Implementing Data Engineering Solutions Using Microsoft Fabric 🛸 時間限定無料で使える▶ DP-700 ◀の試験問題は➡ www.goshiken.com ️⬅️サイトで検索DP-700受験練習参考書
- DP-700日本語独学書籍 🕋 DP-700模擬資料 ☣ DP-700最新資料 😲 ⮆ www.passtest.jp ⮄サイトにて▛ DP-700 ▟問題集を無料で使おうDP-700テスト模擬問題集
- DP-700最新対策問題 🧩 DP-700最新対策問題 ⛑ DP-700技術問題 💞 検索するだけで( www.goshiken.com )から▛ DP-700 ▟を無料でダウンロードDP-700資料的中率
- DP-700技術試験 😶 DP-700的中合格問題集 🌹 DP-700最新資料 🚵 《 www.mogiexam.com 》に移動し、{ DP-700 }を検索して無料でダウンロードしてくださいDP-700的中合格問題集
- Microsoft DP-700合格体験談: Implementing Data Engineering Solutions Using Microsoft Fabric - GoShiken 有効なオファー 出題内容 🗯 { www.goshiken.com }は、▛ DP-700 ▟を無料でダウンロードするのに最適なサイトですDP-700的中合格問題集
- 真実的なDP-700合格体験談 - 合格スムーズDP-700出題内容 | 素敵なDP-700日本語版 🧘 [ DP-700 ]の試験問題は《 www.xhs1991.com 》で無料配信中DP-700日本語版復習資料
- 完璧なDP-700合格体験談 | 素晴らしい合格率のDP-700 Exam | ハイパスレートDP-700: Implementing Data Engineering Solutions Using Microsoft Fabric 💌 “ DP-700 ”の試験問題は「 www.goshiken.com 」で無料配信中DP-700関連問題資料
- DP-700試験対応 🎢 DP-700関連資格知識 🍟 DP-700試験対応 🚍 「 www.passtest.jp 」で使える無料オンライン版“ DP-700 ” の試験問題DP-700一発合格
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, scalar.usc.edu, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, kumu.io, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. TopexamがGoogle Driveで共有している無料かつ新しいDP-700ダンプ:https://drive.google.com/open?id=1TcE-rznm8up2HbGeWp1UNSQGXw0CqCL3