P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Pass4suresVCE: https://drive.google.com/open?id=1mbHdKWYpfR238t9LoIrzzg-a60Wb8Cp-
our experts have rewritten the textbooks according to the exam outline of Databricks-Generative-AI-Engineer-Associate, and have gathered all the key difficulties and made key notes, so that you can review them in a centralized manner. Experts also conducted authoritative interpretations of all incomprehensible knowledge points through examples and other methods. The expressions used in Databricks-Generative-AI-Engineer-Associate Learning Materials are very easy to understand. Even if you are an industry rookie, you can understand professional knowledge very easily. The Databricks-Generative-AI-Engineer-Associate training torrent will be the best study guide for you to obtain your certification.
| Section | Weight | Objectives |
|---|---|---|
| Design Applications | 14% | - Define functional requirements - Select appropriate models - Design and architect applications |
| Assembling and Deploying Apps | 22% | - Build and deploy RAG pipelines - Package and deploy models - Use Vector Search |
| Data Preparation | 14% | - Manage data quality and chunking - Prepare data for RAG applications |
| Evaluation and Monitoring | 12% | - Evaluate model quality and performance - Monitor deployed applications |
| Application Development | 30% | - Implement prompt engineering - Integrate Databricks tools (LangChain, etc.) - Develop LLM chains |
| Governance | 8% | - Manage permissions and logging - Apply safety filters and guidelines |
>> Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions Answers <<
If you are determined to get the certification, our Databricks-Generative-AI-Engineer-Associate question torrent is willing to give you a hand; because the study materials from our company will be the best study tool for you to get the certification. Now I am going to introduce our Databricks-Generative-AI-Engineer-Associate Exam Question to you in detail, please read our introduction carefully, we can make sure that you will benefit a lot from it. If you are interest in it, you can buy it right now.
NEW QUESTION # 56
A Generative AI Engineer is building a RAG application that will rely on context retrieved from source documents that are currently in PDF format. These PDFs can contain both text and images. They want to develop a solution using the least amount of lines of code.
Which Python package should be used to extract the text from the source documents?
Answer: D
Explanation:
* Problem Context: The engineer needs to extract text from PDF documents, which may contain both text and images. The goal is to find a Python package that simplifies this task using the least amount of code.
* Explanation of Options:
* Option A: flask: Flask is a web framework for Python, not suitable for processing or extracting content from PDFs.
* Option B: beautifulsoup: Beautiful Soup is designed for parsing HTML and XML documents, not PDFs.
* Option C: unstructured: This Python package is specifically designed to work with unstructured data, including extracting text from PDFs. It provides functionalities to handle various types of content in documents with minimal coding, making it ideal for the task.
* Option D: numpy: Numpy is a powerful library for numerical computing in Python and does not provide any tools for text extraction from PDFs.
Given the requirement,Option C(unstructured) is the most appropriate as it directly addresses the need to efficiently extract text from PDF documents with minimal code.
NEW QUESTION # 57
A Generative Al Engineer is helping a cinema extend its website's chat bot to be able to respond to questions about specific showtimes for movies currently playing at their local theater. They already have the location of the user provided by location services to their agent, and a Delta table which is continually updated with the latest showtime information by location. They want to implement this new capability In their RAG application.
Which option will do this with the least effort and in the most performant way?
Answer: A
Explanation:
The task is to extend a cinema chatbot to provide movie showtime information using a RAG application, leveraging user location and a continuously updated Delta table, with minimal effort and high performance.
Let's evaluate the options.
* Option A: Create a Feature Serving Endpoint from a FeatureSpec that references an online store synced from the Delta table. Query the Feature Serving Endpoint as part of the agent logic / tool implementation
* Databricks Feature Serving provides low-latency access to real-time data from Delta tables via an online store. Syncing the Delta table to a Feature Serving Endpoint allows the chatbot to query showtimes efficiently, integrating seamlessly into the RAG agent'stool logic. This leverages Databricks' native infrastructure, minimizing effort and ensuring performance.
* Databricks Reference:"Feature Serving Endpoints provide real-time access to Delta table data with low latency, ideal for production systems"("Databricks Feature Engineering Guide," 2023).
* Option B: Query the Delta table directly via a SQL query constructed from the user's input using a text-to-SQL LLM in the agent logic / tool
* Using a text-to-SQL LLM to generate queries adds complexity (e.g., ensuring accurate SQL generation) and latency (LLM inference + SQL execution). While feasible, it's less performant and requires more effort than a pre-built serving solution.
* Databricks Reference:"Direct SQL queries are flexible but may introduce overhead in real-time applications"("Building LLM Applications with Databricks").
* Option C: Write the Delta table contents to a text column, then embed those texts using an embedding model and store these in the vector index. Look up the information based on the embedding as part of the agent logic / tool implementation
* Converting structured Delta table data (e.g., showtimes) into text, embedding it, and using vector search is inefficient for structured lookups. It's effort-intensive (preprocessing, embedding) and less precise than direct queries, undermining performance.
* Databricks Reference:"Vector search excels for unstructured data, not structured tabular lookups"("Databricks Vector Search Documentation").
* Option D: Set up a task in Databricks Workflows to write the information in the Delta table periodically to an external database such as MySQL and query the information from there as part of the agent logic / tool implementation
* Exporting to an external database (e.g., MySQL) adds setup effort (workflow, external DB management) and latency (periodic updates vs. real-time). It's less performant and more complex than using Databricks' native tools.
* Databricks Reference:"Avoid external systems when Delta tables provide real-time data natively"("Databricks Workflows Guide").
Conclusion: Option A minimizes effort by using Databricks Feature Serving for real-time, low-latency access to the Delta table, ensuring high performance in a production-ready RAG chatbot.
NEW QUESTION # 58
A Generative AI Engineer at a legal firm is designing a RAG system to analyze historical legal cases. The system needs to process millions of court opinions and legal documents, already organized by time and topic, to track how interpretations of specific laws have evolved over time. All of these documents are in plain-text.
The engineer needs to choose a chunking method that would most effectively preserve continuity and the temporal nature of the cases. Which method do they choose?
Answer: B
Explanation:
In the context of legal document analysis where the " evolution of interpretation " is the primary goal, preserving narrative continuity is paramount. Windowed summarization with overlapping chunks is the most effective method for this use case. Overlapping (e.g., 10-15% of the chunk size) ensures that sentences or concepts split at the boundary of one chunk are preserved in the next, preventing the loss of critical context that often occurs in legal jargon. Furthermore, windowed summarization allows the system to condense long- form court opinions into manageable parts while maintaining the chronological " thread " of the argument.
While sentence-level embeddings with metadata (D) are useful for filtering, they often lack the sufficient context required to understand the nuances of a legal ruling. A windowed approach provides the LLM with enough surrounding text to understand the " why " behind a legal evolution, rather than just the " when. "
NEW QUESTION # 59
A Generative AI Engineer I using the code below to test setting up a vector store: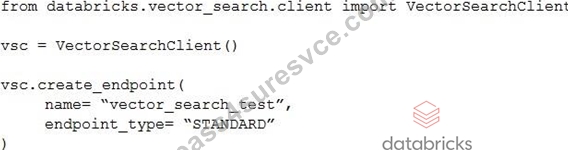
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: D
Explanation:
* Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
* Explanation of Options:
Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, hence Option B.
NEW QUESTION # 60
Generative AI Engineer at an electronics company just deployed a RAG application for customers to ask questions about products that the company carries. However, they received feedback that the RAG response often returns information about an irrelevant product.
What can the engineer do to improve the relevance of the RAG's response?
Answer: B
Explanation:
In a Retrieval-Augmented Generation (RAG) system, the key to providing relevant responses lies in the quality of the retrieved context. Here's why option A is the most appropriate solution:
* Context Relevance:The RAG model generates answers based on retrieved documents or context. If the retrieved information is about an irrelevant product, it suggests that the retrieval step is failing to select the right context. The Generative AI Engineer must first assess the quality of what is being retrieved and ensure it is pertinent to the query.
* Vector Search and Embedding Similarity:RAG typically uses vector search for retrieval, where embeddings of the query are matched against embeddings of product descriptions. Assessing the semantic similarity searchprocess ensures that the closest matches are actually relevant to the query.
* Fine-tuning the Retrieval Process:By improving theretrieval quality, such as tuning the embeddings or adjusting the retrieval strategy, the system can return more accurate and relevant product information.
* Why Other Options Are Less Suitable:
* B (Caching FAQs): Caching can speed up responses for frequently asked questions but won't improve the relevance of the retrieved content for less frequent or new queries.
* C (Use a Different LLM): Changing the LLM only affects the generation step, not the retrieval process, which is the core issue here.
* D (Different Semantic Search Algorithm): This could help, but the first step is to evaluate the current retrieval context before replacing the search algorithm.
Therefore, improving and assessing the quality of the retrieved context (option A) is the first step to fixing the issue of irrelevant product information.
NEW QUESTION # 61
......
You will receive Databricks-Generative-AI-Engineer-Associate exam materials immediately after your payment is successful, and then, you can use Databricks-Generative-AI-Engineer-Associate test guide to learn. Everyone knows that time is very important and hopes to learn efficiently, especially for those who have taken a lot of detours and wasted a lot of time. Once they discover Databricks-Generative-AI-Engineer-Associate study braindumps, they will definitely want to seize the time to learn. However, students often purchase materials from the Internet, who always encounters a problem that they have to waste several days of time on transportation, especially for those students who live in remote areas. But with Databricks-Generative-AI-Engineer-Associate Exam Materials, there is no way for you to waste time. The sooner you download and use Databricks-Generative-AI-Engineer-Associate study braindumps, the sooner you get the certificate.
Databricks-Generative-AI-Engineer-Associate New Dumps Book: https://www.pass4suresvce.com/Databricks-Generative-AI-Engineer-Associate-pass4sure-vce-dumps.html
P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Pass4suresVCE: https://drive.google.com/open?id=1mbHdKWYpfR238t9LoIrzzg-a60Wb8Cp-