P.S. GoShikenがGoogle Driveで共有している無料かつ新しいDP-100ダンプ:https://drive.google.com/open?id=14wuNtw9yO72RL5qwpkYblpgzr3kNw3yn
一部の候補者は、自社のDP-100ソフトウェアテストシミュレーターを購入する場合があります。 ソフトバージョンをインストールできるパーソナルコンピューターの台数を尋ねられます。 実際、コンピューターの数に制限はありません。 したがって、DP-100ソフトウェアテストシミュレータを購入すると、同時にマルチユーザーをサポートします。 無制限にコンピューターにインストールできます。 あなたが訓練学校である場合、教師が気軽に発表して説明するのに適しています。 優れたDP-100ソフトウェアテストシミュレータは合格率が高く、GoShikenは長期的な協力をお待ちしています。
Microsoft DP-100: Azure上でのデータサイエンスソリューションの設計と実装は、データプロフェッショナルがAzure上でデータサイエンスソリューションの設計と実装のスキルを証明するための認定試験です。これは、データエンジニア、データサイエンティスト、および組織内の他のステークホルダーと協力して、エンドツーエンドのデータサイエンスソリューションを作成し、展開する個人を対象としています。
DP-100資格を取得することで、データサイエンスや機械学習のキャリアを進めることができます。これは、Azureサービスを使用したデータ駆動型ソリューションを設計および実装するための知識とスキルを雇用主に証明することができます。さらに、Microsoftは、DP-100を補完し、クラウドコンピューティングの幅広いスキルセットを構築するのに役立つさまざまなAzure認定資格を提供しています。
GoShikenのMicrosoftのDP-100試験トレーニング資料はほかのサイトでの資料よりもっと正確的で、もっと理解やすくて、もっと権威性が高いです。GoShikenを選ぶなら、きっと君に後悔させません。もし君はいささかな心配することがあるなら、あなたはうちの商品を購入する前に、GoShikenは無料でサンプルを提供することができます。GoShikenのMicrosoftのDP-100問題集を購入するなら、君がMicrosoftのDP-100認定試験に合格する率は100パーセントです。
Microsoft DP-100認定試験は、Azureのデータサイエンスソリューションを設計および実装するために必要なスキルと知識をテストするように設計されています。この試験は、データサイエンティスト、データエンジニア、機械学習エンジニアなどのデータサイエンスソリューションの構築と実装に関与している専門家を対象としています。試験に合格すると、候補者がAzureに関するデータサイエンスソリューションを設計および実装するために必要なスキルと知識を持っていることが示されています。
質問 # 317
You are developing a linear regression model in Azure Machine Learning Studio. You run an experiment to compare different algorithms.
The following image displays the results dataset output: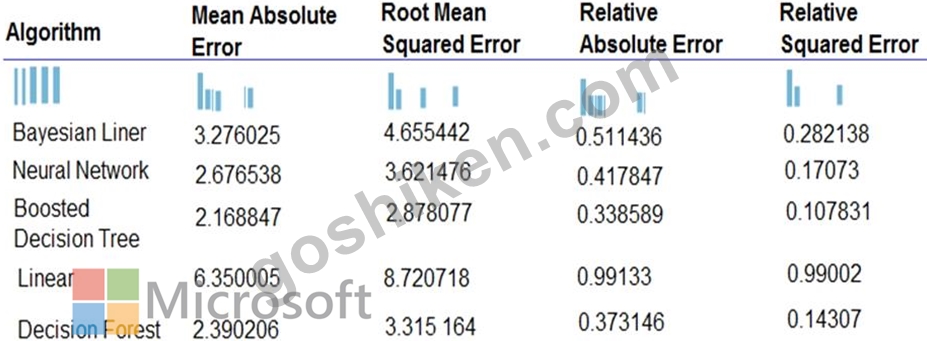
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the image.
NOTE: Each correct selection is worth one point.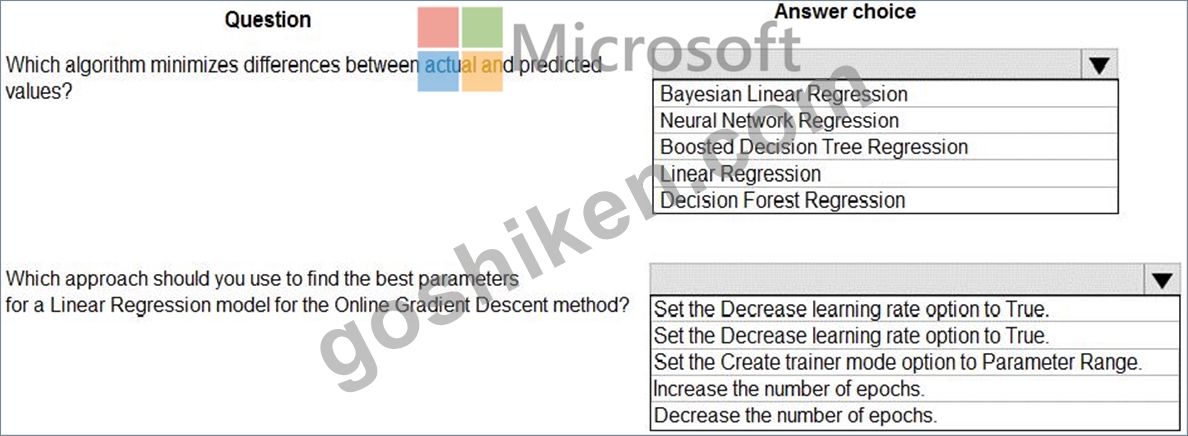
正解:
解説: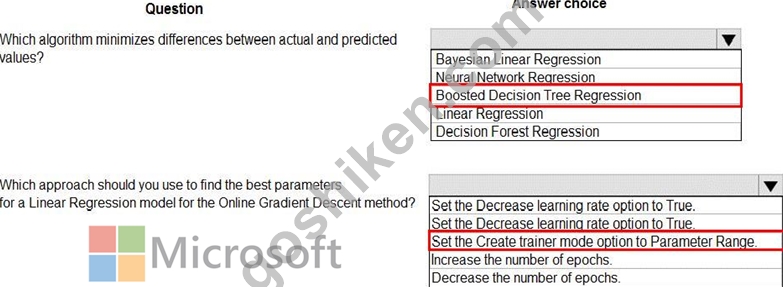
Explanation:
Box 1: Boosted Decision Tree Regression
Mean absolute error (MAE) measures how close the predictions are to the actual outcomes; thus, a lower score is better.
Box 2:
Online Gradient Descent: If you want the algorithm to find the best parameters for you, set Create trainer mode option to Parameter Range. You can then specify multiple values for the algorithm to try.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/evaluate-model
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/linear-regression
質問 # 318
You create an Azure Machine Learning workspace.
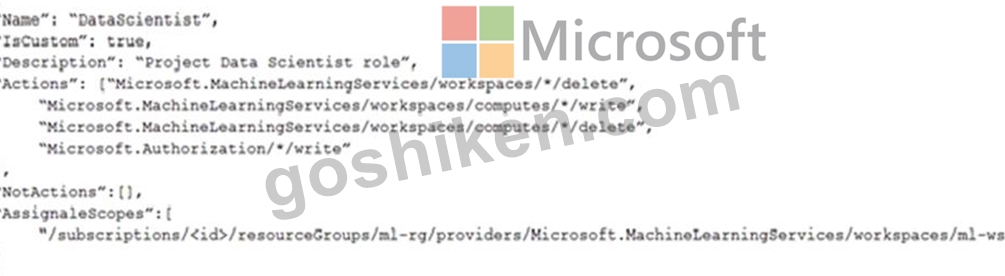
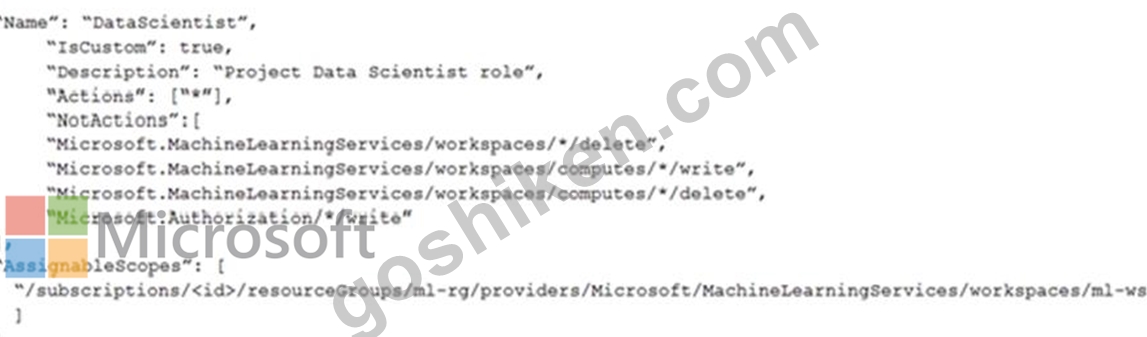
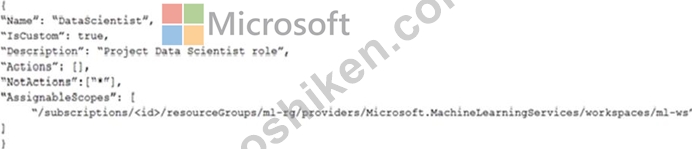
You must create a custom role named DataScientist that meets the following requirements:
Role members must not be able to delete the workspace.
Role members must not be able to create, update, or delete compute resource in the workspace.
Role members must not be able to add new users to the workspace.
You need to create a JSON file for the DataScientist role in the Azure Machine Learning workspace.
The custom role must enforce the restrictions specified by the IT Operations team.
Which JSON code segment should you use?
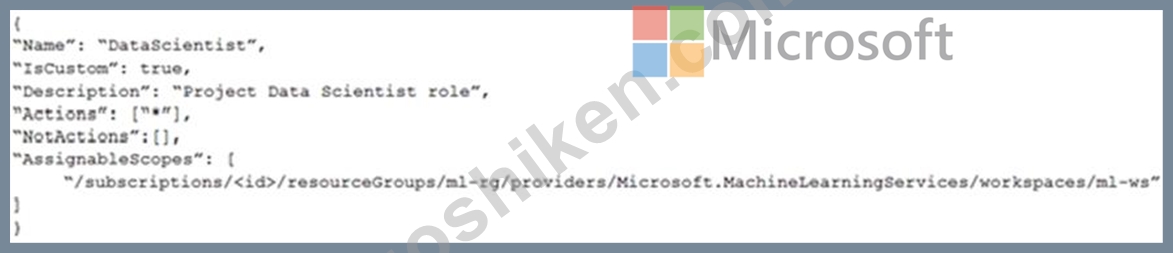
正解:C
解説:
The following custom role can do everything in the workspace except for the following actions:
It can't create or update a compute resource.
It can't delete a compute resource.
It can't add, delete, or alter role assignments.
It can't delete the workspace.
To create a custom role, first construct a role definition JSON file that specifies the permission and scope for the role. The following example defines a custom role named "Data Scientist Custom" scoped at a specific workspace level:
data_scientist_custom_role.json :
{
"Name": "Data Scientist Custom",
"IsCustom": true,
"Description": "Can run experiment but can't create or delete compute.",
"Actions": ["*"],
"NotActions": [
"Microsoft.MachineLearningServices/workspaces/*/delete",
"Microsoft.MachineLearningServices/workspaces/write",
"Microsoft.MachineLearningServices/workspaces/computes/*/write",
"Microsoft.MachineLearningServices/workspaces/computes/*/delete",
"Microsoft.Authorization/*/write"
],
"AssignableScopes": [
"/subscriptions/<subscription_id>/resourceGroups/<resource_group_name>/providers/Microsoft.MachineLearningServices/workspaces/<workspace_name>"
]
}
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-assign-roles
質問 # 319
You have a feature set containing the following numerical features: X, Y, and Z.
The Poisson correlation coefficient (r-value) of X, Y, and Z features is shown in the following image: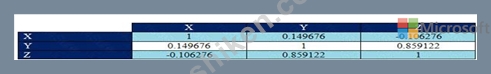
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.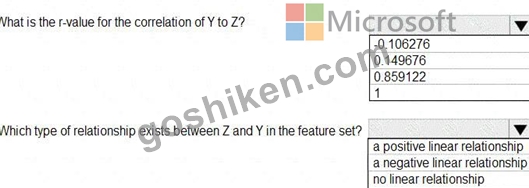
正解:
解説: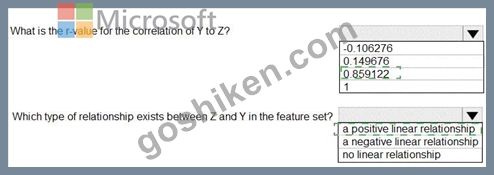
Explanation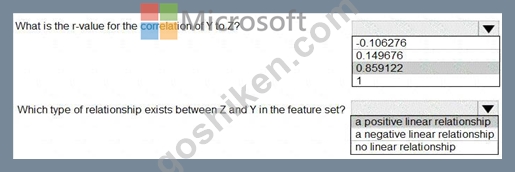
Box 1: 0.859122
Box 2: a positively linear relationship
+1 indicates a strong positive linear relationship
-1 indicates a strong negative linear correlation
0 denotes no linear relationship between the two variables.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/compute-linear-correlation
質問 # 320
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2.
The default datastore of workspace1 contains a folder named sample_dat
a. The folder structure contains the following content: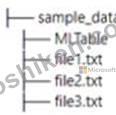
You write Python SDK v2 code to materialize the data from the files in the sample.data folder into a Pandas data frame. You need to complete the Python SDK v2 code to use the MLTaWe folder as the materialization blueprint. How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.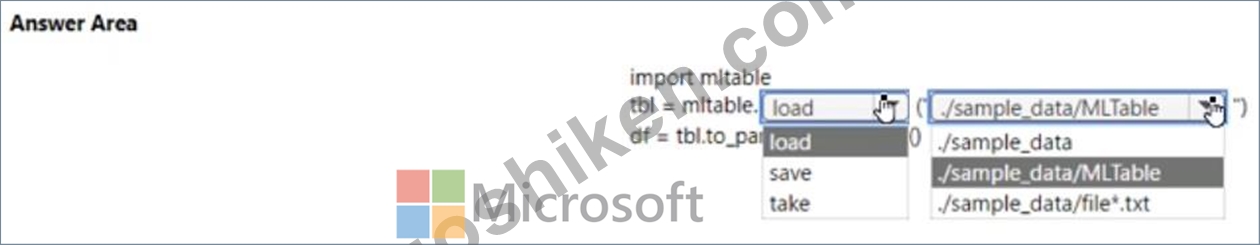
正解:
解説: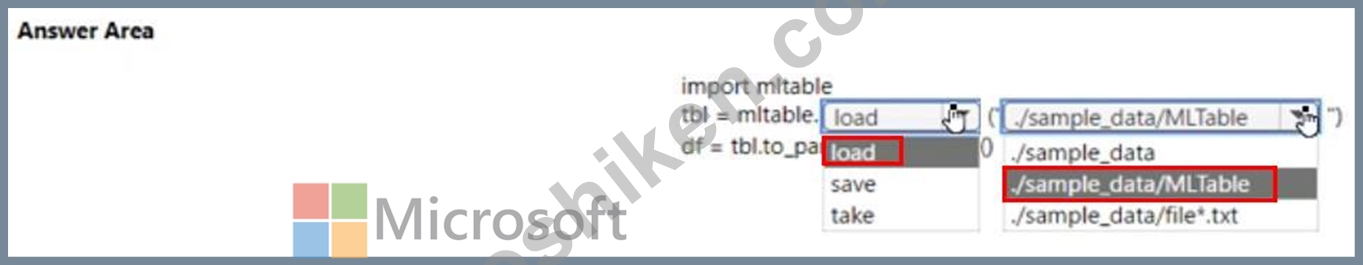
質問 # 321
You are using a decision tree algorithm. You have trained a model that generalizes well at a tree depth equal to 10.
You need to select the bias and variance properties of the model with varying tree depth values.
Which properties should you select for each tree depth? To answer, select the appropriate options in the answer area.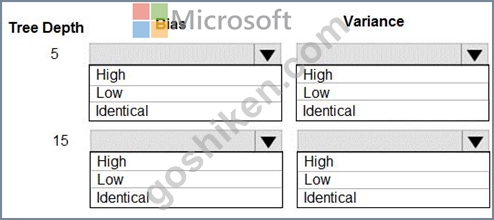
正解:
解説: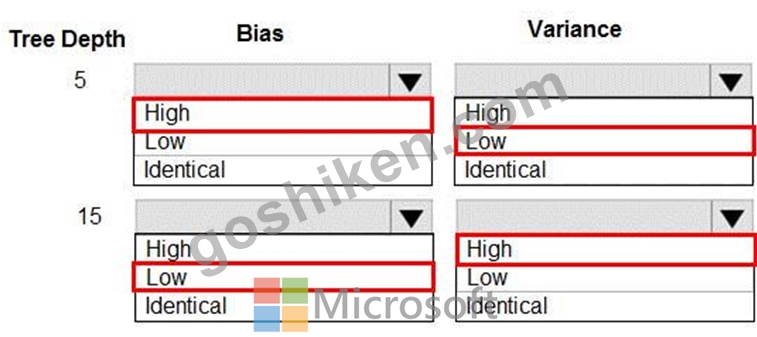
Explanation:
In decision trees, the depth of the tree determines the variance. A complicated decision tree (e.g. deep) has low bias and high variance.
Note: In statistics and machine learning, the bias-variance tradeoff is the property of a set of predictive models whereby models with a lower bias in parameter estimation have a higher variance of the parameter estimates across samples, and vice versa. Increasing the bias will decrease the variance. Increasing the variance will decrease the bias.
References:
https://machinelearningmastery.com/gentle-introduction-to-the-bias-variance-trade-off-in-machine-learning/
質問 # 322
......
DP-100資格参考書: https://www.goshiken.com/Microsoft/DP-100-mondaishu.html
無料でクラウドストレージから最新のGoShiken DP-100 PDFダンプをダウンロードする:https://drive.google.com/open?id=14wuNtw9yO72RL5qwpkYblpgzr3kNw3yn