BONUS!!! Download part of Pass4Test Databricks-Generative-AI-Engineer-Associate dumps for free: https://drive.google.com/open?id=1OfUCUGX-9B1c3FsNrA1GNGb3_b8qQ7kL
The price for the Databricks-Generative-AI-Engineer-Associate certification test's registration is somewhere around $100 to $1000. Thus, you would never risk your precious time and money. Pass4Test offers a demo version of the Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) practice material which is totally free. You can try a free demo to make yourself more confident about the authenticity of the Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) product. After buying the Databricks-Generative-AI-Engineer-Associate material, you can instantly use it.
| Section | Weight | Objectives |
|---|---|---|
| Data Preparation | 14% | - Prepare data for RAG applications - Manage data quality and chunking |
| Assembling and Deploying Apps | 22% | - Package and deploy models - Build and deploy RAG pipelines - Use Vector Search |
| Design Applications | 14% | - Design and architect applications - Select appropriate models - Define functional requirements |
| Governance | 8% | - Apply safety filters and guidelines - Manage permissions and logging |
| Evaluation and Monitoring | 12% | - Monitor deployed applications - Evaluate model quality and performance |
| Application Development | 30% | - Integrate Databricks tools (LangChain, etc.) - Implement prompt engineering - Develop LLM chains |
>> Databricks-Generative-AI-Engineer-Associate Reliable Braindumps Free <<
As the old saying goes, "Everything starts from reality, seeking truth from facts." This means that when we learn the theory, we end up returning to the actual application. Therefore, the effect of the user using the latest Databricks-Generative-AI-Engineer-Associate exam dump is the only standard for proving the effectiveness and usefulness of our products. I believe that users have a certain understanding of the advantages of our Databricks-Generative-AI-Engineer-Associate Study Guide, but now I want to show you the best of our Databricks-Generative-AI-Engineer-Associate training Materials - Amazing pass rate. Based on the statistics, prepare the exams under the guidance of our Databricks-Generative-AI-Engineer-Associate practice materials, the user's pass rate is up to 98% to 100%, And they only need to practice latest Databricks-Generative-AI-Engineer-Associate exam dump to hours.
NEW QUESTION # 79
A Generative AI Engineer is tasked with deploying an application that takes advantage of a custom MLflow Pyfunc model to return some interim results.
How should they configure the endpoint to pass the secrets and credentials?
Answer: B
Explanation:
Context: Deploying an application that uses an MLflow Pyfunc model involves managing sensitive information such as secrets and credentials securely.
Explanation of Options:
* Option A: Use spark.conf.set(): While this method can pass configurations within Spark jobs, using it for secrets is not recommended because it may expose them in logs or Spark UI.
* Option B: Pass variables using the Databricks Feature Store API: The Feature Store API is designed for managing features for machine learning, not for handling secrets or credentials.
* Option C: Add credentials using environment variables: This is a common practice for managing credentials in a secure manner, as environment variables can be accessed securely by applications without exposing them in the codebase.
* Option D: Pass the secrets in plain text: This is highly insecure and not recommended, as it exposes sensitive information directly in the code.
Therefore,Option Cis the best method for securely passing secrets and credentials to an application, protecting them from exposure.
NEW QUESTION # 80
A Generative Al Engineer is developing a RAG system for their company to perform internal document Q&A for structured HR policies, but the answers returned are frequently incomplete and unstructured It seems that the retriever is not returning all relevant context The Generative Al Engineer has experimented with different embedding and response generating LLMs but that did not improve results.
Which TWO options could be used to improve the response quality?
Choose 2 answers
Answer: A,E
Explanation:
The problem describes a Retrieval-Augmented Generation (RAG) system for HR policy Q&A where responses are incomplete and unstructured due to the retriever failing to return sufficient context. The engineer has already tried different embedding and response-generating LLMs without success, suggesting the issue lies in the retrieval process-specifically, how documents are chunked and indexed. Let's evaluate the options.
* Option A: Add the section header as a prefix to chunks
* Adding section headers provides additional context to each chunk, helping the retriever understand the chunk's relevance within the document structure (e.g., "Leave Policy: Annual Leave" vs. just "Annual Leave"). This can improve retrieval precision for structured HR policies.
* Databricks Reference:"Metadata, such as section headers, can be appended to chunks to enhance retrieval accuracy in RAG systems"("Databricks Generative AI Cookbook," 2023).
* Option B: Increase the document chunk size
* Larger chunks include more context per retrieval, reducing the chance of missing relevant information split across smaller chunks. For structured HR policies, this can ensure entire sections or rules are retrieved together.
* Databricks Reference:"Increasing chunk size can improve context completeness, though it may trade off with retrieval specificity"("Building LLM Applications with Databricks").
* Option C: Split the document by sentence
* Splitting by sentence creates very small chunks, which could exacerbate the problem by fragmenting context further. This is likely why the current system fails-it retrieves incomplete snippets rather than cohesive policy sections.
* Databricks Reference: No specific extract opposes this, but the emphasis on context completeness in RAG suggests smaller chunks worsen incomplete responses.
* Option D: Use a larger embedding model
* A larger embedding model might improve vector quality, but the question states that experimenting with different embedding models didn't help. This suggests the issue isn't embedding quality but rather chunking/retrieval strategy.
* Databricks Reference: Embedding models are critical, but not the focus when retrieval context is the bottleneck.
* Option E: Fine tune the response generation model
* Fine-tuning the LLM could improve response coherence, but if the retriever doesn't provide complete context, the LLM can't generate full answers. The root issue is retrieval, not generation.
* Databricks Reference: Fine-tuning is recommended for domain-specific generation, not retrieval fixes ("Generative AI Engineer Guide").
Conclusion: Options A and B address the retrieval issue directly by enhancing chunk context-either through metadata (A) or size (B)-aligning with Databricks' RAG optimization strategies. C would worsen the problem, while D and E don't target the root cause given prior experimentation.
NEW QUESTION # 81
A Generative Al Engineer is working with a retail company that wants to enhance its customer experience by automatically handling common customer inquiries. They are working on an LLM-powered Al solution that should improve response times while maintaining a personalized interaction. They want to define the appropriate input and LLM task to do this.
Which input/output pair will do this?
Answer: C
Explanation:
The task described in the question involves enhancing customer experience by automatically handling common customer inquiries using an LLM-powered AI solution. This requires the system to process input data (customer inquiries) and generate personalized, relevant responses efficiently. Let's evaluate the options step-by-step in the context of Databricks Generative AI Engineer principles, which emphasize leveraging LLMs for tasks like question answering, summarization, and retrieval-augmented generation (RAG).
Option A: Input: Customer reviews; Output: Group the reviews by users and aggregate per-user average rating, then respond This option focuses on analyzing customer reviews to compute average ratings per user. While this might be useful for sentiment analysis or user profiling, it does not directly address the goal of handling common customer inquiries or improving response times for personalized interactions. Customer reviews are typically feedback data, not real-time inquiries requiring immediate responses.
Databricks Reference: Databricks documentation on LLMs (e.g., "Building LLM Applications with Databricks") emphasizes that LLMs excel at tasks like question answering and conversational responses, not just aggregation or statistical analysis of reviews.
Option B: Input: Customer service chat logs; Output: Group the chat logs by users, followed by summarizing each user's interactions, then respond This option uses chat logs as input, which aligns with customer service scenarios. However, the output-grouping by users and summarizing interactions-focuses on user-specific summaries rather than directly addressing inquiries. While summarization is an LLM capability, this approach lacks the specificity of finding answers to common questions, which is central to the problem.
Databricks Reference: Per Databricks' "Generative AI Cookbook," LLMs can summarize text, but for customer service, the emphasis is on retrieval and response generation (e.g., RAG workflows) rather than user interaction summaries alone.
Option C: Input: Customer service chat logs; Output: Find the answers to similar questions and respond with a summary This option uses chat logs (real customer inquiries) as input and tasks the LLM with identifying answers to similar questions, then providing a summarized response. This directly aligns with the goal of handling common inquiries efficiently while maintaining personalization (by referencing past interactions or similar cases). It leverages LLM capabilities like semantic search, retrieval, and response generation, which are core to Databricks' LLM workflows.
Databricks Reference: From Databricks documentation ("Building LLM-Powered Applications," 2023), an exact extract states: "For customer support use cases, LLMs can be used to retrieve relevant answers from historical data like chat logs and generate concise, contextually appropriate responses." This matches Option C's approach of finding answers and summarizing them.
Option D: Input: Customer reviews; Output: Classify review sentiment
This option focuses on sentiment classification of reviews, which is a valid LLM task but unrelated to handling customer inquiries or improving response times in a conversational context. It's more suited for feedback analysis than real-time customer service.
Databricks Reference: Databricks' "Generative AI Engineer Guide" notes that sentiment analysis is a common LLM task, but it's not highlighted for real-time conversational applications like customer support.
Conclusion: Option C is the best fit because it uses relevant input (chat logs) and defines an LLM task (finding answers and summarizing) that meets the requirements of improving response times and maintaining personalized interaction. This aligns with Databricks' recommended practices for LLM-powered customer service solutions, such as retrieval-augmented generation (RAG) workflows.
NEW QUESTION # 82
A Generative AI Engineer I using the code below to test setting up a vector store: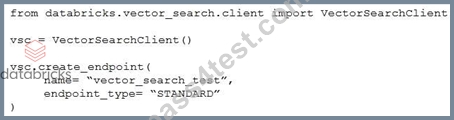
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: A
Explanation:
Context : The Generative AI Engineer is setting up a vector store using Databricks ' VectorSearchClient.
This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options :
* Option A: vsc.get_index() : This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index() : After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index() : This function would create an index that directly accesses the data without synchronization. While also a valid approach, it ' s less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search() : This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, hence Option B .
NEW QUESTION # 83
A Generative AI Engineer is building a Generative AI system that suggests the best matched employee team member to newly scoped projects. The team member is selected from a very large team. Thematch should be based upon project date availability and how well their employee profile matches the project scope. Both the employee profile and project scope are unstructured text.
How should the Generative Al Engineer architect their system?
Answer: D
Explanation:
* Problem Context: The problem involves matching team members to new projects based on two main factors:
* Availability: Ensure the team members are available during the project dates.
* Profile-Project Match: Use the employee profiles (unstructured text) to find the best match for a project's scope (also unstructured text).
The two main inputs are theemployee profilesandproject scopes, both of which are unstructured. This means traditional rule-based systems (e.g., simple keyword matching) would be inefficient, especially when working with large datasets.
* Explanation of Options: Let's break down the provided options to understand why D is the most optimal answer.
* Option Asuggests embedding project scopes into a vector store and then performing retrieval using team member profiles. While embedding project scopes into a vector store is a valid technique, it skips an important detail: the focus should primarily be on embedding employee profiles because we're matching the profiles to a new project, not the other way around.
* Option Binvolves using a large language model (LLM) to extract keywords from the project scope and perform keyword matching on employee profiles. While LLMs can help with keyword extraction, this approach is too simplistic and doesn't leverage advanced retrieval techniques like vector embeddings, which can handle the nuanced and rich semantics of unstructured data. This approach may miss out on subtle but important similarities.
* Option Csuggests calculating a similarity score between each team member's profile and project scope. While this is a good idea, it doesn't specify how to handle the unstructured nature of data efficiently. Iterating through each member's profile individually could be computationally expensive in large teams. It also lacks the mention of using a vector store or an efficient retrieval mechanism.
* Option Dis the correct approach. Here's why:
* Embedding team profiles into a vector store: Using a vector store allows for efficient similarity searches on unstructured data. Embedding the team member profiles into vectors captures their semantics in a way that is far more flexible than keyword-based matching.
* Using project scope for retrieval: Instead of matching keywords, this approach suggests using vector embeddings and similarity search algorithms (e.g., cosine similarity) to find the team members whose profiles most closely align with the project scope.
* Filtering based on availability: Once the best-matched candidates are retrieved based on profile similarity, filtering them by availability ensures that the system provides a practically useful result.
This method efficiently handles large-scale datasets by leveragingvector embeddingsandsimilarity search techniques, both of which are fundamental tools inGenerative AI engineeringfor handling unstructured text.
* Technical References:
* Vector embeddings: In this approach, the unstructured text (employee profiles and project scopes) is converted into high-dimensional vectors using pretrained models (e.g., BERT, Sentence-BERT, or custom embeddings). These embeddings capture the semantic meaning of the text, making it easier to perform similarity-based retrieval.
* Vector stores: Solutions likeFAISSorMilvusallow storing and retrieving large numbers of vector embeddings quickly. This is critical when working with large teams where querying through individual profiles sequentially would be inefficient.
* LLM Integration: Large language models can assist in generating embeddings for both employee profiles and project scopes. They can also assist in fine-tuning similarity measures, ensuring that the retrieval system captures the nuances of the text data.
* Filtering: After retrieving the most similar profiles based on the project scope, filtering based on availability ensures that only team members who are free for the project are considered.
This system is scalable, efficient, and makes use of the latest techniques inGenerative AI, such as vector embeddings and semantic search.
NEW QUESTION # 84
......
Studying for attending Databricks-Generative-AI-Engineer-Associate exam pays attention to the method. The good method often can bring the result with half the effort, therefore we in the examination time, and also should know some test-taking skill. The Databricks-Generative-AI-Engineer-Associate quiz guide on the basis of summarizing the past years, the answers have certain rules can be found, either subjective or objective questions, we can find in the corresponding module of similar things in common. To this end, the Databricks-Generative-AI-Engineer-Associate Exam Dumps have summarized some types of questions in the qualification examination to help you pass the Databricks-Generative-AI-Engineer-Associate exam.
Valid Dumps Databricks-Generative-AI-Engineer-Associate Files: https://www.pass4test.com/Databricks-Generative-AI-Engineer-Associate.html
P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Pass4Test: https://drive.google.com/open?id=1OfUCUGX-9B1c3FsNrA1GNGb3_b8qQ7kL