As long as you spend less time on the game and spend more time on learning, the DP-750 study materials can reduce your pressure so that users can feel relaxed and confident during the preparation and certification process on the DP-750 exam. It is believed that many users have heard of the DP-750 Latest preparation materials from their respective friends or news stories. Our DP-750 exam questions are valid and reliable. So why don't you take this step and try on our DP-750 study guide? You will not regret your wise choice.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30–35% | - Ingest and transform data
|
| Topic 2: Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Topic 3: Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Topic 4: Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
>> DP-750 Question Explanations <<
Furthermore, it is our set of DP-750 brain dumps that stamp your success with a marvelous score. The dumps include DP-750 study questions that likely to be set in real DP-750 exam. They provide you a swift understanding of the key points of DP-750 covered under the syllabus contents. Going through them enhances your knowledge to the optimum level and enables you to ace exam without any hassle. No need of running after unreliable sources such as free courses, online DP-750 courses for free and DP-750 dumps that do not ensure a passing guarantee to the DP-750 exam candidates.
NEW QUESTION # 27
Hotspot Question
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 contains three tasks named Task1, Task2, and Task3.
If Task1 fails, Task2 and Task3 must be prevented from running. Successfully completed tasks must NOT rerun during recovery.
You need to configure Job1 to support controlled failure handling and recovery.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.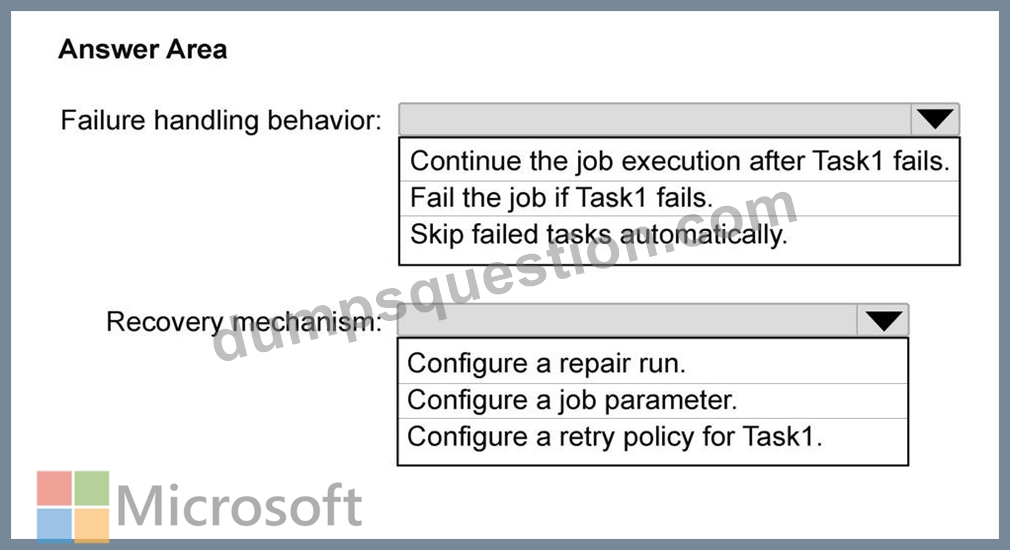
Answer:
Explanation: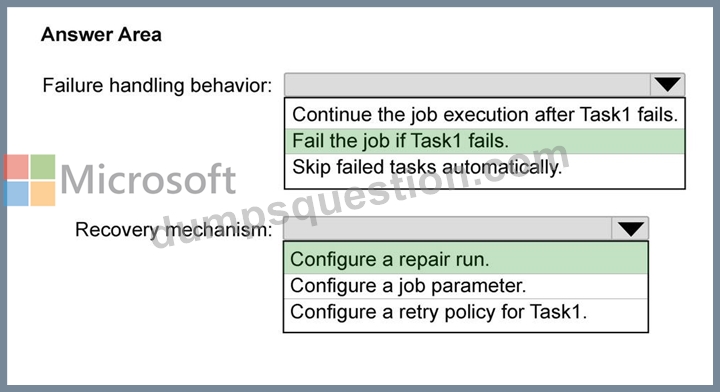
NEW QUESTION # 28
Drag and Drop Question
You have an Azure Databricks workspace named Workspace1 that is attached to a Unity Catalog metastore named metastore1.
You need to register an Azure Storage account named account1 that has a hierarchical namespace enabled as an external location. The external location must use a managed identity to authenticate to account1 and the solution must follow the principle of least privilege.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.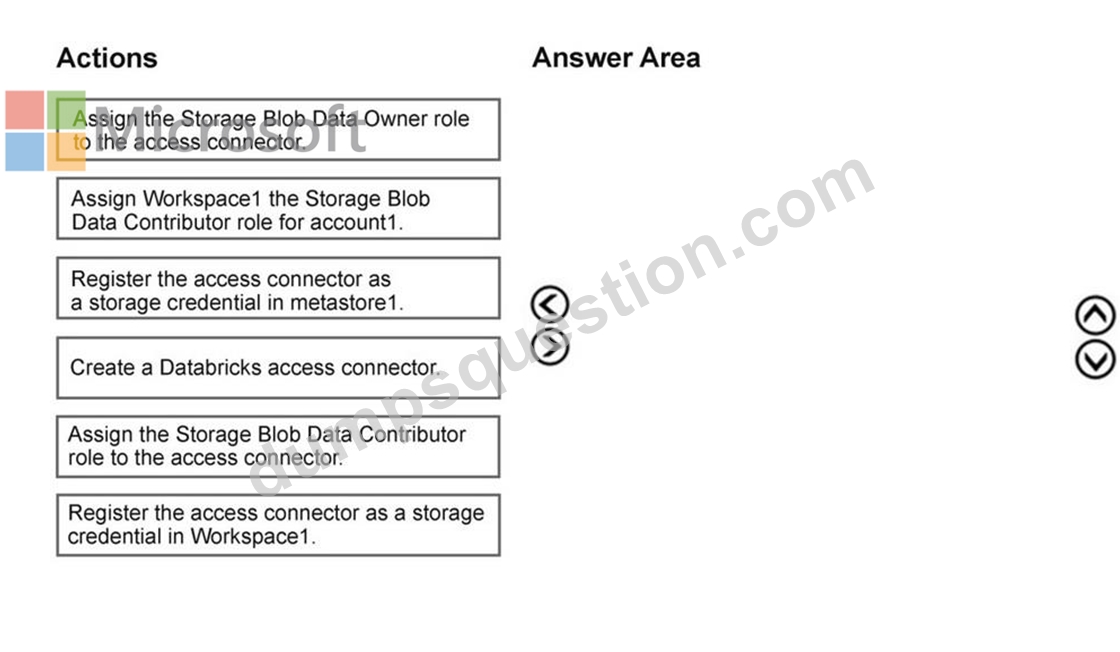
Answer:
Explanation: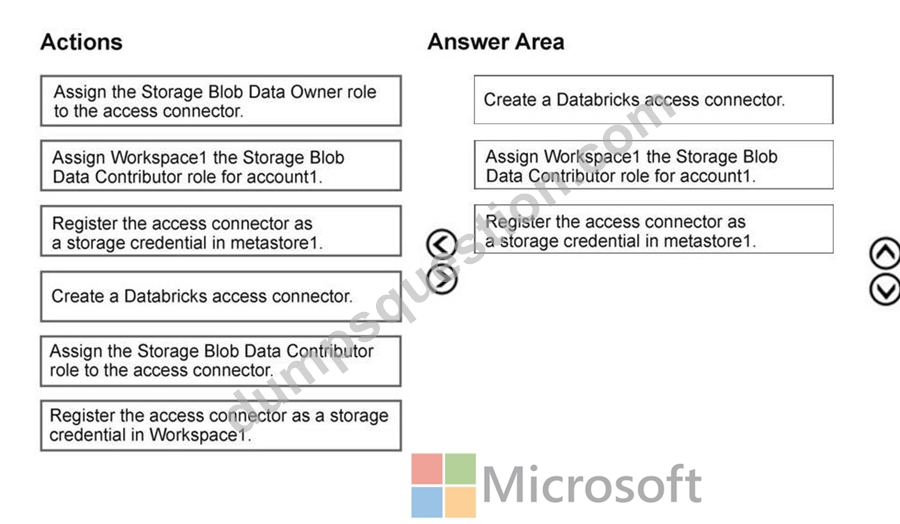
NEW QUESTION # 29
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.dropna(subset=["order_amount"])
Does this meet the goal?
Answer: B
Explanation:
The correct answer is A - Yes.
df.dropna(subset=['order_amount']) is the idiomatic PySpark way to remove rows where a specific column contains a null. It inspects only the columns listed in subset and drops any row where those columns are null.
The resulting DataFrame contains only rows where order_amount is not null - exactly what the requirement asks for.
The subset parameter is important: without it, dropna() would drop rows where ANY column is null, which could incorrectly exclude rows that have nulls in other columns but a valid order_amount. By specifying subset=['order_amount'], the filter is applied precisely and only to the column in question.
This method is semantically equivalent to df.filter(df.order_amount.isNotNull()) and to the SQL clause WHERE order_amount IS NOT NULL. Both are correct - dropna with a subset is arguably the more readable Pythonic approach.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 30
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have 500 GB of sales data stored as multiple CSV files in cloud storage.
You plan to load the data into a Delta table.
You need to ingest the bulk data by using a solution that meets the following requirements:
* Minimize how long it takes to implement the solution.
* Minimize the amount of custom code required.
What should you use?
Answer: D
Explanation:
COPY INTO provides a concise SQL-based mechanism for loading files from cloud storage directly into a Delta table. It requires substantially less custom code than constructing a Spark ingestion application and is suitable for a straightforward bulk load of multiple CSV files. COPY INTO is also retryable and idempotent:
it tracks files already loaded into the target table and skips them during later executions, helping prevent accidental duplication. Auto Loader is optimized primarily for incremental and continuously arriving files and normally requires a streaming or triggered pipeline. Apache Spark read APIs require additional code for reading, transforming, tracking, and writing the files. Manually uploading 500 GB would be inefficient and operationally unsuitable. Therefore, COPY INTO best satisfies both implementation-speed and minimal-code requirements. Microsoft Learn
NEW QUESTION # 31
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1. Job1 contains multiple tasks.
Failures of non-critical tasks must be logged but must NOT trigger notifications. Notifications must be triggered only when critical tasks have failed, and Job1 has completed You need to configure the job alerting behavior.
What should trigger a notification?
Answer: B
Explanation:
The correct answer is B - a job failure.
The requirement draws a clear line: non-critical task failures should be logged silently; notifications should only fire when a critical failure causes the whole job to stop. Configuring the alert on 'Job Failure' achieves this precisely - the notification triggers when the job itself reaches a Failed terminal state, which only happens when at least one critical task has failed and the job cannot complete.
Option A (task failure) would send a notification for every task-level failure, including non-critical ones.
That's exactly the noise the question wants to avoid. Option C (job success) would never alert on failures at all. Option D (task success) confirms completion but doesn't catch failures.
Setting alerting at the job level rather than the task level is also simpler to configure - you don't need to mark individual tasks as critical or non-critical in the notification settings.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/alerts
NEW QUESTION # 32
......
We have three different versions of DP-750 exam questions on the formats: the PDF, the Software and the APP online. Though the content is the same, the varied formats indeed bring lots of conveniences to our customers. The PDF version of DP-750 exam Practice can be printed so that you can take it wherever you go. And the Software version can simulate the real exam environment and support offline practice. Besides, the APP online can be applied to all kind of electronic devices. No matter who you are, I believe you can do your best to achieve your goals through our DP-750 Preparation questions!
New DP-750 Exam Name: https://www.dumpsquestion.com/DP-750-exam-dumps-collection.html