New Databricks-Machine-Learning-Professional Test Question, Exam Databricks-Machine-Learning-Professional Simulator

What's more, part of that TestPDF Databricks-Machine-Learning-Professional dumps now are free: https://drive.google.com/open?id=1D1XGnm5BWv3vj5SQKCr50R7XGOyDh512
Hundreds of candidates want to get the Databricks-Machine-Learning-Professional certification exam because it helps them in accelerating their Databricks careers. Cracking the Databricks Certified Machine Learning Professional (Databricks-Machine-Learning-Professional) exam of this credential is vital when it comes to the up gradation of their resume. The Databricks-Machine-Learning-Professional certification exam helps students earn from online work and it also benefits them in order to get a job in any good tech company. The Databricks-Machine-Learning-Professional Exam is on trend but the main problem that every applicant faces while preparing for it is not making the right choice of the Databricks-Machine-Learning-Professional Questions.
| Topic | Details |
|---|
| Topic 1 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 2 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 3 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| Topic 4 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| Topic 5 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Topic 6 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| Topic 7 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Topic 8 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
>> New Databricks-Machine-Learning-Professional Test Question <<
Exam Databricks-Machine-Learning-Professional Simulator | Pass4sure Databricks-Machine-Learning-Professional Exam Prep
Many exam candidates feel hampered by the shortage of effective Databricks-Machine-Learning-Professional preparation quiz, and the thick books and similar materials causing burden for you. Serving as indispensable choices on your way of achieving success especially during this Databricks-Machine-Learning-Professional Exam, more than 98 percent of candidates pass the exam with our Databricks-Machine-Learning-Professional training guide and all of former candidates made measurable advance and improvement.
Databricks Certified Machine Learning Professional Sample Questions (Q184-Q189):
NEW QUESTION # 184
A Machine Learning Engineer is setting up a cluster for a deep learning training run, but has a number of settings options to choose from. Their cluster will be reused by other engineers on their team and their datasets vary in size from hundreds of MBs to hundreds of GBs. They need to choose a configuration that allows for performant, stable deep learning training without excessive costs. Which configuration will do this?
- A. Using ML Runtime, use a moderate sized GPU VM for the driver and a variable number of memory optimized CPU VMs for the workers with autoscale enabled
- B. Using Databricks Runtime, use a moderately sized CPU VM for the driver and a variable number of GPU enabled VMs for the workers with autoscale enabled
- C. Using ML Runtime, use a large single node, GPU-enabled VM with auto termination set to 20 minutes to reduce costs
- D. Using ML Runtime, use a moderately sized CPU VM for the driver and a variable number of GPU enabled VMs for the workers with autoscale enabled
Answer: D
Explanation:
Using the ML Runtime ensures deep learning frameworks and GPU drivers are preconfigured and optimized. A moderately sized CPU driver is sufficient for coordination, while GPU-enabled worker nodes handle the computationally intensive training workload. Enabling autoscaling allows the cluster to efficiently adapt to datasets ranging from hundreds of megabytes to hundreds of gigabytes, providing strong performance without overprovisioning and controlling costs in a shared team environment.
NEW QUESTION # 185
A Machine Learning Engineer needs to deploy a custom model using Databricks Model Serving.
The model requires an external tokenizer file (for example, a vocabulary or pre-trained tokenizer) to function correctly. They need to ensure this tokenizer file is included with the model so it is available during model serving. How should they package this tokenizer file as part of the model deployment?
- A. Use the code_paths parameter in mlflow.pyfunc.log_model() to include the tokenizer file, assuming it's part of the custom Python logic needed by the model.
- B. Access the tokenizer file directly from Volumes at model inference time, which requires pre- provisioning access to the Volume for every model serving endpoint.
- C. Include tokenizer file as part of the model's software dependencies by adding it to the conda_env specification.
- D. Use the artifacts parameter in mlflow.pyfunc.log_model() to package the tokenizer file, referencing its path in Volumes.
Answer: D
Explanation:
The artifacts parameter in mlflow.pyfunc.log_model is designed for packaging non-code assets required at inference time, such as tokenizer files. By logging the tokenizer as a model artifact and referencing its path, MLflow ensures the file is versioned with the model and automatically made available to Databricks Model Serving during inference.
NEW QUESTION # 186
Concept drift is when there is a change in which element?
- A. The relationship between input variables and target variables
- B. The distribution of a target variable
- C. The distribution of an input variable
- D. The distribution of the predicted target given by the model
Answer: A
Explanation:
Concept drift occurs when the underlying relationship between input features and the target variable changes over time. This means that even if the feature and label distributions remain stable, the way features influence the target (the predictive relationship) has shifted, leading to reduced model accuracy unless retraining occurs.
NEW QUESTION # 187
A machine learning engineer is migrating a machine learning pipeline to use Data bricks Machine Learning. The pipeline needs to automatically refresh its model each time it runs.
They are using the following code block as part of their solution:
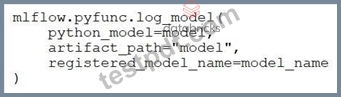
Assuming that this is the first time that the model is being run, which statement describes the impact of the registered_model_name=model_name parameter?
- A. It avoids the need to specify the model name in the subsequent required call to mflow.register_model.
- B. It registers a new model called model_name in the MLflow Model Registry.
- C. It identifies the name of the logged model in the MLflow Experiment.
- D. It registers the new version of the existing model_name model in the MLflow Model Registry.
Answer: B
Explanation:
The parameter registered_model_name=model_name in mlflow.pyfunc.log_model() automatically creates and registers a new model in the MLflow Model Registry if it doesn't already exist. Since this is the first time the model is being run, MLflow will register a new model named model_name and log the current model as version 1 of that registered model.
NEW QUESTION # 188
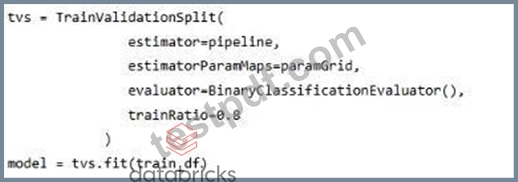
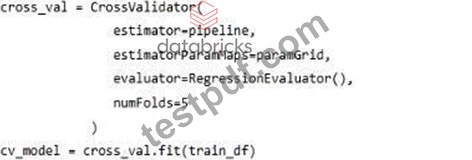
A Data Scientist is using Spark ML to train a model for detecting fraudulent transactions (1:
fraudulent, 0: non-fraudulent). To maximize the model's overall AUC (ROC) score, the Data Scientist wants to perform hyperparameter tuning on a Random Forest classifier. Due to budget constraints, the tuning process must be completed efficiently to avoid excessive compute costs.
Which approach will fulfill their needs?
Answer: B
Explanation:
TrainValidationSplit evaluates each hyperparameter combination using a single train/validation split, which is significantly more compute-efficient than k-fold cross-validation. Using a BinaryClassificationEvaluator aligns directly with optimizing AUC (ROC) for a binary fraud detection task, making this approach well suited for maximizing model performance under budget and compute constraints.
NEW QUESTION # 189
......
No matter how good the product is users will encounter some difficult problems in the process of use. Our Databricks-Machine-Learning-Professional real exam materials are not exceptional also, in order to enjoy the best product experience, as long as the user is in use process found any problem, can timely feedback to us, for the first time you check our Databricks-Machine-Learning-Professional Exam Question performance, professional maintenance staff to help users solve problems. Our Databricks-Machine-Learning-Professional learning reference files have a high efficient product maintenance team, and they can send the Databricks-Machine-Learning-Professional exam questions to you in a few minutes.
Exam Databricks-Machine-Learning-Professional Simulator: https://www.testpdf.com/Databricks-Machine-Learning-Professional-exam-braindumps.html
- Databricks-Machine-Learning-Professional New Test Bootcamp 🔇 Reliable Databricks-Machine-Learning-Professional Test Guide 😸 Reliable Databricks-Machine-Learning-Professional Test Tips 📣 Enter ☀ www.examcollectionpass.com ️☀️ and search for ▷ Databricks-Machine-Learning-Professional ◁ to download for free 🧡Databricks-Machine-Learning-Professional Valid Exam Questions
- Exam Databricks-Machine-Learning-Professional Material ⚗ Valid Test Databricks-Machine-Learning-Professional Experience 🏑 Databricks-Machine-Learning-Professional Test Vce Free 🌽 ▷ www.pdfvce.com ◁ is best website to obtain ▶ Databricks-Machine-Learning-Professional ◀ for free download 🥦Knowledge Databricks-Machine-Learning-Professional Points
- Databricks-Machine-Learning-Professional Brain Exam 🚥 Unlimited Databricks-Machine-Learning-Professional Exam Practice 🌁 Reliable Databricks-Machine-Learning-Professional Test Tips 🎫 Download 「 Databricks-Machine-Learning-Professional 」 for free by simply searching on ▶ www.examcollectionpass.com ◀ 🍂Exam Databricks-Machine-Learning-Professional Material
- 100% Pass-Rate New Databricks-Machine-Learning-Professional Test Question Spend Your Little Time and Energy to Pass Databricks-Machine-Learning-Professional exam one time 🐍 Immediately open 「 www.pdfvce.com 」 and search for ( Databricks-Machine-Learning-Professional ) to obtain a free download 🎊Frenquent Databricks-Machine-Learning-Professional Update
- Overcoming Challenges with www.vceengine.com Databricks Databricks-Machine-Learning-Professional 😢 Search on ➽ www.vceengine.com 🢪 for ✔ Databricks-Machine-Learning-Professional ️✔️ to obtain exam materials for free download 🌛Databricks-Machine-Learning-Professional Exam Course
- Databricks-Machine-Learning-Professional New Test Bootcamp 🐑 Study Databricks-Machine-Learning-Professional Reference 🥓 Exam Databricks-Machine-Learning-Professional Preparation 📀 Open ☀ www.pdfvce.com ️☀️ enter “ Databricks-Machine-Learning-Professional ” and obtain a free download ❔Reliable Databricks-Machine-Learning-Professional Test Tips
- Quiz 2026 Databricks Useful New Databricks-Machine-Learning-Professional Test Question 🧑 Search for ➠ Databricks-Machine-Learning-Professional 🠰 and download it for free immediately on ➡ www.pdfdumps.com ️⬅️ 🔭Practice Databricks-Machine-Learning-Professional Exam Fee
- Reliable Databricks-Machine-Learning-Professional Test Tips 🌸 Latest Databricks-Machine-Learning-Professional Test Notes 🈺 Databricks-Machine-Learning-Professional Exam Course 🏄 Easily obtain free download of ▶ Databricks-Machine-Learning-Professional ◀ by searching on ➡ www.pdfvce.com ️⬅️ 🔦Exam Databricks-Machine-Learning-Professional Preparation
- Quiz 2026 Databricks Useful New Databricks-Machine-Learning-Professional Test Question 🍇 Open ✔ www.prep4sures.top ️✔️ enter { Databricks-Machine-Learning-Professional } and obtain a free download 🦖Latest Databricks-Machine-Learning-Professional Test Notes
- New New Databricks-Machine-Learning-Professional Test Question | Valid Exam Databricks-Machine-Learning-Professional Simulator: Databricks Certified Machine Learning Professional 100% Pass 🐔 Search on ✔ www.pdfvce.com ️✔️ for ▶ Databricks-Machine-Learning-Professional ◀ to obtain exam materials for free download 🏓Unlimited Databricks-Machine-Learning-Professional Exam Practice
- Unlimited Databricks-Machine-Learning-Professional Exam Practice ☀ Reliable Databricks-Machine-Learning-Professional Test Tips 😈 New Databricks-Machine-Learning-Professional Test Discount 🌈 Simply search for [ Databricks-Machine-Learning-Professional ] for free download on ➽ www.pdfdumps.com 🢪 📁Knowledge Databricks-Machine-Learning-Professional Points
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
BONUS!!! Download part of TestPDF Databricks-Machine-Learning-Professional dumps for free: https://drive.google.com/open?id=1D1XGnm5BWv3vj5SQKCr50R7XGOyDh512