Only with high quality and valid information of our AI-200 exam braindumps, our candidates can successfully pass their exams. At the same time, own to our professional experts constantly improvement on the design of the AI-200 study materials, we have developed three versions of layouts: PDF, Software and APP online. Though the content of them are the same, the different layouts provide lots of conveniences out of your imagination. Just have a try and you will love our AI-200 Practice Engine.
| Section | Weight | Objectives |
|---|---|---|
| Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
| Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
| Develop AI solutions using Azure data services | 30% | - Implement vector-enabled databases
|
| Integrate backend services and build event-driven architectures | 25% | - Implement messaging and event systems
|
Considering that different customers have various needs, we provide three versions of AI-200 test torrent available--- PDF version, PC Test Engine and Online Test Engine versions. One of the most favorable demo--- PDF version, in the form of Q&A, can be downloaded for free. This kind of AI-200 exam prep is printable and has instant access to download, which means you can study at any place at any time. PC version of AI-200 exam question stimulates real exam environment and supports MS operating system, which is a more practical way to study for the exam. In addition, the online test engine of the AI-200 Exam Prep seems to get a higher expectation among most candidates, on account that almost every user is accustomed to studying or working with APP in their portable phones or tablet PC. We assure you that each version has the same study materials, just choose one you like.
NEW QUESTION # 114
You are provisioning and configuring a Service Bus processor for AI batch jobs.
The processor must connect to an existing queue, register handlers for message and error processing, and then begin receiving messages.
You need to provision and configure the Service Bus processor for message and error handling.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.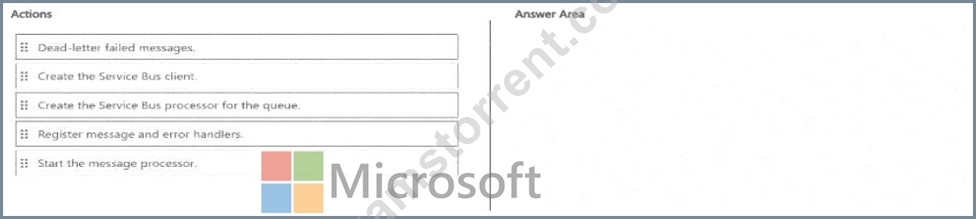
Answer:
Explanation: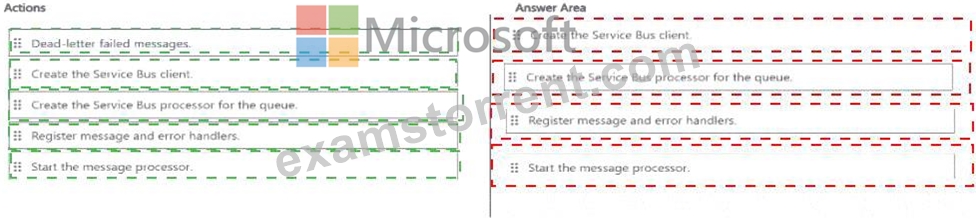
Explanation: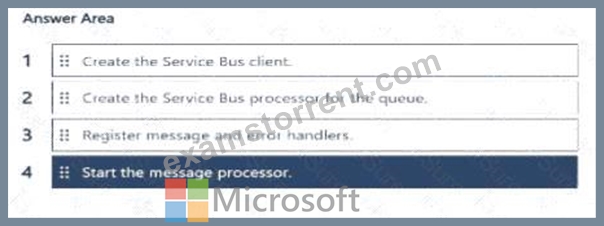
Verified Answer: 1) Create the Service Bus client; 2) create the queue processor/receiver; 3) register message and error handlers; 4) start the message processor.
Detailed Explanation: The processor depends on a namespace client/connection, so the client is created first.
Next, the queue-specific processor or receiver is created from that client. Message and error callbacks must be registered before processing starts so incoming messages and failures have defined handlers. Starting the processor is therefore the final step. Dead-lettering failed messages is an optional application settlement decision and is not a prerequisite for constructing and starting the processor.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Service Bus message transfers, locks, and settlement
NEW QUESTION # 115
You have container source code stored in a Git repository.
The container registry must automatically build and store a new container image whenever a developer commits code to the Git repository.
You must minimize the use of an external build infrastructure.
You need to configure Azure Container Registry (ACR) to manage the build process natively and automatically.
Which two ACR components should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,B
Explanation:
The two components that should be included in the solution are a Source-triggered task and a Webhook.
Source-triggered task: This component fulfills the requirement natively within Azure. An Azure Container Registry (ACR) Task can monitor a Git repository (like GitHub or Azure Repos).
Whenever a developer commits code, it automatically triggers a native build inside Azure without needing external CI/CD build infrastructure.
Webhook: This is the underlying mechanism that connects your Git repository to ACR. When a commit occurs, the Git repository sends a webhook notification to Azure Container Registry to signal the source-triggered task to start building the new image.
Reference:
https://learn.microsoft.com/en-us/azure/container-registry/container-registry-tutorial-build-task
NEW QUESTION # 116
You must ensure that PII (personally identifiable information) such as names and phone numbers is automatically redacted from support ticket transcripts before they are stored. What should you use?
Answer: D
Explanation:
Azure AI Language's PII detection feature identifies and can redact categories of sensitive information (names, phone numbers, SSNs, etc.) from unstructured text, which is the purpose- built service for this scenario.
NEW QUESTION # 117
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Hotspot Question
You need to optimize secure database connectivity from the containerized Recommendation API.
How should you configure the application? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.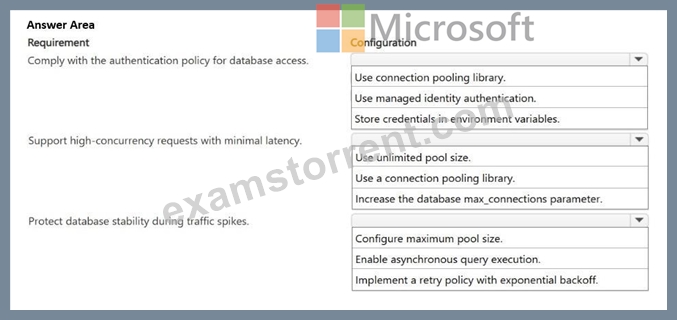
Answer:
Explanation: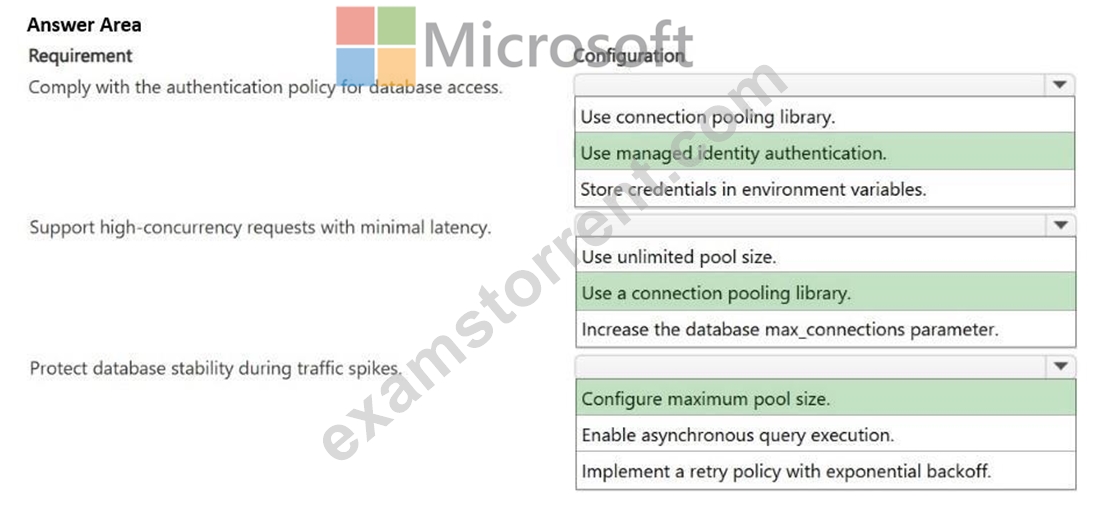
Explanation:
Box 1: Use managed identity authentication.
Scenario: Identity: Use managed identities for all service-to-service and service-to-database authentication. Plain-text credentials in configuration files are strictly prohibited.' Box 2: Use a connection pooling library Scenario: Environment: Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
To support high-concurrency requests with minimal latency on Azure Database for PostgreSQL, the best action is to use a connection pooling library (or leverage Azure's built-in PgBouncer feature).
Eliminates Connection Overhead:
PostgreSQL utilizes a process-per-connection model. Forking a new backend process for every incoming request introduces substantial CPU and memory overhead, severely degrading latency under high concurrency. A connection pool keeps a warm set of reusable database sessions active.
Optimized for Azure: Microsoft provides a built-in managed PgBouncer integration for Azure Database for PostgreSQL. Enabling it in transaction mode allows the database to accept thousands of concurrent client connections while keeping actual backend processes lean and stable Box 3: Configure a maximum pool size Configure a maximum pool size is the best action to directly protect database stability during sudden traffic spikes.
Prevents Resource Exhaustion: Traffic spikes naturally lead to a surge in connection requests.
Unchecked connections consume substantial RAM and CPU overhead, which can crash the database or trigger severe latency. Limiting the pool size stops the "thundering herd" problem Acts as a Shock Absorber: When the pool hits its maximum limit, extra client requests are safely queued at the application or connection pooling layer (like Azure's built-in PgBouncer proxy) rather than overwhelming the database backend Reference:
https://docs.azure.cn/en-us/postgresql/connectivity/concepts-pgbouncer
https://learn.microsoft.com/en-au/answers/questions/5884412/best-practise-azure-postgresql-flexible-server-max
NEW QUESTION # 118
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Hotspot Question
You need to configure the database resources for the Azure Database for PostgreSQL instance.
How should you complete the configuration to meet the business and technical requirements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.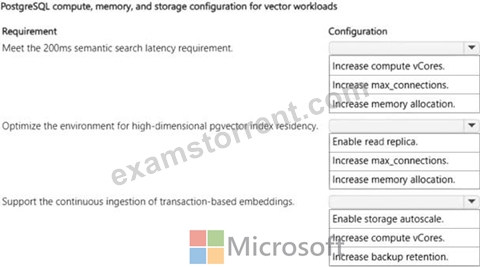
Answer:
Explanation:
Explanation:
Box 1: Increase compute vCores
Technical requirements, Performance: Semantic search latency must remain under 200 milliseconds at peak load.
To reduce semantic search latency under 200 milliseconds at peak load, the best action is to Increase compute vCores.
Vector similarity search and semantic retrieval are highly CPU-intensive operations. The math behind vector distance calculations (such as Cosine similarity, Dot Product, or Euclidean distance) relies heavily on mathematical operations executed per query. When a system experiences peak load, compute vCores easily become the primary bottleneck. Adding more vCores directly increases parallel processing capacity, dramatically shortening the execution time of similarity calculations and keeping retrieval latency within the required 200 ms SLA.
Box 2: Increase memory allocation
The best action is to increase memory allocation.
High-dimensional vector indexes (such as HNSW or IVFFlat managed by the pgvector extension) are highly resource-intensive and rely heavily on RAM. To maintain fast vector similarity searches and avoid high-latency disk operations, the entire vector index must fit into memory (RAM residency). Scaling up the database instance's memory directly expands the PostgreSQL shared buffers and cache, ensuring the high-dimensional index remains resident in RAM for rapid semantic retrieval.
Box 3: Enable storage autoscale
Enable storage autoscale is the best action to support the continuous ingestion of transaction- based embeddings.
Continuous Ingestion Demands Dynamic Space: Continuous transaction processing causes vector databases (such as Azure Database for PostgreSQL with pgvector or Azure SQL Database) to expand constantly over time.
Preventing Ingestion Failures: If storage reaches capacity limits, the database switches into a read-only state. This immediately fails and halts all incoming real-time embedding write operations. Enabling storage autoscale allows the environment to dynamically provision storage on the fly without downtime.
Reference:
https://dl.acm.org/doi/10.1145/3695053.3731013
https://learn.microsoft.com/en-us/training/paths/develop-ai-solutions-azure-database-postgresql/
https://learn.microsoft.com/en-us/azure/architecture/guide/technology-choices/vector-search
NEW QUESTION # 119
......
In order to make sure your whole experience of buying our AI-200 prep guide more comfortable, our company will provide all people with 24 hours online service. The experts and professors from our company designed the online service system for all customers. If you decide to buy the AI-200 study braindumps from our company, we can make sure that you will have the opportunity to enjoy the best online service provided by our excellent online workers. If you purchasing the AI-200 Test Practice files designed by many experts and professors from our company, we can promise that our online workers are going to serve you day and night during your learning period. If you have any questions about our study materials, you can send an email to us, and then the online workers from our company will help you solve your problem in the shortest time. So do not hesitate to buy our AI-200 prep guide.
AI-200 Unlimited Exam Practice: https://www.examstorrent.com/AI-200-exam-dumps-torrent.html