If you are interested in Soft test engine of DP-750 practice questions, you should know below information better. Soft test engine should be downloaded in personal computer first time online, and then install. After installment you can use DP-750 practice questions offline. You can also copy to other electronic products such as Phone, Ipad. On the hand, our exam questions can be used on more than 200 personal computers. If you purchase Soft test engine of DP-750 Practice Questions for your companies, it will be very useful.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
>> Reliable DP-750 Exam Blueprint <<
If you are preparing for the practice exam, we can make sure that the DP-750 test practice files from our company will be the best choice for you, and you cannot find the better study materials than our company'. There are a lot of advantages of our DP-750 preparation materials, and you can free download the demo of our DP-750 training guide to know the special functions of our DP-750 prep guide in detail. And you will know the quality of our DP-750 study prep as well. We are hopeful that you will like our DP-750 exam questions.
NEW QUESTION # 80
You have an Azure Databricks workspace that contains a Git folder and uses Azure Repos as the Git provider.
From the main branch, you create a branch named Branch1. You commit changes to Branch1.
You need to incorporate the changes from Branch1 into main. The solution must preserve the commit history in the repository.
Which command should you run?
Answer: A
Explanation:
To incorporate changes from your feature branch into the main branch while keeping every individual commit intact, you must use a fast-forward merge or a standard merge commit.
In the Azure Databricks Git folders UI or via standard Git operations, use the following command:
The Correct Command: git merge <branch-name>
Preserves History: Unlike a squash merge, a standard merge keeps all individual commit messages, authors, and timestamps.
Maintains Timeline: It seamlessly integrates the exact commit graph from your feature branch into the main branch.
Reference:
https://docs.databricks.com/aws/en/repos/git-operations-with-repos
NEW QUESTION # 81
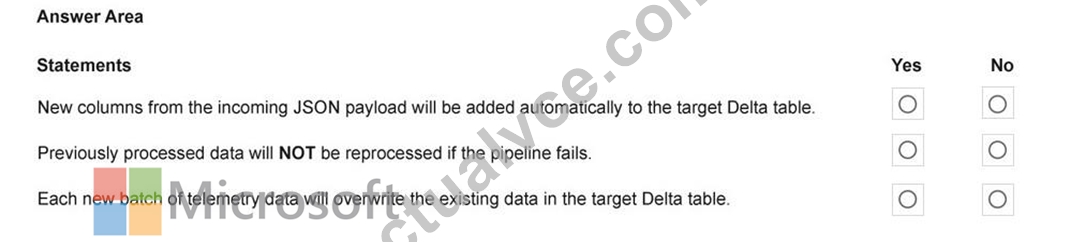
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to run the following PySpark code.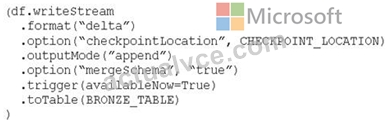
Answer:
Explanation: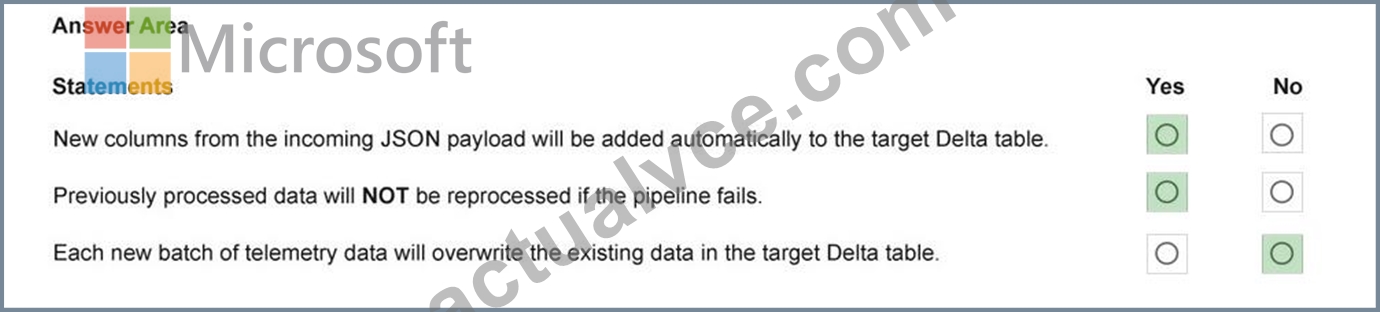
NEW QUESTION # 82
You have an Azure Databricks workspace that contains multiple all-purpose clusters.
You discover that some clusters remain idle for long periods after users finish their work.
You need to reduce compute costs without affecting active workloads.
What should you do?
Answer: A
Explanation:
To reduce compute costs from idle clusters without impacting active workloads, you must configure Auto-Termination and use Cluster Policies.
Core Remedies
*-> Auto-Termination: Set a strict inactivity timeout (e.g., 20-30 minutes) on all-purpose clusters to automatically shut them down when idle.
Cluster Policies: Enforce maximum auto-termination limits across the workspace so users cannot disable or set excessively long idle timeouts.
Single User Access Mode: Use this mode where possible, as it tracks idleness more accurately than Shared mode by monitoring the specific user's activity.
Reference:
https://medium.com/@sujathamudadla1213/databricks-lakehouse-platform-describe-how- clusters-are-terminated-and-the-impact-of-terminating-a-b6236689fd2e
NEW QUESTION # 83
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table1 is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table1.
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
Answer: C
Explanation:
Schema evolution allows the target Delta table to incorporate compatible new source columns instead of failing when the incoming schema changes. This is the appropriate response to additive schema drift and avoids manually rebuilding tables whenever the source evolves. Creating a separate table for every schema version would fragment the dataset and increase operational effort. Disabling schema enforcement removes valuable protection against incompatible or corrupt data rather than handling legitimate evolution safely. Row filters operate on records and cannot remove an unexpected column from the incoming schema. With schema evolution enabled, the pipeline can detect new fields, update the target schema, and continue processing while retaining Delta Lake's transactional guarantees. The solution therefore supports changing source data without sacrificing the managed-table architecture.
NEW QUESTION # 84
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a Databricks access connector.
Does this meet the goal?
Answer: A
Explanation:
The correct answer is B - No.
A Databricks Access Connector is an Azure resource that provides a managed identity for Databricks to authenticate to Azure Storage services. It is an authentication bridge - nothing more. Creating one doesn't register any external database, doesn't create any Unity Catalog objects representing DB1, and doesn't enable querying of SQL Server data from Databricks.
An Access Connector is a prerequisite for setting up storage credentials and external locations in Unity Catalog (to access ADLS Gen2, for example), but it has no role in Lakehouse Federation or foreign catalog creation. It cannot expose an external database's schemas and tables in Unity Catalog alongside native objects.
The correct solution for this scenario is a foreign catalog (Q47), which requires a connection object pointing to DB1 - not an Access Connector.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/storage-credentials
NEW QUESTION # 85
......
To effectively getting ready for Microsoft DP-750 test, do you know what tools are worth using? Let me tell you. ActualVCE Microsoft DP-750 pdf dumps are the most credible. The exam dumps is rare certification training materials which are researched by IT elite. ActualVCE DP-750 braindump has a high hit rate. 100% sail through your exam. This is because IT experts can master the question point well, so that all questions the candidates may come across in the actual test are included in ActualVCE exam dumps. Is it amazing? But it is true. After you use our dumps, you will believe what I am saying.
Study DP-750 Reference: https://www.actualvce.com/Microsoft/DP-750-valid-vce-dumps.html