AI-300試験に合格して証明書を取得する方法に関する質問を検討していますか?最良の答えは、AI-300クイズトレントをダウンロードして学習することです。 AI-300試験の質問は、必要なものを短時間で取得するのに役立ちます。 AI-300トレーニング準備を購入した後、JPTestKingダウンロードしてインストールするのに少し時間が必要です。その後、学習するのに約20〜30時間かかります。 AI-300試験ガイドをご覧いただき、貴重な時間を割いていただければ幸いです。
| Section | Objectives |
|---|---|
| Design and implement an MLOps infrastructure | - Manage environments, data stores, and model registries - Set up Azure Machine Learning workspace and compute targets - Implement security, governance, and compliance for MLOps - Configure source control, CI/CD pipelines, and automation for ML workflows |
| Implement machine learning model lifecycle and operations | - Train, register, and version models using Azure Machine Learning - Retrain, update, and manage model versions in production - Deploy models to real-time and batch endpoints - Monitor model performance, data drift, and operational health |
| Implement generative AI quality assurance and observability | - Implement logging, tracing, and telemetry for GenAI applications - Conduct red teaming, adversarial testing, and content filtering - Evaluate generative AI outputs for quality, safety, and grounding - Monitor latency, token usage, cost, and error rates |
| Optimize generative AI systems and model performance | - Tune prompts, system messages, and grounding strategies - Implement cost management and scaling strategies for GenAI workloads - Optimize inference performance, caching, and throughput - Fine-tune and distill models for specific use cases |
| Design and implement a GenAIOps infrastructure | - Manage API keys, rate limits, and responsible AI guardrails - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Configure prompt orchestration, prompt flows, and agent frameworks - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search |
他のたくさんのトレーニング資料より、JPTestKingのMicrosoftのAI-300試験トレーニング資料は一番良いものです。IT認証のトレーニング資料が必要としたら、JPTestKingのMicrosoftのAI-300試験トレーニング資料を利用しなければ絶対後悔しますよ。JPTestKingのトレーニング資料を選んだら、あなたは一生で利益を受けることができます。
質問 # 132
You have an Azure Machine Learning workspace. You are running an experiment on your local computer.
You need to use MLflow Tracking to store metrics and artifacts from your local experiment runs in the workspace.
In which order should you perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.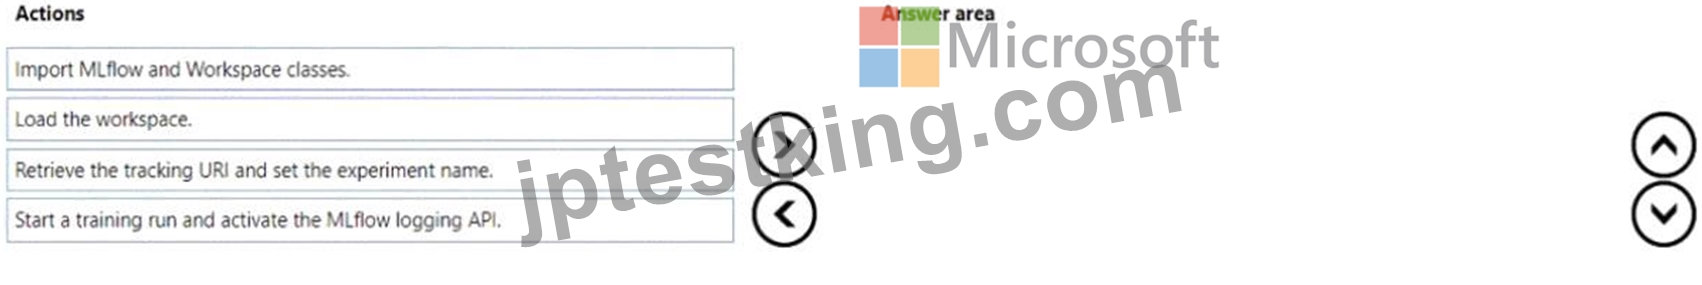
正解:
解説: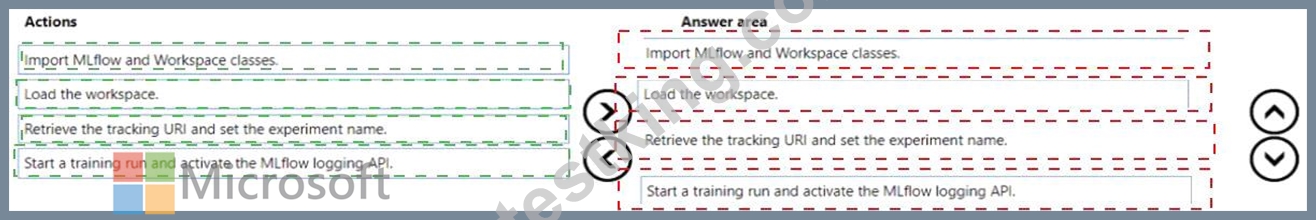
Explanation: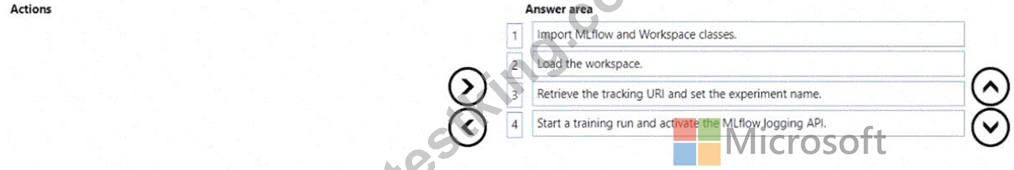
質問 # 133
Fabrikam Inc. must improve its deployment process because traditional machine learning models are deployed manually and the organization has limited rollback capability .
You need to recommend a deployment approach that supports staged rollout and rollback while minimizing operational overhead.
Which deployment approach should you recommend?
正解:B
解説:
Managed online endpoints with traffic splitting are the best fit because Azure Machine Learning supports multiple deployments behind a single online endpoint and allows production traffic to be distributed between them. This enables a blue-green or progressive rollout strategy : deploy the new model version alongside the current version, validate it independently, send a small percentage of production traffic to it, monitor behavior, and then gradually increase traffic. If problems occur, traffic can be redirected immediately to the previous deployment, providing a practical rollback mechanism.
This approach also aligns with Fabrikam's requirement to favor managed services and automation because the team has limited Azure DevOps experience. Managed online endpoints handle much of the serving, scaling, security, and monitoring infrastructure automatically and support both traffic splitting and mirrored traffic for safer validation.
Option B can also implement blue-green deployment, but AKS introduces substantially more infrastructure and operational management than Fabrikam requires. Option A would require custom deployment, routing, scaling, and rollback logic. Option D is intended for asynchronous batch inference rather than staged real-time production serving.
Study Guide Reference: Implement machine learning model lifecycle and operations - managed online endpoints, multiple deployments, traffic splitting, blue-green deployment, staged rollout, monitoring, and rollback.
質問 # 134
A team deploys a generative AI application that uses a model deployed in Microsoft Foundry.
The application must support latency monitoring under production load.
You need to enable performance observability.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.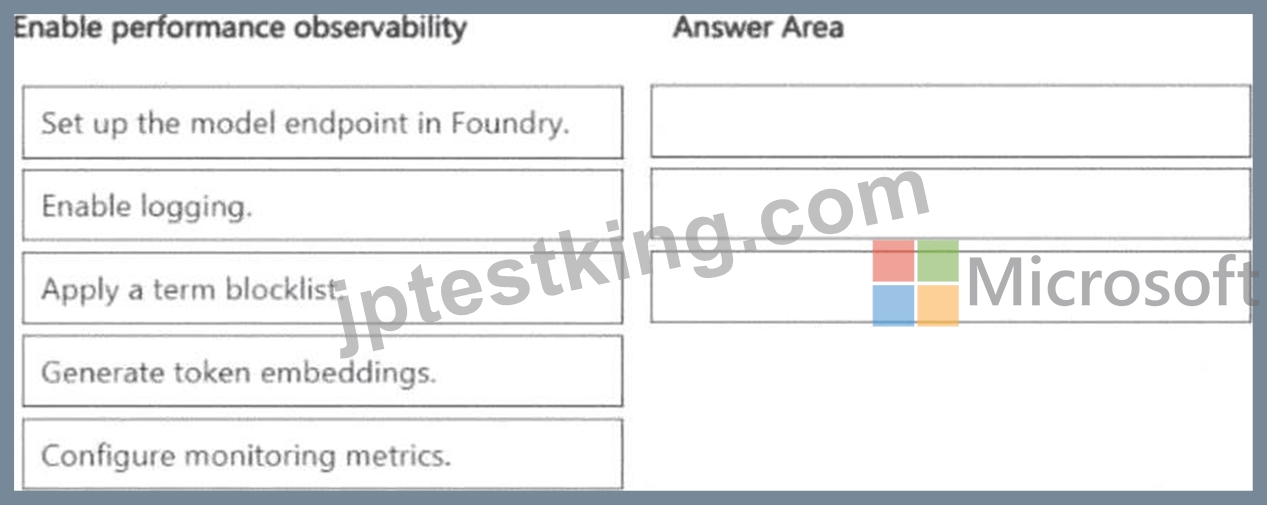
正解:
解説: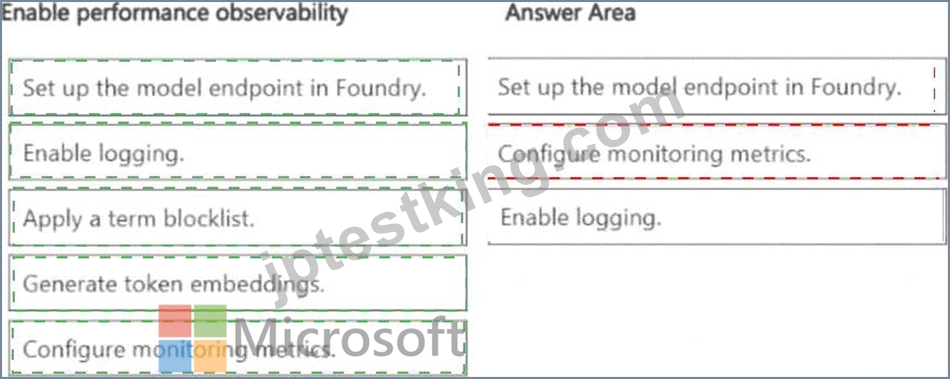
Explanation:
Microsoft ' s observability guidance for Azure AI Foundry applications describes a three-stage activation sequence. First, enable Tracing in the Microsoft Foundry project settings before deployment - Tracing instruments the application ' s LLM calls with OpenTelemetry-compatible spans that capture timing data for each step in the flow. Second, deploy the application to a production endpoint so that real traffic flows through the instrumented code path - without actual production traffic, there is no latency data to observe.
Third, configure Azure Monitor and Application Insights to receive, aggregate, and visualize the telemetry emitted by Tracing. Azure Monitor ' s metrics explorer and Application Insights ' performance views display p50, p95, and p99 latency distributions over time, enabling the team to identify latency regressions and set alert thresholds. This sequence - instrument, deploy, visualize - is the canonical Microsoft path to production AI performance observability.
Microsoft Learn Reference Topic: Monitor generative AI applications with Azure Monitor and Microsoft Foundry Tracing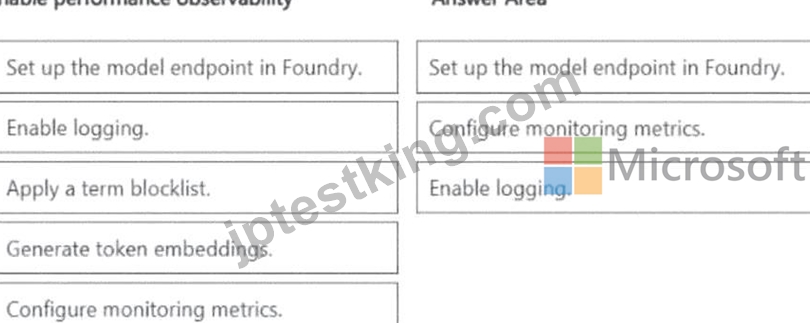
質問 # 135
Hotspot Question
You monitor an Azure Machine Learning classification training experiment named train_classification on Azure Notebooks.
You must store a table named table as an artifact in Azure Machine Learning Studio during model training.
You need to collect and list the metrics by using MLflow.
How should you complete the code segment? To answer, select the appropriate option in the answer area.
NOTE: Each correct selection is worth one point.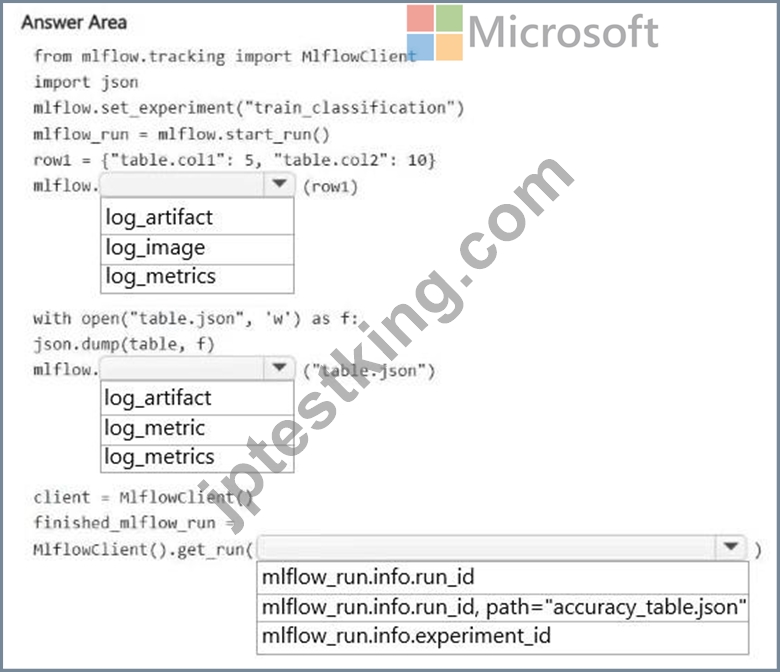
正解:
解説: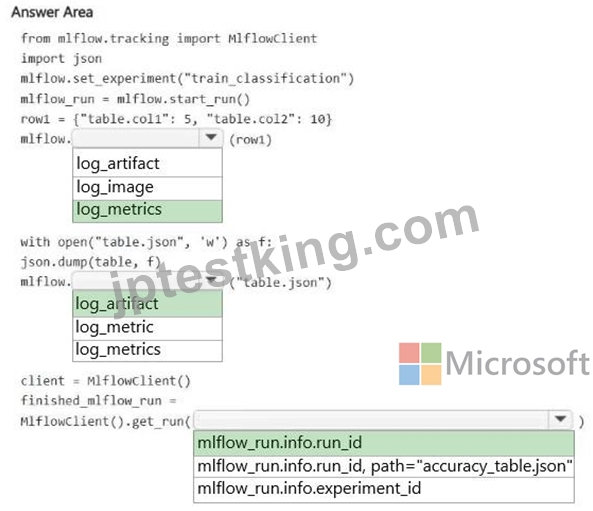
Explanation:
Box 1: log_metrics
Log Metrics dictionary
The dictionary row1 contains key-value pairs representing metrics. The mlflow.log_metrics() function is used to log multiple metrics simultaneously.
Box 2: log_artifact
Save Table Artifact
The code writes a JSON file locally and needs to upload it to the experiment run. The mlflow.log_artifact() function logs a local file or directory as an artifact in Azure Machine Learning Studio.
Box 3: mlflow_run.info.run_id
Retrieve Run ID
To fetch the finalized run data using the MlflowClient, you need to pass the unique run ID string.
This identifier is accessed via the active run object using mlflow_run.info.run_id. Note that you also need to use the instantiated client object variable instead of the class name MlflowClient to call the method correctly.
Reference:
https://levelup.gitconnected.com/mlops-mastering-mlflow-unlocking-efficient-model-management-and-experiment-tracking-d9d0e71cc697
質問 # 136
-
A team is standardizing MLOps practices by using automated deployments.
The team requires infrastructure to be defined declaratively and deployed through automation pipelines.
You need to configure infrastructure deployment.
What should you configure for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.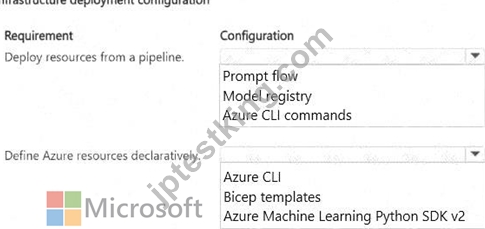
正解:
解説: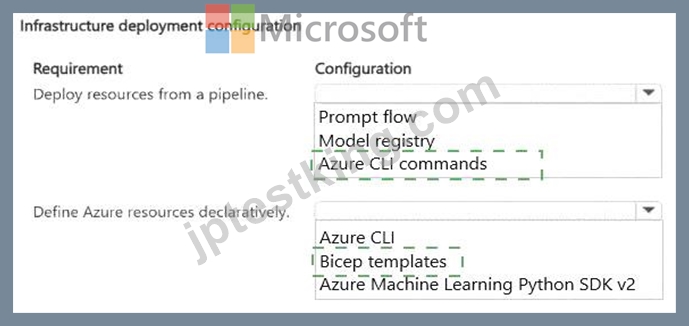
Explanation:
Deploy resources from a pipeline: Azure CLI Commands
Define Azure resources declaratively: Bicep templates
Azure CLI Commands should be used to deploy resources from an automation pipeline. Azure Machine Learning supports integration with CI/CD platforms such as Azure DevOps and GitHub Actions, and Microsoft documents the Azure CLI with the Machine Learning extension as a standard mechanism for automating resource provisioning, training pipelines, model deployment, and other MLOps operations. Azure CLI commands can be executed non-interactively within pipeline stages, making them appropriate for repeatable automated deployments.
Bicep templates should be used to define Azure infrastructure declaratively. Bicep is Microsoft ' s domain- specific Infrastructure-as-Code language for Azure Resource Manager. Instead of specifying individual imperative provisioning steps, a Bicep file describes the desired state of Azure resources. Azure Resource Manager then determines the deployment operations required to reach that state. This provides repeatable, version-controlled, consistent infrastructure across development, testing, and production environments.
Bicep deployments can also be invoked directly through Azure CLI commands such as az deployment group create, allowing the declarative infrastructure definition and automated deployment mechanism to work together in an MLOps CI/CD pipeline.
Study Guide Reference: Design and implement an MLOps infrastructure - Infrastructure as Code, Bicep, Azure CLI, automated deployment pipelines, and reproducible environment provisioning.
質問 # 137
......
AI-300「Operationalizing Machine Learning and Generative AI Solutions」はMicrosoftの一つ認証試験として、もしMicrosoft認証試験に合格してIT業界にとても人気があってので、ますます多くの人がAI-300試験に申し込んで、AI-300試験は簡単ではなくて、時間とエネルギーがかかって用意しなければなりません。
AI-300日本語版サンプル: https://www.jptestking.com/AI-300-exam.html