BONUS!!! Download part of ExamDiscuss Databricks-Certified-Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1Flz0A5oE7PHoyMnjJ-0SaUD35FIkmCZO
The research and production of our Databricks-Certified-Data-Engineer-Associate study materials are undertaken by our first-tier expert team. The clients can have a free download and tryout of our Databricks-Certified-Data-Engineer-Associate study materials before they decide to buy our products. They can use our products immediately after they pay for the Databricks-Certified-Data-Engineer-Associate study materials successfully. If the clients are unlucky to fail in the test we will refund them as quickly as we can. There are so many advantages of our products that we can’t summarize them with several simple words. You’d better look at the introduction of our Databricks-Certified-Data-Engineer-Associate Study Materials in detail as follow by yourselves.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Development and Ingestion | 30% | - Notebook development fundamentals
|
| Topic 2: Productionizing Data Pipelines | 18% | - Monitoring and troubleshooting
|
| Topic 3: Databricks Intelligence Platform | 10% | - Platform architecture and core concepts
|
| Topic 4: Data Governance & Quality | 11% | - Data quality and reliability
|
| Topic 5: Data Processing & Transformations | 31% | - Query optimization and performance
|
>> Databricks Databricks-Certified-Data-Engineer-Associate Reliable Test Answers <<
The Databricks-Certified-Data-Engineer-Associate exam questions are the ideal and recommended study material for quick and easiest Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam dumps preparation. The Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) practice questions are designed and verified by qualified and renowned Databricks Certification Exams trainers. They work closely and check all Databricks Databricks-Certified-Data-Engineer-Associate Exam Dumps step by step. They also ensure the best possible answer for all Databricks-Certified-Data-Engineer-Associate exam questions and strive hard to maintain the top standard of Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam dumps all the time.
NEW QUESTION # 243
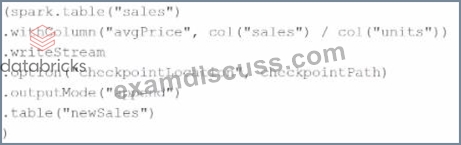
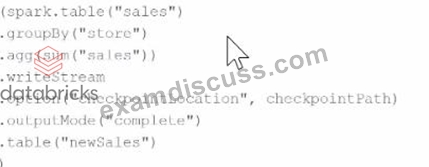
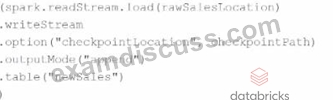
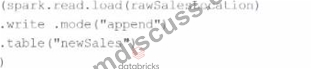
Which query is performing a streaming hop from raw data to a Bronze table?
Answer: C
Explanation:
The query performing a streaming hop from raw data to a Bronze table is identified by using the Spark streaming read capability and then writing to a Bronze table. Let's analyze the options:
Option A: Utilizes .writeStream but performs a complete aggregation which is more characteristic of a roll-up into a summarized table rather than a hop into a Bronze table.
Option B: Also uses .writeStream but calculates an average, which again does not typically represent the raw to Bronze transformation, which usually involves minimal transformations.
Option C: This uses a basic .write with .mode("append") which is not a streaming operation, and hence not suitable for real-time streaming data transformation to a Bronze table.
Option D: It employs spark.readStream.load() to ingest raw data as a stream and then writes it out with .writeStream, which is a typical pattern for streaming data into a Bronze table where raw data is captured in real-time and minimal transformation is applied. This approach aligns with the concept of a Bronze table in a modern data architecture, where raw data is ingested continuously and stored in a more accessible format.
Reference:
Databricks documentation on Structured Streaming: Structured Streaming in Databricks
NEW QUESTION # 244
In order for Structured Streaming to reliably track the exact progress of the processing so that it can handle any kind of failure by restarting and/or reprocessing, which of the following two approaches is used by Spark to record the offset range of the data being processed in each trigger?
Answer: E
Explanation:
Structured Streaming uses checkpointing and write-ahead logs to record the offset range of the data being processed in each trigger. This ensures that the engine can reliably track the exact progress of the processing and handle any kind of failure by restarting and/or reprocessing. Checkpointing is the mechanism of saving the state of a streaming query to fault-tolerant storage (such as HDFS) so that it can be recovered after a failure. Write-ahead logs are files that record the offset range of the data being processed in each trigger and are written to the checkpoint location before the processing starts. These logs are used to recover the query state and resume processing from the last processed offset range in case of a failure. References: Structured Streaming Programming Guide, Fault Tolerance Semantics
NEW QUESTION # 245
In which of the following scenarios should a data engineer use the MERGE INTO command instead of the INSERT INTO command?
Answer: C
Explanation:
The MERGE INTO command is used to perform upserts, which are a combination of insertions and updates, based on a source table into a target Delta table1. The MERGE INTO command can handle scenarios where the target table cannot contain duplicate records, such as when there is a primary key or a unique constraint on the target table. The MERGE INTO command can match the source and target rows based on a merge condition and perform different actions depending on whether the rows are matched or not. For example, the MERGE INTO command can update the existing target rows with the new source values, insert the new source rows that do not exist in the target table, or delete the target rows that do not exist in the source table1.
The INSERT INTO command is used to append new rows to an existing table or create a new table from a query result2. The INSERT INTO command does not perform any updates or deletions on the existing target table rows. The INSERT INTO command can handle scenarios where the location of the data needs to be changed, such as when the data needs to be moved from one table to another, or when the data needs to be partitioned by a certain column2. The INSERT INTO command can also handle scenarios where the target table is an external table, such as when the data is stored in an external storage system like Amazon S3 or Azure Blob Storage3. The INSERT INTO command can also handle scenarios where the source table can be deleted, such as when the source table is a temporary table or a view4. The INSERT INTO command can also handle scenarios where the source is not a Delta table, such as when the source is a Parquet, CSV, JSON, or Avro file5.
:
1: MERGE INTO | Databricks on AWS
2: [INSERT INTO | Databricks on AWS]
3: [External tables | Databricks on AWS]
4: [Temporary views | Databricks on AWS]
5: [Data sources | Databricks on AWS]
NEW QUESTION # 246
Which of the following describes the relationship between Bronze tables and raw data?
Answer: B
NEW QUESTION # 247
A data engineer is using Spark SQL to analyze a large dataset stored in Delta format. The engineer notices that queries filtering on partition columns run significantly faster. What is the primary reason for this performance improvement?
Answer: A
NEW QUESTION # 248
......
People always want to prove that they are competent and skillful in some certain area. The ways to prove their competences are varied but the most direct and convenient method is to attend the Databricks-Certified-Data-Engineer-Associate certification exam and get some certificate. Passing the Databricks-Certified-Data-Engineer-Associate certification can prove that you are very competent and excellent and you can also master useful knowledge and skill through passing the Databricks-Certified-Data-Engineer-Associate test. Purchasing our Databricks-Certified-Data-Engineer-Associate guide torrent can help you pass the Databricks-Certified-Data-Engineer-Associate exam and it costs little time and energy.
Discount Databricks-Certified-Data-Engineer-Associate Code: https://www.examdiscuss.com/Databricks/exam/Databricks-Certified-Data-Engineer-Associate/
BONUS!!! Download part of ExamDiscuss Databricks-Certified-Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1Flz0A5oE7PHoyMnjJ-0SaUD35FIkmCZO