100% Pass Quiz Databricks - Databricks-Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Exam Unparalleled Test Voucher

Work hard and practice with our Databricks Databricks-Certified-Data-Engineer-Professional dumps till you are confident to pass the Databricks Databricks-Certified-Data-Engineer-Professional exam. And that too with flying colors and achieving the Databricks Certified Data Engineer Professional Exam certification on the first attempt. You will identify both your strengths and shortcomings when you utilize Databricks Databricks-Certified-Data-Engineer-Professional Practice Exam software.
| Section | Objectives |
|---|
| Data Modeling and Transformation | - Performance optimization techniques
- Spark SQL transformations
- Dimensional modeling concepts
|
| Delta Lake and Data Management | - Schema evolution and enforcement
- Delta Lake transactions and ACID properties
- Time travel and versioning
|
| Databricks Lakehouse Platform Architecture | - Medallion architecture (Bronze, Silver, Gold)
- Workspace and cluster architecture
- Data governance concepts (Unity Catalog basics)
|
| Production Pipelines and Orchestration | - Error handling and recovery strategies
- Databricks Workflows
- Job scheduling and monitoring
|
| Data Ingestion and Processing | - Batch and streaming ingestion with Auto Loader
- Structured Streaming fundamentals
- ETL pipeline design patterns
|
>> Databricks-Certified-Data-Engineer-Professional Test Voucher <<
100% Pass Quiz 2026 High-quality Databricks Databricks-Certified-Data-Engineer-Professional Test Voucher
We provide three versions to let the clients choose the most suitable equipment on their hands to learn the Databricks-Certified-Data-Engineer-Professional study materials such as the smart phones, the laptops and the tablet computers. We provide the professional staff to reply your problems about our study materials online in the whole day and the timely and periodical update to the clients. So you will definitely feel it is your fortune to buy our Databricks-Certified-Data-Engineer-Professional Study Materials.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q241-Q246):
NEW QUESTION # 241
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
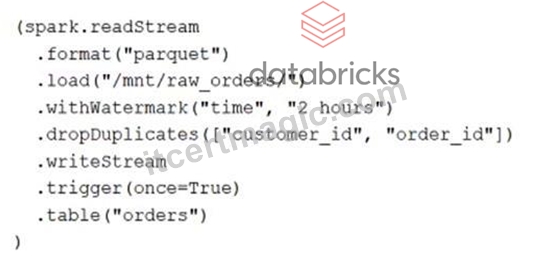
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system.
If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
- A. The orders table will not contain duplicates, but records arriving more than 2 hours late will be ignored and missing from the table.
- B. The orders table will contain only the most recent 2 hours of records and no duplicates will be present.
- C. Duplicate records enqueued more than 2 hours apart may be retained and the orders table may contain duplicate records with the same customer_id and order_id.
- D. All records will be held in the state store for 2 hours before being deduplicated and committed to the orders table.
- E. Duplicate records arriving more than 2 hours apart will be dropped, but duplicates that arrive in the same batch may both be written to the orders table.
Answer: C
NEW QUESTION # 242
The following code has been migrated to a Databricks notebook from a legacy workload:
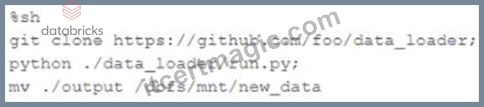
The code executes successfully and provides the logically correct results, however, it takes over
20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
- A. %sh triggers a cluster restart to collect and install Git. Most of the latency is related to cluster startup time.
- B. Instead of cloning, the code should use %sh pip install so that the Python code can get executed in parallel across all nodes in a cluster.
- C. %sh executes shell code on the driver node. The code does not take advantage of the worker nodes or Databricks optimized Spark.
- D. Python will always execute slower than Scala on Databricks. The run.py script should be refactored to Scala.
- E. %sh does not distribute file moving operations; the final line of code should be updated to use %fs instead.
Answer: C
Explanation:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
NEW QUESTION # 243
A data governance team at a large enterprise is improving data discoverability across its organization. The team has hundreds of tables in their Databricks Lakehouse with thousands of columns that lack proper documentation. Many of these tables were created by different teams over several years, with missing context about column meanings and business logic. The data governance team needs to quickly generate comprehensive column descriptions for all existing tables to meet compliance requirements and improve data literacy across the organization. They want to leverage modern capabilities to automatically generate meaningful descriptions rather than manually documenting each column, which would take months to complete. Which approach should the team use in Databricks to automatically generate column comments and descriptions for existing tables?
- A. Use the DESCRIBE TABLE command to extract existing schema information and manually write descriptions based on column names and data types.
- B. Use Delta Lake's DESCRIBE HISTORY command to analyze table evolution and infer column purposes from historical changes.
- C. Write custom PySpark code using df.describe() and df.schema to programmatically generate basic statistical descriptions for each column.
- D. Navigate to the table in Databricks Catalog Explorer, select the table schema view, and use the AI Generate option which leverages artificial intelligence to automatically create meaningful column descriptions based on column names, data types, sample values, and data patterns.
Answer: D
Explanation:
The Catalog Explorer provides an AI-powered "AI Generate" capability that automatically creates intelligent column descriptions by analyzing column names, data types, sample values, and observed data patterns. This approach enables rapid, scalable documentation of existing tables, significantly improving data discoverability and compliance without manual effort.
NEW QUESTION # 244
The data science team has created and logged a production model using MLflow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, loads the customers table containing the customer_id key column into a DataFrame, and defines the feature columns needed for the model.
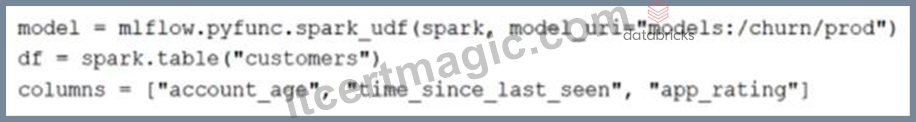
Which code block will output a DataFrame with the schema "customer_id LONG, predictions DOUBLE"?
- A. df.map(lambda x:model(x[columns])).select("customer_id, predictions")
- B. model.predict(df, columns)
- C. df.select("customer_id", model(*columns).alias("predictions"))
- D. df.apply(model, columns).select("customer_id, predictions")
- E. df.select("customer_id", pandas_udf(model, columns).alias("predictions"))
Answer: C
Explanation:
This code block applies the Spark UDF created from the MLflow model to the DataFrame df by selecting the existing customer_id column and the new column produced by the model, which is aliased to predictions. The model(*columns) part is where the UDF is applied to the columns specified in the columns list, and alias("predictions") is used to name the output column of the model's predictions. This will result in a DataFrame with the desired schema: "customer_id LONG, predictions DOUBLE".
NEW QUESTION # 245
A data engineer is evaluating tools to build a production-grade data pipeline. The team must process change data from cloud object storage, filter out or isolate invalid records, and ensure the timely delivery of clean data to downstream consumers. The team is small, under tight deadlines, and wants to minimize operational overhead while keeping pipelines auditable and maintainable.
Which approach should the data engineer implement?
- A. Ingest data directly into Delta tables via Spark jobs, apply data quality filters using UDFs, and use LDP for creating Materialized Views.
- B. Use LDP to build declarative pipelines with Streaming Tables and Materialized Views, leveraging built-in support for data expectations and incremental processing.
- C. Implement ingestion using Auto Loader with Structured Streaming, and manage invalid data handling and table updates using checkpointing and merge logic.
- D. Use a hybrid approach: Ingest with Auto Loader into Bronze tables, then process using SQL queries in Databricks Workflows to generate cleaned Silver and Gold tables on a schedule.
Answer: B
Explanation:
LDP provides a declarative framework for building production-grade pipelines with minimal operational overhead. Streaming Tables and Materialized Views handle incremental processing automatically, while built-in data expectations allow invalid records to be filtered or isolated in a consistent and auditable way. This approach is well suited for small teams under tight deadlines, as it simplifies maintenance, improves reliability, and ensures timely delivery of clean data to downstream consumers.
NEW QUESTION # 246
......
If you are going to buying the Databricks-Certified-Data-Engineer-Professional learning materials online, the safety for the website is quite important. We have professional technicians to examine the website every day, therefore we can provide you with a clean and safe shopping environment. Databricks-Certified-Data-Engineer-Professional learning materials of us contain the most knowledge points for the exam, and it will not only help you to get a certificate successfully but also improve your ability in the process of learning. We also offer you free update for one year if you buy Databricks-Certified-Data-Engineer-Professional Exam Dumps from us.
Exam Databricks-Certified-Data-Engineer-Professional Simulator Fee: https://www.itcertmagic.com/Databricks/real-Databricks-Certified-Data-Engineer-Professional-exam-prep-dumps.html
- New Databricks-Certified-Data-Engineer-Professional Dumps Files 🙇 Databricks-Certified-Data-Engineer-Professional Reliable Exam Testking ⚓ Questions Databricks-Certified-Data-Engineer-Professional Exam 💨 Search for ▶ Databricks-Certified-Data-Engineer-Professional ◀ and download it for free immediately on 「 www.vce4dumps.com 」 🍬Valid Braindumps Databricks-Certified-Data-Engineer-Professional Questions
- Are you ready to prove your technical knowledge and expertise with the Databricks Databricks-Certified-Data-Engineer-Professional certification exam? 🆒 Go to website ▷ www.pdfvce.com ◁ open and search for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 to download for free 🦽Questions Databricks-Certified-Data-Engineer-Professional Exam
- Trustable Databricks-Certified-Data-Engineer-Professional Test Voucher - Easy and Guaranteed Databricks-Certified-Data-Engineer-Professional Exam Success ☮ Search for ▶ Databricks-Certified-Data-Engineer-Professional ◀ and obtain a free download on ➥ www.validtorrent.com 🡄 🟠Databricks-Certified-Data-Engineer-Professional Reliable Exam Test
- 2026 Databricks-Certified-Data-Engineer-Professional Test Voucher | Authoritative Databricks Certified Data Engineer Professional Exam 100% Free Exam Simulator Fee 🌉 Immediately open ⏩ www.pdfvce.com ⏪ and search for 《 Databricks-Certified-Data-Engineer-Professional 》 to obtain a free download 🔛Databricks-Certified-Data-Engineer-Professional Exam Material
- Valid Databricks-Certified-Data-Engineer-Professional Exam Voucher 🧖 Training Databricks-Certified-Data-Engineer-Professional Material 🍺 Databricks-Certified-Data-Engineer-Professional Reliable Practice Materials 🪂 Open ➤ www.pass4test.com ⮘ enter ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ and obtain a free download 💐Valid Databricks-Certified-Data-Engineer-Professional Exam Camp Pdf
- Trustable Databricks-Certified-Data-Engineer-Professional Test Voucher - Easy and Guaranteed Databricks-Certified-Data-Engineer-Professional Exam Success 🎡 Search for 《 Databricks-Certified-Data-Engineer-Professional 》 and download it for free on ☀ www.pdfvce.com ️☀️ website 😿Practice Databricks-Certified-Data-Engineer-Professional Exam
- Practice Databricks-Certified-Data-Engineer-Professional Exam ⭐ Databricks-Certified-Data-Engineer-Professional Latest Examprep 🌖 Valid Databricks-Certified-Data-Engineer-Professional Exam Camp Pdf 🧞 Search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ and easily obtain a free download on ▶ www.testkingpass.com ◀ 🦲New Databricks-Certified-Data-Engineer-Professional Test Duration
- New Databricks-Certified-Data-Engineer-Professional Dumps Files 🔔 Databricks-Certified-Data-Engineer-Professional Exam Simulator Free ☃ Databricks-Certified-Data-Engineer-Professional Exam Dumps.zip 👨 Search for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 and easily obtain a free download on ➽ www.pdfvce.com 🢪 🌞Databricks-Certified-Data-Engineer-Professional Exam Material
- Free PDF Quiz 2026 Databricks - Databricks-Certified-Data-Engineer-Professional Test Voucher 🚇 The page for free download of [ Databricks-Certified-Data-Engineer-Professional ] on { www.prep4sures.top } will open immediately ▛Practice Databricks-Certified-Data-Engineer-Professional Mock
- Get Newest Databricks-Certified-Data-Engineer-Professional Test Voucher and Pass Exam in First Attempt ❎ Open ➤ www.pdfvce.com ⮘ and search for ➽ Databricks-Certified-Data-Engineer-Professional 🢪 to download exam materials for free ➡Valid Databricks-Certified-Data-Engineer-Professional Exam Camp Pdf
- Databricks-Certified-Data-Engineer-Professional Exam Simulator Free 👽 Databricks-Certified-Data-Engineer-Professional Reliable Exam Test 🦓 Valid Databricks-Certified-Data-Engineer-Professional Exam Voucher 🛫 Download “ Databricks-Certified-Data-Engineer-Professional ” for free by simply searching on 【 www.exam4labs.com 】 🌀Databricks-Certified-Data-Engineer-Professional Latest Examprep
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes