What's more, part of that itPass4sure Databricks-Certified-Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=12JjtQuqN26uIt0n6jblz_Y2_FP-WhQFh
The result of your exam is directly related with the Databricks-Certified-Data-Engineer-Associate learning materials you choose. So our company is of particular concern to your exam review. Getting the certificate of the exam is just a start. Our Databricks-Certified-Data-Engineer-Associate practice engine may bring far-reaching influence for you. Any demands about this kind of exam of you can be satisfied by our Databricks-Certified-Data-Engineer-Associate training quiz. So our Databricks-Certified-Data-Engineer-Associate exam questions are of positive interest to your future.
| Section | Weight | Objectives |
|---|---|---|
| Delta Lake Fundamentals | 20-25% | - Understand ACID transactions and time travel - Create and manage Delta tables - Explain Delta Lake features and benefits - Write to and read from Delta tables |
| Lakehouse Platform Concepts | 10-15% | - Describe key Databricks Lakehouse platform components - Understand the Lakehouse architecture and its benefits - Explain data governance and security concepts |
| Spark SQL and DataFrames | 15-20% | - Aggregate and group data - Write and execute Spark SQL queries - Join and union DataFrames - Handle null values and data quality |
| Python for Data Engineering | 10-15% | - Work with Spark APIs in Python - Implement user-defined functions (UDFs) - Use PySpark for data processing |
| Apache Spark Data Processing Fundamentals | 20-25% | - Use Spark SQL for data processing - Work with structured data types (arrays, maps, structs) - Create and use Spark DataFrames - Apply transformations and actions on DataFrames |
| Data Pipeline Architecture | 15-20% | - Implement incremental data processing - Understand ELT vs ETL patterns - Monitor and optimize pipeline performance - Design data pipelines for batch and streaming |
>> Best Databricks-Certified-Data-Engineer-Associate Vce <<
The Databricks Databricks-Certified-Data-Engineer-Associate exam questions are being updated on a regular basis. As you know the Databricks-Certified-Data-Engineer-Associate exam syllabus is being updated on a regular basis. To add all these changes in the Databricks-Certified-Data-Engineer-Associate exam dumps we have hired a team of exam experts. They regularly update the Databricks Databricks-Certified-Data-Engineer-Associate Practice Questions as per the latest Databricks Databricks-Certified-Data-Engineer-Associate exam syllabus. So you have the option to get free Databricks-Certified-Data-Engineer-Associate exam questions update for up to 1 year from the date of Databricks Databricks-Certified-Data-Engineer-Associate PDF dumps purchase.
NEW QUESTION # 286
A data engineer is using the following code block as part of a batch ingestion pipeline to read from a composable table: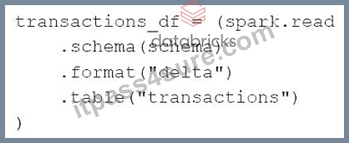
Which of the following changes needs to be made so this code block will work when the transactions table is a stream source?
Answer: B
Explanation:
To read from a stream source, the data engineer needs to use the spark.readStream method instead of the spark.read method. The spark.readStream method returns a DataStreamReader object that can be used to specify the details of the input source, such as the format, the schema, the path, and the options. The spark.read method is only suitable for batch processing, not streaming processing. The other changes are not necessary or correct for reading from a stream source. References: Structured Streaming Programming Guide, Read a stream, Databricks Data Sources
NEW QUESTION # 287
Which of the following describes the storage organization of a Delta table?
Answer: B
Explanation:
Delta Lake is the optimized storage layer that provides the foundation for storing data and tables in the Databricks lakehouse. Delta Lake is open source software that extends Parquet data files with a file-based transaction log for ACID transactions and scalable metadata handling1. Delta Lake stores its data and metadata in a collection of files in a directory on a cloud storage system, such as AWS S3 or Azure Data Lake Storage2. Each Delta table has a transaction log that records the history of operations performed on the table, such as insert, update, delete, merge, etc. The transaction log also stores the schema and partitioning information of the table2. The transaction log enables Delta Lake to provide ACID guarantees, time travel, schema enforcement, and other features1. Reference:
What is Delta Lake? | Databricks on AWS
Quickstart - Delta Lake Documentation
NEW QUESTION # 288
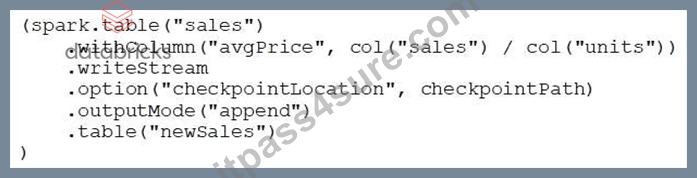
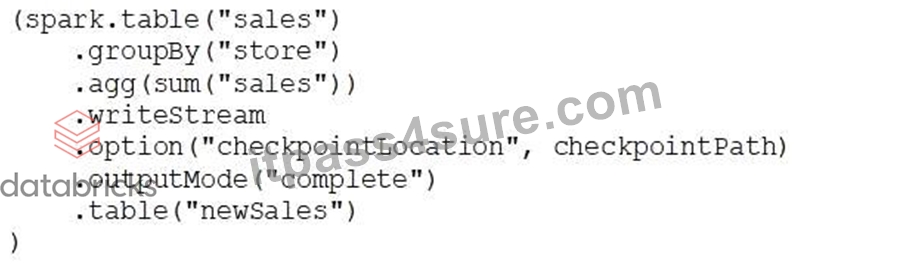
Which of the following Structured Streaming queries is performing a hop from a Silver table to a Gold table?
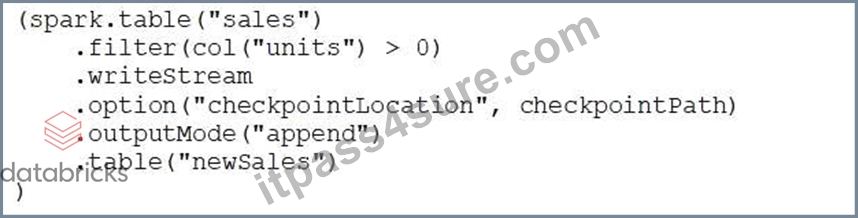
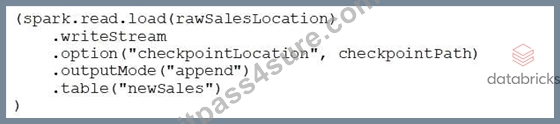
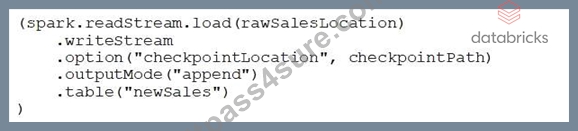
Answer: E
Explanation:
The best practice is to use "Complete" as output mode instead of "append" when working with aggregated tables. Since gold layer is work final aggregated tables, the only option with output mode as complete is option E.
NEW QUESTION # 289
Which of the following describes the relationship between Gold tables and Silver tables?
Answer: E
Explanation:
According to the medallion lakehouse architecture, gold tables are the final layer of data that powers analytics, machine learning, and production applications. They are often highly refined and aggregated, containing data that has been transformed into knowledge, rather than just information. Silver tables, on the other hand, are the intermediate layer of data that represents a validated, enriched version of the raw data from the bronze layer.
They provide an enterprise view of all its key business entities, concepts and transactions, but they may not have all the aggregations and calculations that are required for specific use cases. Therefore, gold tables are more likely to contain aggregations than silver tables. References:
* What is the medallion lakehouse architecture?
* What is a Medallion Architecture?
NEW QUESTION # 290
A data engineer needs to compute metrics such as:
- rolling 7-day sales
- percent of total revenue
- top-N most profitable categories
Which two approaches are appropriate for implementing these metrics with PySpark DataFrames? (Choose two.)
Answer: A,D
Explanation:
Window functions are the correct approach for rolling calculations and ranking tasks such as rolling 7-day sales and top-N categories. Joins and groupBy are appropriate for percent-of-total calculations by first computing total revenue at the needed level and then comparing each subgroup against that total.
NEW QUESTION # 291
......
If you're still learning from the traditional old ways and silently waiting for the test to come, you should be awake and ready to take the Databricks-Certified-Data-Engineer-Associate exam in a different way. Study our Databricks-Certified-Data-Engineer-Associate training materials to write "test data" is the most suitable for your choice, after recent years show that the effect of our Databricks-Certified-Data-Engineer-Associate Guide Torrent has become a secret weapon of the examinee through qualification examination, a lot of the users of our Databricks-Certified-Data-Engineer-Associate guide torrent can get unexpected results in the Databricks-Certified-Data-Engineer-Associate examination.
Databricks-Certified-Data-Engineer-Associate Test Quiz: https://www.itpass4sure.com/Databricks-Certified-Data-Engineer-Associate-practice-exam.html
What's more, part of that itPass4sure Databricks-Certified-Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=12JjtQuqN26uIt0n6jblz_Y2_FP-WhQFh