我們Testpdf Nutanix的NCP-BC-7.5考試認證資料是全球所有網站不能夠媲美的,當然這不僅僅是品質的問題,我們的品質肯定是沒得說,更重要的是我們Testpdf Nutanix的NCP-BC-7.5考試認證資料適合所有的IT考試認證,它的使用性達到各個IT領域,所以我們Testpdf網站得到很多考生的關注,他們相信我們,依賴我們,這也是我們Testpdf網站所擁有的實力所體現之處,我們的考試培訓資料能讓你買了之後不得不向你的朋友推薦,並讚不絕口,因為它真的對你們有很大的幫助。
| Section | Objectives |
|---|---|
| Monitoring, Testing and Troubleshooting | - Resolving third-party backup integration problems - Documenting runbooks for incident response - Non-disruptive recovery testing - Troubleshooting permission issues and misconfigured DR environments - Diagnosing network, storage and replication failures - Setting up alerts for replication lag |
| Data Protection and Snapshots | - Incremental backup implementation - Storage configuration for BCDR - Data restoration at VM and application level - Snapshot retention policies design - Snapshot scheduling and management |
| Nutanix Disaster Recovery Solutions | - Configuring and managing replication policies - Recovery workflows using Nutanix native tools - Metro Availability configuration and management - Integration with third-party backup solutions - Failover procedures and execution |
| Security and Hardening | - Approval policies configuration - RBAC implementation for disaster recovery - Designing secure BCDR environments - Security best practices for replication |
| BCDR Fundamentals and Requirements Interpretation | - Selecting appropriate replication types (async, near-sync, synchronous, metro) - Availability metrics and SLA definitions - Defining recovery strategies aligned to business requirements and risk tolerance - Translating business requirements into resilient recovery architectures - Understanding RTO and RPO concepts and business impact analysis |
| Replication and Failover Architecture | - Synchronous replication across sites - Failover readiness validation - Network segmentation for BCDR environments - Recovery site capacity management - Asynchronous replication planning |
Testpdf是個能夠加速你通過Nutanix NCP-BC-7.5認證考試的網站。我們的Nutanix NCP-BC-7.5 認證考試的考古題是Testpdf的專家不斷研究出來的。當你還在為通過Nutanix NCP-BC-7.5 認證考試而奮鬥時,選擇Testpdf的Nutanix NCP-BC-7.5 認證考試的最新考古題將給你的復習備考帶來很大的幫助。
問題 #75
An administrator is troubleshooting a hung replication. When checking the replication status, the complete percent and bytes completed do not increase. The administrator checks the Stargate logs on the destination cluster and confirms the writes are failing with " nfs status 28 " . Checking the container info on the destination cluster, free space on the container is 0. The administrator confirms that there is sufficient space available in the storage pool. What could be the reason for free space on the container to be 0?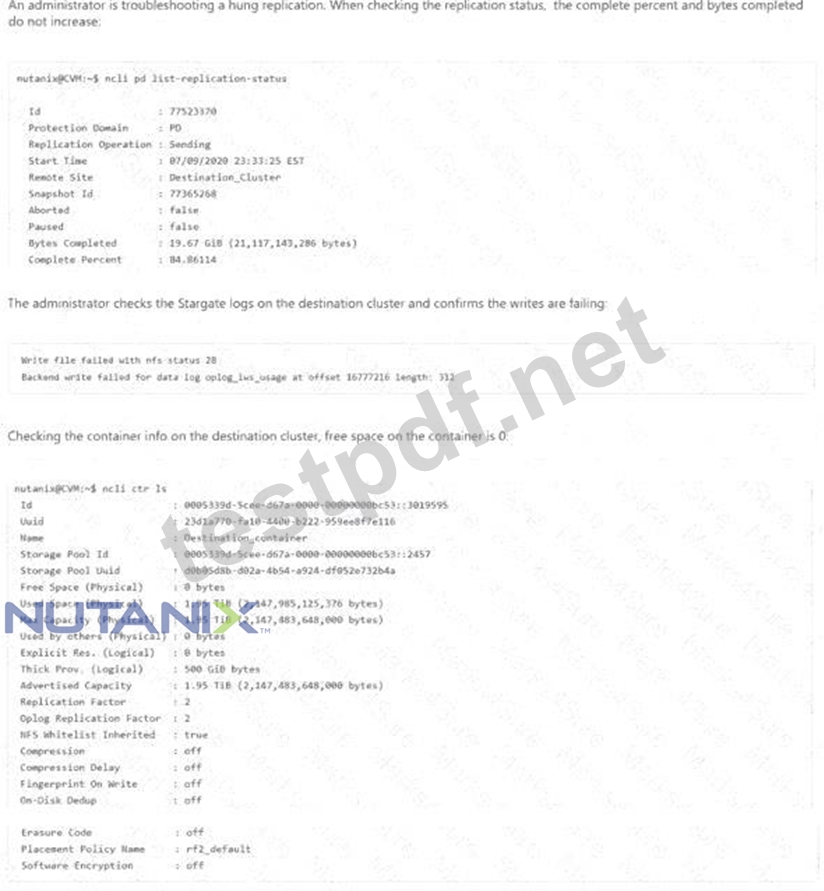
答案:D
解題說明:
In a Nutanix environment, " Advertised Capacity " is a logical limit (a quota) that an administrator can set on a specific storage container. Even if the physical storage pool has terabytes of free space, if a container ' s advertised capacity is reached, the hypervisor and the Nutanix services will perceive the container as being
100% full.
In this troubleshooting scenario, the " nfs status 28 " error code is a standard indicator for " No space left on device " . Since the administrator confirmed the pool is healthy, the logical limit on the container is the only remaining bottleneck. Replication jobs will " hang " because the destination Stargate service cannot write the incoming data blocks to a container that reports zero free space. To resolve this, the administrator must either increase the advertised capacity value in Prism or remove the limit entirely to allow the container to consume the available physical space in the pool. This highlights a common configuration " trap " where logical quotas-intended for multi-tenant management-can inadvertently block critical BCDR processes like replication if not monitored or sized correctly according to the protected VM growth.
問題 #76
A Protection Policy is configured with a Nearsync replication schedule (15-minute RPO). An administrator observes that the system has temporarily transitioned to an hourly replication schedule. Which scenario would cause this automatic transition from Nearsync to Asynchronous (hourly) replication?
答案:A
解題說明:
NearSync replication is a Nutanix technology that provides RPOs as low as 1 minute by using " Lightweight Snapshots " (LWS). However, NearSync has specific operational requirements to maintain its aggressive schedule . If the system detects that it cannot maintain the 15-minute RPO using lightweight snapshots, it will automatically " downshift " to a standard Asynchronous (hourly) replication mode to ensure that protection is not lost entirely.
One of the most common triggers for this temporary transition is the addition of a new virtual machine to the category associated with the Protection Policy. When a new VM is added, the Nutanix cluster must perform a
" full initial sync " (also known as a seed replication) to transfer all the VM ' s data to the remote site. Because a full seed replication involves transferring much more data than a standard delta update, it often exceeds the time window and processing capabilities of the NearSync LWS engine. To handle this large data transfer safely, the system switches to the Async (hourly) schedule, which uses more robust but slower snapshot mechanisms. Once the initial sync of the new VM is complete and the clusters are in a " consistent " state, the system will automatically attempt to " upshift " back to the NearSync schedule to restore the 15-minute RPO.
This behavior ensures that the system handles growth and changes in the environment while maintaining the highest possible level of protection without administrative intervention.
問題 #77
An administrator is managing a mission-critical Inventory-VM that is part of a Protection Domain (PD) named PD_Production.
* Monday: A scheduled snapshot of PD_Production is successfully taken.
* Tuesday: Due to a configuration error during a cleanup task, the administrator accidentally removes Inventory-VM from the PD_Production Protection Domain. The VM continues to run, but it is no longer being snapped or replicated.
* Wednesday: A database corruption occurs on Inventory-VM. The administrator finds the local snapshot from Monday and performs an In-place Restore (Revert) to recover the data.
Following the successful completion of the In-place Restore, what is the status of Inventory-VM regarding its data protection?
答案:D
解題說明:
In Nutanix Protection Domains, the relationship between a virtual machine and a snapshot is tied to the metadata at the time the snapshot was created . When an administrator removes a VM from a PD (Option B), the cluster stops taking new snapshots, but the historical snapshots (recovery points) remain in the storage system until their retention period expires .
If a disaster or corruption occurs (Option Wednesday), the administrator can still use those historical snapshots to perform a " Revert " operation. The Nutanix AOS engine can successfully roll back the VM ' s vDisks to the Monday state because the data exists. However, the " Revert " operation only impacts the data on the disks; it does not re-establish the logical configuration of the Protection Domain. Because the VM was explicitly removed from the PD on Tuesday, the system treats it as an " unprotected " VM after the restore is finished. It will not be included in the next scheduled snapshot cycle of PD_Production. To resume ongoing protection, the administrator must manually add the Inventory-VM back into the PD_Production Protection Domain. This scenario illustrates a critical operational point: restoring data does not automatically restore the protection schedule, and administrators must verify the " Protection Status " of VMs following any manual recovery task to ensure they are not left vulnerable to future failures.
問題 #78
A remote office deployment consists of a two-node Nutanix hybrid cluster. An administrator attempts to configure a protection domain with a 5-minute RPO (Nearsync) replicating to a central datacenter.
Why is the administrator unable to successfully configure this Nearsync schedule?
答案:A
解題說明:
Nutanix NearSync replication provides a middle ground between traditional asynchronous replication and synchronous mirroring, offering RPOs as low as 1 minute using Lightweight Snapshots (LWS). However, the LWS mechanism and the high-frequency metadata operations required to maintain a 1-to-15 minute RPO have specific hardware and cluster-level requirements.
One of the strict prerequisites for enabling NearSync is the cluster size. Nutanix requires a minimum of a three-node cluster for NearSync replication. This is because the system must have enough resources to distribute the LWS metadata and handle the increased I/O overhead without compromising the cluster ' s availability or performance. In a two-node cluster (which is common for small ROBO deployments), the system does not meet the minimum redundancy and resource thresholds required for the NearSync engine to operate reliably. While two-node clusters support standard Asynchronous replication (with a 60-minute RPO or higher), they are restricted from using the NearSync lightweight snapshot engine. An administrator attempting to set a 5-minute RPO on a two-node cluster will find the option either grayed out or the task will fail validation. To achieve a 5-minute RPO, the organization would need to expand the remote office cluster to at least three nodes or settle for a higher RPO supported by standard asynchronous replication on the existing hardware.
問題 #79
A sudden and unrecoverable hardware failure occurs at the primary site, making the Prism Element console for that cluster inaccessible. The secondary site is healthy and contains the latest replicated snapshots. Which action must the administrator take on the secondary cluster to restore the VMs?
答案:C
解題說明:
When a primary Nutanix site suffers a catastrophic failure, the disaster recovery plan must be executed from the recovery (secondary) site . In a legacy Protection Domain-based environment, the secondary site is in a " passive " or " standby " mode, receiving snapshots but not actively running the workloads. The traditional method to failover is using the " Activate " command (Option A), which promotes the PD and registers the VMs. However, in certain specific failure scenarios or older software versions, the secondary cluster may require a service-level reset to recognize its new role as the active master for those specific workloads.
The Cerebro service is the core component responsible for managing Protection Domains and replication metadata. If the primary site is completely inaccessible and the secondary site ' s metadata state needs refreshing to initiate recovery, restarting the Cerebro service on the secondary cluster CVMs can force a re- evaluation of all local snapshots and protection domain states. This action triggers the recovery logic, allowing the administrator to then see and activate the recovery points. While " Activate " is the goal, the first technical step in a situation where the cluster management plane is unstable or the primary is gone is ensuring the data protection services are aware of the current state. This allows the VMs to be restored from the latest snapshots, fulfilling the Recovery Time Objective (RTO) despite the complete loss of the source infrastructure.
問題 #80
......
通過那些很多已經通過Nutanix NCP-BC-7.5 認證考試的IT專業人員的回饋,他們的成功得益於Testpdf的説明。Testpdf提供的針對性測試練習題和答案給了他們很大幫助,節約了他們的寶貴的時間和精力,讓他們輕鬆順利地通過他們第一次參加的Nutanix NCP-BC-7.5 認證考試。所以Testpdf是個值得你們信賴的網站。選擇了Testpdf,下一個成功的IT人士就是你,Testpdf會成就你的夢想。
NCP-BC-7.5熱門考題: https://www.testpdf.net/NCP-BC-7.5.html