DOWNLOAD the newest PDFTorrent MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1qHdv1uawN1A6pd7Os6avOlIYHjx7pC4k
There are many ways to help you pass Amazon certification MLA-C01 exam and selecting a good pathway is a good protection. PDFTorrent can provide you a good training tool and high-quality reference information for you to participate in the Amazon certification MLA-C01 exam. PDFTorrent's practice questions and answers are based on the research of Amazon certification MLA-C01 examination Outline. Therefore, the high quality and high authoritative information provided by PDFTorrent can definitely do our best to help you pass Amazon certification MLA-C01 exam. PDFTorrent will continue to update the information about Amazon certification MLA-C01 exam to meet your need.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Valid Amazon MLA-C01 Exam Answers <<
As is known to all, before purchasing the MLA-C01 Study Guide, we need to know the features of it. We offer you free demo to have a try, so that you can know the characteristics of MLA-C01 exam dumps. Beside we have three versions, each version have its own advantages, and they can meet all of your demands. And we have free update for 365 days after buying, the latest version will send to you email box automatically.
NEW QUESTION # 45
A company is building an Amazon SageMaker AI pipeline for an ML model. The pipeline uses distributed processing and distributed training.
An ML engineer needs to encrypt network communication between instances that run distributed jobs. The ML engineer configures the distributed jobs to run in a private VPC.
What should the ML engineer do to meet the encryption requirement?
Answer: C
Explanation:
In Amazon SageMaker, distributed training and distributed processing jobs often involve multiple instances exchanging data over the network. By default, when these jobs run inside a VPC, network traffic remains private but is not automatically encrypted between instances. When compliance or security requirements mandate encryption of in-transit data, additional configuration is required.
The correct solution is to enable inter-container traffic encryption, which ensures that all network communication between containers running on different instances is encrypted using TLS. Amazon SageMaker provides a built-in feature for this purpose. When inter-container traffic encryption is enabled, SageMaker automatically configures secure communication channels between all nodes participating in a distributed job, including training clusters and processing jobs.
Option A (Network isolation) is incorrect because network isolation prevents containers from making outbound network calls and accessing the internet. It does not encrypt traffic between instances.
Option B (Security groups) is incorrect because security groups control network access and traffic flow, not encryption. They can restrict which instances can communicate, but they do not provide data-in-transit encryption.
Option D (VPC flow logs) is incorrect because VPC flow logs are used for monitoring and auditing network traffic, not for encrypting it.
AWS documentation explicitly states that enabling inter-container traffic encryption is the recommended and supported approach for encrypting data exchanged between instances during distributed SageMaker jobs. This feature aligns with enterprise security best practices and regulatory requirements for protecting sensitive ML training data in transit.
Therefore, Option C is the only solution that directly fulfills the encryption requirement for distributed SageMaker workloads.
NEW QUESTION # 46
Case Study
A company is building a web-based AI application by using Amazon SageMaker. The application will provide the following capabilities and features: ML experimentation, training, a central model registry, model deployment, and model monitoring.
The application must ensure secure and isolated use of training data during the ML lifecycle. The training data is stored in Amazon S3.
The company is experimenting with consecutive training jobs.
How can the company MINIMIZE infrastructure startup times for these jobs?
Answer: D
Explanation:
When running consecutive training jobs in Amazon SageMaker, infrastructure provisioning can introduce latency, as each job typically requires the allocation and setup of compute resources. To minimize this startup time and enhance efficiency, Amazon SageMaker offers Managed Warm Pools.
Key Features of Managed Warm Pools:
Reduced Latency: Reusing existing infrastructure significantly reduces startup time for training jobs.
Configurable Retention Period: Allows retention of resources after training jobs complete, defined by the KeepAlivePeriodInSeconds parameter.
Automatic Matching: Subsequent jobs with matching configurations (e.g., instance type) can reuse retained infrastructure.
Implementation Steps:
Request Warm Pool Quota Increase: Increase the default resource quota for warm pools through AWS Service Quotas.
Configure Training Jobs:
Set KeepAlivePeriodInSeconds for the first training job to retain resources.
Ensure subsequent jobs match the retained pool ' s configuration to enable reuse.
Monitor Warm Pool Usage: Track warm pool status through the SageMaker console or API to confirm resource reuse.
Considerations:
Billing: Resources in warm pools are billable during the retention period.
Matching Requirements: Jobs must have consistent configurations to use warm pools effectively.
Alternative Options:
Managed Spot Training: Reduces costs by using spare capacity but doesn't address startup latency.
SageMaker Training Compiler: Optimizes training time but not infrastructure setup.
SageMaker Distributed Data Parallelism Library: Enhances training efficiency but doesn't reduce setup time.
By using Managed Warm Pools, the company can significantly reduce startup latency for consecutive training jobs, ensuring faster experimentation cycles with minimal operational overhead.
AWS Documentation: Managed Warm Pools
AWS Blog: Reduce ML Model Training Job Startup Time
NEW QUESTION # 47
A company uses a training job on Amazon SageMaker Al to train a neural network. The job first trains a model and then evaluates the model's performance ag test dataset. The company uses the results from the evaluation phase to decide if the trained model will go to production.
The training phase takes too long. The company needs solutions that can shorten training time without decreasing the model's final performance.
Select the correct solutions from the following list to meet the requirements for each description. Select each solution one time or not at all. (Select THREE.)
. Change the epoch count.
. Choose an Amazon EC2 Spot Fleet.
Change the batch size.
. Use early stopping on the training job.
Use the SageMaker Al distributed data parallelism (SMDDP) library.
. Stop the training job.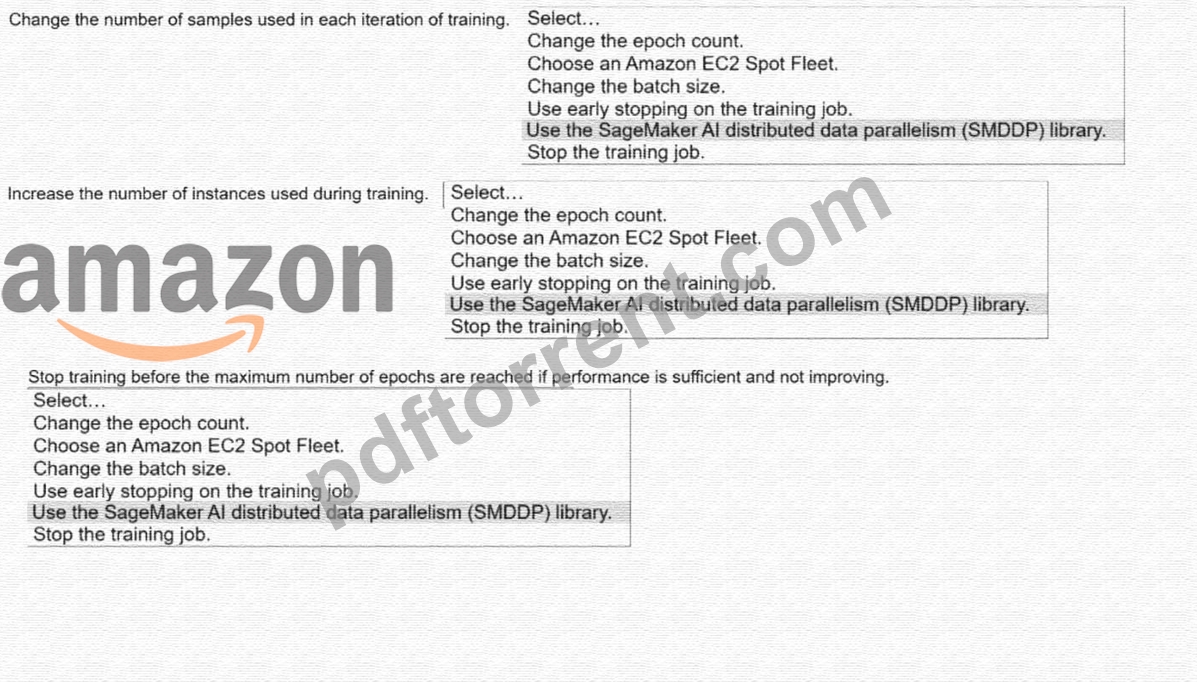
Answer:
Explanation: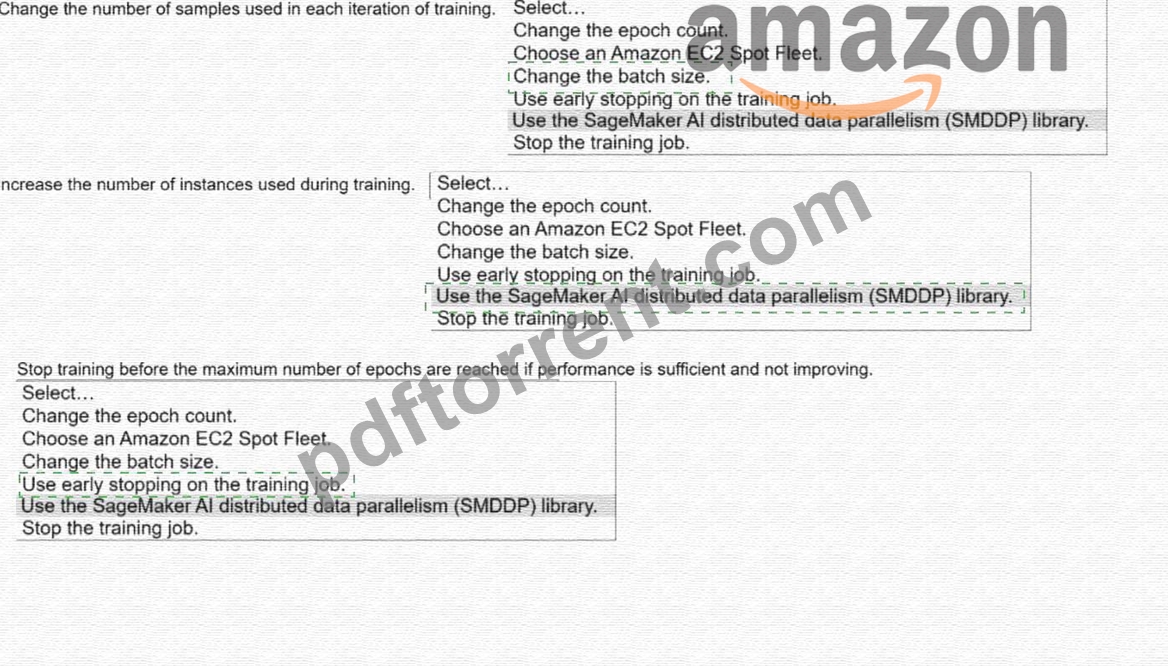
Explanation:
Change the number of samples used in each iteration of training
Correct selection:
Change the batch size
Why:
Increasing the batch size reduces the number of iterations per epoch, which can significantly shorten training time while maintaining model quality when tuned appropriately. AWS explicitly recommends batch size tuning as a primary performance optimization.
Increase the number of instances used during training
Correct selection:
Use the SageMaker AI distributed data parallelism (SMDDP) library
Why:
SMDDP is designed to efficiently distribute training data across multiple GPU instances with optimized gradient synchronization. This accelerates training without affecting model convergence or accuracy, unlike naive scaling approaches.
Stop training before the maximum number of epochs are reached if performance is sufficient and not improving Correct selection:
Use early stopping on the training job
Why:
Early stopping automatically terminates training when validation metrics stop improving. AWS recommends this to reduce wasted compute time while preserving optimal model performance.
NEW QUESTION # 48
A company stores time-series data about user clicks in an Amazon S3 bucket. The raw data consists of millions of rows of user activity every day. ML engineers access the data to develop their ML models.
The ML engineers need to generate daily reports and analyze click trends over the past 3 days by using Amazon Athena. The company must retain the data for 30 days before archiving the data.
Which solution will provide the HIGHEST performance for data retrieval?
Answer: B
Explanation:
Partitioning the time-series data by date prefix in the S3 bucket significantly improves query performance in Amazon Athena by reducing the amount of data that needs to be scanned during queries. This allows the ML engineers to efficiently analyze trends over specific time periods, such as the past 3 days. Applying S3 Lifecycle policies to archive partitions older than 30 days to S3 Glacier FlexibleRetrieval ensures cost- effective data retention and storage management while maintaining high performance for recent data retrieval.
NEW QUESTION # 49
A company has trained an ML model that is packaged in a container. The company will integrate the model with an existing Python web application. The company needs to host the model on AWS by using Kubernetes.
The company does not want to manage the control plane and must provision the resources in a repeatable manner. The infrastructure must be provisioned by using Python.
Which solution will meet these requirements?
Answer: B
Explanation:
Option C is correct because the company needs Kubernetes hosting , does not want to manage the control plane , wants repeatable infrastructure provisioning , and requires that provisioning be done by using Python . Amazon EKS is AWS's managed Kubernetes service, so it satisfies the requirement to avoid managing the Kubernetes control plane directly. The AWS CDK documentation also confirms that Python is a fully supported client language for defining infrastructure as code.
AWS CDK is the best fit because it lets engineers define cloud infrastructure programmatically in Python and deploy it in a repeatable way. The AWS CDK EKS construct library specifically supports defining Amazon EKS clusters and related Kubernetes resources. This makes it a strong match for infrastructure that must be reproducible and expressed in code rather than provisioned manually. Since the model is already packaged in a container, storing the image in Amazon ECR and then deploying it to Amazon EKS follows the normal AWS container workflow.
The other options are less suitable. Option A requires setting up and managing a Kubernetes cluster on EC2, which violates the requirement to avoid control-plane management. Option B uses the AWS CLI, but the question specifically requires infrastructure provisioning by using Python , not command-line provisioning.
Option D uses CloudFormation, which is repeatable infrastructure as code, but the question explicitly says the infrastructure must be provisioned by using Python . AWS CDK uniquely satisfies both the IaC and Python requirements while using managed Kubernetes with EKS.
Therefore, the best verified AWS-docs answer is C .
NEW QUESTION # 50
......
MLA-C01 exam certification is one of the most important certification recently. When qualified by the MLA-C01 certification, you will get a good job easily with high salary. Besides, the career opportunities will be open for a certified person. Now, you can get the valid and best useful MLA-C01 Exam Training material. Our MLA-C01 study torrent is with 100% correct questions & answers, which can ensure you pass at first attempt. All MLA-C01 practice torrents can be easily and instantly downloaded after purchase.
Practice MLA-C01 Mock: https://www.pdftorrent.com/MLA-C01-exam-prep-dumps.html
DOWNLOAD the newest PDFTorrent MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1qHdv1uawN1A6pd7Os6avOlIYHjx7pC4k