Testpdf 考题大师始终致力与为客户提供 DP-750 认证的全真考题及认证学习资料,該模擬試題可以在不同的電腦中使用,這對於考生來說沒有任何限制。我們的 DP-750 權威考試題庫軟體是 Microsoft 認證廠商的授權產品,全新的收錄了 Microsoft 認證考試的所有試題,並根據認證的不斷變化而動態更新,參考資料的考試試題都是最新推出的。能够帮助你一次通过 Microsoft DP-750 认证考试。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Topic 2: Prepare and process data | 30-35% | - Ingest and transform data
|
| Topic 3: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 4: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
Testpdf的DP-750考古題是一個保證你一次及格的資料。這個考古題的命中率非常高,所以你只需要用這一個資料就可以通過考試。如果不相信就先試用一下。因為如果考試不合格的話Testpdf會全額退款,所以你不會有任何損失。用過以後你就知道DP-750考古題的品質了,因此趕緊試一下吧。問題有提供demo,點擊Testpdf的網站去下載吧。
問題 #75
You need to deploy Databricks Asset Bundles to a development environment. The solution must support automated and repeatable deployments across environments.
What should you use?
答案:A
解題說明:
The correct answer is C - the Databricks CLI.
Databricks Asset Bundles are deployed using the Databricks CLI (v0.205+) with the commands databricks bundle validate, databricks bundle deploy, and databricks bundle run. The CLI reads the databricks.yml file, resolves the target environment settings, and creates or updates all declared resources (jobs, pipelines, apps) in the workspace. This is the documented, supported deployment mechanism for DABs and integrates naturally into CI/CD pipelines.
Option A (Azure Developer CLI / azd) is a general Azure IaC tool with no native understanding of Databricks bundles. Option B (Git folders) syncs notebook and file content from a Git repository into a workspace - useful for code, but it doesn't deploy Lakeflow Jobs, SDP pipelines, or bundle configurations. Option D (Azure CLI) manages Azure infrastructure (resource groups, storage accounts, etc.) and has no native DAB deployment support.
Reference: https://learn.microsoft.com/en-us/azure/databricks/dev-tools/bundles/deploy-bundle
問題 #76
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount != None)
Does this meet the goal?
答案:A
解題說明:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
問題 #77
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named Catalog1. Catalog1 contains a table named Transactions. Transactions contains the following columns:
- transaction_id
- customer_name
- email_address
- credit_card_number
- transaction_amount
You need to ensure that business analysts can query all the rows in the Transactions table. The solution must meet the following requirements:
- Prevent the analysts from seeing the full values in the email_address and credit_card_number columns.
- Ensure that the analysts can see only the values after the @
character in each email address.
- Ensure that the analysts can see only the last four digits of each
credit card number.
- Enable the analysts to query the table without errors.
- Follow the principle of least privilege.
What should you do?
答案:A
解題說明:
To protect sensitive customer information while allowing a specific group to run queries, use Unity Catalog's Dynamic Column Masking. This grants the group table access while applying User- Defined Functions (UDFs) to redact the email addresses and credit card numbers dynamically.
Here is the exact SQL implementation to apply:
1. Create the masking SQL UDFs
Define functions to apply the exact partial masking rules requested.
2. Apply the column masks to the tableAlter the transaction table to attach these UDFs to the respective columns.
3. Grant least privilege permissionsGrant the group the SELECT permission on the table, along with the foundational permissions to access the catalog and schema.
Reference:
https://docs.databricks.com/aws/en/data-governance/unity-catalog/filters-and-masks
問題 #78
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Tabid.
Table! is written by batch jobs every hour and is queried frequently by filtering two columns named Customerld and EventDate.
You expect Table1 to grow significantly over time.
The rows in Table1 are frequently updated and deleted to support compliance requests.
You need to keep query performance consistent as Table1 grows. The solution must minimize update and deletion effort.
What should you include in the solution? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.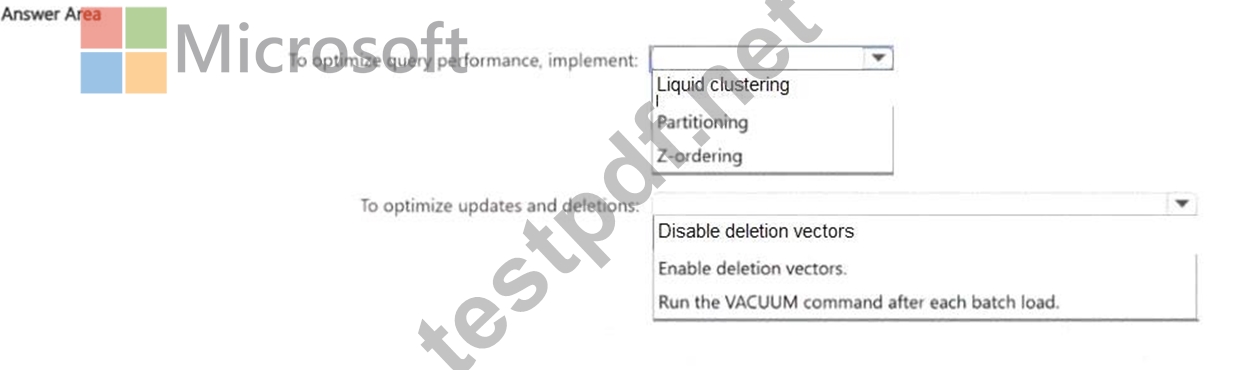
答案:
解題說明: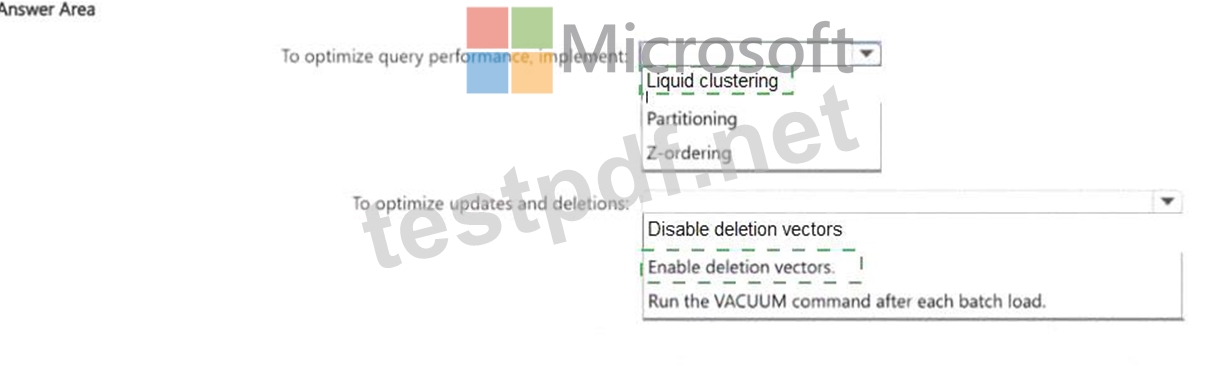
Explanation:
Two features work together to keep performance consistent and update costs low:
OPTIMIZE with ZORDER BY (CustomerId, EventDate). Z-Ordering co-locates rows with the same CustomerId and EventDate values in the same Parquet files. When a query filters on those columns, the Delta engine uses file statistics to skip files that can't possibly contain matching rows (data skipping). As the table grows, skipping scales proportionally - query time stays consistent.
Deletion Vectors (delta.enableDeletionVectors = true). When a row is updated or deleted, instead of rewriting the entire Parquet file, Delta marks the affected row in a small companion deletion vector file. This dramatically reduces write amplification for the frequent compliance-driven updates and deletions the question describes. Actual file rewrites are deferred to the next OPTIMIZE run.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/data-skipping
問題 #79
You need to develop the task logic for a new job in Lakeflow Jobs that processes telemetry data.
Each task must contain only the appropriate logic for its step in the pipeline. The solution must support the planned changes and meet the data ingestion and processing requirements.
What should you do?
答案:D
解題說明:
The correct answer is D. Breaking the pipeline into separate tasks for ingestion, cleansing, and curation is the foundation of well-designed Lakeflow Jobs pipelines. Each task should own one responsibility - when a task does too much, debugging a failure becomes a hunt through unrelated code, and retry logic becomes expensive because you re-execute work that already succeeded.
Contoso ' s planned changes explicitly call for ' a clear execution order and dependencies ' and ' orchestrate multi-step ingestion and transformation workflows. ' Separate tasks map directly to those goals: Lakeflow Jobs tracks each task ' s status independently, so if cleansing fails, ingestion doesn ' t re-run.
Option A bundles everything into one notebook, which means a curation bug forces a full re-ingestion. Option B copies logic three times - any future change must be applied in triplicate, which is a maintenance hazard.
Option C forces everything through SQL MERGE, which is the wrong tool for raw-event ingestion and doesn
' t address cleansing or schema drift.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/
問題 #80
......
在Testpdf的幫助下,你不需要花費大量的金錢參加相關的補習班或者花費很多時間和精力來復習相關知識就可以輕鬆通過考試。Microsoft DP-750考試軟體是Testpdf研究過去的真實的考題開發出來的。Testpdf提供的Microsoft DP-750考試練習題和答案和真實的考試練習題和答案有很大的相似性。
DP-750參考資料: https://www.testpdf.net/DP-750.html