Haben Sie die Schulungsunterlagen zur Microsoft AI-300 Zertifizierungsprüfung aus unserem Zertpruefung, warden Sie den Schlüssel für das Bestehen der Microsoft AI-300 Zertifizierungsprüfung gewinnen, der Ihnen bessere Entwicklung im IT-Bereich gewährleisten kann. Das Alles bedürft Ihres Vertrauens: Sie müssen auf Zertpruefung vertrauen und Sie müssen zudem auf die Schulungsunterlagen zur Microsoft AI-300 Zertifizierungsprüfung vertrauen. Inhalt unserer Lehrmaterialien ist absolut echt und zuversichtlich. Darüber hinaus beträgt unsere Bestehensrate der Microsoft AI-300 Zertifizierungsprüfung 100%.
| Section | Weight | Objectives |
|---|---|---|
| Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
| Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Implement machine learning model lifecycle and operations | 25–30% | - Monitor and maintain models in production
|
| Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
Wenn Sie Microsoft AI-300 Zertifizierungsprüfung ablegen, ist es nötig für Sie, die richtigen Microsoft AI-300 Prüfungsunterlagen zu benutzen. Wenn Sie irgendwo die Unterlagen suchen, stoppen Sie jetzt bitte. Wenn Sie keine richtigen Unterlagen haben, probieren Sie bitte Microsoft AI-300 Dumps von Zertpruefung. Die Hitrate der Dumps ist so hoch, dass sie Ihnen den einmaligen Erfolg garantieren. Im Verglich zu anderen Prüfungsunterlagen können diese Dumps die Prüfungsinhalte ganz richtig greifen. Damit können Sie Ihre Lerneffektivität erhöhen und sich besser auf Microsoft AI-300 Zertifizierungsprüfung vorbereiten.
134. Frage
You use the Azure Machine learning SDK v2 tor Python and notebooks to tram a model. You use Python code to create a compute target, an environment, and a taring script. You need to prepare information to submit a training job.
Which class should you use?
Antwort: C
135. Frage
You train models on GPU-enabled clusters but deploy them on CPU-based endpoints. Recently, inference failures occur due to incompatible dependencies. What should you do to ensure consistency?
Antwort: C
Begründung:
Defining and reusing environment configurations ensures that dependencies remain consistent between training and inference. This prevents runtime errors caused by mismatched libraries.
Using identical compute resources is unnecessary and inefficient, as consistency depends on environment configuration rather than hardware.
136. Frage
You manage an Azure Machine Learning workspace. You create an experiment named experiment1 by using the Azure Machine Learning Python SDK v2 and MLflow.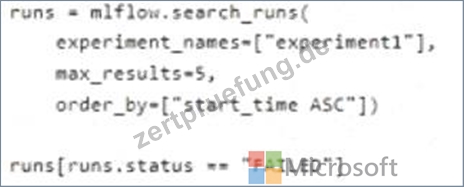
For each of the following statements, select Yes if the statement is true. Otherwise, select No.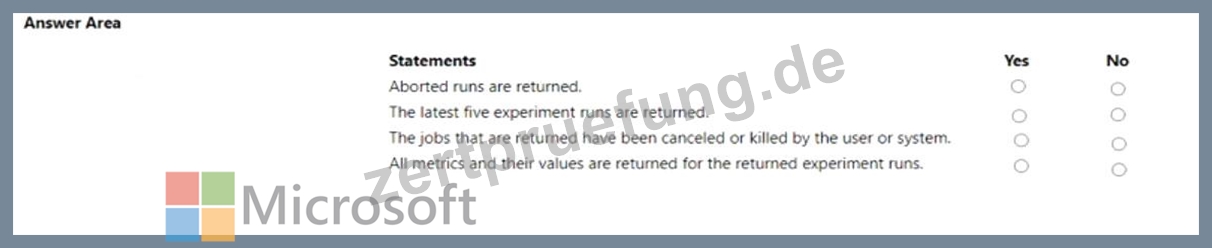
Antwort:
Begründung: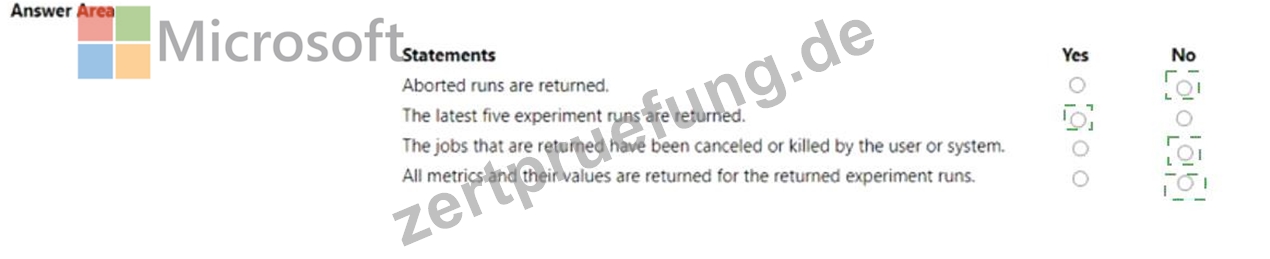
Explanation: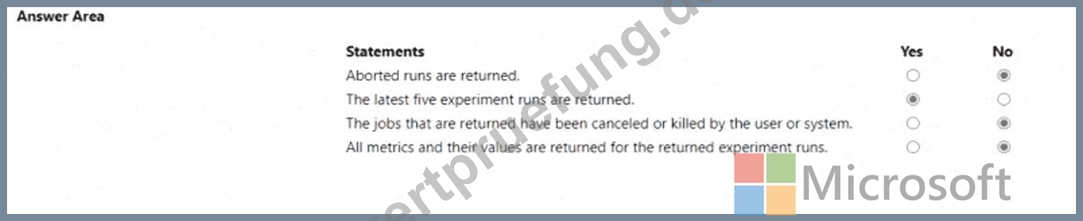
137. Frage
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You work in Microsoft Foundry with a prompt flow.
You must manually evaluate prompts and compare results across prompt variants.
You need to capture the inputs, outputs, token usage, and latencies for each flow run for the evaluation.
Solution: Configure Azure Monitor to collect logs from the workspace. Use the logs to perform prompt evaluation.
Does the solution meet the goal?
Antwort: B
Begründung:
Correct:
* In Microsoft Foundry, turn on Tracing for the prompt flow of the project and execute test runs to produce trace data.
Incorrect:
* Configure Azure Monitor to collect logs from the workspace. Use the logs to perform prompt evaluation.
* Create prompt variants and compare their outputs in the Evaluation experience.
* Use the prompt flow SDK to enable tracing for the flow before executing runs. Then run the flow to generate traceable results.
Note:
In Azure AI Foundry, you can capture and compare these metrics by enabling Tracing and using the Bulk Test feature. This allows you to systematically evaluate different prompt variants against a common dataset.
Steps to Evaluate and Compare Prompt Variants
*-> 1. Enable Tracing
Navigate to your Prompt Flow project.
Locate the Tracing toggle at the top of the flow authoring page.
Switch it to On.
This ensures every execution captures latency, token counts, and node-level inputs/outputs.
2. Create Prompt Variants
Within your flow, identify the LLM node you want to test.
Click Variants to create multiple versions of your prompt (e.g., Variant_0, Variant_1).
This allows you to test different instructions or few-shot examples side-by-side.
3. Run a Bulk Test (Evaluation)
4. Analyze the Results
Reference:
https://www.linkedin.com/pulse/streamlining-generative-ai-development-azure-foundry-tracing-taneja-mbwze
138. Frage
An organization operates a generative AI application in production by using Microsoft Foundry. The application serves live user traffic and is updated by a data scientist team regularly as prompts and models evolve.
The application intermittently times out during production use, which requires ongoing visibility into runtime behavior.
The team must also validate model quality and safety before releasing new updates to avoid introducing regressions.
You need to apply the correct mechanisms for continuous runtime monitoring and for release time validation.
Which mechanisms should you use for each requirement? To answer, move the appropriate mechanisms to the correct requirements. You may use each mechanism once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content . NOTE: Each correct selection is worth one point.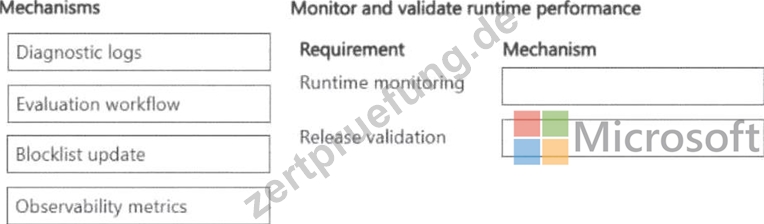
Antwort:
Begründung: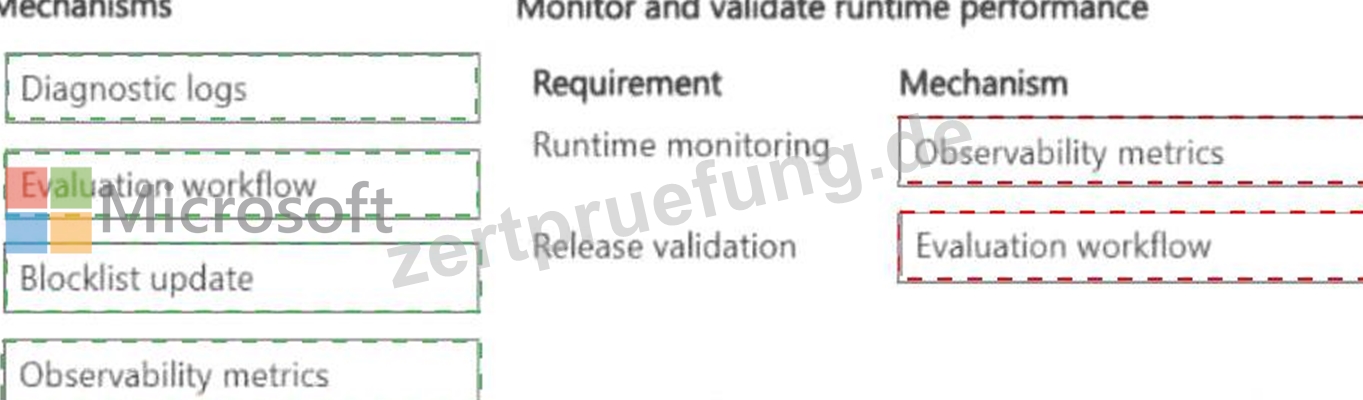
Explanation:
The two requirements target fundamentally different stages of the AI application lifecycle. Continuous runtime monitoring addresses production behavior - an application that intermittently times out needs real- time visibility into latency, error rates, and request volumes for every call in production. Tracing backed by Application Insights or OpenTelemetry exporters is correct here because it captures granular, per-request telemetry continuously without requiring manual triggering - it is always-on by design. Release-time validation addresses pre-release quality gates - before new prompts or model updates go live, you need to verify they have not introduced regressions. An evaluation pipeline in Microsoft Foundry ' s prompt flow is correct here: it runs the updated application against a predefined test dataset, scores outputs on quality and safety metrics, and passes or fails the release based on thresholds. Evaluation pipelines run on demand triggered by CI/CD, not continuously.
Microsoft Learn Reference Topic: Microsoft Foundry observability - Tracing for runtime monitoring vs.
Evaluation pipelines for release gates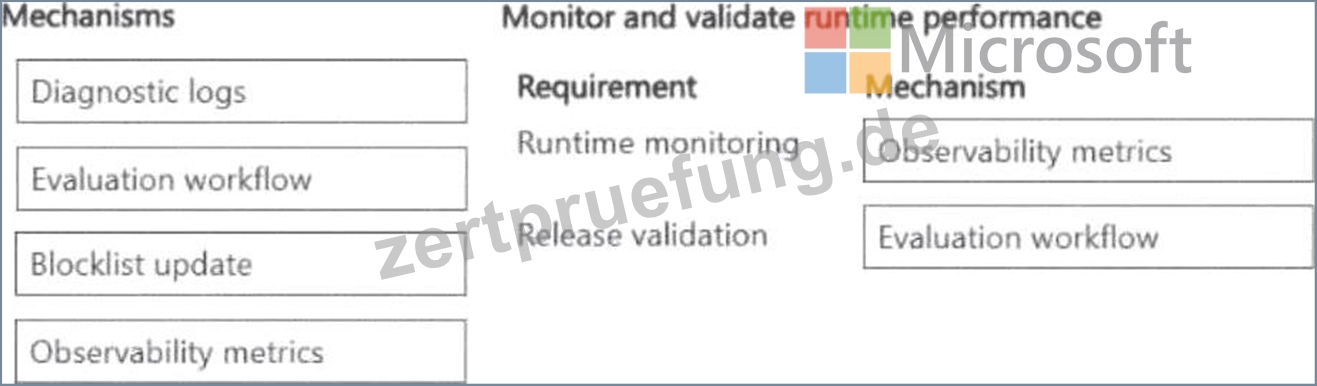
139. Frage
......
Sind Sie mit Ihrer Arbeit zufrieden? Sind Sie damit Zufrieden, was Sie jetzt machen? Wollen Sie Ihre Arbeitsfähigkeit erhöhen? Dann müssen Sie zuerst mehr nützliche Fähigkeiten für Ihre Arbeit beherrschen. Und das wichtigste ist, dass Arbietsgeber wissen, Sie mehr Arbeitsfähigkeiten beherrschen. Dann legen Sie Microsoft AI-300 Prüfung ab. AI-300 Prüfung kann Ihren Wunsch erreichen. Und es macht nichts, wenn Sie die Prüfungsfragen nicht genug kennen, weil Sie die Hilfe und die Vorbereitungswerkzeuge an Zertpruefung finden können. Die Prüfungsfragen und-antworten können Ihnen helfen, Microsoft AI-300 Zertifikat zu bekommen.
AI-300 Vorbereitungsfragen: https://www.zertpruefung.de/AI-300_exam.html