BONUS!!! Download part of Exam4Free SPS-C01 dumps for free: https://drive.google.com/open?id=1tw06EJgL02rs8ecg_y0TCwm2WkJWTJtW
Exam4Free has made the SPS-C01 exam dumps after consulting with professionals and getting positive feedback from customers. The team of Exam4Free has worked hard in making this product a successful Snowflake SPS-C01 Study Material. So we guarantee that you will not face issues anymore in passing the Snowflake SPS-C01 certification test with good grades.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
|
| Topic 2: Snowpark API and Development | 30% | - Python API fundamentals
|
| Topic 3: Data Transformations and Operations | 35% | - DataFrame manipulation
|
| Topic 4: Performance and Best Practices | 10% | - Security and governance
|
>> SPS-C01 Reliable Test Practice <<
Now we can say that Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam questions are real and top-notch Snowflake SPS-C01 exam questions that you can expect in the upcoming Snowflake SPS-C01 exam. In this way, you can easily pass the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam with good scores. The countless SPS-C01 Exam candidates have passed their dream Snowflake SPS-C01 certification exam and they all got help from real, valid, and updated SPS-C01 practice questions, You can also trust on Exam4Free and start preparation with confidence.
NEW QUESTION # 199
You are working with a Snowpark DataFrame called 'customer df that contains customer data, including a column named 'registration_date' of data type TIMESTAMP NTZ. You need to filter the DataFrame to only include customers who registered in the year 2023. Which of the following Snowpark code snippets represents the MOST efficient and correct way to accomplish this filtering, considering potential timezone issues?





Answer: A
Explanation:
Option C is the most efficient and accurate. It directly compares the 'registration_date' (TIMESTAMP_NTZ) to the date range using string literals, avoiding unnecessary function calls Cyear', 'to_date', 'to_varchar', that could impact performance or introduce subtle errors related to timezone conversions. Since TIMESTAMP_NTZ has no timezone, direct comparison is safe and optimal. Options A and E, while seemingly straightforward, involve function calls for each row, which can be slower. Option B uses 'like' on a date converted to string, which is less efficient and can be problematic with different date formats. Option D converts the date to a VARCHAR, which is unnecessary and impacts performance.
NEW QUESTION # 200
You're developing a Snowpark Python application to process log files stored in an external stage 's3_logs'. These logs are in plain text, with each line representing a log entry. You need to filter log entries based on a specific keyword and extract timestamps from the matching lines. Which of the following approaches, using and Snowpark DataFrames, will efficiently accomplish this, avoiding unnecessary data transfer to the client?
Answer: B
Explanation:
Option E provides the most efficient solution. By using 'session.read.option('PATTERN', ' you load the data directly into a DataFrame within Snowflake. A UDTF (User-Defined Table Function) is then used to process each partition of the DataFrame, performing the filtering and timestamp extraction in parallel within the Snowflake environment, minimizing data transfer to the client. Option A is highly inefficient as it downloads all files to the client. Option B is less efficient than E because it processes all rows through a single UDF instead of distributed processing using UDTF. It also assumes all log data can be held in a single dataframe which can create memory issues Option C is similar to B and it uses UDF instead of UDTF making it less efficient. Option D introduces external dependencies to the solution.
NEW QUESTION # 201
You have developed a Snowpark application that uses a Python UDF to perform sentiment analysis on text data extracted from JSON files stored in a Snowflake stage. The UDF relies on a large pre-trained machine learning model that is loaded during the UDF initialization. After deploying the application, you observe that the UDF initialization is taking a significant amount of time, causing slow query performance. What are the three MOST effective strategies to optimize the UDF initialization time in this scenario?
Answer: A,D,E
Explanation:
Optimizing UDF initialization is crucial for performance. Option A is correct because caching the model using 'cachetoolS avoids reloading it for each UDF call. Option C is also correct; 'context.add_dependency' tells Snowflake to distribute and cache the model on worker nodes, further reducing load times. Option D avoids the need for the UDF to load the model, reducing the initialization step down entirely. Streamlit caching is not valid for Snowflake operations, making option E incorrect. 'SnowflakeFile' isn't best used within a UDF initializer as its inefficient, making option B incorrect.
NEW QUESTION # 202
You have a Snowpark DataFrame named 'products_df' with columns 'product_id' (INT), 'product_name' (VARCHAR), and 'price' (FLOAT). You want to create a new DataFrame called 'discounted_products df that includes all columns from 'products_df' plus a new column named 'discounted_price', which is calculated as the original price minus a discount percentage specified by the variable 'discount_rate' (e.g., 0.1 for 10%). The 'discount_rate' is stored in the database table named 'discount_table'. You want to load the rate to variable. Choose the correct ways to achieve this. (Select all that apply)





Answer: A,C,E
Explanation:
Options A, B and D provide valid ways to fetch 'discount_rate' as a single numerical value. And fetch the data and gets the first value from the first row. Similarly, gets the data and return the first row. However, Option C does not have LIMIT 1 and will not work. Option E fetches one row as one array, thus requires rate[0] to compute discounted_price.
NEW QUESTION # 203
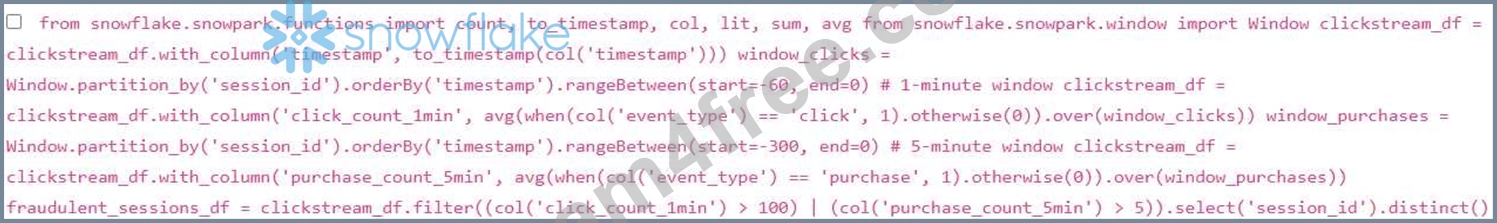
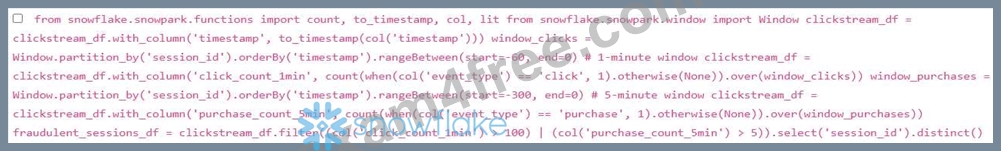
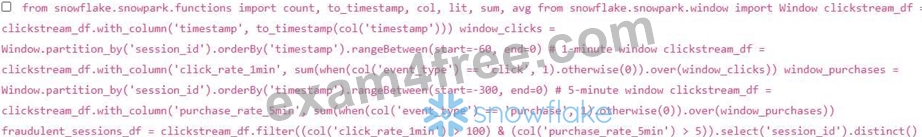
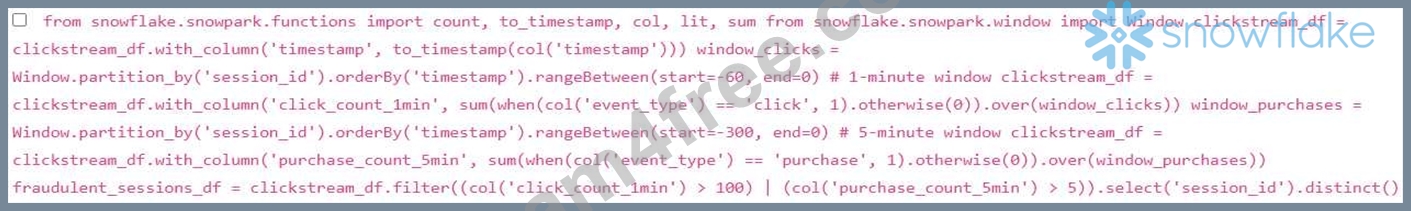
You are using Snowpark for Python to process a large dataset of website clickstream data'. The dataset contains columns such as 'session_id', 'user_id', 'timestamp', 'page_url', and 'event_type' (e.g., 'click', 'pageview', 'purchase'). You want to identify fraudulent user sessions based on the following criteria: A user session is considered fraudulent if it contains more than 100 clicks within a I-minute window. A user session is considered fraudulent if it contains more than 5 purchase events within a 5-minute window. Which of the following code snippets demonstrates the most efficient way to identify fraudulent sessions using Snowpark for Python? Select two that apply.

Answer: C,E
Explanation:
Options A and E are the most efficient and correct because they use window functions to calculate the click and purchase counts within the specified time windows and then filter the results based on the fraud criteria. Option A uses 'sum' on a conditional aggregation to count clicks and purchases. Option E Uses 'Count' and 'Otherwise(None)'. Option B is inefficient because it uses a UDF, which is slower than using built-in window functions. Options C and D are incorrect because 'click_rate_1min','purchase_rate_5min' are calculated incorrectly by making comparison, furthermore Option D uses average instead of SUM.
NEW QUESTION # 204
......
Passing the Snowflake SPS-C01 certification exam is necessary for professional development, and employing real Snowflake SPS-C01 Exam Dumps can assist applicants in reaching their professional goals. These actual SPS-C01 questions assist students in discovering areas in which they need improvement, boost confidence, and lower anxiety. Candidates will breeze through Snowflake SPS-C01 Certification examination with flying colors and advance to the next level of their jobs if they prepare with updated Snowflake SPS-C01 exam questions.
SPS-C01 Actual Dumps: https://www.exam4free.com/SPS-C01-valid-dumps.html
BONUS!!! Download part of Exam4Free SPS-C01 dumps for free: https://drive.google.com/open?id=1tw06EJgL02rs8ecg_y0TCwm2WkJWTJtW