P.S. Free & New AI-103 dumps are available on Google Drive shared by PrepAwayExam: https://drive.google.com/open?id=1MFPS8RK8x9BqBPaxPwFyYAP9vTNQ6m7x
With the rapid development of society, people pay more and more attention to knowledge and skills. So every year a large number of people take AI-103 tests to prove their abilities. But even the best people fail sometimes. In addition to the lack of effort, may also not make the right choice. A good choice can make one work twice the result with half the effort, and our AI-103 Study Materials will be your right choice.
| Section | Objectives |
|---|---|
| Implement Computer Vision Solutions | - OCR and document intelligence - Image classification and object detection |
| Knowledge Mining and Information Retrieval | - RAG (Retrieval Augmented Generation) patterns - Azure AI Search configuration - Indexing and semantic search |
| Implement Natural Language Processing Solutions | - Translation and multilingual support - Text analytics and summarization - Language understanding and intent recognition |
| Plan and Manage Azure AI Solutions | - Responsible AI principles and governance - Model selection and lifecycle management - Azure AI resource provisioning and configuration |
| Develop Generative AI Applications and Agents | - Azure OpenAI Service integration
|
As job seekers looking for the turning point of their lives, it is widely known that the workers of recruitment is like choosing apples---viewing resumes is liking picking up apples, employers can decide whether candidates are qualified by the AI-103 appearances, or in other words, candidates’ educational background and relating AI-103 professional skills. The reason why we are so confident lies in the sophisticated expert group and technical team we have, which do duty for our solid support. They develop the AI-103 Exam Guide targeted to real exam. The wide coverage of important knowledge points in our AI-103 latest braindumps would be greatly helpful for you to pass the exam.
NEW QUESTION # 28
You have a Microsoft Foundry project that contains a customer support agent. The agent calls an internal knowledge API tool before generating responses.
Users report the following issues:
- Some requests take more than 15 seconds to complete.
- Some responses are incorrect, even when the knowledge API returns the expected data.
You need to inspect individual agent runs to view the ordered sequence of large language model (LLM) calls, tool invocations, and timing information.
Which observability capability should you use?
Answer: D
Explanation:
Here is LLM tracing (also known as trace view or distributed tracing for GenAI) needed.
Tracks Execution Flow: It captures the exact ordered sequence of LLM calls and tool invocations.
Pinpoints Latency: It provides timestamps and durations for every individual step to catch the 15- second bottlenecks.
Inspects Inputs/Outputs: It lets you see the exact payload sent to and from the knowledge API and the final LLM prompt to find out why the agent hallucinated or ignored the data.
Reference:
https://coralogix.com/ai-blog/advanced-techniques-for-monitoring-traces-in-ai-workflows/
NEW QUESTION # 29
You have a Microsoft Foundry project that contains an agent. The agent generates summaries from retrieved policy documents.
You need to improve response completeness. The solution must be implemented in the logic of the application code before responses are returned.
What should you do?
Answer: B
Explanation:
To enhance response completeness in your Microsoft Foundry agent, you must intercept the retrieved documents and the generated summary within your backend application logic before returning the payload to the user.
1. Implement Completeness Verification Logic
Add a verification step in your orchestration code (e.g., in your Python/Semantic Kernel or LangChain pipeline) that compares the generated summary against the retrieved chunks.' Map Key Assertions: Extract main policy rules from retrieved text.Cross-Reference Entities: Verify all key entities are in the summary.
Check Scope Coverage: Ensure every retrieved document is represented.
Scan for Gaps: Identify critical missing constraints or exceptions.
2. Apply Application-Level Mitigation Strategies
If the verification step detects that the summary is incomplete, use your code to correct it before the final response leaves your system.
Reference:
https://dev.to/moonrunnerkc/how-i-built-a-verification-layer-for-copilot-clis-multi-agent-output-4b7h
NEW QUESTION # 30
You have a Microsoft Foundry project.
You plan to build a customer support solution that contains an agent. The solution must meet the following requirements:
- Provide accurate, context-aware responses grounded in internal
product documentation stored in Azure AI Search.
- Require deep, multi-step reasoning across long contexts.
- Generate detailed natural language responses.
Which type of model should you use to power the agent?
Answer: B
Explanation:
For a support agent requiring deep multi-step reasoning, long context processing, and strict grounding in internal documents, the GPT-5.5 (or GPT-5.5-Pro) model from the Azure AI Foundry model catalog is the best choice.
Here is how GPT-5.5 directly addresses the requirements:
Deep Multi-Step Reasoning: These frontier models use deliberate reasoning and iterative planning before generating a response. This allows the agent to decompose complex support queries, analyze alternatives, and prevent hallucinations without requiring heavy custom prompt engineering.
Grounded, Accurate Responses:
Rather than doing this alone, pair the model with Foundry IQ connected to your Azure AI Search indices. Foundry IQ's agentic retrieval engine will pull exactly the right context, allowing GPT-5.5 to synthesize the answer and cite the original documentation.
Long Context Handling:
GPT-5.5 models support massive context windows, allowing them to ingest extensive previous conversational turns alongside detailed internal documentation in a single pass without losing track of important rules.
Note:
GPT-5.5 is a large language model (LLM).While it is a flagship LLM built on OpenAI's advanced transformer architecture, it also features natively omnimodal capabilities that allow it to process both text and images seamlessly within a single unified framework. However, when choosing between the specific categories provided, its primary core classification is a Large Language Model (LLM).
Key Details About GPT-5.5
Core Architecture: Large Language Model (LLM) built by OpenAI.
Primary Focus: Highly optimized for complex reasoning, multi-step problem solving, coding, and autonomous agentic workflows.
Input/Output Capabilities: Supports text and image inputs with text-based outputs.
Reference:
https://developers.openai.com/api/docs/guides/reasoning
NEW QUESTION # 31
You have a Microsoft Foundry project that contains an agent.
The agent uses tools to retrieve internal content and call external APIs. The agent is configured to let the model decide when to call the tools.
You need to publish the agent for a compliance workflow. The solution must meet the following requirements:
* Each workflow run must include a retrieval step before generating a response.
* Tool calls must authenticate by using the published agent's own identity.
* Tool access must use an identity isolated from other project resources.
* Tool access must support audit tracing.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.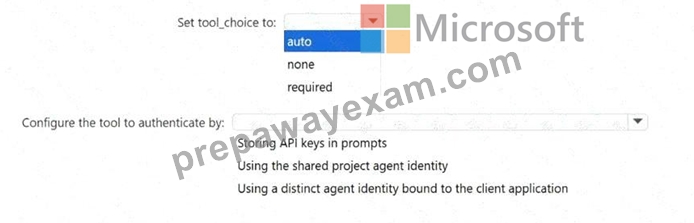
Answer:
Explanation: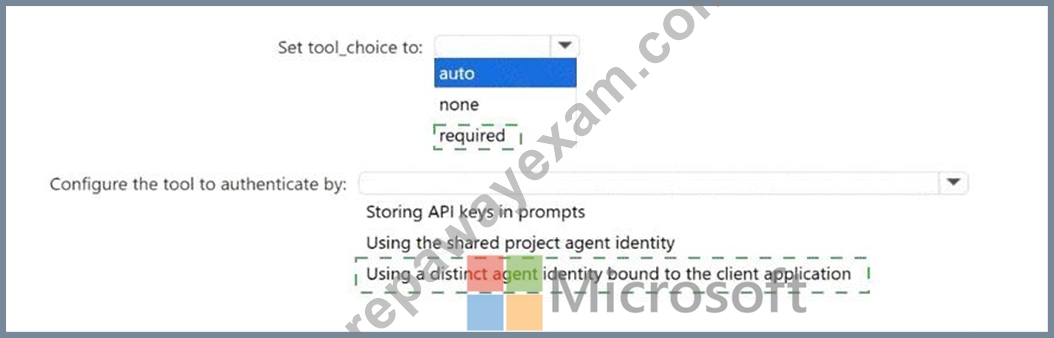
Explanation:
Set tool_choice to: required
Configure the tool to authenticate by: Using a distinct agent identity bound to the client application Set tool_choice to required because the compliance workflow must deterministically include a tool-based retrieval step before the agent generates a response. Microsoft Foundry Agent Service guidance states that tool_choice provides the most deterministic control over tool use: auto lets the model decide, none prevents tool calls, and required forces the model to call one or more tools. This directly corrects the current nondeterministic behavior where the model decides whether to call tools.
For authentication, use a distinct agent identity bound to the client application . Microsoft Foundry creates a shared identity for unpublished or in-development agents, but publishing an agent automatically creates a dedicated agent identity blueprint and agent identity associated with the agent application resource. Published agents authenticate tool calls by using that unique agent identity, and RBAC permissions must be assigned to the new identity. This provides isolation from the broader shared project identity and supports independent audit trails for compliance workflows.
Storing API keys in prompts violates security guidance and prevents robust audit attribution. The shared project agent identity is easier for development, but it has a broader blast radius and does not meet the isolation requirement. Reference topics: Foundry Agent Service tool choice, tool authentication, published agent identities, RBAC, and auditability.
NEW QUESTION # 32
You have a Microsoft Foundry project.
You plan to build a customer support solution that contains an agent. The solution must meet the following requirements:
* Provide accurate, context-aware responses grounded in internal product documentation stored in Azure AI Search.
* Require deep, multi-step reasoning across long contexts.
* Generate detailed natural language responses.
Which type of model should you use to power the agent?
Answer: B
Explanation:
The correct model type is a large language model (LLM) . The scenario requires an agent that can reason over retrieved documentation, synthesize context-aware answers, and generate detailed natural language responses. Microsoft Foundry RAG guidance defines Retrieval Augmented Generation as a pattern that combines search with large language models so responses are grounded in organizational data, which directly matches the use of Azure AI Search for internal product documentation.
An LLM is also the correct fit for deep, multi-step reasoning across long contexts. Azure AI Search agentic retrieval guidance states that complex chat and agent scenarios use an LLM to break a user query into smaller focused subqueries for better coverage over indexed content. Microsoft also describes Azure AI Search as a way to ground agents and chatbots in proprietary enterprise data for accurate, context-aware responses.
A multimodal model is unnecessary because the requirements are text-focused, not image, audio, or video based. A key phrase extraction model performs narrow text analytics and cannot generate detailed answers.
An SLM may reduce cost and latency, but the stated need for deep reasoning and long-context synthesis favors an LLM. Reference topics: Microsoft Foundry RAG, Azure AI Search grounding, agentic retrieval, and model selection for generative AI agents.
NEW QUESTION # 33
......
The client can try out and download our AI-103 training materials freely before their purchase so as to have an understanding of our product and then decide whether to buy them or not. The website pages of our product provide the details of our AI-103 learning questions. You can see the demos which are part of the all titles selected from the test bank and the forms of the questions and answers and know the form of our software on the website pages of our study materials.
AI-103 Exam Braindumps: https://www.prepawayexam.com/Microsoft/braindumps.AI-103.ete.file.html
DOWNLOAD the newest PrepAwayExam AI-103 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1MFPS8RK8x9BqBPaxPwFyYAP9vTNQ6m7x