順便提一下,可以從雲存儲中下載VCESoft Databricks-Generative-AI-Engineer-Associate考試題庫的完整版:https://drive.google.com/open?id=1jPXiacvg0dmBbQFqvKAQY_jMNuJixNts
在VCESoft網站上你可以免費下載我們提供的關於Databricks Databricks-Generative-AI-Engineer-Associate認證考試的部分考題及答案測驗我們的可靠性。VCESoft提供的產品是可以100%把你推上成功,那麼IT行業的巔峰離你又近了一步。
| 主題 | 簡介 |
|---|---|
| 主題 1 |
|
| 主題 2 |
|
| 主題 3 |
|
| 主題 4 |
|
>> Databricks-Generative-AI-Engineer-Associate信息資訊 <<
通過Databricks-Generative-AI-Engineer-Associate認證考試好像是一件很難的事情。已經報名參加考試的你,現在正在煩惱應該怎麼準備考試嗎?如果是這樣的話,請看下面的內容,我現在告訴你通過Databricks-Generative-AI-Engineer-Associate考試的捷徑。可以讓你一次就通過考試的優秀的Databricks-Generative-AI-Engineer-Associate考試資料出現了。它就是VCESoft的Databricks-Generative-AI-Engineer-Associate考古題。如果你想輕鬆通過考試,那麼快來試試吧。
問題 #56
A Generative AI Engineer has deployed a RAG application to production. Its Vector Search index is built from a Delta table that receives incremental updates every hour from an upstream ETL pipeline. The team wants the index to automatically reflect source-table changes without manual re-indexing and without changing the endpoint used by downstream applications.
Which approach should the engineer use?
答案:A
解題說明:
D identifies the index type designed to synchronize with a source Delta table. Delta Sync supports incremental maintenance, avoiding a custom process that repeatedly rebuilds the complete index or manually pushes every changed vector. A Direct Vector Access index transfers update responsibility to the application.
However, this question has a configuration ambiguity: Delta Sync also has a synchronization mode.
Continuous mode processes arriving changes automatically, while triggered mode requires an explicit synchronization request, which can be scheduled after ETL. If the existing index is already a triggered Delta Sync index, B is the relevant configuration change. D is therefore the intended architectural answer, with continuous synchronization or an automated trigger needed to deliver the requested operational behavior.
Databricks API documentation
問題 #57
A Generative AI Engineer needs to allocate costs for an agent deployed via Agent Framework behind AI Gateway. The finance team requires daily reporting by workspace and endpoint, including token usage and request counts. The engineer wants to query this data with SQL and join it to an internal cost-center mapping table.
Which table type best serves their needs?
答案:A
解題說明:
The AI Gateway usage table is designed to capture operational consumption information for SQL-based reporting. Its records include identifiers for the workspace, endpoint, and request, together with token-usage information and timestamps. The engineer can aggregate consumption by day and endpoint, then join those results to the company's cost-center mapping. Request counting should respect the table's request and invocation identifiers because a single logical request can involve multiple inference calls. Served-entity metadata describes deployed entities rather than providing the primary consumption records. Inference tables emphasize request and response payloads, while MLflow runs organize experiments and evaluations. Token consumption supports cost allocation, but calculating actual monetary charges may additionally require applicable pricing or billing records. Databricks documentation
問題 #58
A Generative Al Engineer is building a system that will answer questions on currently unfolding news topics. As such, it pulls information from a variety of sources including articles and social media posts. They are concerned about toxic posts on social media causing toxic outputs from their system.
Which guardrail will limit toxic outputs?
答案:D
解題說明:
The system answers questions on unfolding news topics using articles and social media, with a concern about toxic outputs from toxic inputs. A guardrail must limit toxicity in the LLM's responses. Let's evaluate the options.
Option A: Use only approved social media and news accounts to prevent unexpected toxic data from getting to the LLM Curating input sources (e.g., verified accounts) reduces exposure to toxic content at the data ingestion stage, directly limiting toxic outputs. This is a proactive guardrail aligned with data quality control.
Databricks Reference: "Control input data quality to mitigate unwanted LLM behavior, such as toxicity" ("Building LLM Applications with Databricks," 2023).
Option B: Implement rate limiting
Rate limiting controls request frequency, not content quality. It prevents overload but doesn't address toxicity in social media inputs or outputs.
Databricks Reference: Rate limiting is for performance, not safety: "Use rate limits to manage compute load" ("Generative AI Cookbook").
Option C: Reduce the amount of context items the system will include in consideration for its response Reducing context might limit exposure to some toxic items but risks losing relevant information, and it doesn't specifically target toxicity. It's an indirect, imprecise fix.
Databricks Reference: Context reduction is for efficiency, not safety: "Adjust context size based on performance needs" ("Databricks Generative AI Engineer Guide").
Option D: Log all LLM system responses and perform a batch toxicity analysis monthly Logging and analyzing responses is reactive, identifying toxicity after it occurs rather than preventing it. Monthly analysis doesn't limit real-time toxic outputs.
Databricks Reference: Monitoring is for auditing, not prevention: "Log outputs for post-hoc analysis, but use input filters for safety" ("Building LLM-Powered Applications").
Conclusion: Option A is the most effective guardrail, proactively filtering toxic inputs from unverified sources, which aligns with Databricks' emphasis on data quality as a primary safety mechanism for LLM systems.
問題 #59
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.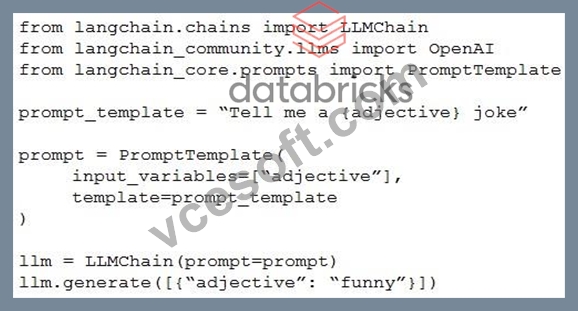
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
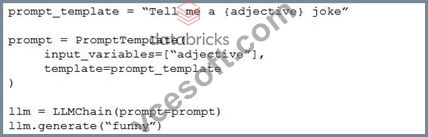
答案:C
解題說明:
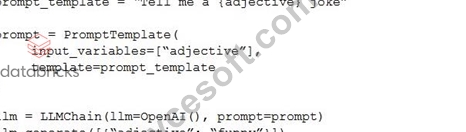
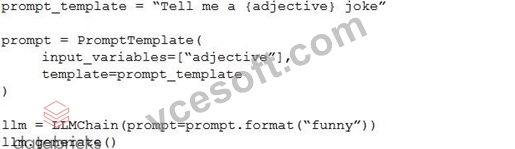
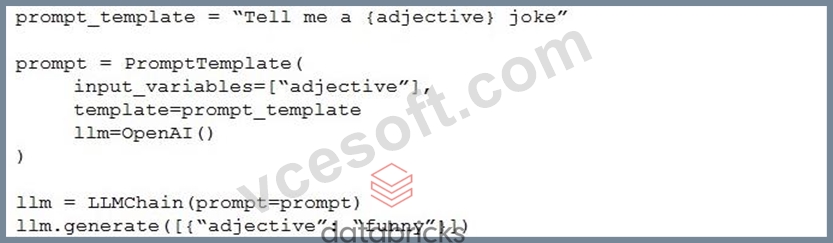
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
Correct Use of Classes and Methods:
The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
問題 #60
A Generative Al Engineer is setting up a Databricks Vector Search that will lookup news articles by topic within 10 days of the date specified An example query might be "Tell me about monster truck news around January 5th 1992". They want to do this with the least amount of effort.
How can they set up their Vector Search index to support this use case?
答案:B
解題說明:
The task is to set up a Databricks Vector Search index for news articles, supporting queries like "monster truck news around January 5th, 1992," with minimal effort. The index must filter by topic and a 10-day date range. Let's evaluate the options.
* Option A: Split articles by 10-day blocks and return the block closest to the query
* Pre-splitting articles into 10-day blocks requires significant preprocessing and index management (e.g., one index per block). It's effort-intensive and inflexible for dynamic date ranges.
* Databricks Reference:"Static partitioning increases setup complexity; metadata filtering is preferred"("Databricks Vector Search Documentation").
* Option B: Include metadata columns for article date and topic to support metadata filtering
* Adding date and topic as metadata in the Vector Search index allows dynamic filtering (e.g., date
± 5 days, topic = "monster truck") at query time. This leverages Databricks' built-in metadata filtering, minimizing setup effort.
* Databricks Reference:"Vector Search supports metadata filtering on columns like date or category for precise retrieval with minimal preprocessing"("Vector Search Guide," 2023).
* Option C: Pass the query directly to the vector search index and return the best articles
* Passing the full query (e.g., "Tell me about monster truck news around January 5th, 1992") to Vector Search relies solely on embeddings, ignoring structured filtering for date and topic. This risks inaccurate results without explicit range logic.
* Databricks Reference:"Pure vector similarity may not handle temporal or categorical constraints effectively"("Building LLM Applications with Databricks").
* Option D: Create separate indexes by topic and add a classifier model to appropriately pick the best index
* Separate indexes per topic plus a classifier model adds significant complexity (index creation, model training, maintenance), far exceeding "least effort." It's overkill for this use case.
* Databricks Reference:"Multiple indexes increase overhead; single-index with metadata is simpler"("Databricks Vector Search Documentation").
Conclusion: Option B is the simplest and most effective solution, using metadata filtering in a single Vector Search index to handle date ranges and topics, aligning with Databricks' emphasis on efficient, low-effort setups.
問題 #61
......
我們VCESoft Databricks的Databricks-Generative-AI-Engineer-Associate考試認證資料是全球所有網站不能夠媲美的,當然這不僅僅是品質的問題,我們的品質肯定是沒得說,更重要的是我們VCESoft Databricks的Databricks-Generative-AI-Engineer-Associate考試認證資料適合所有的IT考試認證,它的使用性達到各個IT領域,所以我們VCESoft網站得到很多考生的關注,他們相信我們,依賴我們,這也是我們VCESoft網站所擁有的實力所體現之處,我們的考試培訓資料能讓你買了之後不得不向你的朋友推薦,並讚不絕口,因為它真的對你們有很大的幫助。
Databricks-Generative-AI-Engineer-Associate考古題介紹: https://www.vcesoft.com/Databricks-Generative-AI-Engineer-Associate-pdf.html
BONUS!!! 免費下載VCESoft Databricks-Generative-AI-Engineer-Associate考試題庫的完整版:https://drive.google.com/open?id=1jPXiacvg0dmBbQFqvKAQY_jMNuJixNts