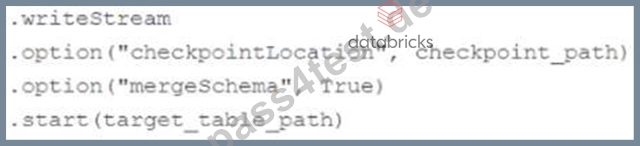
Databricks Certified-Data-Engineer-Professional Deutsch Prüfungsfragen - Certified-Data-Engineer-Professional Prüfungsmaterialien

Wenn Sie die Fragen und Antworten zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung kaufen, können Sie nicht nur die Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung erfolgreich bestehen, sonder einen einjährigen kostenlosen Update-Service genießen. Falls Sie in der Prüfung durchfallen, zahlen wir Ihnen die gesammte Summe zurück. Sie können im Internet teilweise die Fragen und Antworten zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung kostenlos als Probe herunterladen, um die Zuverlässigkeit unserer Produkte zu prüfen.
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Apply Change Data Feed to address streaming table limitations and improve latency
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
| Topic 2: Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Topic 3: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Create pipeline components using control flow operators such as if/else and foreach
- 2. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 3. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 4. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 5. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 6. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 7. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 8. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
|
| Topic 4: Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Query Profile and Spark UI to monitor workloads
- 4. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
|
| Topic 5: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Topic 6: Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Design and implement scalable data models using Delta Lake to manage large datasets
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Identify the benefits of liquid clustering over partitioning and Z-Ordering
|
| Topic 7: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Topic 8: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Topic 9: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 10: Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
- Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Use row filters and column masks to protect sensitive table data
|
>> Databricks Certified-Data-Engineer-Professional Deutsch Prüfungsfragen <<
Databricks Certified-Data-Engineer-Professional Prüfungsmaterialien, Certified-Data-Engineer-Professional Ausbildungsressourcen
Vielleicht können Sie auch die relevanten Databricks Certified-Data-Engineer-Professional Schulungsunterlagen in anderen Büchern oder auf anderen Websites finden. Aber wenn Sie die Produkte von Pass4Test mit ihnen vergleichen, würden Sie herausfinden, dass unsere Produkte mehr Wissensgebiete umfassen. Sie können auch im Internet teilweise die Fragen und Antworten zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung kostenlos herunterladen, so dass Sie die Qualität unserer Produkte testen können. Die Gründe, dass Pass4Test exklusiv umfassende Materialien von guter Qualität bieten können, liegt darin, dass wir ein exzellentes Expertenteam hat. Sie bearbeiten die neuesten Fragen und Antworten zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung nach ihren IT-Kenntnissen und Erfahrungen. Deshalb sind die Fragen und Antworten zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung von Pass4Test bei den Kandidaten ganz beliebt.
Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional Prüfungsfragen mit Lösungen (Q17-Q22):
17. Frage
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in the geo_lookup table.
Before executing the code, running SHOW TABLES on the current database indicates the database contains only two tables: geo_lookup and sales.
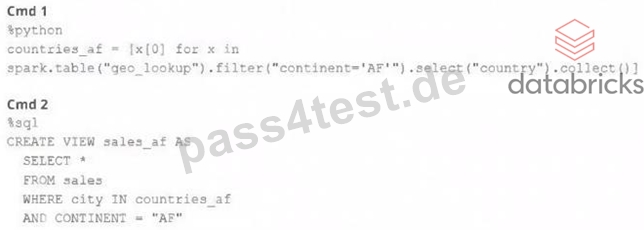
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
- A. Both commands will succeed. Executing show tables will show that countries at and sales at have been registered as views.
- B. Both commands will fail. No new variables, tables, or views will be created.
- C. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable containing a list of strings.
- D. Cmd 1 will succeed. Cmd 2 will search all accessible databases for a table or view named countries af: if this entity exists, Cmd 2 will succeed.
- E. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable representing a PySpark DataFrame.
Antwort: C
Begründung:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view.
Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter.
18. Frage
A data engineer is optimizing a managed Delta table that suffers from data skew and frequently changing query filter columns. The engineer wants to avoid costly data rewrites when query patterns evolve. The table size is under 1 TB. How should the data engineer meet this requirement?
- A. Combine partitioning and Z-ordering to maximize flexibility and minimize maintenance as query patterns change.
- B. Use Hive-style partitioning, as it provides efficient data skipping and is easy to change partition columns at any time.
- C. Enable liquid clustering, as it efficiently handles data skew, allows clustering keys to be changed without rewriting existing data, and adapts to evolving query patterns.
- D. Apply Z-ordering, since it allows flexible reorganization of data layout without rewriting existing files and adapts easily to new filter columns.
Antwort: C
Begründung:
Liquid clustering is designed for managed tables under 1TB with evolving query patterns. It efficiently addresses data skew, continuously optimizes data layout, and allows clustering keys to be changed without requiring full data rewrites, making it well suited for frequently changing filter columns while minimizing maintenance overhead.
19. Frage
Which statement describes a key benefit of an end-to-end test?
- A. It pinpoint errors in the building blocks of your application.
- B. It makes it easier to automate your test suite
- C. It closely simulates real world usage of your application.
- D. It provides testing coverage for all code paths and branches.
Antwort: C
Begründung:
End-to-end testing is a methodology used to test whether the flow of an application, from start to finish, behaves as expected. The key benefit of an end-to-end test is that it closely simulates real- world, user behavior, ensuring that the system as a whole operates correctly.
20. Frage
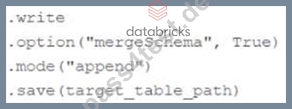
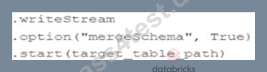
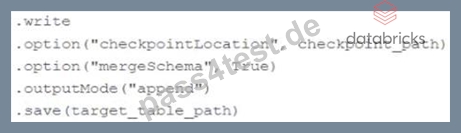
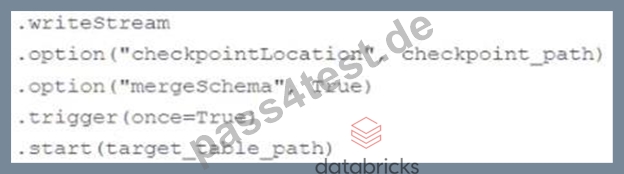
In order to facilitate near real-time workloads, a data engineer is creating a helper function to leverage the schema detection and evolution functionality of Databricks Auto Loader. The desired function will automatically detect the schema of the source directly, incrementally process JSON files as they arrive in a source directory, and automatically evolve the schema of the table when new fields are detected.
The function is displayed below with a blank:
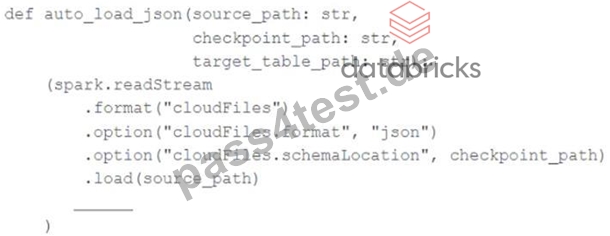
Which response correctly fills in the blank to meet the specified requirements?
Antwort: E
Begründung:
https://docs.databricks.com/en/ingestion/auto-loader/schema.html
21. Frage
A data engineer is evaluating tools to build a production-grade data pipeline. The team must process change data from cloud object storage, filter out or isolate invalid records, and ensure the timely delivery of clean data to downstream consumers. The team is small, under tight deadlines, and wants to minimize operational overhead while keeping pipelines auditable and maintainable.
Which approach should the data engineer implement?
- A. Use LDP to build declarative pipelines with Streaming Tables and Materialized Views, leveraging built-in support for data expectations and incremental processing.
- B. Use a hybrid approach: Ingest with Auto Loader into Bronze tables, then process using SQL queries in Databricks Workflows to generate cleaned Silver and Gold tables on a schedule.
- C. Implement ingestion using Auto Loader with Structured Streaming, and manage invalid data handling and table updates using checkpointing and merge logic.
- D. Ingest data directly into Delta tables via Spark jobs, apply data quality filters using UDFs, and use LDP for creating Materialized Views.
Antwort: A
Begründung:
LDP provides a declarative framework for building production-grade pipelines with minimal operational overhead. Streaming Tables and Materialized Views handle incremental processing automatically, while built-in data expectations allow invalid records to be filtered or isolated in a consistent and auditable way. This approach is well suited for small teams under tight deadlines, as it simplifies maintenance, improves reliability, and ensures timely delivery of clean data to downstream consumers.
22. Frage
......
Wenn Sie die richtige Methode benutzen, haben Sie schon halben Erfolg erhalten. Wir Pass4Test bieten Ihnen die effizienteste Methode für Databricks Certified-Data-Engineer-Professional Prüfung, die von unseren erfahrenen Forschungs-und Entwicklungsstellen hergestellt wird. Auf unserer offiziellen Webseite können Sie durch Paypal die Databricks Certified-Data-Engineer-Professional Prüfungsunterlagen gesichert kaufen. Wir werden Ihre Persönliche Informationen und Zahlungsinformationen gut bewahren und bieten Ihnen nach dem Kauf der Databricks Certified-Data-Engineer-Professional Unterlagen immer weiter hochwertigen Dienst.
Certified-Data-Engineer-Professional Prüfungsmaterialien: https://www.pass4test.de/Certified-Data-Engineer-Professional.html
- Certified-Data-Engineer-Professional Fragen&Antworten 🕚 Certified-Data-Engineer-Professional Trainingsunterlagen ❓ Certified-Data-Engineer-Professional Online Tests 👊 Suchen Sie auf 【 www.it-pruefung.com 】 nach kostenlosem Download von “ Certified-Data-Engineer-Professional ” ⏸Certified-Data-Engineer-Professional Online Tests
- Certified-Data-Engineer-Professional Vorbereitungsfragen 🔛 Certified-Data-Engineer-Professional Fragen&Antworten 🌄 Certified-Data-Engineer-Professional Echte Fragen 🦑 { www.itzert.com } ist die beste Webseite um den kostenlosen Download von 【 Certified-Data-Engineer-Professional 】 zu erhalten 🖕Certified-Data-Engineer-Professional Trainingsunterlagen
- Certified-Data-Engineer-Professional Prüfungsunterlagen 📭 Certified-Data-Engineer-Professional Vorbereitung 🧢 Certified-Data-Engineer-Professional Echte Fragen 💔 Suchen Sie jetzt auf 《 www.echtefrage.top 》 nach “ Certified-Data-Engineer-Professional ” um den kostenlosen Download zu erhalten ⏪Certified-Data-Engineer-Professional Echte Fragen
- Certified-Data-Engineer-Professional Übungsfragen: Databricks Certified Data Engineer Professional - Certified-Data-Engineer-Professional Dateien Prüfungsunterlagen 💰 Suchen Sie auf ☀ www.itzert.com ️☀️ nach “ Certified-Data-Engineer-Professional ” und erhalten Sie den kostenlosen Download mühelos 🕥Certified-Data-Engineer-Professional Trainingsunterlagen
- Certified-Data-Engineer-Professional Examengine 🍮 Certified-Data-Engineer-Professional Prüfungsunterlagen ☘ Certified-Data-Engineer-Professional Originale Fragen 🆚 Erhalten Sie den kostenlosen Download von ▷ Certified-Data-Engineer-Professional ◁ mühelos über ▷ www.zertpruefung.ch ◁ 📰Certified-Data-Engineer-Professional Online Praxisprüfung
- Certified-Data-Engineer-Professional Deutsch Prüfung 🏓 Certified-Data-Engineer-Professional Antworten 🎇 Certified-Data-Engineer-Professional Online Tests 👔 Erhalten Sie den kostenlosen Download von ▶ Certified-Data-Engineer-Professional ◀ mühelos über ⮆ www.itzert.com ⮄ 😃Certified-Data-Engineer-Professional Echte Fragen
- Wir machen Certified-Data-Engineer-Professional leichter zu bestehen! 🎱 URL kopieren 「 www.deutschpruefung.com 」 Öffnen und suchen Sie ➥ Certified-Data-Engineer-Professional 🡄 Kostenloser Download 🤶Certified-Data-Engineer-Professional Vorbereitung
- Certified-Data-Engineer-Professional Vorbereitungsfragen 🔻 Certified-Data-Engineer-Professional Prüfungsinformationen 🏚 Certified-Data-Engineer-Professional Schulungsangebot 🥰 Suchen Sie auf [ www.itzert.com ] nach { Certified-Data-Engineer-Professional } und erhalten Sie den kostenlosen Download mühelos 🆘Certified-Data-Engineer-Professional Fragenpool
- Certified-Data-Engineer-Professional Trainingsunterlagen 🥽 Certified-Data-Engineer-Professional Prüfungs-Guide 🤸 Certified-Data-Engineer-Professional Antworten 🤖 Suchen Sie jetzt auf 《 de.fast2test.com 》 nach 「 Certified-Data-Engineer-Professional 」 um den kostenlosen Download zu erhalten ✒Certified-Data-Engineer-Professional Übungsmaterialien
- Certified-Data-Engineer-Professional Übungsmaterialien - Certified-Data-Engineer-Professional Lernressourcen - Certified-Data-Engineer-Professional Prüfungsfragen 🍦 Suchen Sie auf 【 www.itzert.com 】 nach kostenlosem Download von ➡ Certified-Data-Engineer-Professional ️⬅️ 💥Certified-Data-Engineer-Professional Examengine
- Certified-Data-Engineer-Professional Übungsmaterialien - Certified-Data-Engineer-Professional Lernressourcen - Certified-Data-Engineer-Professional Prüfungsfragen 🗺 Suchen Sie jetzt auf ✔ de.fast2test.com ️✔️ nach ➠ Certified-Data-Engineer-Professional 🠰 um den kostenlosen Download zu erhalten 🕴Certified-Data-Engineer-Professional Originale Fragen
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, telegra.ph, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes