P.S. Free & New Databricks-Certified-Data-Analyst-Associate dumps are available on Google Drive shared by ExamDiscuss: https://drive.google.com/open?id=1zbk9HhOmcUHbzgp1K2LX5hCQL7uvuT5Q
Are you looking for valid IT exam materials or study guide? You can try our free Databricks Databricks-Certified-Data-Analyst-Associate new exam collection materials. We offer free demo download for our PDF version. You can know several questions of the real test. It can make you master fundamental knowledge quickly. Our Databricks-Certified-Data-Analyst-Associate new exam collection materials are authorized legal products. Our accuracy is nearly 100% pass which will help you clear exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> Databricks-Certified-Data-Analyst-Associate Test Price <<
This desktop practice exam software completely depicts the Databricks Databricks-Certified-Data-Analyst-Associate exam scenario with proper rules and regulations and any other plugins to access Databricks Databricks-Certified-Data-Analyst-Associate Practice Test. One such trustworthy point about exam preparation material is that it first gains your trust, and then asks you to purchase it.
NEW QUESTION # 102
A data engineer wants to schedule their Databricks SQL dashboard to refresh once per day, but they only want the associated SQL endpoint to be running when it is necessary.
Which of the following approaches can the data engineer use to minimize the total running time of the SQL endpoint used in the refresh schedule of their dashboard?
Answer: C
Explanation:
Option C is correct because Auto Stop is specifically designed to stop a SQL warehouse when it has been idle for a configured number of minutes. This minimizes total warehouse running time after the scheduled dashboard refresh completes. Reducing cluster size may reduce hourly cost but does not stop the warehouse.
Serverless can help with management, but the feature directly matching "only running when necessary" is Auto Stop. Official Databricks extract: "Auto Stop determines whether the warehouse stops if it's idle for the specified number of minutes." Databricks also notes that idle SQL warehouses continue to accumulate charges until stopped.
NEW QUESTION # 103
Which of the following SQL keywords can be used to convert a table from a long format to a wide format?
Answer: C
Explanation:
Option B is correct. PIVOT rotates unique values from rows into separate columns, which is exactly the process of converting long-format data into wide-format data. UNPIVOT does the reverse. SUM is an aggregate function, WHERE filters rows, and TRANSFORM is not the SQL keyword used for this reshaping task. Official Databricks extract: the PIVOT clause "rotat[es] unique values from a column into separate columns."
NEW QUESTION # 104
Consider the following two statements:
Statement 1: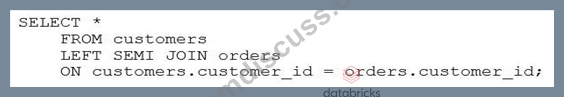
Statement 2: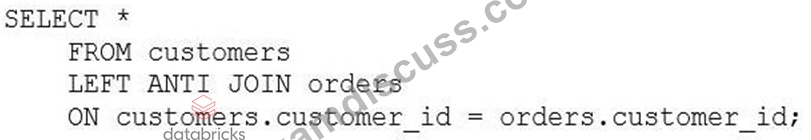
Which of the following describes how the result sets will differ for each statement when they are run in Databricks SQL?
Answer: D
Explanation:
Based on the images you sent, the two statements are SQL queries for different types of joins between the customers and orders tables. A join is a way of combining the rows from two table references based on some criteria. The join type determines how the rows are matched and what kind of result set is returned. The first statement is a query for a LEFT SEMI JOIN, which returns only the rows from the left table reference (customers) that have a match with the right table reference (orders) on the join condition (customer_id). The second statement is a query for a LEFT ANTI JOIN, which returns only the rows from the left table reference (customers) that have no match with the right table reference (orders) on the join condition (customer_id). Therefore, the result sets for the two statements will differ in the following way:
The first statement will return a subset of the customers table that contains only the customers who have placed at least one order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT SEMI JOIN does not include any columns from the orders table.
The second statement will return a subset of the customers table that contains only the customers who have not placed any order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have no orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT ANTI JOIN does not include any columns from the orders table.
The other options are not correct because:
A) The first statement will not return all data from the customers table, as it will exclude the customers who have no orders. The second statement will not return all data from the orders table, as it will exclude the orders that have a matching customer. Neither statement will fill in any missing data with NULL, as they do not return any columns from the other table.
C) There is a difference between the result sets for both statements, as explained above. The LEFT SEMI JOIN and the LEFT ANTI JOIN are not equivalent operations and will produce different outputs.
D) Both statements will not fail, as Databricks SQL does support those join types. Databricks SQL supports various join types, including INNER, LEFT OUTER, RIGHT OUTER, FULL OUTER, LEFT SEMI, LEFT ANTI, and CROSS. You can also use NATURAL, USING, or LATERAL keywords to specify different join criteria.
E) The first statement will not return only the customer_id from the orders table, as it will return all columns from the customers table. The second statement is correct, but it is not the only difference between the result sets.
NEW QUESTION # 105
A data analyst needs to share a Databricks SQL dashboard with stakeholders that are not permitted to have accounts in the Databricks deployment. The stakeholders need to be notified every time the dashboard is refreshed.
Which approach can the data analyst use to accomplish this task with minimal effort/
Answer: D
Explanation:
To share a Databricks SQL dashboard with stakeholders who do not have accounts in the Databricks deployment and ensure they are notified upon each refresh, the data analyst can add the stakeholders ' email addresses to the dashboard ' s refresh schedule subscribers list. This approach allows the stakeholders to receive email notifications containing the latest dashboard updates without requiring them to have direct access to the Databricks workspace. This method is efficient and minimizes effort, as it automates the notification process and ensures stakeholders remain informed of the most recent data insights.
Reference: Manage scheduled dashboard updates and subscriptions
NEW QUESTION # 106
In a healthcare provider organization using Delta Lake to store electronic health records, a data analyst needs to analyze a snapshot of the patient_records table from two weeks ago before some recent data corrections were applied.
What approach should the Data Engineer take to allow the analyst to query that specific prior version?
Answer: A
Explanation:
Option B is correct. Delta Lake supports time travel, which allows users to query previous table versions by timestamp or version number. The version can be obtained from table history and queried using VERSION AS OF. Restoring the table would change the current table state for everyone, which is not necessary when the analyst only needs to analyze a historical snapshot. VACUUM would remove old data files and can prevent time travel. Official Databricks extract: time travel supports "querying previous table versions," and the syntax includes SELECT * FROM people10m VERSION AS OF 123. Databricks also states that the version can be obtained from DESCRIBE HISTORY. Note: the two-week snapshot is queryable only if the required log and data files are still retained.
NEW QUESTION # 107
......
You only need 20-30 hours to learn our Databricks-Certified-Data-Analyst-Associate test braindumps and then you can attend the exam and you have a very high possibility to pass the exam. For many people whether they are the in-service staff or the students they are busy in their job, family lives and other things. But you buy our Databricks-Certified-Data-Analyst-Associate prep torrent you can mainly spend your time energy and time on your job, the learning or family lives and spare little time every day to learn our Databricks Certified Data Analyst Associate Exam exam torrent. Our answers and questions are compiled elaborately and easy to be mastered. Because our Databricks-Certified-Data-Analyst-Associate Test Braindumps are highly efficient and the passing rate is very high you can pass the exam fluently and easily with little time and energy needed.
Databricks-Certified-Data-Analyst-Associate Latest Exam Forum: https://www.examdiscuss.com/Databricks/exam/Databricks-Certified-Data-Analyst-Associate/
BONUS!!! Download part of ExamDiscuss Databricks-Certified-Data-Analyst-Associate dumps for free: https://drive.google.com/open?id=1zbk9HhOmcUHbzgp1K2LX5hCQL7uvuT5Q