P.S. PassTestがGoogle Driveで共有している無料かつ新しいCCDAKダンプ:https://drive.google.com/open?id=1fSx5RHQdLcmeYkd9tq7VszKUJ7WqEPZ7
煩わしいConfluentのCCDAK試験問題で、悩んでいますか?悩むことはありません。PassTestが提供した問題と解答はIT領域のエリートたちが研究して、実践して開発されたものです。それは十年過ぎのIT認証経験を持っています。PassTestのConfluentのCCDAKの試験問題と解答は当面の市場で最も徹底的な正確的な最新的な模擬テストです。
| Certification Vendor: | Confluent |
|---|---|
| Exam Name: | Confluent Certified Developer for Apache Kafka Certification Examination |
| Exam Number: | CCDAK |
| Exam Price: | $150 USD |
| Related Certifications: | Confluent Certified Administrator for Apache Kafka (CCAAK) |
| Real Exam Qty: | 60 |
| Available Languages: | English |
| Certificate Validity Period: | 3 years |
| Passing Score: | Approximately 60% |
| Exam Duration: | 90 minutes |
| Exam Format: | Multiple Choice (Multiple Answers), Multiple Choice (Single Answer) |
| Sample Questions: | Confluent CCDAK Sample Questions |
| Exam Way: | Online proctored exam (Pearson VUE) or in-person testing center |
| Pre Condition: | Recommended: 6+ months of hands-on experience with Apache Kafka and Confluent Platform. Familiarity with distributed systems concepts is strongly recommended. |
| Official Syllabus URL: | https://www.confluent.io/certification/ |
長年にわたり、PassTestはずっとIT認定試験を受験する皆さんに最良かつ最も信頼できる参考資料を提供するために取り組んでいます。IT認定試験の出題範囲に対して、PassTestは豊富な経験を持っています。また、PassTestは数え切れない受験生を助け、皆さんの信頼と称賛を得ました。ですから、PassTestのCCDAK問題集の品質を疑わないでください。これは間違いなくあなたがCCDAK認定試験に合格することを保証できる問題集です。PassTestは試験に失敗すれば全額返金を保証します。このような保証があれば、PassTestのCCDAK問題集を購入しようか購入するまいかと躊躇する必要は全くないです。この問題集をミスすればあなたの大きな損失ですよ。
CCDAK試験は、エンタープライズ版Kafkaを提供するConfluent社が作成し、世界中で利用可能です。この認定試験は、メッセージ分配、ストリーム処理、Kafkaエコシステムツールなど、さまざまなKafka関連トピックにおけるKafka開発者のスキル、専門知識、知識を検証するために設計されています。CCDAK試験に合格することは、効率的でスケーラブル、信頼性の高いKafkaベースのアプリケーションを構築するために使用できるKafkaコンセプトの実用的な理解を開発者が持っていることを示す重要な業績です。
質問 # 25
If I supply the setting compression.type=snappy to my producer, what will happen? (select two)
正解:E
解説:
Kafka transfers data with zero copy and no transformation. Any transformation (including compression) is the responsibility of clients.
質問 # 26
Match each configuration parameter with the correct deployment step in installing a Kafka connector.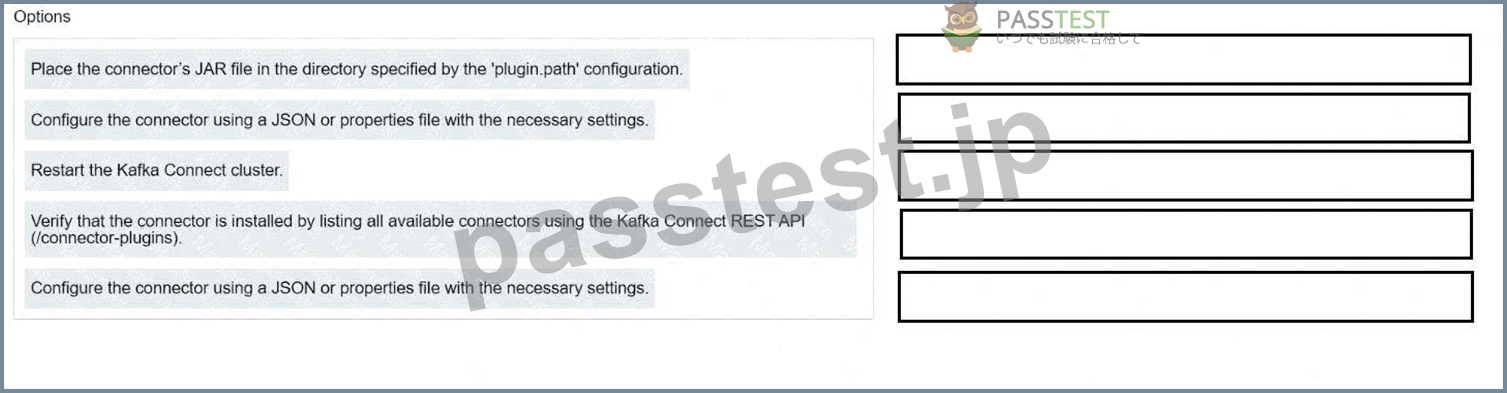
正解:
解説: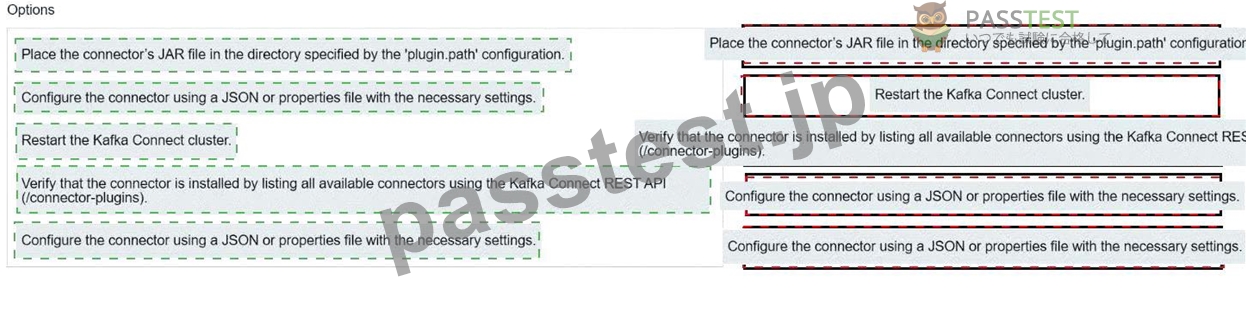
Explanation:
1st: Place the connector's JAR file in the directory specified by plugin.path
2nd: Restart the Kafka Connect cluster
3rd: Verify using REST API (/connector-plugins)
4th: Configure the connector
5th: (Repeat of 4th, duplicate step)
1st # Place the connector's JAR file in the directory specified by the plugin.path configuration.
2nd # Restart the Kafka Connect cluster.
3rd # Verify that the connector is installed by listing all available connectors using the Kafka Connect REST API (/connector-plugins).
4th # Configure the connector using a JSON or properties file with the necessary settings.
5th # Configure the connector using a JSON or properties file with the necessary settings.
Kafka Connect requires that custom connectors be placed in the directory defined by plugin.path. After restarting the cluster, you can use the REST API to confirm availability and then deploy the connector configuration.
From Kafka Connect Documentation:
"After placing the JAR in the plugin.path, you must restart the Connect cluster to pick it up. Use the
/connector-plugins REST endpoint to verify."
The duplication of configuration is an error in the question options and should occur only once.
Reference: Kafka Connect Plugin Installation Guide
質問 # 27
Using the Confluent Schema Registry, where are Avro schema stored?
正解:A
解説:
The Schema Registry stores all the schemas in the _schemas Kafka topic
質問 # 28
A customer has many consumer applications that process messages from a Kafka topic. Each consumer application can only process 50 MB/s. Your customer wants to achieve a target throughput of 1 GB/s. What is the minimum number of partitions will you suggest to the customer for that particular topic?
正解:B
解説:
each consumer can process only 50 MB/s, so we need at least 20 consumers consuming one partition so that 50 * 20 = 1000 MB target is achieved.
質問 # 29
(Which configuration is valid for deploying a JDBC Source Connector to read all rows from the orders table and write them to the dbl-orders topic?)
正解:B
解説:
According to the official Apache Kafka Connect and Confluent JDBC Source Connector documentation, the correct connector class for a JDBC source connector is io.confluent.connect.jdbc.JdbcSourceConnector. This connector is used to read data from relational databases and publish each table as a Kafka topic.
To read all rows from a specific table, the configuration must include table.whitelist (or table.include.list in newer versions) with the table name, and a topic.prefix to determine the Kafka topic name. In this case, using topic.prefix=dbl- with table.whitelist=orders results in records being written to the dbl-orders topic, which matches the requirement.
Options A, B, and C are invalid because they reference a non-existent connector class (DdbcSourceConnector), contain unsupported properties such as topic.whitelist for a source connector, or include malformed/incorrect JDBC parameters. Additionally, blacklisting tables does not ensure that only the orders table is read.
Therefore, option D is the only configuration that is syntactically correct, uses the proper connector class, and aligns with the official Kafka Connect JDBC Source Connector documentation.
質問 # 30
......
CCDAK認定試験: https://www.passtest.jp/Confluent/CCDAK-shiken.html
2026年PassTestの最新CCDAK PDFダンプおよびCCDAK試験エンジンの無料共有:https://drive.google.com/open?id=1fSx5RHQdLcmeYkd9tq7VszKUJ7WqEPZ7