無料でクラウドストレージから最新のShikenPASS Databricks-Certified-Data-Engineer-Professional PDFダンプをダウンロードする:https://drive.google.com/open?id=174niFVSisN8WQH1PIt6EclxwMaI5nnJ9
DatabricksのDatabricks-Certified-Data-Engineer-Professional認定試験は競争が激しい今のIT業界中でいよいよ人気があって、受験者が増え一方で難度が低くなくて結局専門知識と情報技術能力の要求が高い試験なので、普通の人がDatabricks認証試験に合格するのが必要な時間とエネルギーをかからなければなりません。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Debugging and Deploying | 10% | - Deploy using Asset Bundles, CLI, and APIs - Implement CI/CD and DevOps practices - Troubleshoot and debug pipelines |
| Topic 2: Data Governance | 7% | - Manage data assets and metadata - Use Unity Catalog for governance - Enforce data policies and standards |
| Topic 3: Ensuring Data Security and Compliance | 10% | - Implement access control and permissions - Ensure data privacy and compliance - Secure data at rest and in transit |
| Topic 4: Data Ingestion & Acquisition | 7% | - Use Auto Loader and structured streaming - Handle incremental and batch data loads - Ingest data from diverse sources |
| Topic 5: Data Transformation, Cleansing, and Quality | 10% | - Apply data cleansing and validation rules - Implement schema evolution and management - Enforce data quality standards |
| Topic 6: Data Sharing and Federation | 5% | - Use Delta Sharing for secure data sharing - Implement Lakehouse Federation - Manage cross-platform data access |
| Topic 7: Data Modelling | 6% | - Optimize table design and partitioning - Design Medallion Architecture - Implement dimensional and relational models |
| Topic 8: Monitoring and Alerting | 10% | - Monitor pipeline performance and health - Set up alerts and notifications - Track data lineage and metrics |
| Topic 9: Cost & Performance Optimisation | 13% | - Apply cost management best practices - Optimize compute and storage resources - Improve query and pipeline performance |
| Topic 10: Developing Code for Data Processing using Python and SQL | 22% | - Use Databricks-specific libraries and APIs - Implement complex data processing logic - Write efficient and maintainable code |
>> Databricks-Certified-Data-Engineer-Professional復習問題集 <<
最近、Databricks Databricks-Certified-Data-Engineer-Professional試験に合格するのは重要な課題になっています。同時に、Databricks-Certified-Data-Engineer-Professional資格認証を受け入れるのは傾向になります。Databricks-Certified-Data-Engineer-Professional試験に参加したい、我々ShikenPASSのDatabricks-Certified-Data-Engineer-Professional練習問題を参考しましょう。弊社は1年間の無料更新サービスを提供いたします。あなたがご使用になっているとき、何か質問がありましたらご遠慮なく弊社とご連絡ください。
質問 # 133
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below: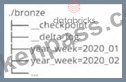
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
正解:B
解説:
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss.
質問 # 134
A data engineer created a daily batch ingestion pipeline using a cluster with the latest DBR version to store banking transaction data, and persisted it in a MANAGED DELTA table called prod.gold.all_banking_transactions_daily. The data engineer is constantly receiving complaints from business users who query this table ad hoc through a SQL Serverless Warehouse about poor query performance. Upon analysis, the data engineer identified that these users frequently use high- cardinality columns as filters. The engineer now seeks to implement a data layout optimization technique that is incremental, easy to maintain, and can evolve over time. Which command should the data engineer implement?
正解:B
解説:
Databricks recommends Liquid Clustering for optimizing data layout in large Delta tables where query filters involve high-cardinality columns. Liquid Clustering automatically manages file organization and supports incremental maintenance without the need to rewrite data when clustering keys evolve. This is a key advantage over static partitioning or Z-ordering, which require costly file rewrites whenever optimization keys change. By combining Liquid Clustering with a periodic OPTIMIZE command, Databricks automatically compacts small files and maintains efficient data skipping performance. As stated in the Delta Lake optimization guide, Liquid Clustering is designed for scalability, minimal maintenance, and adaptability for analytical workloads with evolving query patterns--making B the correct answer.
質問 # 135
A data engineering team uses Databricks Lakehouse Monitoring to track the percent_null metric for a critical column in their Delta table.
The profile metrics table (prod_catalog.prod_schema.customer_data_profile_metrics) stores hourly percent_null values.
The team wants to:
Trigger an alert when the daily average of percent_null exceeds 5% for
three consecutive days.
Ensure that notifications are not spammed during sustained issues.
正解:B
解説:
The key requirement is to detect when the daily average of percent_null is greater than 5% for three consecutive days.
Option A only checks the last 24 hours, not consecutive days. It would trigger too frequently and cause spam.
Option C calculates an average across all records in the last 3 days, but this could be skewed by one high or low day -- it does not ensure consecutive daily violations.
Option D simply counts days where the threshold was exceeded, but it does not guarantee that those days were consecutive. This could incorrectly trigger on non-adjacent violations.
Option B is correct:
It aggregates hourly values into daily averages.
It checks that the last 3 consecutive days all had averages above 5%.
It avoids redundant alerts by using Notification Frequency: Just once.
This matches Databricks Lakehouse Monitoring best practices, where SQL alerts should be designed to aggregate metrics to the correct granularity (daily here) and ensure consecutive threshold violations before triggering.
質問 # 136
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
正解:A
解説:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. These statistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.
質問 # 137
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from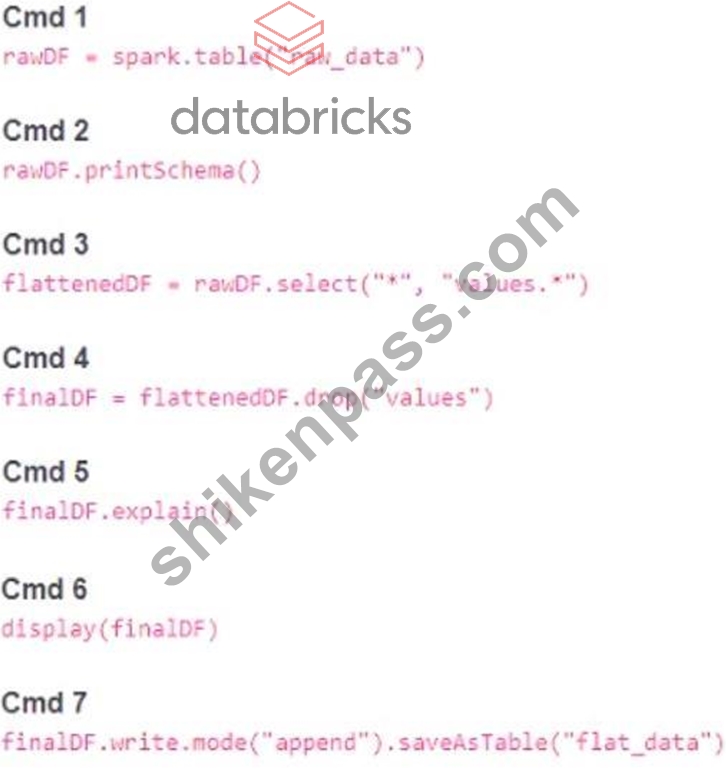
Which command should be removed from the notebook before scheduling it as a job?
正解:C
解説:
When scheduling a Databricks notebook as a job, it's generally recommended to remove or modify commands that involve displaying output, such as using the display() function. Displaying data using display() is an interactive feature designed for exploration and visualization within the notebook interface and may not work well in a production job context.
The finalDF.explain() command, which provides the execution plan of the DataFrame transformations and actions, is often useful for debugging and optimizing queries. While it doesn't Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from display interactive visualizations like display(), it can still be informative for understanding how Spark is executing the operations on your DataFrame.
質問 # 138
......
ShikenPASS弊社が提供する製品は、専門家によって精巧にコンパイルされており、Databricksお客様に便利な方法でDatabricks-Certified-Data-Engineer-Professional学習教材の学習を支援することを目的としたさまざまなバージョンを強化しています。 Databricks-Certified-Data-Engineer-Professional彼らは毎日アップデートをチェックしており、Databricks Certified Data Engineer Professional Exam購入日から無料のアップデートサービスが受けられることを保証できます。Databricks-Certified-Data-Engineer-Professional 販売前または販売後にカスタマーサービスを提供するDatabricks試験問題について質問や疑問がある場合は、試験資料について質問や疑問がある場合は連絡してください。Databricks Certified Data Engineer Professional Exam専門の担当者が解決に役立ちます。 Databricks-Certified-Data-Engineer-Professional学習資料の使用に関する問題。
Databricks-Certified-Data-Engineer-Professional資格復習テキスト: https://www.shikenpass.com/Databricks-Certified-Data-Engineer-Professional-shiken.html
ちなみに、ShikenPASS Databricks-Certified-Data-Engineer-Professionalの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=174niFVSisN8WQH1PIt6EclxwMaI5nnJ9