What's more, part of that RealExamFree DP-600 dumps now are free: https://drive.google.com/open?id=1DwZgNZXmn9CBJkj5xa7aoOLPdPTvrQ3r
RealExamFree Microsoft DP-600 practice exam support team cooperates with users to tie up any issues with the correct equipment. If Implementing Analytics Solutions Using Microsoft Fabric (DP-600) certification exam material changes, RealExamFree also issues updates free of charge for three months following the purchase of our Implementing Analytics Solutions Using Microsoft Fabric (DP-600) exam questions.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Reliable DP-600 Test Preparation <<
According to different kinds of questionnaires based on study condition among different age groups, our DP-600 test prep is totally designed for these study groups to improve their capability and efficiency when preparing for DP-600 exams, thus inspiring them obtain the targeted DP-600 certificate successfully. There are many advantages of our DP-600 question torrent that we are happy to introduce you and you can pass the DP-600 exam for sure.
NEW QUESTION # 115
You need to ensure that Contoso can use version control to meet the data analytics requirements and the general requirements. What should you do?
Answer: D
Explanation:
You need to ensure that Contoso can use version control to meet the data analytics requirements and the general requirements.
Requirement: "All the semantic models and reports for the Research division must use version control that s upports branching." Fabric supports Git integration (Azure Repos or GitHub) for semantic models and reports.
Storing in Data Lake Gen2 or OneDrive does not provide version control with branching.
The correct action is to integrate workspaces with a Git repository.
Modify the settings of the Research division workspaces to use an Azure Repos repository.
NEW QUESTION # 116
You have a Fabric tenant that contains a workspace named Workspace_DEV. Workspace_DEV contains the semantic models shown in the following table.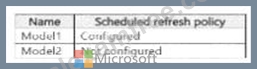
Workspace_DEV contains the dataflows shown in the following table.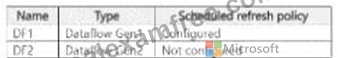
Answer:
Explanation: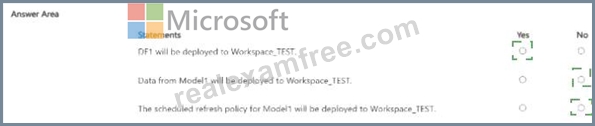
Explanation: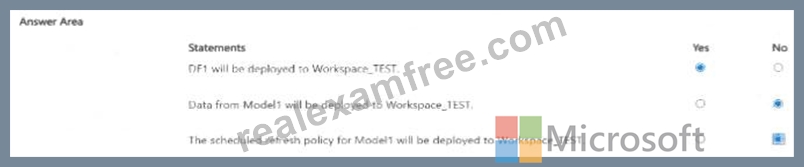
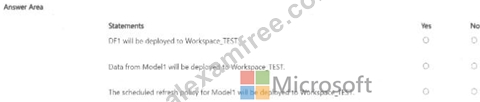
DF1 will be deployed to Workspace_TEST: Yes
Data from Model1 will be deployed to Workspace_TEST: No
The scheduled refresh policy for Model1 will be deployed to Workspace_TEST: No DF1 is a Dataflow Gen1 with a configured scheduled refresh policy, so it will be deployed to Workspace_TEST.
Data from Model1 will not be deployed as Model1 ' s scheduled refresh policy is not configured, indicating it is not set up for deployment.
The scheduled refresh policy for Model1 will not be deployed since it is listed as " Not configured. "
NEW QUESTION # 117
You have a Fabric tenant that contains a lakehouse.
You are using a Fabric notebook to save a large DataFrame by using the following code.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.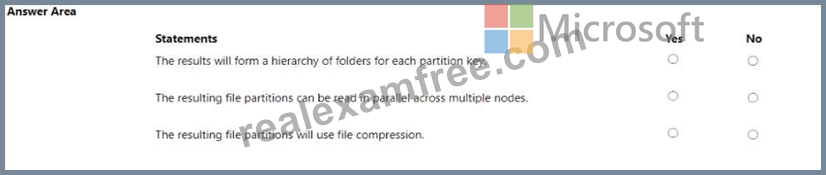
Answer:
Explanation: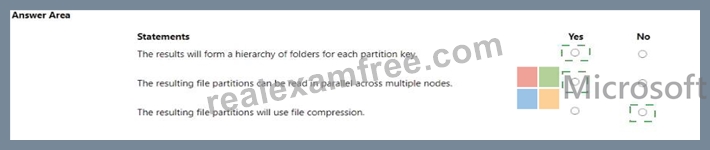
Explanation:
* The results will form a hierarchy of folders for each partition key. - Yes
* The resulting file partitions can be read in parallel across multiple nodes. - Yes
* The resulting file partitions will use file compression. - No
Partitioning data by columns such as year, month, and day, as shown in the DataFrame write operation, organizes the output into a directory hierarchy that reflects the partitioning structure. This organization can improve the performance of read operations, as queries that filter by the partitioned columns can scan only the relevant directories. Moreover, partitioning facilitates parallelism because each partition can be processed independently across different nodes in a distributed system like Spark. However, the code snippet provided does not explicitly specify that file compression should be used, so we cannot assume that the output will be compressed without additional context.
References =
* DataFrame write partitionBy
* Apache Spark optimization with partitioning
NEW QUESTION # 118
You are implementing two dimension tables named Customers and Products in a Fabric warehouse.
You need to use slowly changing dimension (SCO) to manage the versioning of data. The solution must meet the requirements shown in the following table.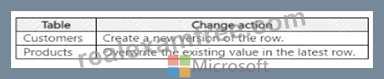
Which type of SCD should you use for each table? To answer, drag the appropriate SCD types to the correct tables. Each SCD type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.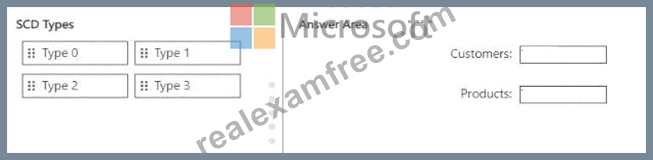
Answer:
Explanation: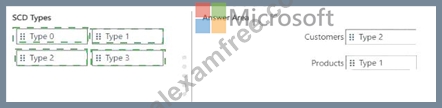
Explanation: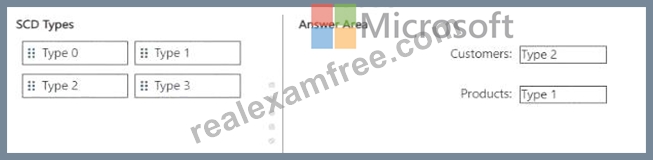
For the Customers table, where the requirement is to create a new version of the row, you would use:
* Type 2 SCD: This type allows for the creation of a new record each time a change occurs, preserving the history of changes over time.
For the Products table, where the requirement is to overwrite the existing value in the latest row, you would use:
* Type 1 SCD: This type updates the record directly, without preserving historical data.
NEW QUESTION # 119
You have a Fabric warehouse named Warehousel that contains a table named Table! Tablel contains customer data.
You need to implement row-level security (RLS) for Tablel. The solution must ensure that users can see only their respective data.
Which two objects should you create? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,B
Explanation:
To implement row-level security (RLS) in a Fabric Warehouse (like in Azure Synapse or SQL Server):
You must define a predicate function (usually an inline table-valued function) that filters rows for each user
# Function.
Then you bind that function to the table using a Security Policy # Security Policy.
A Database Role is used for group-based access control but not specifically for implementing RLS.
Stored procedures and constraints are not used for RLS.
Correct answers: A and D
Reference: Row-Level Security (RLS) in Synapse/Fabric SQL
NEW QUESTION # 120
......
If you find any quality problems of our DP-600 or you do not pass the exam, we will unconditionally full refund. RealExamFree is professional site that providing Microsoft DP-600 Questions and answers, it covers almost the DP-600 full knowledge points.
Valid DP-600 Practice Materials: https://www.realexamfree.com/DP-600-real-exam-dumps.html
What's more, part of that RealExamFree DP-600 dumps now are free: https://drive.google.com/open?id=1DwZgNZXmn9CBJkj5xa7aoOLPdPTvrQ3r