Fast Download Databricks-Certified-Professional-Data-Engineer Exam Discount Voucher & Correct Databricks Certification Training - Marvelous Databricks Databricks Certified Professional Data Engineer Exam

It is well known that obtaining such a Databricks-Certified-Professional-Data-Engineer certificate is very difficult for most people, especially for those who always think that their time is not enough to learn efficiently. With our Databricks-Certified-Professional-Data-Engineer test prep, you don't have to worry about the complexity and tediousness of the operation. As long as you enter the learning interface of our soft test engine of Databricks-Certified-Professional-Data-Engineer Quiz guide and start practicing on our Windows software, you will find that there are many small buttons that are designed to better assist you in your learning.
| Section | Weight | Objectives |
|---|
| Delta Lake | 20-25% | - Delta Lake fundamentals
- 1. Time travel and data versioning
- 2. Optimize and Z-order
- 3. ACID transactions
- Delta Lake operations
- 1. Schema evolution and enforcement
- 2. Delta Live Tables
- 3. Merge, update, delete operations
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Monitoring and alerting
- 2. Task dependencies and orchestration
- 3. Jobs and job scheduling
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Bronze, silver, gold data layers
- 2. Data governance fundamentals
- 3. Differences between data lake, data warehouse, and lakehouse
|
| Data Processing with Spark | 25-30% | - Python and SQL for data engineering
- 1. Built-in and user-defined functions
- 2. Performance optimization techniques
- 3. Spark APIs in Python
- Spark DataFrames and Spark SQL
- 1. Window functions
- 2. Spark SQL queries and functions
- 3. DataFrame operations and transformations
|
| Data Ingestion | 15-20% | - Streaming ingestion
- 1. Kafka integration
- 2. Structured streaming fundamentals
- Batch ingestion methods
- 1. Spark APIs for ingestion
- 2. Integration with external systems
- 3. DBR autoloader
|
>> Databricks-Certified-Professional-Data-Engineer Exam Discount Voucher <<
Valid Databricks Databricks-Certified-Professional-Data-Engineer Exam Answers & Vce Databricks-Certified-Professional-Data-Engineer Exam
We present our Databricks Databricks-Certified-Professional-Data-Engineer real questions in PDF format. It is beneficial for those applicants who are busy in daily routines. The Databricks-Certified-Professional-Data-Engineer PDF QUESTIONS contains all the exam questions which will appear in the real test. You can easily get ready for the examination in a short time by just memorizing Databricks-Certified-Professional-Data-Engineer Actual Questions.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q95-Q100):
NEW QUESTION # 95
A company wants to implement Lakehouse Federation across multiple data sources but is concerned about data consistency and ensuring that all teams access the same authoritative version of their data.
Which statement is applicable for Lakehouse Federations to maintain data consistency?
- A. A separate data synchronization service must be deployed.
- B. Federation creates local copies that must be manually refreshed.
- C. Federation provides read-only access that reflects the current state of source systems.
- D. Federation implements change data capture (CDC) from all sources.
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Lakehouse Federation allows Databricks to query and manage external data sources through a single governance layer, without moving or copying data. The documentation specifies that "Federated queries provide read-only access to data, reflecting the current state of the underlying source system." This ensures consistency across teams since all users access the same source of truth directly from the external system through Unity Catalog. Federation does not perform CDC replication or local caching; it queries live data on demand. Hence, option A accurately represents how Lakehouse Federation maintains consistency across federated sources.
NEW QUESTION # 96
A Delta Lake table representing metadata about content posts from users has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE This table is partitioned by the date column. A query is run with the following filter:
longitude < 20 and longitude > -20
Which statement describes how data will be filtered?
- A. The Delta Engine will use row-level statistics in the transaction log to identify the flies that meet the filter criteria.
- B. Statistics in the Delta Log will be used to identify partitions that might Include files in the filtered range.
- C. Statistics in the Delta Log will be used to identify data files that might include records in the filtered range.
- D. The Delta Engine will scan the parquet file footers to identify each row that meets the filter criteria.
- E. No file skipping will occur because the optimizer does not know the relationship between the partition column and the longitude.
Answer: C
Explanation:
This is the correct answer because it describes how data will be filtered when a query is run with the following filter: longitude < 20 and longitude > -20. The query is run on a Delta Lake table that has the following schema: user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE. This table is partitioned by the date column. When a query is run on a partitioned Delta Lake table, Delta Lake uses statistics in the Delta Log to identify data files that might include records in the filtered range. The statistics include information such as min and max values for each column in each data file. By using these statistics, Delta Lake can skip reading data files that do not match the filter condition, which can improve query performance and reduce I/O costs. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Data skipping" section.
NEW QUESTION # 97
A data engineering team has created a series of tables using Parquet data stored in an external sys-tem. The
team is noticing that after appending new rows to the data in the external system, their queries within
Databricks are not returning the new rows. They identify the caching of the previous data as the cause of this
issue.
Which of the following approaches will ensure that the data returned by queries is always up-to-date?
- A. The tables should be altered to include metadata to not cache
- B. The tables should be stored in a cloud-based external system
- C. The tables should be converted to the Delta format
- D. The tables should be updated before the next query is run
- E. The tables should be refreshed in the writing cluster before the next query is run
Answer: C
NEW QUESTION # 98
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in thegeo_lookuptable.
Before executing the code, runningSHOWTABLESon the current database indicates the database contains only two tables:geo_lookupandsales.
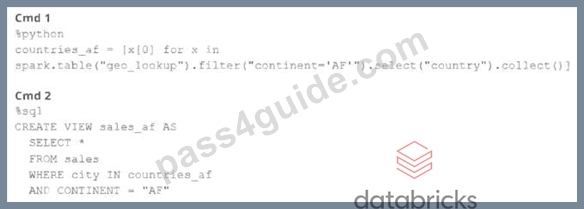
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
- A. Both commands will fail. No new variables, tables, or views will be created.
- B. Cmd 1 will succeed. Cmd 2 will search all accessible databases for a table or view named countries af: if this entity exists, Cmd 2 will succeed.
- C. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable representing a PySpark DataFrame.
- D. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable containing a list of strings.
- E. Both commands will succeed. Executing show tables will show that countries at and sales at have been registered as views.
Answer: D
Explanation:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view. Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter. Verified References: [Databricks Certified Data Engineer Professional], under
"Language Interoperability" section; Databricks Documentation, under "Mix languages" section.
NEW QUESTION # 99
Which statement describes Delta Lake optimized writes?
- A. A shuffle occurs prior to writing to try to group data together resulting in fewer files instead of each executor writing multiple files based on directory partitions.
- B. Optimized writes logical partitions instead of directory partitions partition boundaries are only represented in metadata fewer small files are written.
- C. Before a job cluster terminates, OPTIMIZE is executed on all tables modified during the most recent job.
- D. An asynchronous job runs after the write completes to detect if files could be further compacted; yes, an OPTIMIZE job is executed toward a default of 1 GB.
Answer: A
Explanation:
Delta Lake optimized writes involve a shuffle operation before writing out data to the Delta table. The shuffle operation groups data by partition keys, which can lead to a reduction in the number of output files and potentially larger files, instead of multiple smaller files. This approach can significantly reduce the total number of files in the table, improve read performance by reducing the metadata overhead, and optimize the table storage layout, especially for workloads with many small files.
Reference:
Databricks documentation on Delta Lake performance tuning: https://docs.databricks.com/delta/optimizations/auto-optimize.html
NEW QUESTION # 100
......
Even if you have received a lot of services, you will still be surprised by the service of our Databricks-Certified-Professional-Data-Engineer simulating exam. Our company takes great care in every aspect from the selection of staff, training, and system setup. No matter what problems of the Databricks-Certified-Professional-Data-Engineer Practice Questions you encounter, our staff can solve them for you right away and give you the most professional guide. And our service can help you 24/7 on the the Databricks-Certified-Professional-Data-Engineer exam materials.
Valid Databricks-Certified-Professional-Data-Engineer Exam Answers: https://www.pass4guide.com/Databricks-Certified-Professional-Data-Engineer-exam-guide-torrent.html
- Databricks Databricks-Certified-Professional-Data-Engineer Free Updates 🥟 Download ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ for free by simply searching on ⏩ www.dumpsmaterials.com ⏪ 🍽Databricks-Certified-Professional-Data-Engineer Detailed Study Plan
- Databricks Databricks-Certified-Professional-Data-Engineer Free Updates ⬆ Search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ and download exam materials for free through “ www.pdfvce.com ” 🚵Reliable Databricks-Certified-Professional-Data-Engineer Test Review
- Pass your Databricks-Certified-Professional-Data-Engineer exam in 2026 Smoothly! 🎪 Search for “ Databricks-Certified-Professional-Data-Engineer ” and download it for free on ➽ www.examdiscuss.com 🢪 website 👲Databricks-Certified-Professional-Data-Engineer Formal Test
- Databricks Databricks-Certified-Professional-Data-Engineer Free Updates 🏘 Search for 《 Databricks-Certified-Professional-Data-Engineer 》 on ➡ www.pdfvce.com ️⬅️ immediately to obtain a free download 🐾Databricks-Certified-Professional-Data-Engineer Advanced Testing Engine
- Pass Guaranteed 2026 Databricks Databricks-Certified-Professional-Data-Engineer –Professional Exam Discount Voucher ❗ Search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ and download it for free immediately on ✔ www.torrentvce.com ️✔️ 🚊Frenquent Databricks-Certified-Professional-Data-Engineer Update
- Reliable Databricks-Certified-Professional-Data-Engineer Test Review ☯ Databricks-Certified-Professional-Data-Engineer Advanced Testing Engine 🔸 Reliable Databricks-Certified-Professional-Data-Engineer Test Camp 🦨 ✔ www.pdfvce.com ️✔️ is best website to obtain ▛ Databricks-Certified-Professional-Data-Engineer ▟ for free download 🔟Reliable Databricks-Certified-Professional-Data-Engineer Test Review
- Databricks-Certified-Professional-Data-Engineer Test Result 🧶 Frenquent Databricks-Certified-Professional-Data-Engineer Update 😷 Practice Databricks-Certified-Professional-Data-Engineer Test Engine 🥩 ⇛ www.vce4dumps.com ⇚ is best website to obtain ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ for free download 🍅Databricks-Certified-Professional-Data-Engineer Advanced Testing Engine
- Databricks-Certified-Professional-Data-Engineer Reliable Test Tutorial 🔚 Databricks-Certified-Professional-Data-Engineer Test Result 🤕 Frenquent Databricks-Certified-Professional-Data-Engineer Update 🐟 Download ➠ Databricks-Certified-Professional-Data-Engineer 🠰 for free by simply entering ( www.pdfvce.com ) website 🖍Frenquent Databricks-Certified-Professional-Data-Engineer Update
- Databricks-Certified-Professional-Data-Engineer Trustworthy Practice 🐸 Databricks-Certified-Professional-Data-Engineer Reliable Test Tutorial ☂ Reliable Databricks-Certified-Professional-Data-Engineer Test Review ⚛ Search for [ Databricks-Certified-Professional-Data-Engineer ] and download exam materials for free through ( www.prep4sures.top ) 🍥Databricks-Certified-Professional-Data-Engineer Test Result
- Pass your Databricks-Certified-Professional-Data-Engineer exam in 2026 Smoothly! 🕠 Immediately open ✔ www.pdfvce.com ️✔️ and search for ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ to obtain a free download ⛷Reliable Databricks-Certified-Professional-Data-Engineer Braindumps
- Pass Guaranteed 2026 Databricks Databricks-Certified-Professional-Data-Engineer –Professional Exam Discount Voucher 🈵 Search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ on 《 www.prep4sures.top 》 immediately to obtain a free download 🏜New Databricks-Certified-Professional-Data-Engineer Dumps Ppt
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, mayagriffiths253.blogspot.com, www.impactio.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, learn.csisafety.com.au, www.stes.tyc.edu.tw, Disposable vapes