Außerdem sind jetzt einige Teile dieser PrüfungFrage Data-Engineer-Associate Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1Ip0P5XEjw2Y436hsA07n6bgWfiGp6lEm
Wir PrüfungFrage haben viel Zeit und Mühe für die Amazon Data-Engineer-Associate Prüfungssoftware eingesetzt, die für Sie entwickelt. Das Ziel ist nur, dass Sie wenig Zeit und Mühe aufwenden, um Amazon Data-Engineer-Associate Prüfung zu bestehen. Die „100% Geld-zurück- Garantie “ ist kein leeres Geschwätz. Trotz unsere Verlässlichkeit auf unsere Produkte geben wir Ihnen die ganzen Gebühren der Amazon Data-Engineer-Associate Prüfungssoftware rechtzeitig zurück, falls Sie keine befriedigte Hilfe davon finden. Allerdings glauben wir, dass die Amazon Data-Engineer-Associate Prüfungssoftware will Ihrer Hoffnung nicht enttäuschen. Wir wünschen Ihnen viel Erfolg bei der Prüfung!
| Section | Weight | Objectives |
|---|---|---|
| Data Security and Governance | 18% | - Apply governance and compliance best practices - Implement data security controls |
| Data Operations and Support | 22% | - Monitor and maintain data pipelines - Troubleshoot data workflow issues |
| Data Store Management | 26% | - Optimize storage performance and cost - Select appropriate data storage solutions |
| Data Ingestion and Transformation | 34% | - Ingest and transform data using AWS services - Build and manage data pipelines |
>> Amazon Data-Engineer-Associate Schulungsangebot <<
Zurzeit ist Amazon Data-Engineer-Associate Zertifizierungsprüfung eine sehr populäre Prüfung. Wollen die Data-Engineer-Associate Zeritifizierungsprüfung ablegen? Tatsächlich ist diese Prüfung sehr schwierig. Aber es bedeutet nicht, dass Sie diese Prüfung mit guter Note bestehen können. Wollen Sie die Methode, die Data-Engineer-Associate Prüfung sehr leicht zu bestehen, kennenzulernen? Das ist Amazon Data-Engineer-Associate dumps von PrüfungFrage.
10. Frage
Two developers are working on separate application releases. The developers have created feature branches named Branch A and Branch B by using a GitHub repository's master branch as the source.
The developer for Branch A deployed code to the production system. The code for Branch B will merge into a master branch in the following week's scheduled application release.
Which command should the developer for Branch B run before the developer raises a pull request to the master branch?
Antwort: B
Begründung:
To ensure that Branch B is up to date with the latest changes in the master branch before submitting a pull request, the correct approach is to perform a git rebase. This command rewrites the commit history so that Branch B will be based on the latest changes in the master branch.
git rebase master:
This command moves the commits of Branch B to be based on top of the latest state of the master branch. It allows the developer to resolve any conflicts and create a clean history.
Reference: Git Rebase Documentation
Alternatives Considered:
A (git diff): This will only show differences between Branch B and master but won't resolve conflicts or bring Branch B up to date.
B (git pull master): Pulling the master branch directly does not offer the same clean history management as rebase.
D (git fetch -b): This is an incorrect command.
References:
Git Rebase Best Practices
11. Frage
A data engineer needs to join data from multiple sources to perform a one-time analysis job. The data is stored in Amazon DynamoDB, Amazon RDS, Amazon Redshift, and Amazon S3.
Which solution will meet this requirement MOST cost-effectively?
Antwort: B
Begründung:
Amazon Athena Federated Query is a feature that allows you to query data from multiple sources using standard SQL. You can use Athena Federated Query to join data from Amazon DynamoDB, Amazon RDS, Amazon Redshift, and Amazon S3, as well as other data sources such as MongoDB, Apache HBase, and Apache Kafka1. Athena Federated Query is a serverless and interactive service, meaning you do not need to provision or manage any infrastructure, and you only pay for the amount of data scanned by your queries. Athena Federated Query is the most cost-effective solution for performing a one-time analysis job on data from multiple sources, as it eliminates the need to copy or move data, and allows you to query data directly from the source.
The other options are not as cost-effective as Athena Federated Query, as they involve additional steps or costs. Option A requires you to provision and pay for an Amazon EMR cluster, which can be expensive and time-consuming for a one-time job. Option B requires you to copy or move data from DynamoDB, RDS, and Redshift to S3, which can incur additional costs for data transfer and storage, and also introduce latency and complexity. Option D requires you to have an existing Redshift cluster, which can be costly and may not be necessary for a one-time job. Option D also does not support querying data from RDS directly, so you would need to use Redshift Federated Query to access RDS data, which adds another layer of complexity2. Reference:
Amazon Athena Federated Query
Redshift Spectrum vs Federated Query
12. Frage
An application uses an AWS Lambda function that is configured with managed runtimes. The Lambda function successfully writes logs to the default Amazon CloudWatch Logs log group. A data engineer wants to modify the logging behavior to show only ERROR level logs for application logs and WARN level logs for system logs.
Which solution will meet these requirements?
Antwort: B
Begründung:
Option C is correct because AWS Lambda's advanced logging controls support separate application log level and system log level filtering, but AWS documentation states that for Lambda to filter application logs according to their log level, the function must use JSON formatted logs. AWS also documents that in the advanced logging configuration you can choose a log level such as ERROR for application logs and WARN for system logs. Therefore, configuring the function to use JSON log format is the necessary step that enables the required log-level filtering behavior.
Option A is irrelevant because the function already writes logs successfully. Option B alone is insufficient because changing code-level logging does not configure Lambda's separate system log filtering behavior, and Lambda's application log filtering relies on structured JSON logs. Option D changes the log destination but does not implement the required filtering levels. The official Lambda documentation makes clear that JSON log format is the enabling configuration for this feature, so that is the correct answer.
13. Frage
A company is building a new application that ingests CSV files into Amazon Redshift. The company has developed the frontend for the application.
The files are stored in an Amazon S3 bucket. Files are no larger than 5 MB.
A data engineer is developing the extract, transform, and load (ETL) pipeline for the CSV files. The data engineer configured a Redshift cluster and an AWS Lambda function that copies the data out of the files into the Redshift cluster.
Which additional steps should the data engineer perform to meet these requirements?
Antwort: B
Begründung:
Option A is the most direct and operationally efficient way to trigger the existing Lambda-based load into Amazon Redshift whenever a new CSV file is uploaded to Amazon S3. The key requirement is event-driven automation on "new object created" events, and the study material explicitly describes using Amazon EventBridge to react to S3 uploads by creating a rule on the default event bus and routing matching events to a target application.
Compared with queue-based designs (Options B and D), Option A reduces components: there is no need to manage an SQS queue, batching/visibility timeout behavior, or retry semantics at the consumer layer. This is especially appropriate because the files are small (# 5 MB) and the Lambda function is already implemented to perform the copy/load step. Using DMS (Option C) is not designed for "S3 object arrival # Lambda # Redshift" event triggering; it introduces unnecessary services and operational work for a simple file-ingestion trigger.
Therefore, integrating S3 event notifications with EventBridge and targeting the Lambda function best meets the requirement with the least added complexity.
14. Frage
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?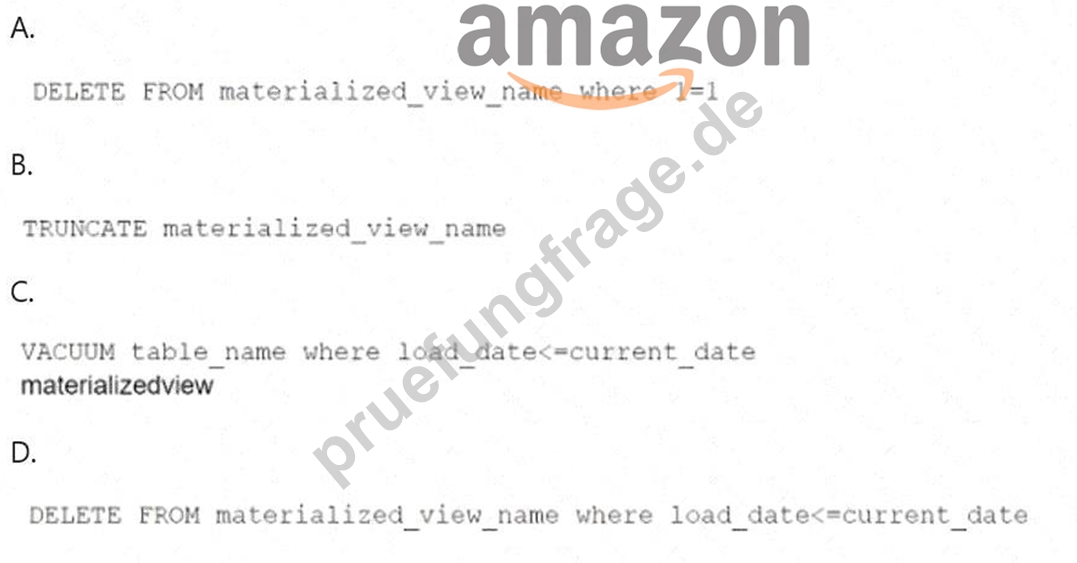
Antwort: C
Begründung:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use a DELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as 1=1. This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
Option A: DELETE FROM materialized_view_name WHERE 1=1;This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
References:
Amazon Redshift Materialized Views Documentation
Deleting Data from Redshift
15. Frage
......
Mit den Schulungsunterlagen zur Amazon Data-Engineer-Associate Zertifizierungsprüfung von PrüfungFrage würden Sie eine glänzende Zukunft haben und Erfolg erzielen. Sie werden Sie nicht nur zum Erfolg führen, sondern auch Ihre Fähigkeiten in der IT-Branche effizient entfalten. Sie umfassen zahlreiche Wissensgebiete und können Ihre Kenntnisse verbessern. Wenn Sie noch warten oder zögern, denn Sie wissen nicht, wie man die Amazon Data-Engineer-Associate Zertifizierungsprüfung bestehen kann, keine Sorge. Die Schulungsunterlagen zur Amazon Data-Engineer-Associate Zertifizierungsprüfung von PrüfungFrage wird alle Ihren Probleme lösen.
Data-Engineer-Associate Prüfungen: https://www.pruefungfrage.de/Data-Engineer-Associate-dumps-deutsch.html
Übrigens, Sie können die vollständige Version der PrüfungFrage Data-Engineer-Associate Prüfungsfragen aus dem Cloud-Speicher herunterladen: https://drive.google.com/open?id=1Ip0P5XEjw2Y436hsA07n6bgWfiGp6lEm