참고: Itcertkr에서 Google Drive로 공유하는 무료, 최신 DP-700 시험 문제집이 있습니다: https://drive.google.com/open?id=19NlLG-ulF9xfG9iZCFA4IAsUrYSa7zWb
Itcertkr에는 베터랑의전문가들로 이루어진 연구팀이 잇습니다, 그들은 it지식과 풍부한 경험으로 여러 가지 여러분이Microsoft인증DP-700시험을 패스할 수 있을 자료 등을 만들었습니다, Itcertkr 에서는 일년무료 업뎃을 제공하며, Itcertkr 의 덤프들은 모두 높은 정확도를 자랑합니다. Itcertkr 선택함으로 여러분이Microsoft인증DP-700시험에 대한 부담은 사라질 것입니다.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
>> Microsoft DP-700최신 인증시험 기출자료 <<
IT인증시험이 다가오는데 어느 부분부터 공부해야 할지 망설이고 있다구요? 가장 간편하고 시간을 절약하며 한방에 자격증을 취득할수 있는 최고의 방법을 추천해드립니다. 바로 우리Itcertkr IT인증덤프제공사이트입니다. Itcertkr는 고품질 고적중율을 취지로 하여 여러분들인 한방에 시험에서 패스하도록 최선을 다하고 있습니다. Microsoft인증DP-700시험준비중이신 분들은Itcertkr 에서 출시한Microsoft인증DP-700 덤프를 선택하세요.
질문 # 43
You need to recommend a solution to resolve the MAR1 connectivity issues. The solution must minimize development effort. What should you recommend?
정답:B
설명:
Topic 2, Litware, IncCase Study
This is a case study. Case studies are not timed separately. You can use as much exam time as you would like to complete each case. However, there may be additional case studies and sections on this exam. You must manage your time to ensure that you are able to complete all questions included on this exam in the time provided.
To answer the questions included in a case study, you will need to reference information that is provided in the case study. Case studies might contain exhibits and other resources that provide more information about the scenario that is described in the case study. Each question is independent of the other questions in this case study.
At the end of this case study, a review screen will appear. This screen allows you to review your answers and to make changes before you move to the next section of the exam. After you begin a new section, you cannot return to this section.
To start the case study
To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment, and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
Overview
Litware, Inc. is a publishing company that has an online bookstore and several retail bookstores worldwide.
Litware also manages an online advertising business for the authors it represents.
Existing Environment. Fabric Environment
Litware has a Fabric workspace named Workspace1. High concurrency is enabled for Workspace1.
The company has a data engineering team that uses Python for data processing.
Existing Environment. Data Processing
The retail bookstores send sales data at the end of each business day, while the online bookstore constantly provides logs and sales data to a central enterprise resource planning (ERP) system.
Litware implements a medallion architecture by using the following three layers: bronze, silver, and gold. The sales data is ingested from the ERP system as Parquet files that land in the Files folder in a lakehouse.
Notebooks are used to transform the files in a Delta table for the bronze and silver layers. The gold layer is in a warehouse that has V-Order disabled.
Litware has image files of book covers in Azure Blob Storage. The files are loaded into the Files folder.
Existing Environment. Sales Data
Month-end sales data is processed on the first calendar day of each month. Data that is older than one month never changes.
In the source system, the sales data refreshes every six hours starting at midnight each day.
The sales data is captured in a Dataflow Gen1 dataflow. When the dataflow runs, new and historical data is captured. The dataflow captures the following fields of the source:
Sales Date
Author
Price
Units
SKU
A table named AuthorSales stores the sales data that relates to each author. The table contains a column named AuthorEmail. Authors authenticate to a guest Fabric tenant by using their email address.
Existing Environment. Security Groups
Litware has the following security groups:
Sales
Fabric Admins
Streaming Admins
Existing Environment. Performance Issues
Business users perform ad-hoc queries against the warehouse. The business users indicate that reports against the warehouse sometimes run for two hours and fail to load as expected. Upon further investigation, the data engineering team receives the following error message when the reports fail to load: "The SQL query failed while running." The data engineering team wants to debug the issue and find queries that cause more than one failure.
When the authors have new book releases, there is often an increase in sales activity. This increase slows the data ingestion process.
The company's sales team reports that during the last month, the sales data has NOT been up-to-date when they arrive at work in the morning.
Requirements. Planned Changes
Litware recently signed a contract to receive book reviews. The provider of the reviews exposes the data in Amazon Simple Storage Service (Amazon S3) buckets.
Litware plans to manage Search Engine Optimization (SEO) for the authors. The SEO data will be streamed from a REST API.
Requirements. Version Control
Litware plans to implement a version control solution in Fabric that will use GitHub integration and follow the principle of least privilege.
Requirements. Governance Requirements
To control data platform costs, the data platform must use only Fabric services and items. Additional Azure resources must NOT be provisioned.
Requirements. Data Requirements
Litware identifies the following data requirements:
Process the SEO data in near-real-time (NRT).
Make the book reviews available in the lakehouse without making a copy of the data.
When a new book cover image arrives in the Files folder, process the image as soon as possible.
질문 # 44
You need to implement the solution for the book reviews.
Which should you do?
정답:D
설명:
The requirement specifies that Litware plans to make the book reviews available in the lakehouse without making a copy of the data. In this case, creating a shortcut in Fabric is the most appropriate solution. A shortcut is a reference to the external data, and it allows Litware to access the book reviews stored in Amazon S3 without duplicating the data into the lakehouse.
질문 # 45
You have a Fabric warehouse named DW1 that contains a Type 2 slowly changing dimension (SCD) dimension table named DimCustomer. DimCustomer contains 100 columns and 20 million rows. The columns are of various data types, including int, varchar, date, and varbinary.
You need to identify incoming changes to the table and update the records when there is a change. The solution must minimize resource consumption.
What should you use to identify changes to attributes?
정답:B
질문 # 46
You have a Fabric workspace named Workspace1 that contains a lakehouse named Lakehouse1.
You need to automate a PySpark-based data transformation process. The solution must meet the following requirements:
* Ensure that users can edit and test the PySpark code interactively.
* Ensure that the code can be operationalized for automated execution.
Which three actions should you perform in sequence?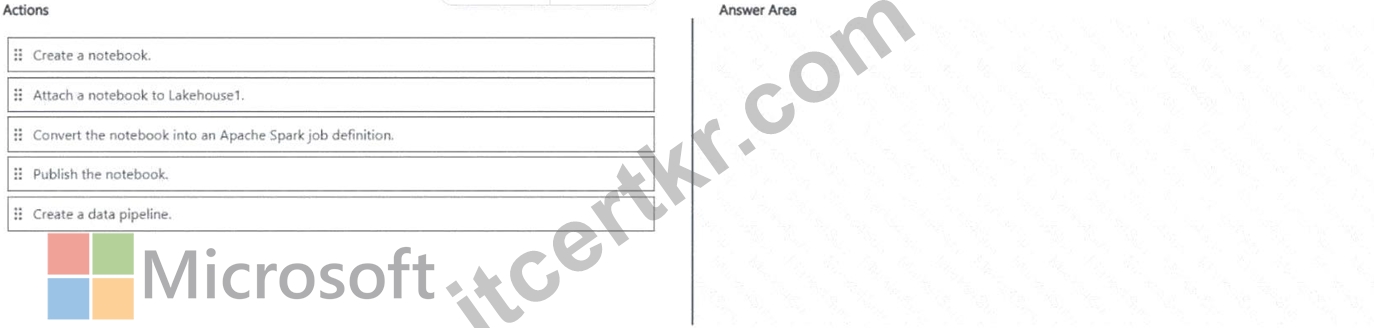
정답:
설명: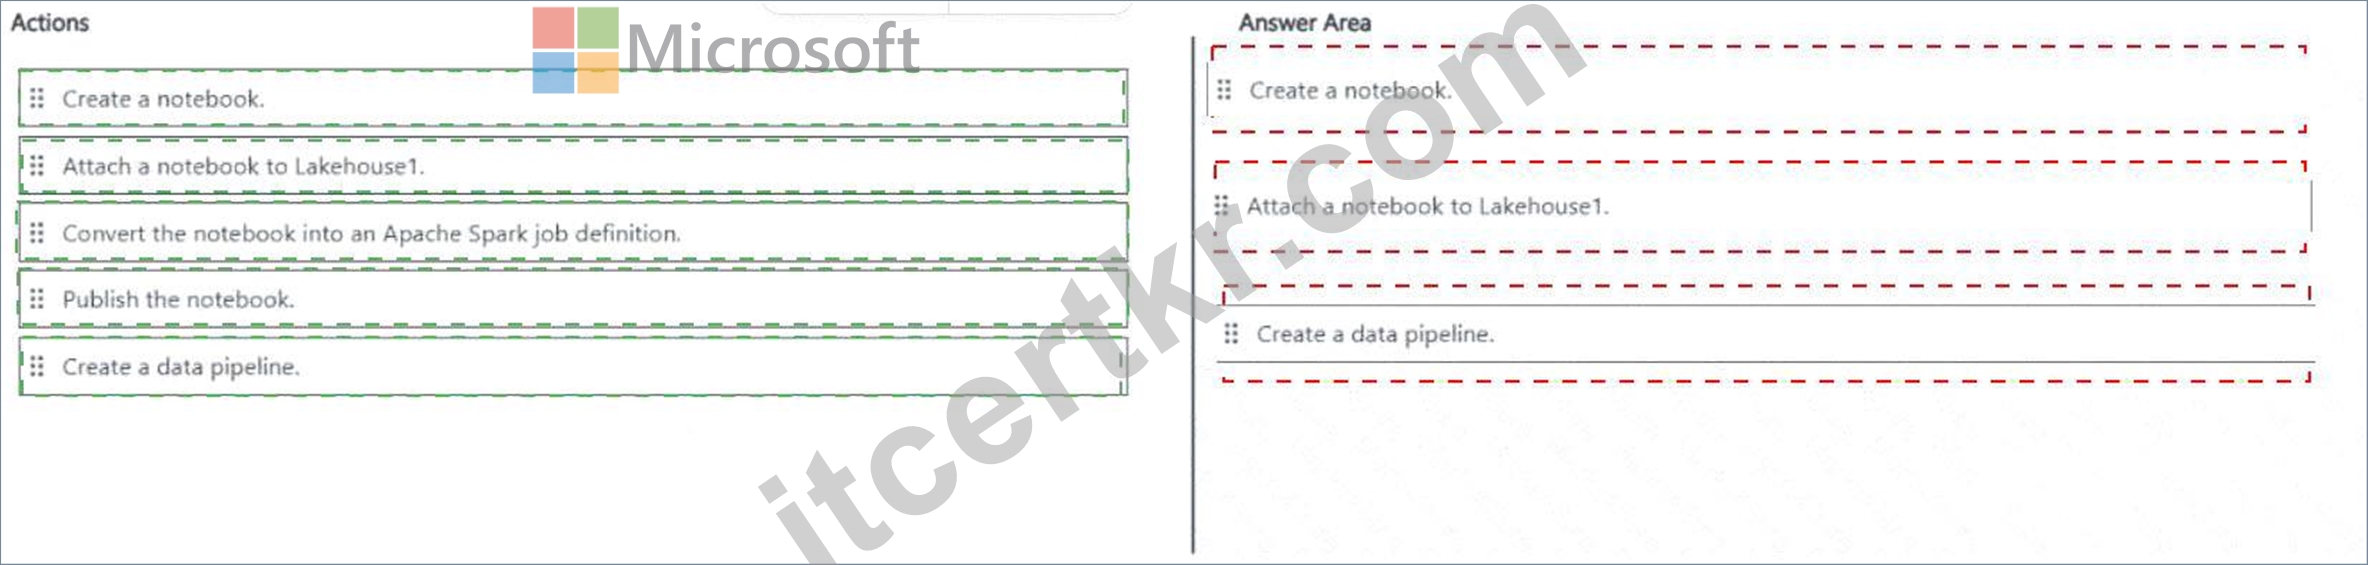
Explanation:
The correct sequence is Create a notebook # Attach the notebook to Lakehouse1 # Create a data pipeline
.
First, create a Fabric notebook because notebooks provide the interactive development environment required for authoring, executing, debugging, and testing PySpark code. Microsoft describes Fabric notebooks as a primary code item for developing Apache Spark workloads and specifically supports their use for data ingestion, preparation, and transformation.
Second, attach the notebook to Lakehouse1 . Attaching a lakehouse establishes the notebook ' s lakehouse context, allowing PySpark code to access the lakehouse ' s Files and Tables through Spark and OneLake. This enables developers to interactively validate the transformation against the required Fabric data.
Third, create a data pipeline and use a Notebook activity to operationalize the notebook. Fabric Data Factory explicitly supports running Fabric notebooks as pipeline activities for automated data transformation workflows. Pipelines can subsequently be run manually, scheduled, or incorporated into larger orchestration processes.
Converting the notebook to an Apache Spark job definition is unnecessary; Spark job definitions are separate executable Fabric items. Publishing the notebook is also not required for pipeline execution.
Study Guide reference: Ingest and transform data # Transform data with Apache Spark # Fabric notebooks # Orchestrate processes and schedules with Data Factory pipelines.
질문 # 47
HOTSPOT
You are processing streaming data from an external data provider.
You have the following code segment.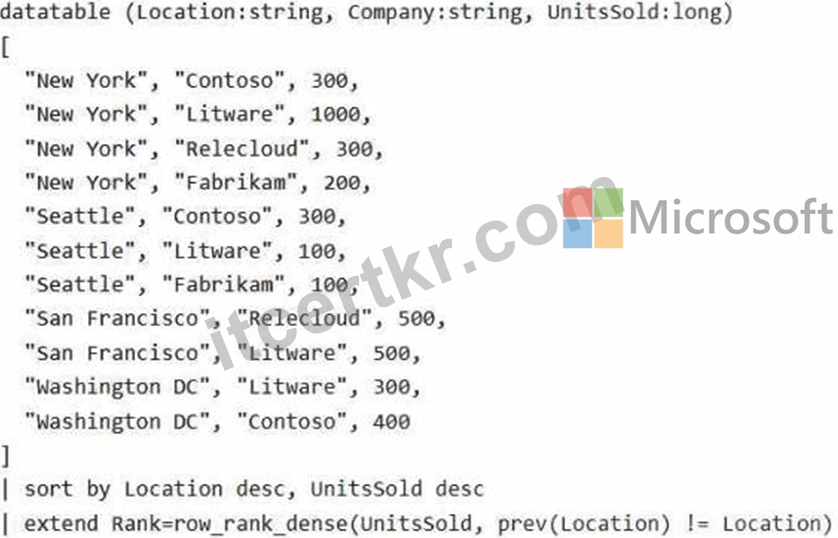
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.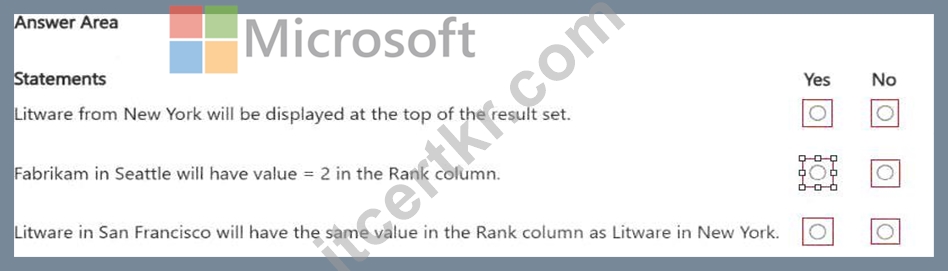
정답:
설명: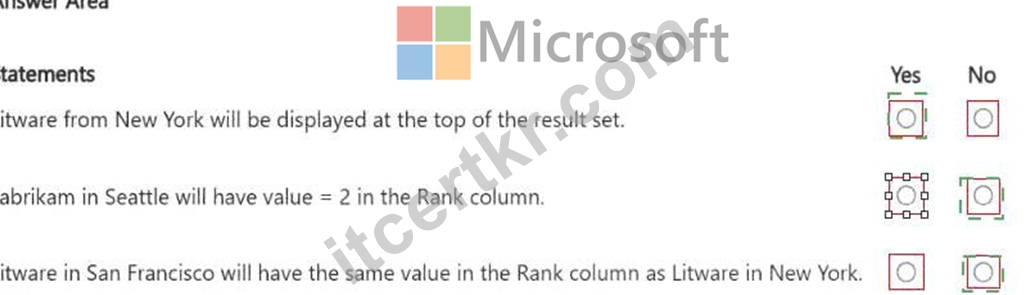
Explanation: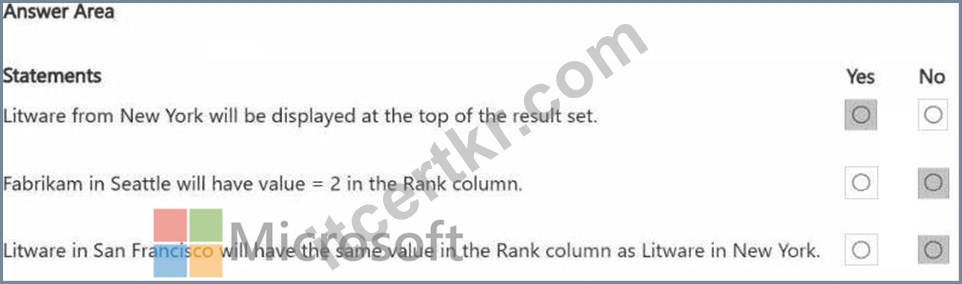
Litware from New York will be displayed at the top of the result set - Yes The data is sorted first by Location in descending order and then by UnitsSold in descending order. Since
"New York" is alphabetically the last Location, it will appear first in the result set. Within "New York", Litware has the highest UnitsSold (1000), so it will be displayed at the top.
Fabrikam in Seattle will have value = 2 in the Rank column - No
The row_rank_dense function assigns dense ranks based on UnitsSold within each location. In "Seattle":
Contoso has UnitsSold = 300 # Rank 1
Litware has UnitsSold = 100 # Rank 2
Fabrikam also has UnitsSold = 100, so it shares the same rank (2) as Litware.
Litware in San Francisco will have the same value in the Rank column as Litware in New York - No The rank is calculated separately for each location. In "San Francisco":
Both Relecloud and Litware have UnitsSold = 500, so they share the same rank (1).
In "New York", Litware has the highest UnitsSold = 1000 # Rank 1.
Since ranks are calculated independently for each location, Litware in San Francisco does not share the same rank as Litware in New York.
질문 # 48
......
DP-700는Microsoft의 인증시험입니다.DP-700인증시험을 패스하면Microsoft인증과 한 발작 더 내디딘 것입니다. 때문에DP-700시험의 인기는 날마다 더해갑니다.DP-700시험에 응시하는 분들도 날마다 더 많아지고 있습니다. 하지만DP-700시험의 통과 율은 아주 낮습니다.DP-700인증시험준비중인 여러분은 어떤 자료를 준비하였나요?
DP-700인기자격증 시험대비 공부자료: https://www.itcertkr.com/DP-700_exam.html
참고: Itcertkr에서 Google Drive로 공유하는 무료 2026 Microsoft DP-700 시험 문제집이 있습니다: https://drive.google.com/open?id=19NlLG-ulF9xfG9iZCFA4IAsUrYSa7zWb