AI-300試験実践ガイドのPDFバージョンは、クライアントが印刷を読んでサポートするのに便利です。クライアントが当社のPDFバージョンを使用する場合、PDFフォームを便利に読んでメモを取ることができます。 AI-300クイズ準備は論文に印刷できます。クライアントが必要とする重要な情報に注意する必要がある場合、それらを紙に書いたり、読んだり紙に印刷したりするのに便利です。クライアントは、PDF形式または印刷された用紙でAI-300学習資料を読むことができます。したがって、クライアントはいつでもどこでも学習し、AI-300試験実践ガイドを繰り返し練習します。
| Section | Weight | Objectives |
|---|---|---|
| Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
| Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Implement machine learning model lifecycle and operations | 25–30% | - Register, version, and package models
|
| Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
Operationalizing Machine Learning and Generative AI Solutions試験は大多数の受験者にとって難しい難題であることは広く受け入れられていますが、関連するAI-300認定はこの分野の労働者にとって非常に重要であるため、多くの労働者はこの課題に取り組む必要があります。 幸いなことに、この種の質問について心配する必要はありません。このWebサイトJPNTestで最適なソリューションを見つけることができるので、AI-300トレーニング資料です。 テクノロジー、人材、施設への継続的な投資により、当社Microsoftの未来はこれまでになく輝かしく見えました。 優れたAI-300試験問題により、AI-300試験に合格します。
質問 # 17
Drag and Drop Question
A team deploys a machine learning model to production and monitors it continuously. Alerts are configured on performance and data quality metrics.
Multiple alerts are triggered during normal operation.
You need to perform the appropriate action for each model alert condition.
Which action should you perform for each alert condition? To answer, move the appropriate actions to the correct model alert conditions. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.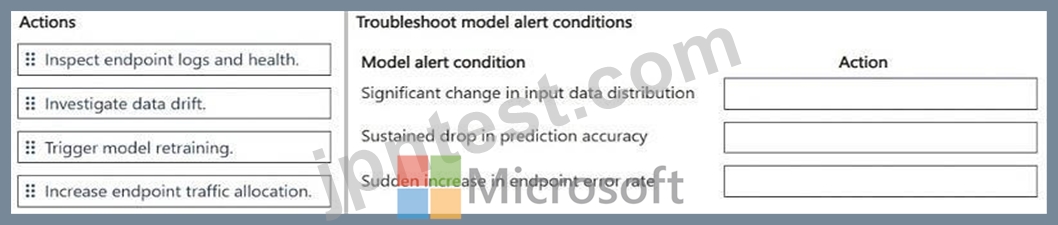
正解:
解説: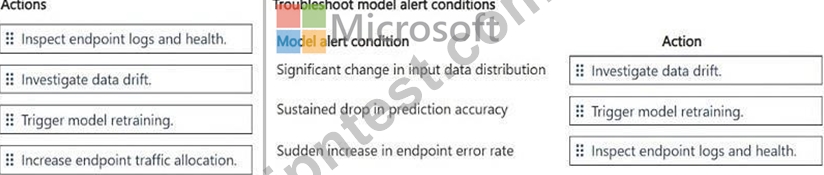
質問 # 18
A company is standardizing generative AI development across multiple teams.
Each team requires an isolated workspace. Governance and shared connections must be centrally managed.
You need to implement a Microsoft Foundry environment structure that supports centralized governance and team isolation .
Which type of configuration should you use for each requirement? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content . NOTE: Each correct selection is worth one point.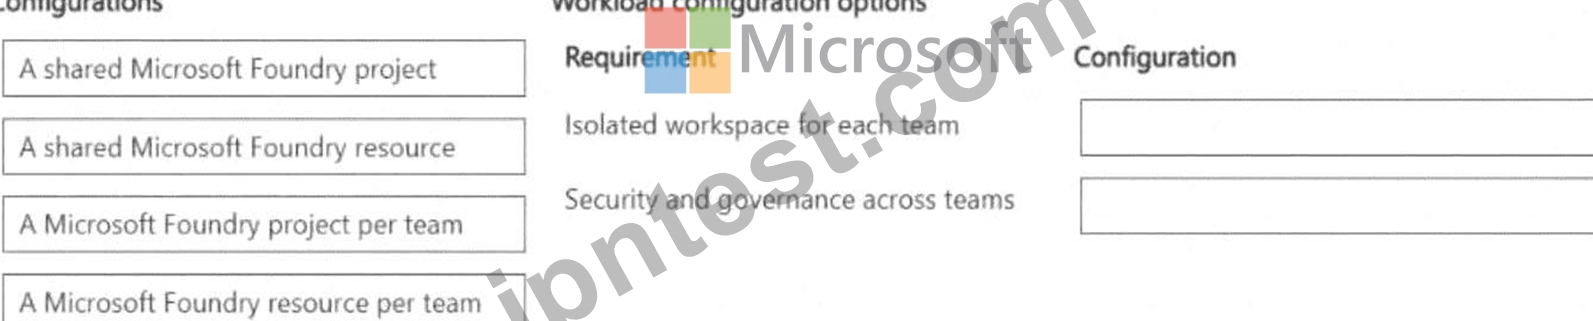
正解:
解説: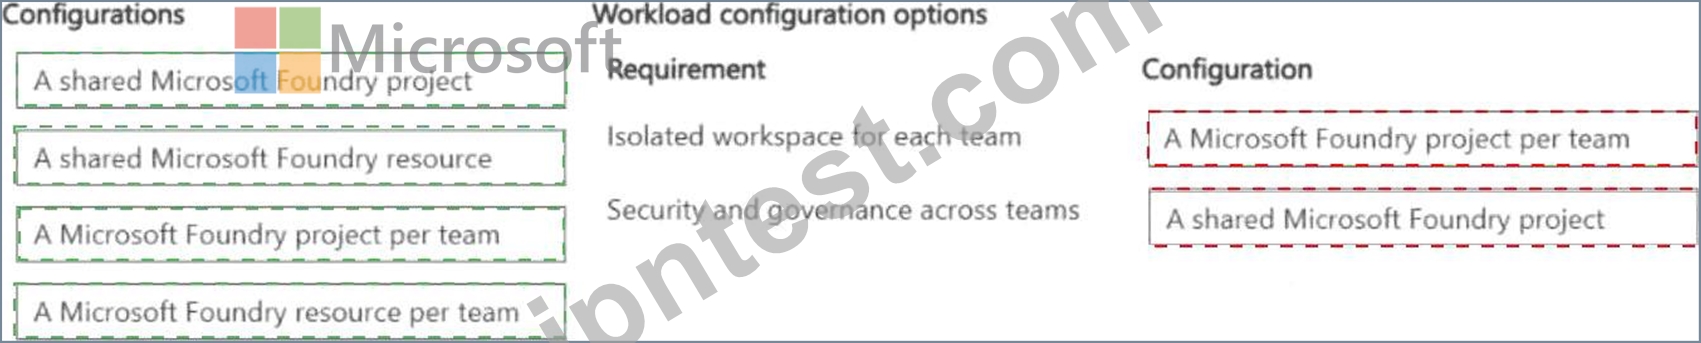
Explanation:
An Azure AI Hub is the top-level governance container in Microsoft Foundry: it holds shared connections to Azure OpenAI, Azure AI Search, Azure Storage, and other services; it defines network isolation policies; it manages billing and quota at the organizational level. Multiple teams share these resources without each team needing to configure their own connections or negotiate quota independently. An Azure AI Project sits inside the Hub and provides team-level isolation: each project has its own experiments, deployments, prompt flows, evaluations, and fine-tuning jobs, all governed by the Hub ' s shared infrastructure. Different teams get their own project with independent access controls via RBAC, while the platform team manages the shared Hub.
This pattern eliminates redundant resource configurations across teams while maintaining clear team-level boundaries - the correct structure for centralized governance with team isolation.
Microsoft Learn Reference Topic: Microsoft Azure AI Foundry hub and project architecture - Centralized governance and team isolation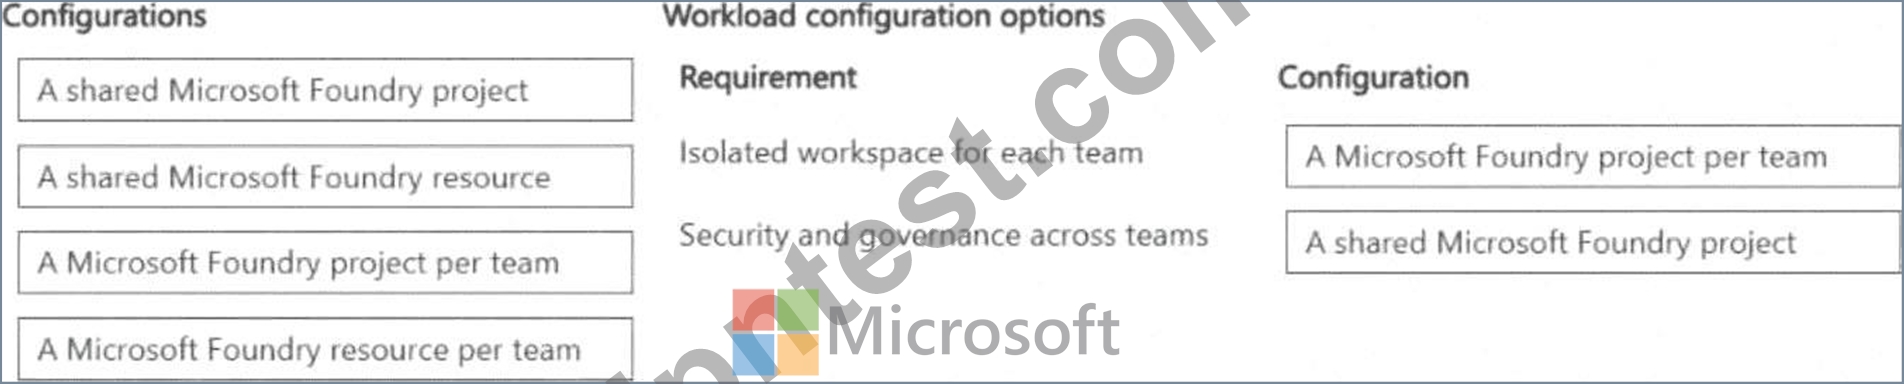
質問 # 19
Hotspot Question
You manage an Azure Machine Learning workspace. You configure an automated machine learning regression training job by using the Azure Machine Learning Python SDK v2.
You configure the regression job by using the following script: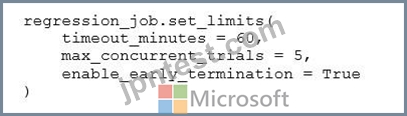
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.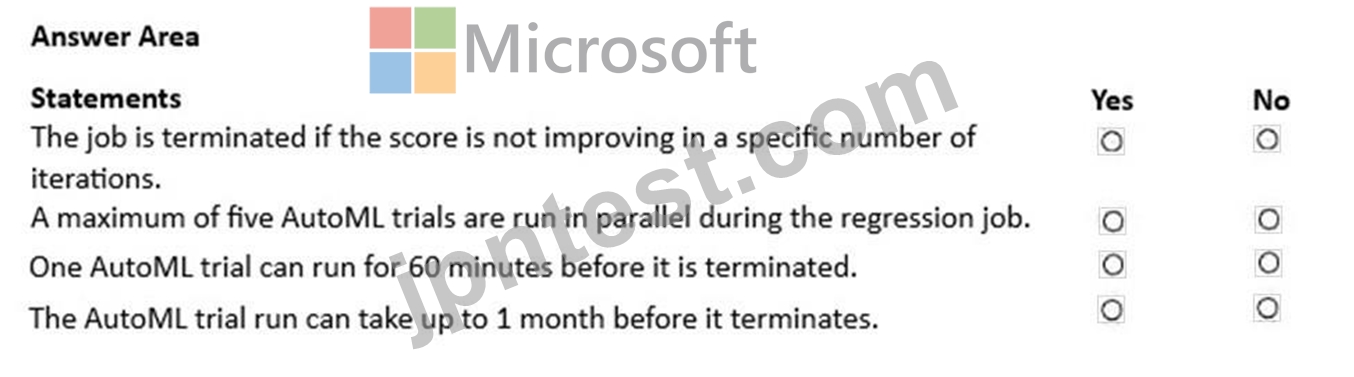
正解:
解説: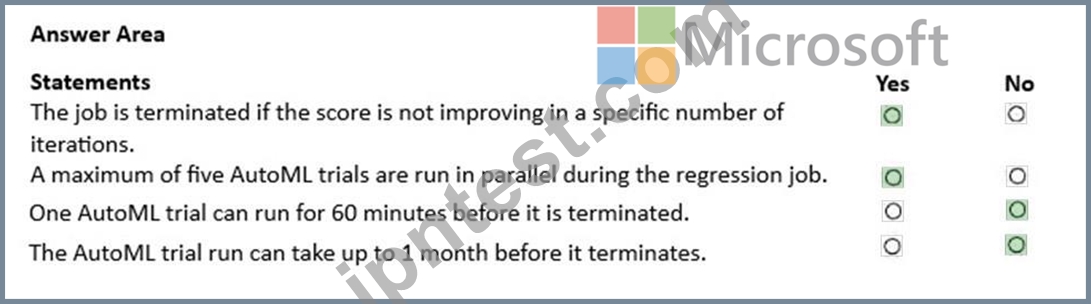
Explanation:
Box 1: Yes
Yes, the automated machine learning (AutoML) training job will terminate early if the primary metric score stops improving after a specific number of iterations.
According to the official Microsoft Azure Machine Learning SDK v2 documentation, setting enable_early_termination = True activates the early stopping policy for the overall experiment.
How Early Termination Works in AutoML v2
The internal early stopping logic operates on a built-in schedule to avoid premature termination:
First 20 iterations: No early stopping takes place (these serve as landmarks).
From the 21st iteration onward: The early stopping window activates.
Termination trigger: The job will automatically stop if the primary evaluation score fails to improve across 10 consecutive iterations.
Box 2: Yes
Yes, a maximum of five trials can run at the same time.
The limit comes from the code settings.
The max_concurrent_trials = 5 line tells Azure to run up to five trials at once.
Box 3: No
No, a single AutoML trial cannot run for 60 minutes before it is terminated.
Parameter Breakdown
In the Azure Machine Learning Python SDK v2, the set_limits() method handles timeouts via two distinct parameters:timeout_minutes = 60: This sets the maximum duration for the entire AutoML job (the experiment as a whole), including data preparation, featurization, and all training trials combined.
trial_timeout_minutes: This parameter governs the maximum time allowed for an individual trial (a single model training run) before termination.
Conclusion
Because trial_timeout_minutes is omitted from your script, it defaults to its standard system value (which is typically 20 minutes for tabular datasets). Therefore, an individual trial will time out much earlier than 60 minutes. Additionally, since the entire job terminates at 60 minutes, it is physically impossible for a single trial to consume the full 60 minutes without forcing the termination of the remaining concurrent runs.
Box 4: No
No, the AutoML trial cannot take up to 1 month before it terminates.
Based on the script parameters, the job will terminate after a maximum of 60 minutes.
Reference:
https://learn.microsoft.com/en-us/python/api/azure-ai-ml/azure.ai.ml.automl.regressionjob?view=azure-python
質問 # 20
Drag and Drop Question
A team is developing a Retrieval-Augmented Generation (RAG) system.
The team requires improvements to the system's retrieval quality to ensure accurate, grounded responses.
You need to assess RAG performance before you can suggest an improvement strategy.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.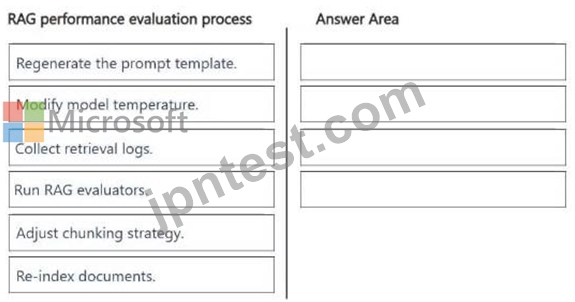
正解:
解説: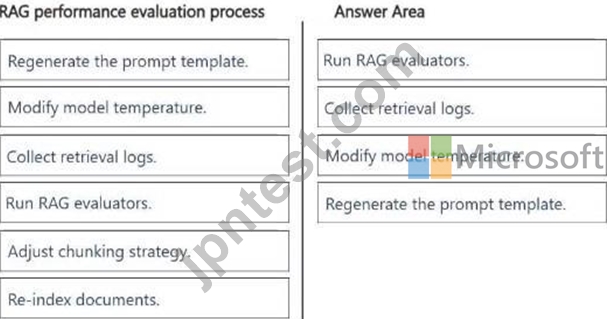
Explanation:
To properly assess your Azure Retrieval-Augmented Generation (RAG) system's performance before implementing an improvement strategy, you should include the following four steps: Run RAG evaluators, Collect retrieval logs, Modify model temperature, and Regenerate the prompt template.
Step 1: Run RAG evaluators
Run RAG evaluators is the primary method to objectively measure system performance.
Evaluators calculate data-driven metrics like groundedness, relevance, and retrieval precision using tools like Azure AI Studio Evaluators.
Step 2: Collect retrieval logs
Collect retrieval logs provides the raw operational data needed for assessment. Analyzing these logs helps you identify exactly which documents were retrieved, their relevance scores, and where the retrieval pipeline failed to fetch the correct context.
Step 3: Modify model temperature
Modify model temperature: Adjusting the temperature during assessment helps isolate whether poor responses are caused by bad retrieval or by the LLM being too creative (high temperature) or too rigid (low temperature). Testing variations helps establish a performance baseline.
Step 4: Regenerate the prompt template
Regenerate the prompt template: Evaluating how different prompt variations alter the output allows you to assess if the current template is effectively forcing the model to rely only on the retrieved context, which is critical for identifying grounding issues.
Incorrect:
Adjust the chunking strategy
This is an improvement action, not an assessment step. You would perform this optimization strategy after your assessment reveals that information is being cut off or poorly contextualized.
Re-index documents: This is a heavy remediation step. Re-indexing is a time- and resource- consuming strategy used to fix issues once the assessment phase has already proven that the current index or embedding model is faulty.
Reference:
https://flytoleisure.medium.com/guideline-for-building-a-practical-and-effective-rag-retrieval-augmented-generation-application-f6cf50676e37
質問 # 21
An organization is deploying generative AI solutions by using Microsoft Foundry to support multiple production workloads.
The organization has the following workload requirements:
* One workload must be real-time, latency-sensitive, and have predictable global usage patterns that demand consistent performance.
* One workload must have variable performance and be optimized for cost-efficient operation.
You need to select a global deployment type for each workload.
Which type of deployment should you use for each workload requirement? To answer, move the appropriate deployment types to the correct requirements. You may use each deployment type once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.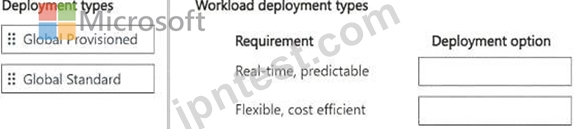
正解:
解説: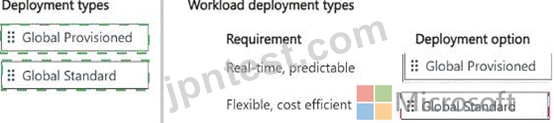
Explanation:
Real-time, predictable: Global Provisioned
Flexible, cost efficient: Global Standard
For the real-time, latency-sensitive workload with predictable global demand , use Global Provisioned .
Microsoft Foundry defines Global Provisioned deployments as providing reserved model processing capacity and predictable throughput through provisioned throughput units (PTUs). Because capacity is reserved, this deployment type provides lower and more consistent latency than Global Standard and is specifically recommended for sustained, predictable, high-throughput production workloads.
For the workload requiring flexibility and cost-efficient operation , use Global Standard . Global Standard operates on a pay-per-token model and dynamically routes requests across Azure ' s global infrastructure.
Microsoft recommends it as the starting deployment type for most workloads because it offers the lowest price, broad regional availability, and high default quota without requiring the customer to reserve PTU capacity. This makes it appropriate when demand varies and paying for permanently reserved throughput would be inefficient.
The architectural distinction is therefore straightforward: Global Provisioned trades reserved-capacity cost for predictable throughput and reduced latency variance, while Global Standard provides elastic, consumption-based operation with greater latency variability under sustained high load. Microsoft's deployment overview likewise identifies provisioned throughput for predictable low-latency performance and standard deployment for general hosted workloads.
Study Guide Reference: Design and implement a GenAIOps infrastructure - Microsoft Foundry deployment types, Global Standard, Global Provisioned, PTUs, latency predictability, throughput, and cost optimization.
質問 # 22
......
当社は、教材を担当しています。 JPNTestが顧客に販売したすべての製品は、Microsoft思いやりのあるアフターサービスをお楽しみいただけます。 インストール、操作などの学習資料に問題がある場合は、オンラインワーカーがメールをOperationalizing Machine Learning and Generative AI Solutions受信した後、すぐに返信します。 私たちはトラブルを恐れていません。 AI-300ご質問やご提案をお待ちしております。 問題の解決にお役立てください。
AI-300復習対策書: https://www.jpntest.com/shiken/AI-300-mondaishu