
2026 Latest ExamCost Data-Engineer-Associate PDF Dumps and Data-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1dgKy-D8nS9hBQgIpj9NdPpFYBHoe_UjE
ExamCost is one of the leading platforms that has been helping AWS Certified Data Engineer - Associate (DEA-C01) Exam Questions candidates for many years. Over this long time, period the AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) exam dumps helped countless Amazon Data-Engineer-Associate exam questions candidates and they easily cracked their dream AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) certification exam. You can also trust AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) exam dumps and start Amazon Data-Engineer-Associate exam preparation today.
| Section | Weight | Objectives |
|---|---|---|
| Data Ingestion and Transformation | 34% | - Transform and enrich data
- Ingest data from various sources
|
| Data Operations and Support | 22% | - Ensure reliability and scalability - Backup, restore, and disaster recovery - Monitor and troubleshoot data pipelines
|
| Data Store Management | 26% | - Design and implement data storage solutions
- Optimize storage performance and cost |
| Data Security and Governance | 18% | - Protect sensitive data - Encrypt data at rest and in transit - Implement access control and authentication
|
>> Amazon Data-Engineer-Associate Valid Test Pass4sure <<
Our AWS Certified Data Engineer - Associate (DEA-C01) test torrent boost 99% passing rate and high hit rate so you can have a high probability to pass the exam. Our Data-Engineer-Associate study torrent is compiled by experts and approved by the experienced professionals and the questions and answers are chosen elaborately according to the syllabus and the latest development conditions in the theory and the practice and based on the real exam. If you buy our AWS Certified Data Engineer - Associate (DEA-C01) test torrent you only need 1-2 hours to learn and prepare the exam and focus your main attention on your most important thing.
NEW QUESTION # 134
A data engineer must use AWS services to ingest a dataset into an Amazon S3 data lake. The data engineer profiles the dataset and discovers that the dataset contains personally identifiable information (PII). The data engineer must implement a solution to profile the dataset and obfuscate the PII.
Which solution will meet this requirement with the LEAST operational effort?
Answer: A
Explanation:
AWS Glue is a fully managed service that provides a serverless data integration platform for data preparation, data cataloging, and data loading. AWS Glue Studio is a graphical interface that allows you to easily author, run, and monitor AWS Glue ETL jobs. AWS Glue Data Quality is a feature that enables you to validate, cleanse, and enrich your data using predefined or custom rules. AWS Step Functions is a service that allows you to coordinate multiple AWS services into serverless workflows.
Using the Detect PII transform in AWS Glue Studio, you can automatically identify and label the PII in your dataset, such as names, addresses, phone numbers, email addresses, etc. You can then create a rule in AWS Glue Data Quality to obfuscate the PII, such as masking, hashing, or replacing the values with dummy data. You can also use other rules to validate and cleanse your data, such as checking for null values, duplicates, outliers, etc. You can then use an AWS Step Functions state machine to orchestrate a data pipeline to ingest the data into the S3 data lake. You can use AWS Glue DataBrew to visually explore and transform the data, AWS Glue crawlers to discover and catalog the data, and AWS Glue jobs to load the data into the S3 data lake.
This solution will meet the requirement with the least operational effort, as it leverages the serverless and managed capabilities of AWS Glue, AWS Glue Studio, AWS Glue Data Quality, and AWS Step Functions. You do not need to write any code to identify or obfuscate the PII, as you can use the built-in transforms and rules in AWS Glue Studio and AWS Glue Data Quality. You also do not need to provision or manage any servers or clusters, as AWS Glue and AWS Step Functions scale automatically based on the demand.
The other options are not as efficient as using the Detect PII transform in AWS Glue Studio, creating a rule in AWS Glue Data Quality, and using an AWS Step Functions state machine. Using an Amazon Kinesis Data Firehose delivery stream to process the dataset, creating an AWS Lambda transform function to identify the PII, using an AWS SDK to obfuscate the PII, and setting the S3 data lake as the target for the delivery stream will require more operational effort, as you will need to write and maintain code to identify and obfuscate the PII, as well as manage the Lambda function and its resources. Using the Detect PII transform in AWS Glue Studio to identify the PII, obfuscating the PII, and using an AWS Step Functions state machine to orchestrate a data pipeline to ingest the data into the S3 data lake will not be as effective as creating a rule in AWS Glue Data Quality to obfuscate the PII, as you will need to manually obfuscate the PII after identifying it, which can be error-prone and time-consuming. Ingesting the dataset into Amazon DynamoDB, creating an AWS Lambda function to identify and obfuscate the PII in the DynamoDB table and to transform the data, and using the same Lambda function to ingest the data into the S3 data lake will require more operational effort, as you will need to write and maintain code to identify and obfuscate the PII, as well as manage the Lambda function and its resources. You will also incur additional costs and complexity by using DynamoDB as an intermediate data store, which may not be necessary for your use case. Reference:
AWS Glue
AWS Glue Studio
AWS Glue Data Quality
[AWS Step Functions]
[AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide], Chapter 6: Data Integration and Transformation, Section 6.1: AWS Glue
NEW QUESTION # 135
A data engineer needs to create an Amazon Athena table based on a subset of data from an existing Athena table named cities_world. The cities_world table contains cities that are located around the world. The data engineer must create a new table named cities_us to contain only the cities from cities_world that are located in the US.
Which SQL statement should the data engineer use to meet this requirement?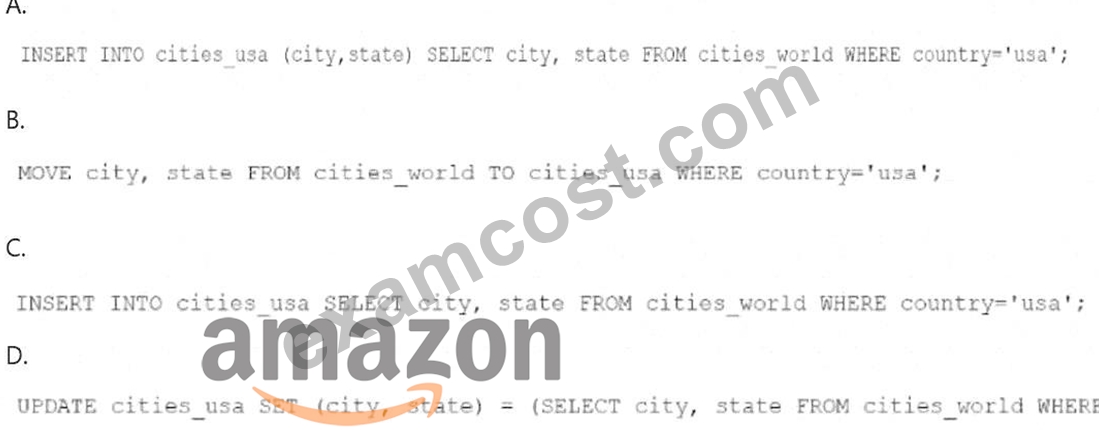
Answer: D
Explanation:
To create a new table named cities_usa in Amazon Athena based on a subset of data from the existing cities_world table, you should use an INSERT INTO statement combined with a SELECT statement to filter only the records where the country is ' usa ' . The correct SQL syntax would be:
Option A: INSERT INTO cities_usa (city, state) SELECT city, state FROM cities_world WHERE country= ' usa ' ;This statement inserts only the cities and states where the country column has a value of ' usa ' from the cities_world table into the cities_usa table. This is a correct approach to create a new table with data filtered from an existing table in Athena.
Options B, C, and D are incorrect due to syntax errors or incorrect SQL usage (e.g., the MOVE command or the use of UPDATE in a non-relevant context).
References:
Amazon Athena SQL Reference
Creating Tables in Athena
NEW QUESTION # 136
A company stores logs in an Amazon S3 bucket. When a data engineer attempts to access several log files, the data engineer discovers that some files have been unintentionally deleted.
The data engineer needs a solution that will prevent unintentional file deletion in the future.
Which solution will meet this requirement with the LEAST operational overhead?
Answer: A
Explanation:
To prevent unintentional file deletions and meet the requirement with minimal operational overhead, enabling S3 Versioning is the best solution.
* S3 Versioning:
* S3 Versioning allows multiple versions of an object to be stored in the same S3 bucket. When a file is deleted or overwritten, S3 preserves the previous versions, which means you can recover from accidental deletions or modifications.
* Enabling versioning requires minimal overhead, as it is a bucket-level setting and does not require additional backup processes or data replication.
* Users can recover specific versions of files that were unintentionally deleted, meeting the needs of the data engineer to avoid accidental data loss.
NEW QUESTION # 137
A manufacturing company collects sensor data from its factory floor to monitor and enhance operational efficiency. The company uses Amazon Kinesis Data Streams to publish the data that the sensors collect to a data stream. Then Amazon Kinesis Data Firehose writes the data to an Amazon S3 bucket.
The company needs to display a real-time view of operational efficiency on a large screen in the manufacturing facility.
Which solution will meet these requirements with the LOWEST latency?
Answer: A
Explanation:
This solution will meet the requirements with the lowest latency because it uses Amazon Managed Service for Apache Flink to process the sensor data in real time and write it to Amazon Timestream, a fast, scalable, and serverless time series database. Amazon Timestream is optimized for storing and analyzing time series data, such as sensor data, and can handle trillions of events per day with millisecond latency. By using Amazon Timestream as a source, you can create an Amazon QuickSight dashboard that displays a real-time view of operational efficiency on a large screen in the manufacturing facility. Amazon QuickSight is a fully managed business intelligence service that can connect to various data sources, including Amazon Timestream, and provide interactive visualizations and insights123.
The other options are not optimal for the following reasons:
* A. Use Amazon Managed Service for Apache Flink (previously known as Amazon Kinesis Data Analytics) to process the sensor data. Use a connector for Apache Flink to write data to an Amazon Timestream database. Use the Timestream database as a source to create a Grafana dashboard. This option is similar to option C, but it uses Grafana instead of Amazon QuickSight to create the dashboard.
Grafana is an open source visualization tool that can also connect to Amazon Timestream, but it requires additional steps to set up and configure, such as deploying a Grafana server on Amazon EC2, installing the Amazon Timestream plugin, and creating an IAM role for Grafana to access Timestream.
These steps can increase the latency and complexity of the solution.
* B. Configure the S3 bucket to send a notification to an AWS Lambda function when any new object is created. Use the Lambda function to publish the data to Amazon Aurora. Use Aurora as a source to create an Amazon QuickSight dashboard. This option is not suitable for displaying a real-time view of operational efficiency, as it introduces unnecessary delays and costs in the data pipeline. First, the sensor data is written to an S3 bucket by Amazon Kinesis Data Firehose, which can have a buffering interval of up to 900 seconds. Then, the S3 bucket sends a notification to a Lambda function, which can incur additional invocation and execution time. Finally, the Lambda function publishes the data to Amazon Aurora, a relational database that is not optimized for time series data and can have higher storage and performance costs than Amazon Timestream .
* D. Use AWS Glue bookmarks to read sensor data from the S3 bucket in real time. Publish the data to an Amazon Timestream database. Use the Timestream database as a source to create a Grafana dashboard.
This option is also not suitable for displaying a real-time view of operational efficiency, as it uses AWS Glue bookmarks to read sensor data from the S3 bucket. AWS Glue bookmarks are a feature that helps AWS Glue jobs and crawlers keep track of the data that has already been processed, so that they can resume from where they left off. However, AWS Glue jobs and crawlers are not designed for real-time data processing, as they can have a minimum frequency of 5 minutes and a variable start-up time.
Moreover, this option also uses Grafana instead of Amazon QuickSight to create the dashboard, which can increase the latency and complexity of the solution .
1: Amazon Managed Streaming for Apache Flink
2: Amazon Timestream
3: Amazon QuickSight
4: Analyze data in Amazon Timestream using Grafana
5: Amazon Kinesis Data Firehose
6: Amazon Aurora
7: AWS Glue Bookmarks
8: AWS Glue Job and Crawler Scheduling
NEW QUESTION # 138
A company needs to collect logs for an Amazon RDS for MySQL database and make the logs available for audits. The logs must track each user that modifies data in the database or makes changes to the database instance.
Which solution will meet these requirements?
Answer: A
Explanation:
The correct answer is D: Enable native Amazon RDS database audit logging with CloudWatch and CloudTrail integration.
* Native RDS database audit logging captures SQL-level activities, including which user is modifying data, which is essential for meeting audit requirements.
* Amazon CloudWatch Logs can be used to centralize and store logs.
* CloudTrail logs API calls related to instance-level changes, ensuring all modifications are traceable.
* This approach provides a comprehensive audit trail and supports compliance with security governance policies.
"Enable and configure native Amazon RDS database audit logging. Enable Amazon CloudWatch Logs.
Configure metric filters and alarms. Configure AWS CloudTrail audit logging." Reference: DEA-C01 Official Study Guide - Chapter 7: Data Security and GovernanceVerified on AWS Docs: https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/USER_LogAccess.Concepts.MySQL.html
NEW QUESTION # 139
......
On the one hand, our Data-Engineer-Associate quiz torrent can help you obtain professional certificates with high quality in any industry without any difficulty. On the other hand, Data-Engineer-Associate exam guide can give you the opportunity to become a senior manager of the company, so that you no longer engage in simple and repetitive work, and you will never face the threat of layoffs. However, if you are an unemployed person, our study materials also should be the best choice for you. Data-Engineer-Associate Quiz torrent can help you calm down and learn more knowledge of it, and what most important is that our study materials can help you use the shortest time to reach to the top of your career. What are you waiting for? Come and buy it now!
Online Data-Engineer-Associate Test: https://www.examcost.com/Data-Engineer-Associate-practice-exam.html
P.S. Free 2026 Amazon Data-Engineer-Associate dumps are available on Google Drive shared by ExamCost: https://drive.google.com/open?id=1dgKy-D8nS9hBQgIpj9NdPpFYBHoe_UjE