BONUS!!! DumpTOP NCA-GENM 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=1x9W_Gz_SC6tD7WR6YFkZo3nmMB8TaLoy
DumpTOP 의 엘리트는 다년간 IT업계에 종사한 노하우로 높은 적중율을 자랑하는 NVIDIA NCA-GENM덤프를 연구제작하였습니다. 한국어 온라인서비스가 가능하기에 NVIDIA NCA-GENM덤프에 관하여 궁금한 점이 있으신 분은 구매전 문의하시면 됩니다. NVIDIA NCA-GENM덤프로 시험에서 좋은 성적 받고 자격증 취득하시길 바랍니다.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Software Development and Engineering | 15% | - Development workflows for generative AI applications - Best practices for building and maintaining systems - Libraries, frameworks, and tools for multimodal AI |
| Topic 2: Multimodal Data | 15% | - Characteristics of text, image, and audio data - Multimodal model architectures and integration - Data preprocessing, fusion, and representation |
| Topic 3: Trustworthy AI | 5% | - Robustness and error mitigation - Reliability, fairness, and safety in generative systems - Ethical considerations and responsible use |
| Topic 4: Experimentation | 25% | - Model training, fine-tuning, and evaluation - Metrics and validation strategies for generative models - Experiment design and methodology |
| Topic 5: Core Machine Learning and AI Knowledge | 20% | - Neural network architectures relevant to multimodal systems - Fundamental concepts of machine learning and deep learning - Generative AI principles and techniques |
| Topic 6: Performance Optimization | 10% | - Scalability and deployment considerations - Hardware acceleration with NVIDIA platforms - Model efficiency and inference optimization |
| Topic 7: Data Analysis and Visualization | 10% | - Visualization techniques for model behavior and results - Analyzing multimodal datasets and outputs - Interpretation of generative AI outputs |
NVIDIA NCA-GENM인증시험패스에는 많은 방법이 있습니다. 먼저 많은 시간을 투자하고 신경을 써서 전문적으로 과련 지식을 터득한다거나; 아니면 적은 시간투자와 적은 돈을 들여 DumpTOP의 인증시험덤프를 구매하는 방법 등이 있습니다.
질문 # 14
What are some methods to overcome limited throughput between CPU and GPU?
정답:C
설명:
CPU-GPU data transfer over the PCIe (or NVLink) bus is frequently a throughput bottleneck in ML pipelines, particularly when small, frequent transfers dominate rather than large batched ones - each transfer incurs fixed overhead independent of data size, so many small transfers waste a disproportionate amount of time on overhead rather than useful data movement. Memory pooling techniques - pre-allocating and reusing pinned (page-locked) host memory buffers rather than repeatedly allocating and freeing memory for each transfer - reduce this overhead and enable faster, more predictable DMA transfers between host and device. Related software-level techniques include using CUDA streams to overlap data transfer with computation (so the GPU keeps computing while the next batch transfers in the background), and batching transfers to amortize fixed per-transfer overhead across more data.
Options A, B, and D each propose hardware upgrades that address a different bottleneck than the one described: increasing CPU clock speed (A) or core count (B) improves CPU-side compute throughput, not the data-transfer bandwidth or latency between CPU and GPU specifically. Upgrading the GPU (D) increases GPU compute capability but does nothing to address a PCIe/interconnect bandwidth limitation - a faster GPU sitting idle waiting for data across the same bottlenecked bus would not see meaningfully improved end- to-end throughput. The question specifically asks about *throughput between* CPU and GPU, which points to interconnect/transfer-management optimization rather than raw compute upgrades on either side.
Reference: Performance Optimization domain - CPU-GPU data transfer optimization, pinned memory, memory pooling, CUDA streams.
질문 # 15
You're building a multimodal model that predicts customer satisfaction based on their written reviews and associated call center audio recordings. You've pre-trained separate text and audio encoders. What's the MOST effective strategy to fuse these modalities for the final prediction task?
정답:A
설명:
An attention mechanism allows the model to dynamically learn the importance of each modality based on the input. This is more flexible and effective than simple concatenation or averaging (A, B, E), which treat both modalities equally. Fine-tuning only one encoder (C) doesn't leverage the benefits of multimodal fusion. While concatenation (A) is a common starting point, attention provides a more nuanced and powerful way to combine modalities. Adding features (E) is also not effective.
질문 # 16
Consider the following PyTorch code snippet intended for training a variational autoencoder (VAE):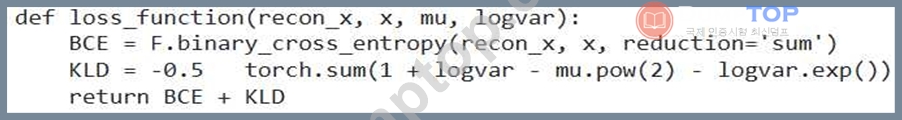
What potential issue(s) exist(s) in this code, and how would you address them?
정답:B
설명:
All the mentioned issues exist. Firstly, BCE requires inputs between 0 and 1 . Secondly, KLD loss needs to be scaled according to batch size for proper gradients during training. Thirdly, simply summing the BCE isn't ideal, average is better. Finally, the KLD calculation is indeed reverse of what it should be.
질문 # 17
You are developing a text-to-image generative model and want to evaluate the quality and diversity of the generated images. Which metric is MOST appropriate for assessing the diversity of generated images, considering computational efficiency is also important?
정답:B
설명:
FID is a commonly used metric for evaluating the quality and diversity of generated images, and it's more robust than IS. While LPIPS and MS-SSIM are useful for measuring perceptual similarity between images, they don't directly quantify diversity across a large set of generated images. Simply counting unique images doesn't capture the semantic diversity of the generated content. FID calculates the distance between the feature representations of real and generated images, capturing both quality and diversity.
질문 # 18
You are tasked with generating realistic images of human faces using a GAN. However, you notice that the generated images often contain artifacts, such as distorted facial features or unrealistic textures. Which of the following techniques would be most effective in improving the realism and quality of the generated faces?
정답:C
설명:
StyleGAN architecture, with its AdalN and mapping network, is specifically designed to control and manipulate the style attributes of generated images, leading to more realistic and high-quality outputs, particularly for complex structures like human faces. AdalN helps in normalizing feature statistics based on style codes, enabling fine-grained control over the visual appearance.
질문 # 19
......
DumpTOP의 완벽한 NVIDIA인증 NCA-GENM덤프는 고객님이NVIDIA인증 NCA-GENM시험을 패스하는 지름길입니다. 시간과 돈을 적게 들이는 반면 효과는 십점만점에 십점입니다. DumpTOP의 NVIDIA인증 NCA-GENM덤프를 선택하시면 고객님께서 원하시는 시험점수를 받아 자격증을 쉽게 취득할수 있습니다.
NCA-GENM 100%시험패스 자료: https://www.dumptop.com/NVIDIA/NCA-GENM-dump.html
참고: DumpTOP에서 Google Drive로 공유하는 무료, 최신 NCA-GENM 시험 문제집이 있습니다: https://drive.google.com/open?id=1x9W_Gz_SC6tD7WR6YFkZo3nmMB8TaLoy