P.S. Free & New CCAR-P dumps are available on Google Drive shared by Real4test: https://drive.google.com/open?id=1CDsQ9Tar71kS-J2zlqtxnmkCIURubDzq
In the such a brilliant era of IT industry in the 21st century competition is very fierce. Naturally, Anthropic Certification CCAR-P Exam has become a very popular exam in the IT area. More and more people register for the exam and passing the certification exam is also those ambitious IT professionals' dream.
| Section | Weight | Objectives |
|---|---|---|
| Developer Productivity & Operational Enablement | 7% | - Improve developer workflows with AI-assisted tooling - Configure Claude tools and environments for teams - Support debugging, monitoring, and operational resolution |
| Solution Design & Architecture | 17% | - Design multi-agent systems and orchestration strategies - Design end-to-end architectures and feedback loops - Align solutions to business value pillars - Translate business problems into Claude-based AI solutions - Select architectural patterns: workflow, agentic, augmented LLM |
| Integration | 19% | - Implement Model Context Protocol (MCP) integrations - Integrate with data pipelines and RAG systems - Integrate Claude with enterprise systems, APIs, and tools - Design authentication, authorization, and observability |
| Claude Models, Prompting & Context Engineering | 13% | - Design system prompts, templates, and guardrails - Select appropriate Claude models based on trade-offs - Apply context engineering and context management techniques - Mitigate prompt injection, leaks, and jailbreak risks |
| Stakeholder Communication & Lifecycle Management | 14% | - Conduct structured discovery and requirement gathering - Manage stakeholder feedback and expectation alignment - Communicate architectural decisions and trade-offs - Document architectures and support full lifecycle phases |
| Evaluation, Testing & Optimization | 16% | - Define evaluation metrics and success criteria - Test accuracy, reliability, latency, and cost - Optimize performance, prompting, and model selection - Implement iterative improvement pipelines |
| Governance, Safety & Risk Management | 14% | - Address ethical AI considerations and bias mitigation - Manage data privacy and security compliance - Implement guardrails and safety controls - Ensure regulatory compliance (GDPR, HIPAA, etc.) |
>> Exam CCAR-P Study Solutions <<
All three Anthropic CCAR-P exam questions formats are easy to use and compatible with all devices, operating systems, and the latest browsers. Now take the best decision for your career and take part in the Claude Certified Architect - Professional CCAR-P Certification test and start preparation with Anthropic CCAR-P PDF Questions and practice tests. Real4test offers free updates for 365 days.
NEW QUESTION # 99
You are evaluating an evaluation set used to score a Claude-based hiring-support tool. The set is drawn from one geographic region and one tenure band.
Which response is most appropriate?
Answer: C
Explanation:
An evaluation set must represent the populations, operating conditions, and use cases that the deployed system will encounter. A dataset drawn from only one geographic region and one tenure band cannot reliably demonstrate that the hiring-support tool performs consistently across its intended users. Expanding the evaluation set enables architects to identify regional performance differences, tenure-related errors, unsupported generalizations, and potentially discriminatory outcomes before broader deployment. The system should then be rescored using the expanded dataset, with results examined across relevant population slices rather than relying only on an aggregate score. Options A and B preserve or worsen the representation gap.
Option D is also inappropriate because qualitative feedback can supplement structured evaluation but cannot replace measurable, repeatable testing of accuracy, fairness, and reliability across the intended deployment population.
NEW QUESTION # 100
You are listing characteristics of strong architectural-decision communication.
Which two characteristics belong on the list? (Select two.)
Each correct answer presents a complete solution.
Answer: A,C
Explanation:
Strong decision communication must explain both how the decision was reached and how it will remain governed. Option D provides the reasoning structure: the alternatives considered and the criteria used to compare them. This allows reviewers to verify that capability, cost, latency, security, maintainability, integration complexity, and business outcomes were evaluated consistently rather than selectively.
Option A establishes lifecycle accountability. Architectural decisions depend on assumptions about requirements, models, data, regulations, usage volume, and operational constraints. Naming an owner and review cadence ensures the decision is reconsidered when those assumptions materially change.
Option B imposes a meeting mechanism rather than describing decision quality. Mandatory attendance by senior leaders may add delay without improving the clarity or correctness of the record. Option C removes important evidence and increases the chance that rejected approaches will be proposed again without addressing the original objections. Option E can improve consistency and discoverability, but visual standardization alone does not establish substantive architectural communication.
A strong decision record should therefore be evidence-based, audience-accessible, traceable to requirements, explicit about alternatives and consequences, assigned to an accountable owner, and governed by defined review triggers.
Study Guide references/topics: Architectural-decision communication; alternatives analysis; evaluation criteria; decision ownership; review cadence; changing assumptions; lifecycle governance.
NEW QUESTION # 101
You are a solution architect evaluating candidate use cases for a Claude-based program.
For each scenario, select Yes if Claude is appropriate as the primary solution at the architectural level.
Otherwise, select No.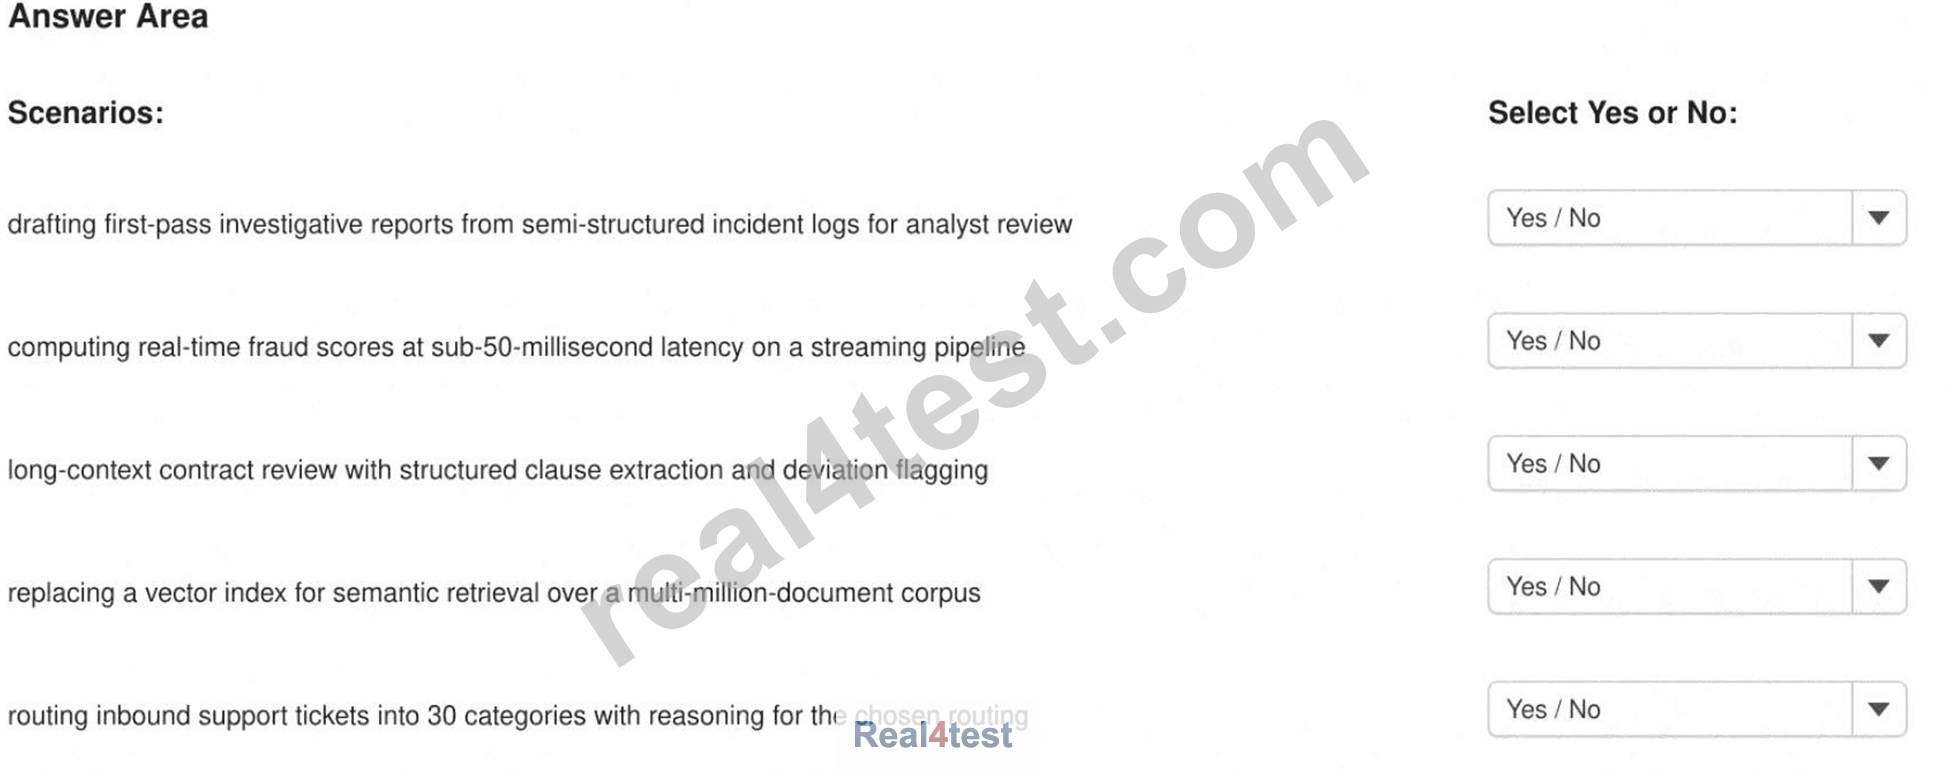
Answer:
Explanation: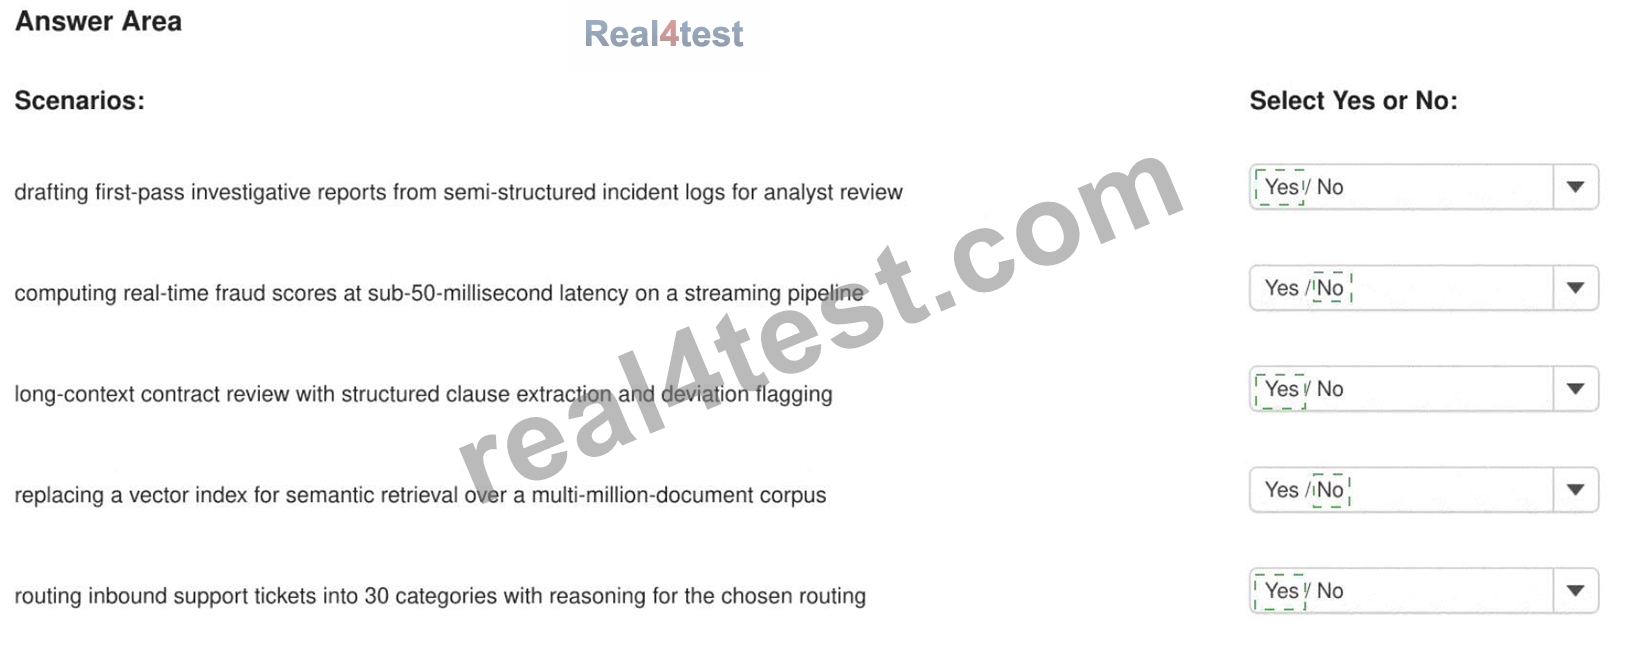
Explanation:
* Drafting first-pass investigative reports from semi-structured incident logs for analyst review - Yes
* Computing real-time fraud scores at sub-50-millisecond latency on a streaming pipeline - No
* Long-context contract review with structured clause extraction and deviation flagging - Yes
* Replacing a vector index for semantic retrieval over a multi-million-document corpus - No
* Routing inbound support tickets into 30 categories with reasoning for the selected route - Yes Claude is well suited to language-intensive analysis, summarization, extraction, classification, and drafting.
Investigative-report drafting, contract analysis, and support-ticket routing all require interpretation of unstructured or semi-structured language and can incorporate human review. A sub-50-millisecond fraud- scoring path requires deterministic, specialized real-time processing and should not place LLM inference on the critical path. Claude also does not replace the retrieval index used to search millions of documents; it consumes the results produced by that infrastructure. The correct architectural decision separates tasks requiring semantic language reasoning from deterministic computation and information-retrieval infrastructure. Model selection and evaluation must then confirm that the chosen Claude model satisfies quality, latency, and cost requirements.
NEW QUESTION # 102
You are classifying token-management tactics by where each tactic applies in the request lifecycle: "Input Preparation," "Prompt Construction," or "Output Handling."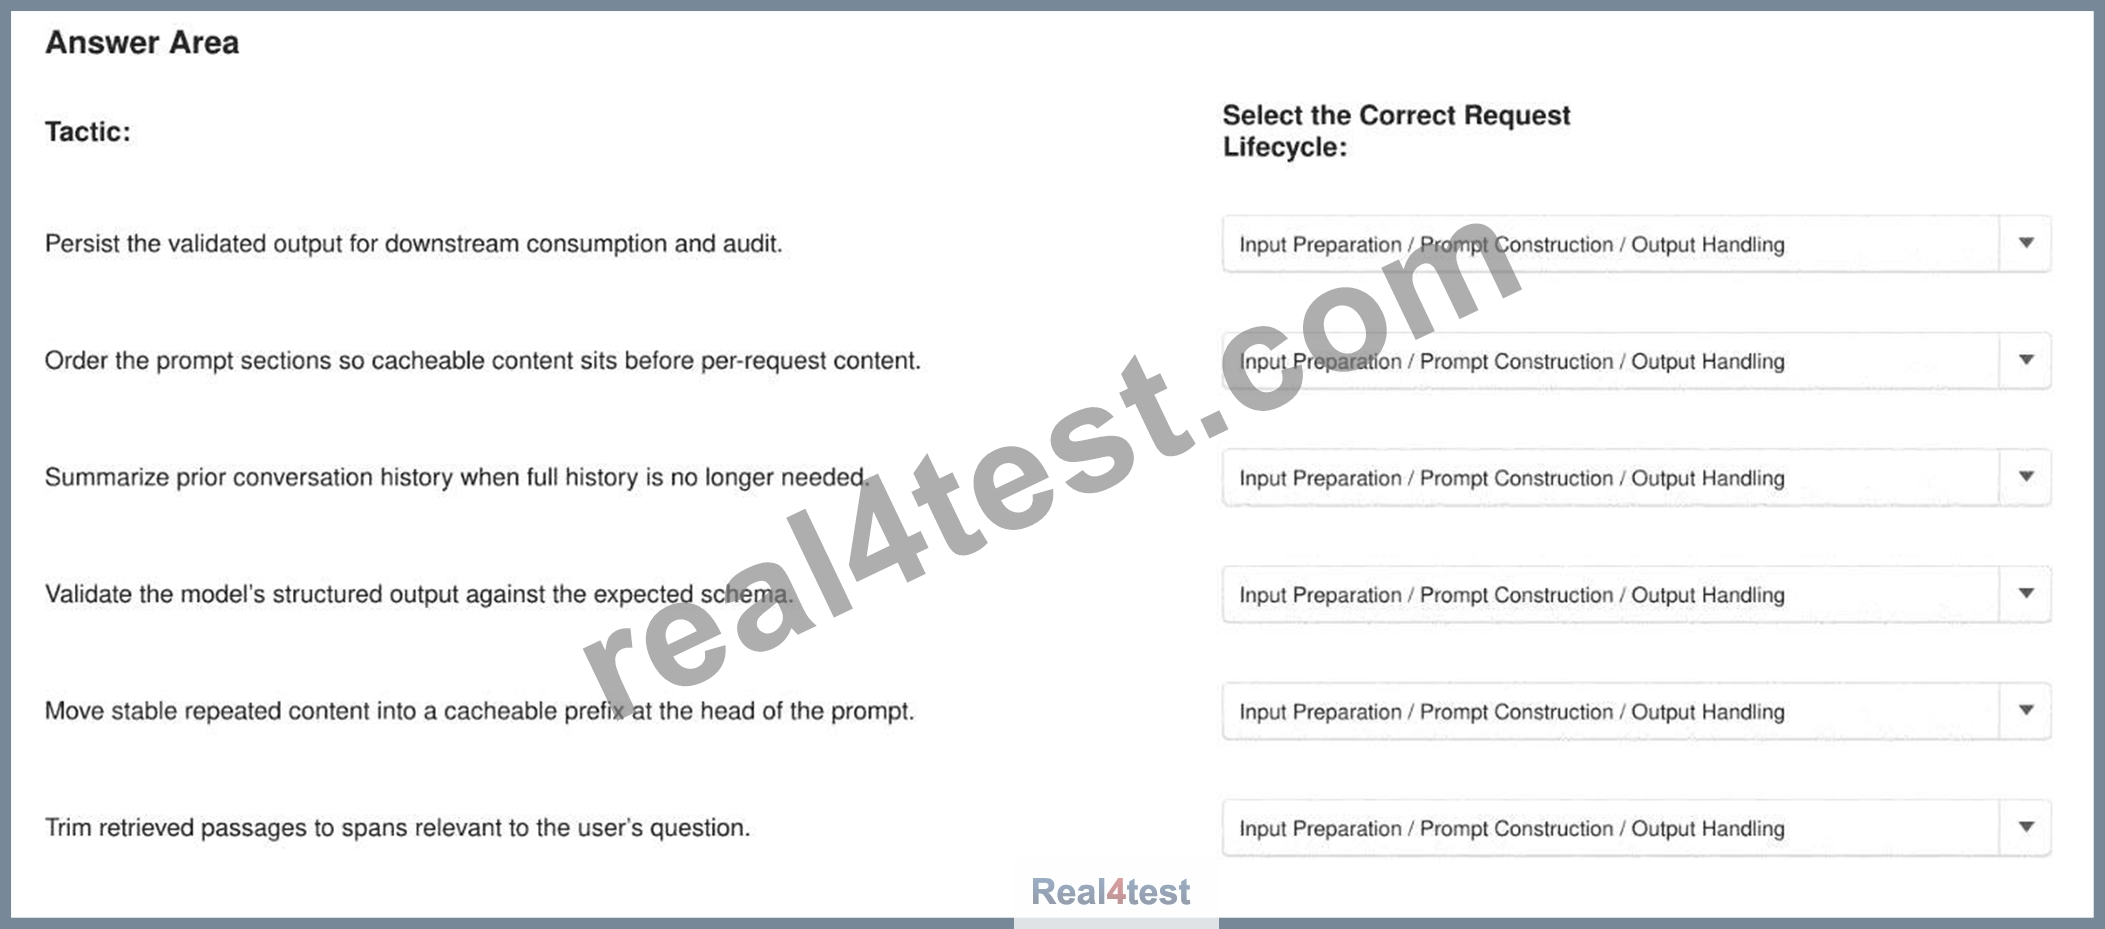
Answer:
Explanation: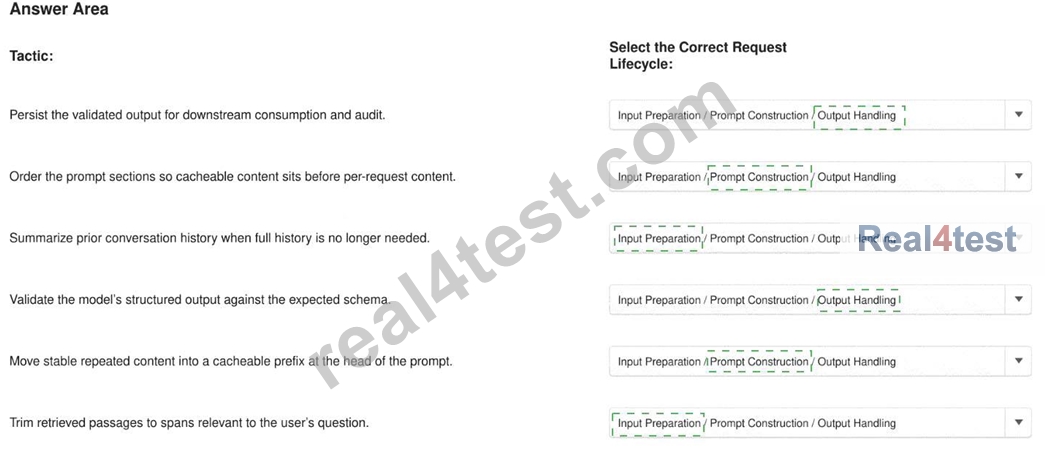
Explanation:
Persist the validated output for downstream consumption and audit - Output Handling Order prompt sections so cacheable content appears before per-request content - Prompt Construction Summarize prior conversation history when full history is no longer needed - Input Preparation Validate the model's structured output against the expected schema - Output Handling Move stable repeated content into a cacheable prefix at the beginning of the prompt - Prompt Construction Trim retrieved passages to spans relevant to the user's question - Input Preparation Input preparation determines what evidence and history should enter the request, so summarization and retrieval trimming belong there. Prompt construction determines ordering and cache boundaries; stable repeated instructions must precede dynamic per-request content to maximize cache reuse. Output handling begins after generation and includes schema validation, persistence, auditing, and downstream delivery.
Mixing these responsibilities creates inefficient prompts and weak validation boundaries. Anthropic's context guidance emphasizes curating the smallest useful context because unnecessary tokens can reduce recall and accuracy. Prompt caching similarly depends on a stable reusable prefix, while structured outputs or schema validation protect downstream systems from malformed responses. Context windows; prompt caching
NEW QUESTION # 103
You are responding to an adversarial input pattern in which users include text claiming admin authority and instructing the model to bypass safety restrictions.
Which combination of controls most effectively mitigates this attack pattern?
Answer: B
Explanation:
Self-declared administrative authority inside a prompt is untrusted data, not authenticated identity or authorization evidence. Option B correctly combines independent controls across the model, runtime, authorization, and monitoring layers.
Prompt instructions establish that user content cannot override system policy. Runtime classifiers detect known and generalized attempts to bypass controls. Tool permissions are enforced outside the model and must derive from authenticated identity, role, and approved scope-not statements contained in the conversation. Audit logging records the actor, attempted override, classifier result, tool requests, and final disposition for investigation and control improvement.
Anthropic recommends input screening, hardened system prompts, safe handling of untrusted content, narrowly scoped permissions, red-team testing, and continuous monitoring. Mitigate Jailbreaks and Prompt Injections Option A depends entirely on model behavior and provides no containment if the model fails. Option C removes the protections the attacker is attempting to defeat. Option D commits a fundamental authorization error by accepting an unverified claim as privilege elevation.
The strongest design also rate-limits repeated attempts, escalates suspicious activity, validates outputs, and requires human confirmation for consequential actions.
Study Guide references/topics: Direct prompt injection; untrusted user content; runtime classifiers; non-model authorization; scoped tools; audit logging; defense in depth.
NEW QUESTION # 104
......
As we know, everyone has opportunities to achieve their own value and life dream. And our CCAR-P can help them achieve all of these more easily and leisurely. Our CCAR-P exam materials are pleased to serve you as such an exam tool. With over a decade’s endeavor, our CCAR-P Practice Guide successfully become the most reliable products in the industry. There is a great deal of advantages of our CCAR-P exam questions you can spare some time to get to know.
CCAR-P Real Dump: https://www.real4test.com/CCAR-P_real-exam.html
BONUS!!! Download part of Real4test CCAR-P dumps for free: https://drive.google.com/open?id=1CDsQ9Tar71kS-J2zlqtxnmkCIURubDzq