DOWNLOAD the newest PrepAwayETE DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1nQT3MCZSx5u5874q5Xba6aN2Hn86GEam
If you want to sharpen your skills, or get the DP-100 certification done within the target period, it is important to get the best DP-100 exam questions. You must try PrepAwayETE DP-100 practice exam that will help you get Microsoft DP-100 certification. PrepAwayETE hires the top industry experts to draft the Designing and Implementing a Data Science Solution on Azure (DP-100) exam dumps and help the candidates to clear their DP-100 exam easily. PrepAwayETE plays a vital role in their journey to get the DP-100 certification.
| Section | Objectives |
|---|---|
| Topic 1: Train machine learning models | - Tune hyperparameters and evaluate models - Train models using Azure Machine Learning |
| Topic 2: Explore and analyze data | - Perform exploratory data analysis - Ingest and prepare data for modeling |
| Topic 3: Deploy and consume models | - Monitor deployed models and endpoints - Deploy models to endpoints |
| Topic 4: Optimize and manage models | - Improve model performance - Track experiments and manage model lifecycle |
| Topic 5: Design and prepare a machine learning solution | - Select appropriate Azure services for machine learning workloads - Plan and configure Azure Machine Learning workspace - Manage compute and data assets |
Our DP-100 exam questions are supposed to help you pass the exam smoothly. Don't worry about channels to the best DP-100 study materials so many exam candidates admire our generosity of offering help for them. Up to now, no one has ever challenged our leading position of this area. The existence of our DP-100 learning guide is regarded as in favor of your efficiency of passing the exam. And the pass rate of our DP-100 training braindumps is high as 98% to 100%.
NEW QUESTION # 272
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You create an Azure Machine Learning service datastore in a workspace. The datastore contains the following files:
* /data/2018/Q1.csv
* /data/2018/Q2.csv
* /data/2018/Q3.csv
* /data/2018/Q4.csv
* /data/2019/Q1.csv
All files store data in the following format:
id,f1,f2,I
1,1,2,0
2,1,1,1
3,2,1,0
4,2,2,1
You run the following code: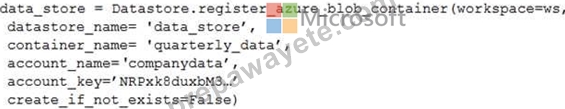
You need to create a dataset named training_data and load the data from all files into a single data frame by using the following code:
Solution: Run the following code:
Does the solution meet the goal?
Answer: B
Explanation:
Use two file paths.
Use Dataset.Tabular_from_delimeted, instead of Dataset.File.from_files as the data isn't cleansed.
Note:
A FileDataset references single or multiple files in your datastores or public URLs. If your data is already cleansed, and ready to use in training experiments, you can download or mount the files to your compute as a FileDataset object.
A TabularDataset represents data in a tabular format by parsing the provided file or list of files. This provides you with the ability to materialize the data into a pandas or Spark DataFrame so you can work with familiar data preparation and training libraries without having to leave your notebook. You can create a TabularDataset object from .csv, .tsv, .parquet, .jsonl files, and from SQL query results.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-create-register-datasets
NEW QUESTION # 273
You create an Azure Machine Learning workspace. You use the Azure Machine Learning SDK for Python.
You must create a dataset from remote paths. The dataset must be reusable within the workspace.
You need to create the dataset.
How should you complete the following code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.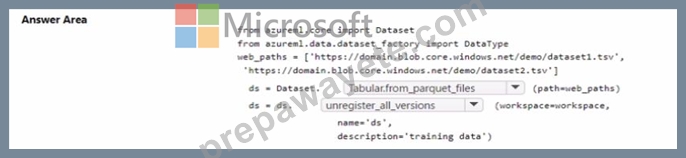
Answer:
Explanation: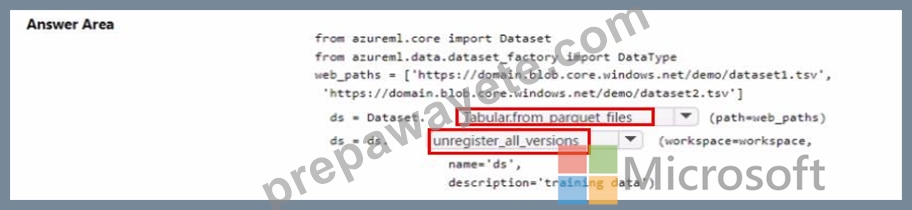
NEW QUESTION # 274
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You create a model to forecast weather conditions based on historical data.
You need to create a pipeline that runs a processing script to load data from a datastore and pass the processed data to a machine learning model training script.
Solution: Run the following code: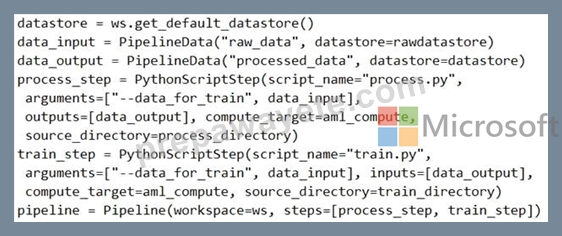
Does the solution meet the goal?
Answer: B
Explanation:
Explanation
Note: Data used in pipeline can be produced by one step and consumed in another step by providing a PipelineData object as an output of one step and an input of one or more subsequent steps.
Compare with this example, the pipeline train step depends on the process_step_output output of the pipeline process step:
from azureml.pipeline.core import Pipeline, PipelineData
from azureml.pipeline.steps import PythonScriptStep
datastore = ws.get_default_datastore()
process_step_output = PipelineData("processed_data", datastore=datastore) process_step = PythonScriptStep(script_name="process.py", arguments=["--data_for_train", process_step_output], outputs=[process_step_output], compute_target=aml_compute, source_directory=process_directory) train_step = PythonScriptStep(script_name="train.py", arguments=["--data_for_train", process_step_output], inputs=[process_step_output], compute_target=aml_compute, source_directory=train_directory) pipeline = Pipeline(workspace=ws, steps=[process_step, train_step]) Reference:
https://docs.microsoft.com/en-us/python/api/azureml-pipeline-core/azureml.pipeline.core.pipelinedata?view=azu
NEW QUESTION # 275
You need to select a feature extraction method.
Which method should you use?
Answer: C
Explanation:
In statistics, the Kendall rank correlation coefficient, commonly referred to as Kendall's tau coefficient (after the Greek letter τ), is a statistic used to measure the ordinal association between two measured quantities.
It is a supported method of the Azure Machine Learning Feature selection.
Note: Both Spearman's and Kendall's can be formulated as special cases of a more general correlation coefficient, and they are both appropriate in this scenario.
Scenario: The MedianValue and AvgRoomsInHouse columns both hold data in numeric format. You need to select a feature selection algorithm to analyze the relationship between the two columns in more detail.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/feature-selection-modules
NEW QUESTION # 276
You use Azure Machine Learning to deploy a model as a real-time web service.
You need to create an entry script for the service that ensures that the model is loaded when the service starts and is used to score new data as it is received.
Which functions should you include in the script? To answer, drag the appropriate functions to the correct actions. Each function may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.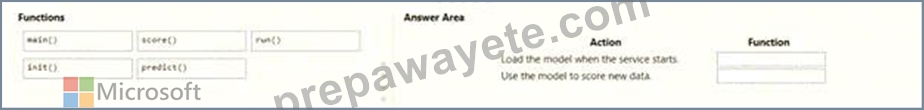
Answer:
Explanation:
Explanation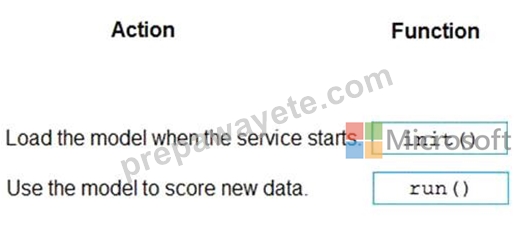
Box 1: init()
The entry script has only two required functions, init() and run(data). These functions are used to initialize the service at startup and run the model using request data passed in by a client. The rest of the script handles loading and running the model(s).
Box 2: run()
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-deploy-existing-model
NEW QUESTION # 277
......
As the saying goes, time is the most precious wealth of all wealth. If you abandon the time, the time also abandons you. So it is also vital that we should try our best to save our time, including spend less time on preparing for exam. Our Designing and Implementing a Data Science Solution on Azure guide torrent will be the best choice for you to save your time. Because our products are designed by a lot of experts and professors in different area, our DP-100 exam questions can promise twenty to thirty hours for preparing for the exam. If you decide to buy our DP-100 Test Guide, which means you just need to spend twenty to thirty hours before you take your exam. By our DP-100 exam questions, you will spend less time on preparing for exam, which means you will have more spare time to do other thing. So do not hesitate and buy our Designing and Implementing a Data Science Solution on Azure guide torrent.
DP-100 Exam Format: https://www.prepawayete.com/Microsoft/DP-100-practice-exam-dumps.html
2026 Latest PrepAwayETE DP-100 PDF Dumps and DP-100 Exam Engine Free Share: https://drive.google.com/open?id=1nQT3MCZSx5u5874q5Xba6aN2Hn86GEam