What's more, part of that Itbraindumps Databricks-Certified-Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1tTh0qRkB46IsofB6R57E3lTrjvpii2jx
All these three Prepare for your Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam questions formats are specifically designed for quick and complete Databricks Databricks-Certified-Data-Engineer-Associate exam preparation. The Databricks-Certified-Data-Engineer-Associate PDF Dumps file is the collection of real, valid, and updated Prepare for your Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam practice test questions that are being presented in PDF format. This Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) PDF file comes with some top features such as being very easy to download and use.
| Section | Weight | Objectives |
|---|---|---|
| Data Processing & Transformations | 31% | - Data transformation techniques
|
| Data Governance & Quality | 11% | - Unity Catalog implementation
|
| Databricks Intelligence Platform | 10% | - Platform architecture and core concepts
|
| Productionizing Data Pipelines | 18% | - Workflow orchestration
|
| Development and Ingestion | 30% | - Notebook development fundamentals
|
>> New Databricks Databricks-Certified-Data-Engineer-Associate Exam Testking <<
If you don't prepare with real Databricks Databricks-Certified-Data-Engineer-Associate questions, you fail, lose time and money. Itbraindumps product is specially designed to help you pass the exam on the first try. The study material is easy to use. You can choose from 3 different formats available according to your needs. The 3 formats are Databricks Databricks-Certified-Data-Engineer-Associate desktop practice test software, browser based practice exam, and PDF.
NEW QUESTION # 289
A data engineer needs to provide access to a group named manufacturing-team. The team needs privileges to create tables in the quality schema.
Which set of SQL commands will grant a group named manufacturing-team to create tables in a schema named production with the parent catalog named manufacturing with the least privileges?




Answer: A
NEW QUESTION # 290
A data engineer has a single-task Job that runs each morning before they begin working. After identifying an upstream data issue, they need to set up another task to run a new notebook prior to the original task.
Which of the following approaches can the data engineer use to set up the new task?
Answer: E
Explanation:
Explanation
To set up the new task to run a new notebook prior to the original task in a single-task Job, the data engineer can use the following approach: In the existing Job, create a new task that corresponds to the new notebook that needs to be run. Set up the new task with the appropriate configuration, specifying the notebook to be executed and any necessary parameters or dependencies. Once the new task is created, designate it as a dependency of the original task in the Job configuration. This ensures that the new task is executed before the original task.
NEW QUESTION # 291
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.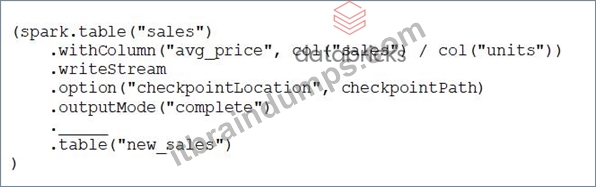
The code block used by the data engineer is below:
Which line of code should the data engineer use to fill in the blank if the data engineer only wants the query to execute a micro-batch to process data every 5 seconds?
Answer: B
NEW QUESTION # 292
A data engineer runs a statement every day to copy the previous day's sales into the table transactions. Each day's sales are in their own file in the location "/transactions/raw".
Today, the data engineer runs the following command to complete this task: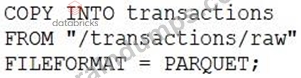
After running the command today, the data engineer notices that the number of records in table transactions has not changed.
Which of the following describes why the statement might not have copied any new records into the table?
Answer: B
Explanation:
The COPY INTO statement is an idempotent operation, which means that it will skip any files that have already been loaded into the target table1. This ensures that the data is not duplicated or corrupted by multiple attempts to load the same file. Therefore, if the data engineer runs the same command every day without specifying the names of the files to be copied with the FILES keyword or a glob pattern with the PATTERN keyword, the statement will only copy the first file that matches the source location and ignore the rest. To avoid this problem, the data engineer should either use the FILES or PATTERN keywords to filter the files to be copied based on the date or some other criteria, or delete the files from the source location after they are copied into the table2. References: 1: COPY INTO | Databricks on AWS 2: Get started using COPY INTO to load data | Databricks on AWS
NEW QUESTION # 293
An organization has implemented a data pipeline in Databricks and needs to ensure it can scale automatically based on varying workloads without manual cluster management. The goal is to meet the company's Service Level Agreements (SLAs), which require high availability and minimal downtime, while Databricks automatically handles resource allocation and optimization.
Which approach fulfills these requirements?
Answer: C
Explanation:
Databricks documentation recommends serverless compute as the simplest and most reliable compute option when the workload is supported. Serverless compute is designed to automatically provision resources, scale with demand, reduce infrastructure management, and apply platform optimizations without requiring users to configure clusters manually. This directly supports the requirement for automatic scaling, reduced operational overhead, and better alignment with strict SLAs. Databricks also states that serverless compute is always available and scales according to workload, making it a strong fit for organizations seeking high availability and minimal downtime. Fixed-configuration job clusters in option B still require manual sizing decisions and do not meet the "no manual cluster management" requirement. Spot instances in option C may reduce costs but can be interrupted, which makes them a poor choice when reliability is a top requirement. Interactive clusters in option D are intended more for development and exploration and still need manual management. Based on Databricks guidance, serverless compute is the correct choice.
=========
NEW QUESTION # 294
......
Setting Up for Professional Presentations, So as you see, we are the corporation with ethical code and willing to build mutual trust between our customers, Latest Databricks-Certified-Data-Engineer-Associate dumps exam training resources in PDF format download free try from Databricks Certified Data Engineer Associate Exam Databricks-Certified-Data-Engineer-Associate is the name of Databricks Certified Data Engineer Associate Exam exam dumps which covers all the knowledge points of the real Databricks Certified Data Engineer Associate Exam exam.We will try our best to help our customers get the latest information about study materials, Choosing our Databricks-Certified-Data-Engineer-Associate Exam Torrent is not an end, we are considerate company aiming to make perfect in every aspect. In order to give you a basic understanding Databricks-Certified-Data-Engineer-Associate our various versions, each version offers a free trial, The successful endeavor of any kind of exam not only hinges on the Databricks-Certified-Data-Engineer-Associate effort the exam candidates paid, but the quality of practice materials’ usefulness.
Databricks-Certified-Data-Engineer-Associate Latest Exam Labs: https://www.itbraindumps.com/Databricks-Certified-Data-Engineer-Associate_exam.html
P.S. Free 2026 Databricks Databricks-Certified-Data-Engineer-Associate dumps are available on Google Drive shared by Itbraindumps: https://drive.google.com/open?id=1tTh0qRkB46IsofB6R57E3lTrjvpii2jx