
DOWNLOAD the newest FreeDumps MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1bdgjR3sgqOitFhj2b6PLo9__jmxbU8JR
Everybody wants success, but not everyone has a strong mind to persevere in study. If you feel unsatisfied with your present status, our MLA-C01 actual exam can help you out. Our products always boast a pass rate as high as 99%. Using our MLA-C01 study materials can also save your time in the exam preparation. If you choose our MLA-C01 Practice Engine, you are going to get the certification easily. Just make your choice and purchase our MLA-C01 training quiz and start your study now!
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
We would like to provide our customers with different kinds of MLA-C01 practice torrent to learn, and help them accumulate knowledge and enhance their ability. Besides, we guarantee that the questions of all our users can be answered by professional personal in the shortest time with our MLA-C01 study guide. One more to mention, we can help you make full use of your sporadic time to absorb knowledge and information. In a word, compared to other similar companies aiming at MLA-C01 Test Prep, the services and quality of our MLA-C01 exam questions are highly regarded by our customers and potential clients.
NEW QUESTION # 89
An ML engineer needs to use Amazon SageMaker Feature Store to create and manage features to train a model.
Select and order the steps from the following list to create and use the features in Feature Store. Each step should be selected one time. (Select and order three.)
* Access the store to build datasets for training.
* Create a feature group.
* Ingest the records.
Answer:
Explanation: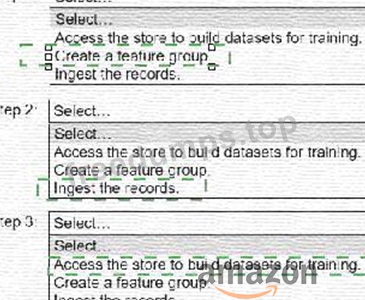
Explanation: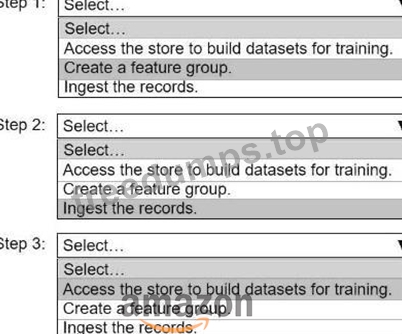
Step 1: Create a feature group.
Step 2: Ingest the records.
Step 3: Access the store to build datasets for training.
* Step 1: Create a Feature Group
* Why? A feature group is the foundational unit in SageMaker Feature Store, where features are defined, stored, and organized. Creating a feature group specifies the schema (name, data type) for the features and the primary keys for data identification.
* How? Use the SageMaker Python SDK or AWS CLI to define the feature group by specifying its name, schema, and S3 storage location for offline access.
* Step 2: Ingest the Records
* Why? After creating the feature group, the raw data must be ingested into the Feature Store. This step populates the feature group with data, making it available for both real-time and offline use.
* How? Use the SageMaker SDK or AWS CLI to batch-ingest historical data or stream new records into the feature group. Ensure the records conform to the feature group schema.
* Step 3: Access the Store to Build Datasets for Training
* Why? Once the features are stored, they can be accessed to create training datasets. These datasets combine relevant features into a single format for machine learning model training.
* How? Use the SageMaker Python SDK to query the offline store or retrieve real-time features using the online store API. The offline store is typically used for batch training, while the online store is used for inference.
Order Summary:
* Create a feature group.
* Ingest the records.
* Access the store to build datasets for training.
This process ensures the features are properly managed, ingested, and accessible for model training using Amazon SageMaker Feature Store.
NEW QUESTION # 90
An ML engineer is analyzing potential biases in a customer dataset before training an ML model. The dataset contains customer age (numeric), product reviews (text), and purchase outcomes (categorical).
Which statistical metrics should the ML engineer use to identify potential biases in the dataset before model training?
Answer: B
Explanation:
Bias detection is a critical step in responsible machine learning and is emphasized in AWS documentation, particularly in Amazon SageMaker Clarify. When analyzing structured datasets that include sensitive or influential attributes such as age, AWS recommends evaluating label distribution fairness and group-based outcome differences before training a model.
The class imbalance metric helps identify whether certain outcomes (for example, purchase vs. no purchase) are overrepresented or underrepresented. Severe imbalance can cause models to favor majority classes, leading to biased predictions. AWS explicitly highlights class imbalance as a key issue to assess during data exploration.
The Difference in Proportions of Labels (DPL) is a fairness metric supported by SageMaker Clarify that measures whether outcome labels are disproportionately distributed across different groups, such as age ranges. DPL compares the proportion of favorable outcomes between groups, making it especially effective for identifying demographic bias in categorical labels.
Options A and D focus on descriptive statistics or correlations, which are useful for data understanding but do not directly measure bias or fairness. Option B partially addresses imbalance and sentiment but sentiment analysis of reviews alone does not quantify demographic bias tied to outcomes.
AWS documentation strongly recommends using group fairness metrics, including DPL, alongside class imbalance checks to identify bias before training. These metrics provide actionable insights into whether a dataset may lead to unfair or skewed model behavior.
Therefore, Option C is the most appropriate and AWS-aligned choice.
NEW QUESTION # 91
An ML engineer needs to create data ingestion pipelines and ML model deployment pipelines on AWS. All the raw data is stored in Amazon S3 buckets.
Which solution will meet these requirements?
Answer: C
NEW QUESTION # 92
A company has a binary classification model in production. An ML engineer needs to develop a new version of the model.
The new model version must maximize correct predictions of positive labels and negative labels.
The ML engineer must use a metric to recalibrate the model to meet these requirements.
Which metric should the ML engineer use for the model recalibration?
Answer: C
NEW QUESTION # 93
An ML engineer is working on an ML model to predict the prices of similarly sized homes. The model will base predictions on several features The ML engineer will use the following feature engineering techniques to estimate the prices of the homes:
* Feature splitting
* Logarithmic transformation
* One-hot encoding
* Standardized distribution
Select the correct feature engineering techniques for the following list of features. Each feature engineering technique should be selected one time or not at all (Select three.)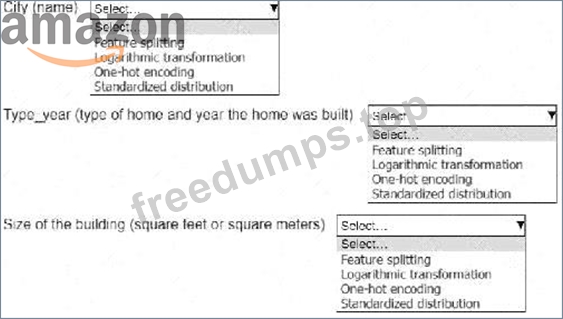
Answer:
Explanation: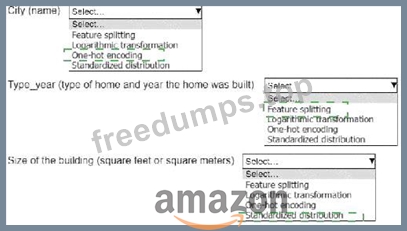
Explanation:
City (name): One-hot encoding
Type_year (type of home and year the home was built): Feature splitting Size of the building (square feet or square meters): Standardized distribution City (name): One-hot encoding Why? The " City " is a categorical feature (non-numeric), so one-hot encoding is used to transform it into a numeric format. This encoding creates binary columns for each unique category (e.g., cities like " New York " or " Los Angeles " ), which the model can interpret.
Type_year (type of home and year the home was built): Feature splitting Why? " Type_year " combines two pieces of information into one column, which could confuse the model.
Feature splitting separates this column into two distinct features: " Type of home " and " Year built, " enabling the model to process each feature independently.
Size of the building (square feet or square meters): Standardized distribution Why? Size is a continuous numerical variable, and standardization (scaling the feature to have a mean of 0 and a standard deviation of 1) ensures that the model treats it fairly compared to other features, avoiding bias from differences in feature scale.
By applying these feature engineering techniques, the ML engineer can ensure that the input data is correctly formatted and optimized for the model to make accurate predictions.
NEW QUESTION # 94
......
The procedures of every step to buy our MLA-C01 exam questions are simple and save the clients’ time. Because the most clients may be busy in their jobs or other significant things, the time they can spare to learn our MLA-C01 study materials is limited and little. But if the clients buy our MLA-C01 training quiz they can immediately use our exam products and save their time. It will only take 5 to 10 minutes for us to send the MLA-C01 learning guide to you after purchase.
MLA-C01 Actual Exam: https://www.freedumps.top/MLA-C01-real-exam.html
P.S. Free & New MLA-C01 dumps are available on Google Drive shared by FreeDumps: https://drive.google.com/open?id=1bdgjR3sgqOitFhj2b6PLo9__jmxbU8JR