그 외, PassTIP Databricks-Generative-AI-Engineer-Associate 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=1qKE9gjiYWFdU623waqzg2xlP-qZ95P4q
꿈을 안고 사는 인생이 멋진 인생입니다. 고객님의 최근의 꿈은 승진이나 연봉인상이 아닐가 싶습니다. Databricks인증 Databricks-Generative-AI-Engineer-Associate시험은 IT인증시험중 가장 인기있는 국제승인 자격증을 취득하는데서의 필수시험과목입니다.그만큼 시험문제가 어려워 시험도전할 용기가 없다구요? 이제 이런 걱정은 버리셔도 됩니다. PassTIP의 Databricks인증 Databricks-Generative-AI-Engineer-Associate덤프는Databricks인증 Databricks-Generative-AI-Engineer-Associate시험에 대비한 공부자료로서 시험적중율 100%입니다.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
| 주제 4 |
|
| 주제 5 |
|
>> Databricks Databricks-Generative-AI-Engineer-Associate합격보장 가능 덤프자료 <<
PassTIP Databricks인증Databricks-Generative-AI-Engineer-Associate시험덤프 구매전 구매사이트에서 무료샘플을 다운받아 PDF버전 덤프내용을 우선 체험해보실수 있습니다. 무료샘플을 보시면PassTIP Databricks인증Databricks-Generative-AI-Engineer-Associate시험대비자료에 믿음이 갈것입니다.고객님의 이익을 보장해드리기 위하여PassTIP는 시험불합격시 덤프비용전액환불을 무조건 약속합니다. PassTIP의 도움으로 더욱 많은 분들이 멋진 IT전문가로 거듭나기를 바라는바입니다.
질문 # 16
A company has a typical RAG-enabled, customer-facing chatbot on its website.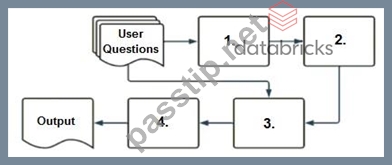
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
정답:C
설명:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
Embedding Model (1):
The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
Vector Search (2):
The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
Context-Augmented Prompt (3):
The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
Response-Generating LLM (4):
Finally, the context-augmented prompt is fed into a response-generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence is embedding model, vector search, context-augmented prompt, response-generating LLM, which is option A.
질문 # 17
A Generative Al Engineer is working with a retail company that wants to enhance its customer experience by automatically handling common customer inquiries. They are working on an LLM-powered Al solution that should improve response times while maintaining a personalized interaction. They want to define the appropriate input and LLM task to do this.
Which input/output pair will do this?
정답:D
설명:
The task described in the question involves enhancing customer experience by automatically handling common customer inquiries using an LLM-powered AI solution. This requires the system to process input data (customer inquiries) and generate personalized, relevant responses efficiently. Let's evaluate the options step-by-step in the context of Databricks Generative AI Engineer principles, which emphasize leveraging LLMs for tasks like question answering, summarization, and retrieval-augmented generation (RAG).
* Option A: Input: Customer reviews; Output: Group the reviews by users and aggregate per-user average rating, then respond
* This option focuses on analyzing customer reviews to compute average ratings per user. While this might be useful for sentiment analysis or user profiling, it does not directly address the goal of handling common customer inquiries or improving response times for personalized interactions. Customer reviews are typically feedback data, not real-time inquiries requiring immediate responses.
* Databricks Reference: Databricks documentation on LLMs (e.g., "Building LLM Applications with Databricks") emphasizes that LLMs excel at tasks like question answering and conversational responses, not just aggregation or statistical analysis of reviews.
* Option B: Input: Customer service chat logs; Output: Group the chat logs by users, followed by summarizing each user's interactions, then respond
* This option uses chat logs as input, which aligns with customer service scenarios. However, the output-grouping by users and summarizing interactions-focuses on user-specific summaries rather than directly addressing inquiries. While summarization is an LLM capability, this approach lacks the specificity of finding answers to common questions, which is central to the problem.
* Databricks Reference: Per Databricks' "Generative AI Cookbook," LLMs can summarize text, but for customer service, the emphasis is on retrieval and response generation (e.g., RAG workflows) rather than user interaction summaries alone.
* Option C: Input: Customer service chat logs; Output: Find the answers to similar questions and respond with a summary
* This option uses chat logs (real customer inquiries) as input and tasks the LLM with identifying answers to similar questions, then providing a summarized response. This directly aligns with the goal of handling common inquiries efficiently while maintaining personalization (by referencing past interactions or similar cases). It leverages LLM capabilities like semantic search, retrieval, and response generation, which are core to Databricks' LLM workflows.
* Databricks Reference: From Databricks documentation ("Building LLM-Powered Applications," 2023), an exact extract states:"For customer support use cases, LLMs can be used to retrieve relevant answers from historical data like chat logs and generate concise, contextually appropriate responses."This matches Option C's approach of finding answers and summarizing them.
* Option D: Input: Customer reviews; Output: Classify review sentiment
* This option focuses on sentiment classification of reviews, which is a valid LLM task but unrelated to handling customer inquiries or improving response times in a conversational context.
It's more suited for feedback analysis than real-time customer service.
* Databricks Reference: Databricks' "Generative AI Engineer Guide" notes that sentiment analysis is a common LLM task, but it's not highlighted for real-time conversational applications like customer support.
Conclusion: Option C is the best fit because it uses relevant input (chat logs) and defines an LLM task (finding answers and summarizing) that meets the requirements of improving response times and maintaining personalized interaction. This aligns with Databricks' recommended practices for LLM-powered customer service solutions, such as retrieval-augmented generation (RAG) workflows.
질문 # 18
A Generative AI Engineer is experimenting with using parameters to configure an agent in Mosaic Agent Framework. However, they are struggling to get the agent to respond with relevant information with this configuration:
config = { " prompt_template " : " You are a trivia bot. Generate a question based on the user ' s input:
{user_input} " , " input_vars " : [ " user_input " ], " parameters " : { " temperature " : 0.01, " max_tokens " :
500}}
Which error is causing the problem?
정답:B
설명:
In the Mosaic AI Agent Framework and underlying LangChain-based configurations, the " input_vars " or " input_variables " must be correctly mapped and referenced within the template. If the configuration dictionary identifies user_input as the variable but the logic executing the chain does not correctly " inject " the runtime value into the {user_input} placeholder, the LLM will receive a literal string (or an empty value) rather than the user ' s actual question. This results in the model failing to provide relevant information because it essentially doesn ' t know what the user asked. Engineering standards require ensuring that the key used in the input_vars list matches the key in the JSON payload sent to the model serving endpoint. If there is a mismatch or a failure to parse, the prompt remains static, leading to generic or irrelevant responses.
질문 # 19
A Generative Al Engineer is developing a RAG system for their company to perform internal document Q&A for structured HR policies, but the answers returned are frequently incomplete and unstructured It seems that the retriever is not returning all relevant context The Generative Al Engineer has experimented with different embedding and response generating LLMs but that did not improve results.
Which TWO options could be used to improve the response quality?
Choose 2 answers
정답:C,E
설명:
The problem describes a Retrieval-Augmented Generation (RAG) system for HR policy Q&A where responses are incomplete and unstructured due to the retriever failing to return sufficient context. The engineer has already tried different embedding and response-generating LLMs without success, suggesting the issue lies in the retrieval process-specifically, how documents are chunked and indexed. Let's evaluate the options.
* Option A: Add the section header as a prefix to chunks
* Adding section headers provides additional context to each chunk, helping the retriever understand the chunk's relevance within the document structure (e.g., "Leave Policy: Annual Leave" vs. just "Annual Leave"). This can improve retrieval precision for structured HR policies.
* Databricks Reference:"Metadata, such as section headers, can be appended to chunks to enhance retrieval accuracy in RAG systems"("Databricks Generative AI Cookbook," 2023).
* Option B: Increase the document chunk size
* Larger chunks include more context per retrieval, reducing the chance of missing relevant information split across smaller chunks. For structured HR policies, this can ensure entire sections or rules are retrieved together.
* Databricks Reference:"Increasing chunk size can improve context completeness, though it may trade off with retrieval specificity"("Building LLM Applications with Databricks").
* Option C: Split the document by sentence
* Splitting by sentence creates very small chunks, which could exacerbate the problem by fragmenting context further. This is likely why the current system fails-it retrieves incomplete snippets rather than cohesive policy sections.
* Databricks Reference: No specific extract opposes this, but the emphasis on context completeness in RAG suggests smaller chunks worsen incomplete responses.
* Option D: Use a larger embedding model
* A larger embedding model might improve vector quality, but the question states that experimenting with different embedding models didn't help. This suggests the issue isn't embedding quality but rather chunking/retrieval strategy.
* Databricks Reference: Embedding models are critical, but not the focus when retrieval context is the bottleneck.
* Option E: Fine tune the response generation model
* Fine-tuning the LLM could improve response coherence, but if the retriever doesn't provide complete context, the LLM can't generate full answers. The root issue is retrieval, not generation.
* Databricks Reference: Fine-tuning is recommended for domain-specific generation, not retrieval fixes ("Generative AI Engineer Guide").
Conclusion: Options A and B address the retrieval issue directly by enhancing chunk context-either through metadata (A) or size (B)-aligning with Databricks' RAG optimization strategies. C would worsen the problem, while D and E don't target the root cause given prior experimentation.
질문 # 20
A company has a typical RAG-enabled, customer-facing chatbot on its website.
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
정답:C
설명:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1):The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2):The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3):The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4):Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
* B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence isembedding model, vector search, context-augmented prompt, response- generating LLM, which is option A.
질문 # 21
......
꿈을 안고 사는 인생이 멋진 인생입니다. 고객님의 최근의 꿈은 승진이나 연봉인상이 아닐가 싶습니다. Databricks인증 Databricks-Generative-AI-Engineer-Associate시험은 IT인증시험중 가장 인기있는 국제승인 자격증을 취득하는데서의 필수시험과목입니다.그만큼 시험문제가 어려워 시험도전할 용기가 없다구요? 이제 이런 걱정은 버리셔도 됩니다. PassTIP의 Databricks인증 Databricks-Generative-AI-Engineer-Associate덤프는Databricks인증 Databricks-Generative-AI-Engineer-Associate시험에 대비한 공부자료로서 시험적중율 100%입니다.
Databricks-Generative-AI-Engineer-Associate합격보장 가능 공부: https://www.passtip.net/Databricks-Generative-AI-Engineer-Associate-pass-exam.html
2026 PassTIP 최신 Databricks-Generative-AI-Engineer-Associate PDF 버전 시험 문제집과 Databricks-Generative-AI-Engineer-Associate 시험 문제 및 답변 무료 공유: https://drive.google.com/open?id=1qKE9gjiYWFdU623waqzg2xlP-qZ95P4q