Fast2test를 선택함으로 여러분은 Microsoft 인증DP-750시험에 대한 부담은 사라질 것입니다.우리 Fast2test는 끊임없는 업데이트로 항상 최신버전의 Microsoft 인증DP-750시험덤프임을 보장해드립니다.만약 덤프품질을 확인하고 싶다면Fast2test 에서 무료로 제공되는Microsoft 인증DP-750덤프의 일부분 문제를 체험하시면 됩니다.Fast2test 는 100%의 보장도를 자랑하며Microsoft 인증DP-750시험을 한번에 패스하도록 도와드립니다.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Topic 2: Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Topic 3: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Topic 4: Prepare and process data | 30-35% | - Data quality and validation
|
Microsoft인증 DP-750시험이 너무 어려워 보여서 오르지못할 산처럼 보이시나요? 그건Fast2test의 Microsoft인증 DP-750시험문제에 대비하여 제작한Microsoft인증 DP-750덤프가 있다는 것을 모르고 있기때문입니다. Microsoft인증 DP-750시험에 도전하고 싶으시다면 최강 시험패스율로 유명한Fast2test의 Microsoft인증 DP-750덤프로 시험공부를 해보세요.시간절약은 물론이고 가격도 착해서 간단한 시험패스에 딱 좋은 선택입니다.
질문 # 74
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You need to configure Cluster1 to meet the following requirements:
- The cluster must scale up automatically when workloads increase.
- The cluster must scale down automatically when workloads decrease.
The solution must minimize costs.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
정답:A,B
설명:
Enabling autoscaling and setting a 30-minute auto-termination timeout is the correct configuration to meet the goals.
Autoscaling handles fluctuating workloads, while auto-termination prevents you from paying for idle compute resources.
Dynamic Scaling: Autoscaling automatically adds workers during high loads and removes them when demand drops.
Cost Control: The 30-minute termination window ensures the cluster shuts down completely if no jobs are running, stopping all compute charges.
Reference:
https://community.databricks.com/t5/get-started-discussions/cluster-auto-termination-best- practices/td-p/75826
질문 # 75
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Tabid.
Table! is written by batch jobs every hour and is queried frequently by filtering two columns named Customerld and EventDate.
You expect Table1 to grow significantly over time.
The rows in Table1 are frequently updated and deleted to support compliance requests.
You need to keep query performance consistent as Table1 grows. The solution must minimize update and deletion effort.
What should you include in the solution? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.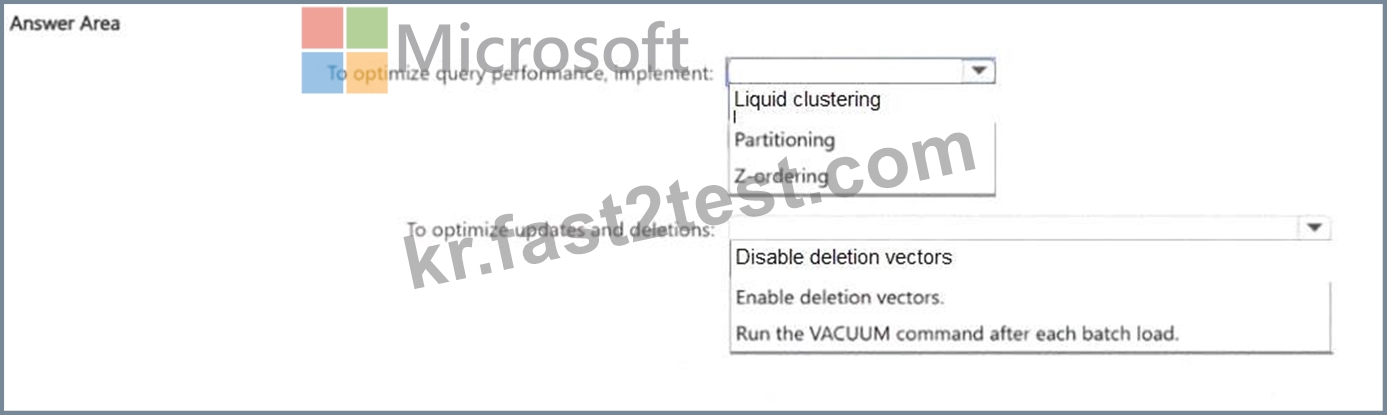
정답:
설명: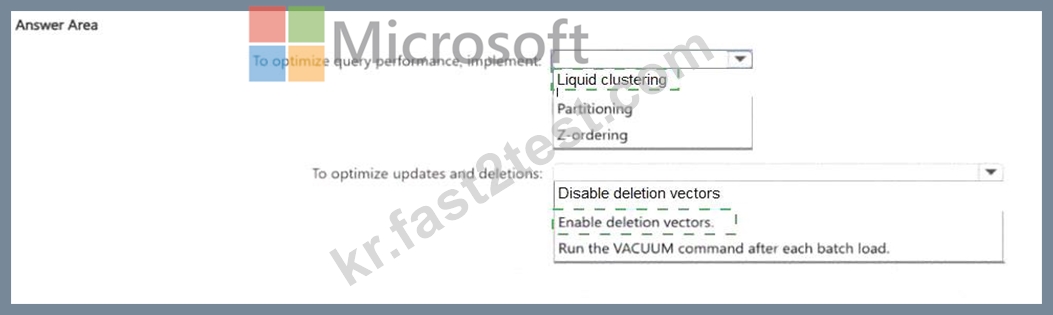
Explanation:
Two features work together to keep performance consistent and update costs low:
OPTIMIZE with ZORDER BY (CustomerId, EventDate). Z-Ordering co-locates rows with the same CustomerId and EventDate values in the same Parquet files. When a query filters on those columns, the Delta engine uses file statistics to skip files that can't possibly contain matching rows (data skipping). As the table grows, skipping scales proportionally - query time stays consistent.
Deletion Vectors (delta.enableDeletionVectors = true). When a row is updated or deleted, instead of rewriting the entire Parquet file, Delta marks the affected row in a small companion deletion vector file. This dramatically reduces write amplification for the frequent compliance-driven updates and deletions the question describes. Actual file rewrites are deferred to the next OPTIMIZE run.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/data-skipping
질문 # 76
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1. Job1 contains multiple tasks.
Failures of non-critical tasks must be logged but must NOT trigger notifications. Notifications must be triggered only when critical tasks have failed, and Job1 has completed You need to configure the job alerting behavior.
What should trigger a notification?
정답:B
설명:
The correct answer is B - a job failure.
The requirement draws a clear line: non-critical task failures should be logged silently; notifications should only fire when a critical failure causes the whole job to stop. Configuring the alert on ' Job Failure ' achieves this precisely - the notification triggers when the job itself reaches a Failed terminal state, which only happens when at least one critical task has failed and the job cannot complete.
Option A (task failure) would send a notification for every task-level failure, including non-critical ones. That
' s exactly the noise the question wants to avoid. Option C (job success) would never alert on failures at all.
Option D (task success) confirms completion but doesn ' t catch failures.
Setting alerting at the job level rather than the task level is also simpler to configure - you don ' t need to mark individual tasks as critical or non-critical in the notification settings.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/alerts
질문 # 77
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Payments.
Payments stores transaction data and contains a column named payment_amount of the Decimal data type.
You must enforce the following business rule:
payment_amount must be between 0 and 10,000, inclusive
You need to ensure that records that violate the rule are rejected when data is written to the Payments table.
What should you do?
정답:B
설명:
A CHECK constraint enforces a Boolean condition whenever data is inserted or updated. The constraint can require payment_amount > = 0 AND payment_amount < = 10000, causing a transaction containing an invalid value to fail instead of allowing the record into Payments. This provides storage-level data-quality enforcement regardless of which pipeline, notebook, or SQL statement performs the write. Row-level security controls which existing records users can see; it does not reject invalid writes. SELECT statements filter results only when they are executed and therefore cannot protect the underlying table. Table update triggers are not the standard Delta Lake mechanism for this requirement. Azure Databricks classifies CHECK constraints as enforced constraints and rejects transactions when their conditions are violated. Microsoft Learn
질문 # 78
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2. You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.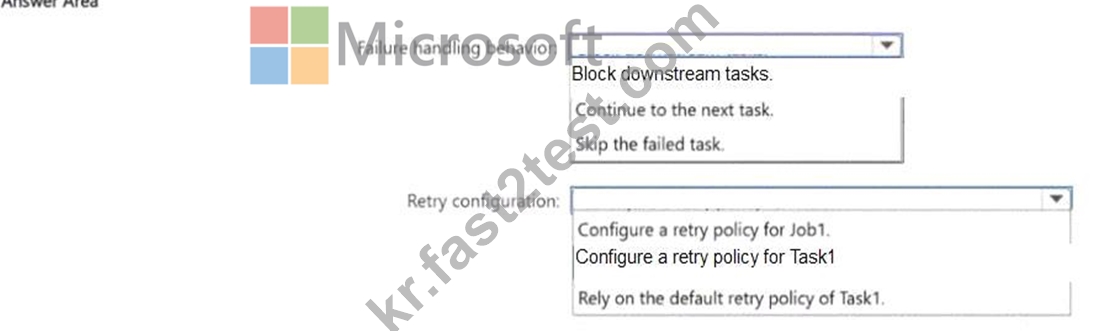
정답:
설명: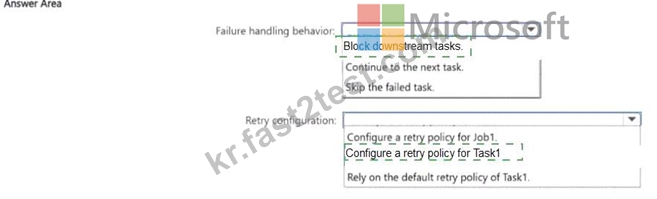
Explanation:
Two task-level settings solve this:
Task1 retry policy: configure Task1 with a maximum number of retries and a retry interval. When Task1 fails, Lakeflow Jobs automatically re-runs it up to the retry limit without any manual intervention. This handles transient infrastructure failures transparently.
Task2 run condition set to ' All succeeded ' with Task1 as its dependency: this means Task2 only starts when Task1 has succeeded. If Task1 fails and exhausts all retries, Task2 remains blocked - it never runs on data from a failed upstream ingestion. The dependency is declared in Task2 ' s ' Depends on ' setting in the job configuration.
These two settings are independent and composable. Task1 ' s retry policy gives it multiple chances to recover. Task2 ' s dependency and run condition ensure the downstream transformation only runs on clean, successfully ingested data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#task-retries
질문 # 79
......
지금 같은 세대에 많은 분들이 IT업계에 관심을 가지고 있습니다. 이렇게 인재가 많은 사회에서 IT관련인사들은 아직도 적은 편입니다. 면접 시에도 IT인증 자격증유무를 많이들 봅니다. 때문에 IT자격증이 많은 인기를 누리고 있습니다.이런 살아가기 힘든 사회에서 이런 자격증들 또한 취득하기가 넘 어렵습니다.Microsoft DP-750인증시험 또한 아주 어려운 시험입니다. 많은 분들이 응시하지만 통과하는 분들은 아주 적습니다.
DP-750유효한 인증시험덤프: https://kr.fast2test.com/DP-750-premium-file.html