Microsoftご存知のように、競争の激しい世界では、JapancertのAI-300認定などのソフトパワーを向上させる以外に選択肢はありません。 あなたは転職の状態にあるかもしれませんが、あなた自身のキャリアを持つことは信じられないほど難しいです。 それからあなた自身を改善し、不可能な任務を可能にする方法はあなたの優先事項です。 Operationalizing Machine Learning and Generative AI Solutionsガイドトレントがあなたを助けてくれます。 AI-300質問トレントを使用してv試験に合格し、履歴書を強調することは非常に重要です。したがって、職場で成功を収めることができます。
| Section | Objectives |
|---|---|
| Topic 1: Operationalizing machine learning solutions | - ML lifecycle management
|
| Topic 2: Implement secure and scalable AI systems | - Security and governance
|
| Topic 3: Design and implement generative AI solutions | - RAG (Retrieval Augmented Generation) solutions
|
| Topic 4: Plan and design AI solutions using Azure AI services | - Responsible AI design
|
誰もが良い仕事とまともな収入を望んでいます。しかし、彼らが優れた能力と優れた主要な知識を持っていない場合、彼らはまともな仕事を見つけるのは難しいです。テストAI-300認定に合格すると、夢を実現し、満足のいく仕事を見つけることができます。 AI-300学習教材は、AI-300試験に簡単に合格するのに役立つ優れたツールです。時間をかけて学習する必要はありません。 AI-300試験ガイドは高品質であり、当社の製品を使用する場合、AI-300試験に合格する可能性は99%〜100%と非常に高くなっています。
質問 # 94
You have a deployment of an Azure OpenAI Service base model.
You plan to fine-tune the model.
You need to prepare a file that contains training data for multi-turn chat.
Which file encoding method should you use?
正解:D
解説:
UTF-8 is the universal encoding standard: it is backward-compatible with ASCII for standard Latin characters, supports every Unicode code point covering over 140,000 characters, and is the de facto standard for all modern APIs including Azure OpenAI. This matters for fine-tuning because training data often contains diverse characters from multiple languages, special punctuation, and domain-specific symbols. If they use ASCII encoding, any accented character or non-Latin script will be corrupted or lost entirely. UTF-
16 adds a Byte Order Mark and can cause parsing issues with tools that expect standard JSONL. ISO-8859-1 covers Western European characters only and fails immediately with CJK or Arabic scripts. The Azure OpenAI fine-tuning documentation explicitly states that training files must be UTF-8 encoded, making it the only safe choice.
Microsoft Learn Reference Topic: Azure OpenAI fine-tuning - File format and encoding requirements
質問 # 95
Drag and Drop Question
A team is deploying a new version of a customer scoring model to a production online endpoint in Azure Machine Learning.
The team must minimize risk by gradually introducing the new model version and ensuring that traffic can be reverted immediately if issues occur.
You need to roll out the new model according to the requirements.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.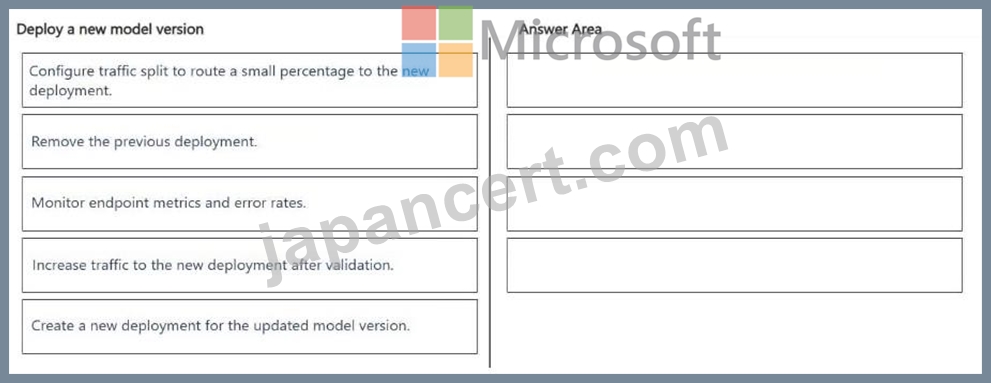
正解:
解説: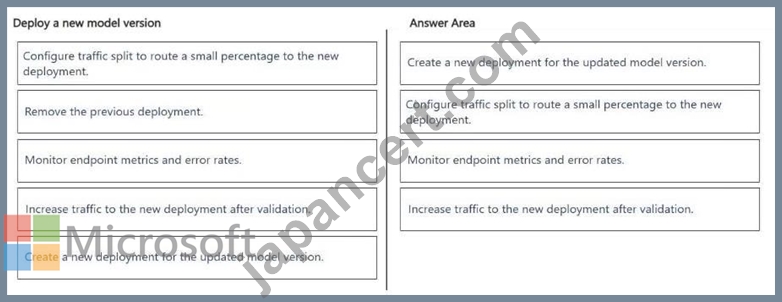
Explanation:
To safely deploy your new customer scoring model with minimal risk, you should use Azure Machine Learning managed online endpoints with a blue-green deployment strategy. This allows you to test the new model (green) alongside the old model (blue) and route traffic gradually.
Here is the step-by-step process to execute this rollout.
Step 1: Create a New Deployment for the updated model version.
1. Create a New Deployment under the Existing Endpoint
Do not overwrite your current production deployment. Instead, deploy the new model version as a separate deployment within the same managed online endpoint.
Keep the existing deployment (e.g., blue-deployment) running at 100% traffic.
Create the new deployment (e.g., green-deployment) with the new model version.
Set the initial traffic allocation for the new deployment to 0%.
2. Test the New Deployment in Isolation [Step not in this question]
Before exposing real customers to the new model, test its stability and performance in the production environment.
Send test scoring requests directly to the green-deployment.
Use the X-MS-Routing-Override: green-deployment HTTP header in your SDK or REST requests to bypass the traffic split and target the new model directly.
Verify that the data schema, latency, and prediction outputs match your expectations.
Step 2: Configure traffic split to route a small percentage to the new deployment.
3. Gradually Shift Traffic (Canary Testing)
Once internal testing passes, begin introducing real production traffic to the new model in phases.
3a. Update the endpoint's traffic configuration to route a small percentage (e.g., 10%) to green- deployment. [Step 2] Step 3: Monitor endpoint metrics and error rates.
3b) Monitor system metrics closely, looking for spikes in HTTP 4xx/5xx errors, timeouts, or unusual scoring distributions. [Step 3] Step 4: Increase traffic to the new deployment after validation
3c) If performance remains stable over a designated observation period, incrementally increase the traffic (e.g., to 30%, 50%, then 100%). [Step 4] Further future actions outside the context of the question:
4. Monitor App Insights and MetricsAzure ML integrates natively with Azure Monitor and Application Insights. Track these critical metrics during the shift:CPU/Memory Utilization: Ensure the new model does not exhaust container resources.
Model Latency: Compare the response times of the new deployment against the old one.
Tracking Token/Feature Drift: Ensure the live customer data matches the model's expected input feature distribution.
5. Instant Rollback Plan
If the new model causes errors, triggers high latency, or skews customer scores, you can revert traffic immediately.
Update the endpoint traffic settings to route 100% of traffic back to the original blue-deployment.
Set the green-deployment traffic to 0%.This configuration change takes effect almost instantly, isolating the faulty model without any downtime for your users.
Keep the green-deployment alive at 0% traffic while you pull the logs to investigate the root cause, then delete it once fixed.
Incorrect:
[Remove the previous deployment]
A step further in the future.
Reference:
https://chandras4bigdata.medium.com/mlops-interview-and-study-guide-489d13ff82fa
質問 # 96
A team manages an Azure Machine Learning workspace and deploys a model to an endpoint.
A deployed online endpoint shows inconsistent response times during periods of high traffic.
You need to identify potential performance degradation.
Which three metrics should you monitor? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point. Choose three
正解:B、D、E
解説:
During high traffic, the question is whether the endpoint is keeping up with demand. Requests per minute (B) tells you the actual request load on the endpoint, letting you correlate traffic spikes with degradation.
Connections active (C) reveals whether the endpoint ' s connection pool is saturating - too many concurrent connections without adequate scaling causes queuing and timeouts. Request latency (E) is the gold-standard measure of user-perceived performance; rising latency under load is the clearest signal of degradation. Feature count (A) is a model-design attribute, not a runtime performance metric. Dataset size (D) is a training-time concern unrelated to endpoint performance. Azure Machine Learning online endpoints expose these metrics through Azure Monitor, and Microsoft recommends configuring alert rules on latency and request rate thresholds for all production endpoints.
Microsoft Learn Reference Topic: Monitor Azure Machine Learning online endpoints - Azure Monitor metrics for managed endpoints
質問 # 97
Hotspot Question
You manage a Retrieval-Augmented Generation (RAG) system that uses Azure AI Search to retrieve documents from an indexed knowledge base.
The system must support the following retrieval requirements:
- Queries that include exact policy identifiers must return matching
documents even when semantic similarity is low.
- Natural-language questions must prioritize semantically relevant
documents even when keywords are not an exact match.
You need to configure the retrieval approach to meet the requirements.
How should you configure the retrieval behavior for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.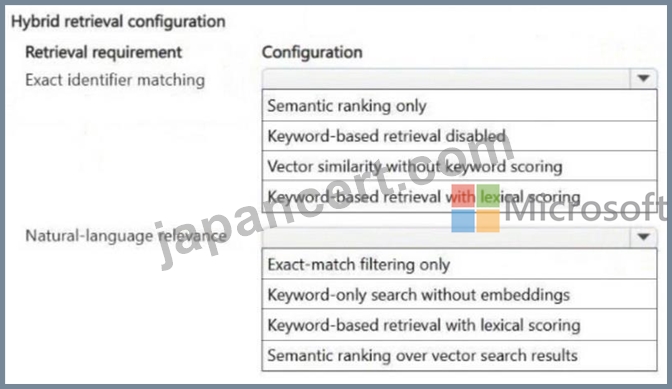
正解:
解説: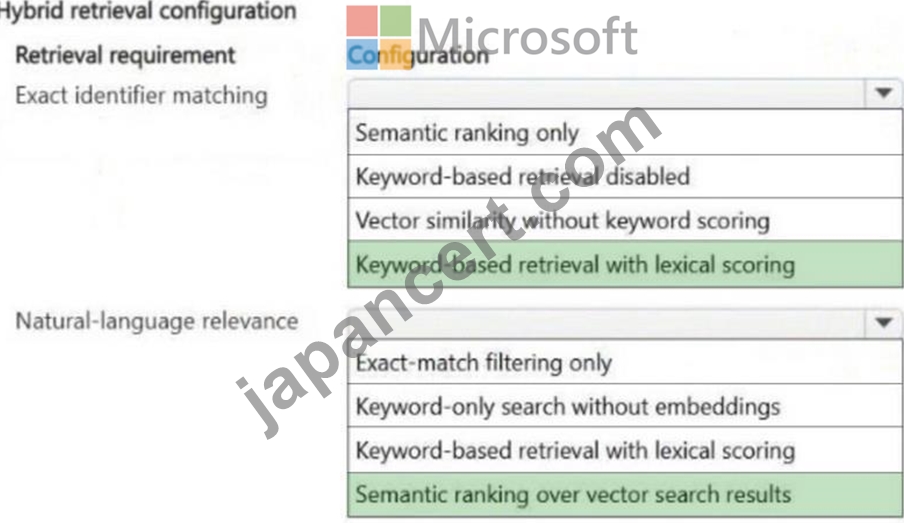
質問 # 98
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to refine a GPT-5 model so that its performance and behavior align with the technical and business requirements of Fabrikam Inc.
Which two Foundry strategies should you apply? Each correct answer presents a complete solution. Choose two.
NOTE: Each correct selection is worth one point.
正解:A、B
解説:
Scenario, Technical Requirements:
Improve RAG-based solution output quality.
Apply advanced fine-tuning techniques only when prompt engineering is insufficient Business Requirements:
Provide a conversational interface that answers analytics questions by using internal documents and datasets.
The two Foundry strategies that would be most useful in this scenario are Evaluations and Supervised fine-tuning.
Evaluations: This strategy is critical for improving RAG-based solution output quality. It provides systemic measurement to test how changes to your data, prompts, or retrieval chunks impact the accuracy, relevance, and groundedness of the model's answers before moving to more complex methods.
Supervised fine-tuning: This strategy directly satisfies the requirement to apply advanced fine- tuning techniques only when prompt engineering is insufficient. It allows you to deeply customize the model's behavior and conversational tone to fit your specific analytics interface requirements.
Incorrect:
Guardrails: While valuable for safety and compliance, guardrails focus on enforcing hard operational boundaries (e.g., blocking toxic content or preventing data leaks). They do not optimize RAG output quality or provide advanced behavioral updates when prompt engineering fails.
Synthetic data generation: While helpful for bootstrapping training datasets when real-world data is scarce, it is an data-preparation step rather than a core model refinement strategy designed to iteratively solve prompt engineering limitations or build conversational systems.
Reference:
https://medium.com/@hugoparreao/context-engineering-what-really-improves-the-performance-of-llms-0c0e3ed45c98
質問 # 99
......
JapancertのMicrosoftどのバージョンでも、Operationalizing Machine Learning and Generative AI Solutionsガイド資料はダウンロード数とAI-300同時ユーザー数に制限がないため、ユーザーは同じ質問セットで複数の演習を練習し、知識を繰り返し統合できます。 学習の過程で、Operationalizing Machine Learning and Generative AI Solutions実際の試験のテストエンジンは、学習プロセスの弱点を強化するのに便利です。 これは、間違ったAI-300質問を整理するプロセスの代替として使用できます
AI-300 PDF: https://www.japancert.com/AI-300.html