Our website aimed to helping you and fully supporting you to pass SPS-C01 actual test with high passing score in your first try. So we prepared top SPS-C01 pdf torrent including the valid questions and answers written by our certified professionals for you. Our SPS-C01 Practice Exam available in three modes, pdf files, and PC test engine and online test engine, which apply to any level of candidates.
| Section | Objectives |
|---|---|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Data Engineering with Snowpark | - Pipeline development
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Testing, Debugging, and Deployment | - Production readiness
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
>> Snowflake SPS-C01 Practical Information <<
You can pass your Snowflake SPS-C01 certification exam in less time, without wasting time and money on outdated or unreliable Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam study materials. Don't let fear or a lack of resources hold you back from achieving your goals, trust VCEDumps Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) practice test material and achieve the highest marks in your Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam.
NEW QUESTION # 280
You are tasked with optimizing a Snowpark application that uses a Python UDF to perform complex string manipulations on a large dataset. The current implementation uses a scalar UDF. You are considering converting it to a vectorized UDF. What are the key considerations and potential limitations you need to address during the conversion to ensure correctness and optimal performance? Choose all that apply:
Answer: A,C,E
Explanation:
A, B, and C are all crucial considerations. Vectorized UDFs need to handle NULLs, leverage efficient array processing libraries (while respecting package limitations), and maintain type compatibility and consistent array lengths. D is incorrect, as the performance benefit depends on the workload. For very small datasets or simple operations, the overhead of vectorization might outweigh the benefits. E is partially true. Data type compatability is needed, however, you can cast data type to ensure compatibility.
NEW QUESTION # 281
A data engineering team is building a Snowpark pipeline to process IoT sensor data'. They want to create a UDF that uses a 3rd-party Python library (not available in Snowflake's Anaconda channel) to analyze the sensor readings. The UDF needs to be efficiently deployed and managed within Snowflake. Which of the following approaches represents the MOST robust and scalable way to register and deploy this UDF using Snowpark?
Answer: B
Explanation:
Option B is the correct answer. It describes the best practice for deploying UDFs with external Python libraries in Snowflake. Creating a virtual environment, zipping it, uploading it to a stage, and referencing it during UDF registration ensures proper dependency management and avoids conflicts. Option A is problematic because embedding the library directly makes the UDF definition very large and unmanageable. Option C will not work if the required version isn't available. Option D is incorrect because functions.udf relies on packages available in the Snowflake Anaconda channel and doesn't manage custom packages. While Option E could work, its overly complex for this specific scenario compared to utilizing Snowpark virtual enviornment and stage management. Option B is more efficient and streamlined.
NEW QUESTION # 282
You are developing a Snowpark application to load data into a Snowflake table named 'SALES DATA. The DataFrame 'sales_df contains new sales records. You need to insert these records into 'SALES DATA. Which of the following Snowpark DataFrame methods will efficiently perform this operation, considering potential data type mismatches between the DataFrame and the target table? Assume no explicit schema definition is necessary.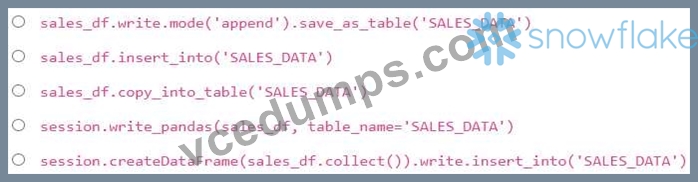
Answer: E
Explanation:
The method directly inserts the DataFrame's data into the specified Snowflake table. Snowpark implicitly handles data type conversions where possible. is generally for creating new tables. is for loading data from files in stages, and 'write_pandas' method requires pandas DataFrame and session object. Using is inefficient as it collects all the data into the driver and then inserts and can cause memory issues.
NEW QUESTION # 283
You are developing a Snowpark Python application that reads data from a Snowflake table, performs several transformations including filtering, aggregation, and joining with another DataFrame, and then writes the results back to a new table. You want to optimize the execution plan to minimize data movement and processing time. Which of the following strategies would be MOST effective in leveraging Snowpark's lazy evaluation capabilities to achieve this optimization?
Answer: D
Explanation:
Chaining transformations and delaying execution until the final action allows Snowpark to optimize the entire query plan. Caching the initial DataFrame might improve performance in some cases, but it can also introduce unnecessary materialization. Defining transformations in a single SQL query string bypasses Snowpark's optimization capabilities. Calling 'collect()' after each transformation defeats the purpose of lazy evaluation. Python multiprocessing does not directly interact with Snowpark's query optimization.
NEW QUESTION # 284
You are tasked with building a Snowpark application that receives a DataFrame 'new customers_df containing customer data'. Your application needs to insert this data into the 'CUSTOMERS' table in Snowflake. The 'CUSTOMERS table has columns 'CUSTOMER ONT), 'NAME' (VARCHAR), and 'JOIN DATE' (DATE). However, contains all columns as VARCHAR. Which of the following approaches ensures the correct data types are inserted into the 'CUSTOMERS' table, minimizing errors and maximizing performance? Assume the 'session' object is already defined and a valid connection exists.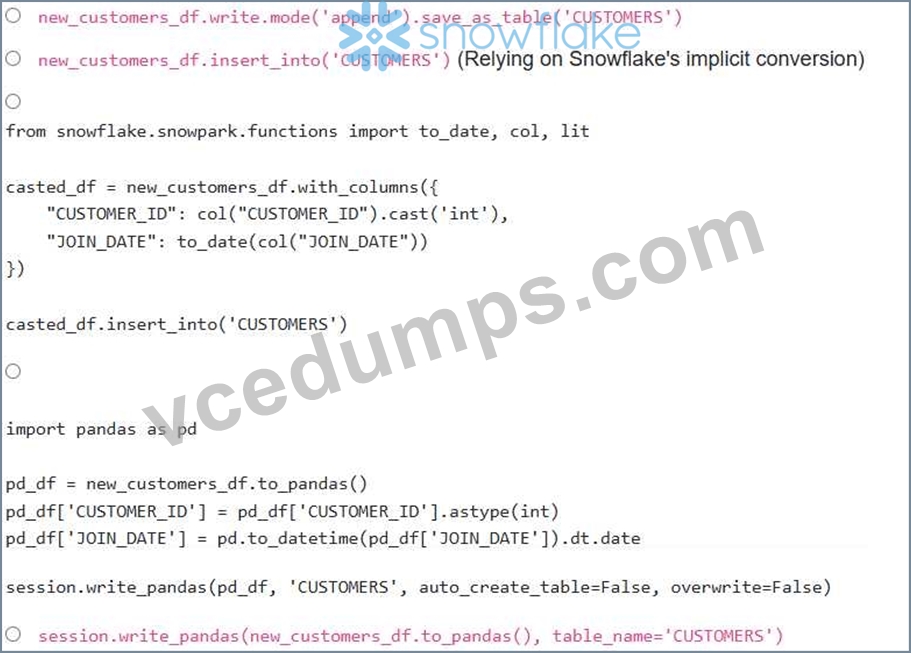
Answer: D
Explanation:
Option C provides explicit casting of the VARCHAR columns to their respective data types (INT and DATE) using Snowpark functions before inserting them into the 'CUSTOMERS' table. This approach ensures data type compatibility and prevents potential errors during the insertion process. Option A, while seemingly simple, might lead to data type mismatch errors if Snowflake cannot implicitly convert the VARCHAR values to INT and DATE. Option B relies on implicit conversion, which is risky. Option D, although it converts to pandas, performs the correct transformations. However, converting to a Pandas DataFrame and using session.write_pandas is less performant and not necessary when using Snowpark. Option E, does not do type conversions and assumes the dataframe is already in required format.
NEW QUESTION # 285
......
Our SPS-C01 learning guide is very efficient tool in the world. As is known to us, in our modern world, everyone is looking for to do things faster, better, smarter, so it is no wonder that productivity hacks are incredibly popular. So we must be aware of the importance of the study tool. In order to promote the learning efficiency of our customers, our SPS-C01 Training Materials were designed by a lot of experts from our company. Our SPS-C01 study materials will be very useful for all people to improve their learning efficiency.
Exam SPS-C01 Labs: https://www.vcedumps.com/SPS-C01-examcollection.html