DOWNLOAD the newest ValidVCE Databricks-Certified-Professional-Data-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=19MEwq-vssMc8F_yaOvsnMjjmn109mDsf
To make sure your situation of passing the certificate efficiently, our Databricks-Certified-Professional-Data-Engineer practice materials are compiled by first-rank experts. So the proficiency of our team is unquestionable. They help you review and stay on track without wasting your precious time on useless things. They handpicked what the Databricks-Certified-Professional-Data-Engineer Study Guide usually tested in exam recent years and devoted their knowledge accumulated into these Databricks-Certified-Professional-Data-Engineer actual tests.
| Section | Objectives |
|---|---|
| Security, Governance, Monitoring, and Optimization | - Cost optimization and performance tuning - Implement Unity Catalog governance and access control - Monitor and optimize Spark workloads |
| Data Ingestion and Transformation | - Handle batch and streaming data pipelines - Transform and clean datasets using Spark SQL and DataFrame APIs - Ingest data using Apache Spark and Databricks |
| Production Pipelines and Orchestration | - Automate ETL pipelines and scheduling - Build and manage workflows using Databricks Jobs - Pipeline reliability and fault tolerance |
| Data Modeling and Storage | - Design scalable data lakehouse architectures - Schema evolution and data partitioning strategies - Delta Lake table design and optimization |
>> Test Databricks-Certified-Professional-Data-Engineer Practice <<
With the company of our Databricks-Certified-Professional-Data-Engineer study dumps, you will find the direction of success. There is nothing more exciting than an effective and useful Databricks-Certified-Professional-Data-Engineer question bank to study with for your coming exam. The sooner you use Databricks-Certified-Professional-Data-Engineer Training Materials, the more chance you will pass the Databricks-Certified-Professional-Data-Engineer exam, and the earlier you get your certificate. You definitely have to have a try and you will be satisfied without doubt.
NEW QUESTION # 195
A data team's Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.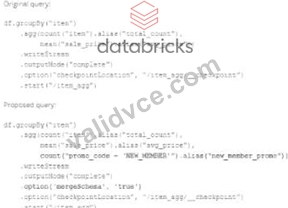
Which step must also be completed to put the proposed query into production?
Answer: D
Explanation:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
References:
* Databricks documentation on Structured Streaming:
https://docs.databricks.com/spark/latest/structured-streaming/index.html
* Databricks documentation on streaming checkpoints:
https://docs.databricks.com/spark/latest/structured-streaming/production.html#checkpointing
NEW QUESTION # 196
A new data engineer notices that a critical field was omitted from an application that writes its Kafka source to Delta Lake. This happened even though the critical field was in the Kafka source. That field was further missing from data written to dependent, long-term storage. The retention threshold on the Kafka service is seven days. The pipeline has been in production for three months.
Which describes how Delta Lake can help to avoid data loss of this nature in the future?
Answer: C
Explanation:
Explanation
This is the correct answer because it describes how Delta Lake can help to avoid data loss of this nature in the future. By ingesting all raw data and metadata from Kafka to a bronze Delta table, Delta Lake creates a permanent, replayable history of the data state that can be used for recovery or reprocessing in case of errors or omissions in downstream applications or pipelines. Delta Lake also supports schema evolution, which allows adding new columns to existing tables without affecting existing queries or pipelines. Therefore, if a critical field was omitted from an application that writes its Kafka source to Delta Lake, it can be easily added later and the data can be reprocessed from the bronze table without losing any information. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Delta Lake core features" section.
NEW QUESTION # 197
Assuming that the Databricks CLI has been installed and configured correctly, which Databricks CLI command can be used to upload a custom Python Wheel to object storage mounted with the DBFS for use with a production job?
Answer: E
Explanation:
Explanation
The libraries command group allows you to install, uninstall, and list libraries on Databricks clusters. You can use the libraries install command to install a custom Python Wheel on a cluster by specifying the --whl option and the path to the wheel file. For example, you can use the following command to install a custom Python Wheel named mylib-0.1-py3-none-any.whl on a cluster with the id 1234-567890-abcde123:
databricks libraries install --cluster-id 1234-567890-abcde123 --whl
dbfs:/mnt/mylib/mylib-0.1-py3-none-any.whl
This will upload the custom Python Wheel to the cluster and make it available for use with a production job.
You can also use the libraries uninstall command to uninstall a library from a cluster, and the libraries list command to list the libraries installed on a cluster.
References:
Libraries CLI (legacy): https://docs.databricks.com/en/archive/dev-tools/cli/libraries-cli.html Library operations: https://docs.databricks.com/en/dev-tools/cli/commands.html#library-operations Install or update the Databricks CLI: https://docs.databricks.com/en/dev-tools/cli/install.html
NEW QUESTION # 198
The data governance team has instituted a requirement that all tables containing Personal Identifiable Information (PH) must be clearly annotated. This includes adding column comments, table comments, and setting the custom table property"contains_pii" = true.
The following SQL DDL statement is executed to create a new table: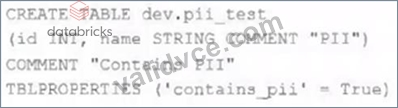
Which command allows manual confirmation that these three requirements have been met?
Answer: B
Explanation:
Explanation
This is the correct answer because it allows manual confirmation that these three requirements have been met.
The requirements are that all tables containing Personal Identifiable Information (PII) must be clearly annotated, which includes adding column comments, table comments, and setting the custom table property
"contains_pii" = true. The DESCRIBE EXTENDED command is used to display detailed information about a table, such as its schema, location, properties, and comments. By using this command on the dev.pii_test table, one can verify that the table has been created with the correct column comments, table comment, and custom table property as specified in the SQL DDL statement. Verified References: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "DESCRIBE EXTENDED" section.
NEW QUESTION # 199
Which of the following statements can successfully read the notebook widget and pass the python variable to a SQL statement in a Python notebook cell?
Answer: E
NEW QUESTION # 200
......
Simplified language allows candidates to see at a glance. With this purpose, our Databricks-Certified-Professional-Data-Engineer learning materials simplify the questions and answers in easy-to-understand language so that each candidate can understand the test information and master it at the first time, and they can pass the test at their first attempt. Our experts aim to deliver the most effective information in the simplest language. Each candidate takes only a few days can attend to the Databricks-Certified-Professional-Data-Engineer Exam. In addition, our Databricks-Certified-Professional-Data-Engineer Databricks-Certified-Professional-Data-Engineer provides end users with real questions and answers. We have been working hard to update the latest Databricks-Certified-Professional-Data-Engineer learning materials and provide all users with the correct Databricks-Certified-Professional-Data-Engineer answers. Therefore, our Databricks-Certified-Professional-Data-Engineer learning materials always meet your academic requirements.
Databricks-Certified-Professional-Data-Engineer Reliable Braindumps: https://www.validvce.com/Databricks-Certified-Professional-Data-Engineer-exam-collection.html
BONUS!!! Download part of ValidVCE Databricks-Certified-Professional-Data-Engineer dumps for free: https://drive.google.com/open?id=19MEwq-vssMc8F_yaOvsnMjjmn109mDsf