Our materials can make you master the best AI-500 questions torrent in the shortest time and save your much time and energy to complete other thing. What most important is that our AI-500 study materials can be download, installed and used safe. We can guarantee to you that there no virus in our product. Not only that, we also provide the best service and the best AI-500 Exam Torrent to you and we can guarantee that the quality of our AI-500 learning dump is good. So please take it easy after the purchase and we won’t let your money be wasted.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement security for multi-agent solutions
|
| Topic 2: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Design and implement evaluation and validation strategies
|
| Topic 3: Develop multi-agent solutions in Azure | 30-35% | - Implement agent memory, context management, and knowledge integration
|
| Topic 4: Architect multi-agent solutions | 15-20% | - Specify technology components for multi-agent solutions
|
>> AI-500 Valid Exam Format <<
Test4Sure has hired a team of experts who keeps an eye on the Designing and Implementing Multi-Agent AI Solutions real exam content and updates our AI-500 study material according to new changes on daily basis. Moreover, you will receive free Designing and Implementing Multi-Agent AI Solutions exam questions updates if there are any updates in the content of the Designing and Implementing Multi-Agent AI Solutions test. These updates will be given within up to 1 year of your purchase. The 24/7 support system has been made for your assistance to solve your technical problems while using our product. Don't wait anymore. Buy real Designing and Implementing Multi-Agent AI Solutions questions and start preparation for the AI-500 test today!
NEW QUESTION # 72
You have a Microsoft Foundry claims-assistance solution that includes a primary claims agent and three specialist agents. The primary claims agent invokes the specialist agents.
You need to recommend a coordination approach. The solution must meet the following requirements:
* The primary claims agent must retain ownership of the task and synthesize the final response.
* The specialist agents must have a least-privilege view of the claim for their assigned work.
What should you recommend? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.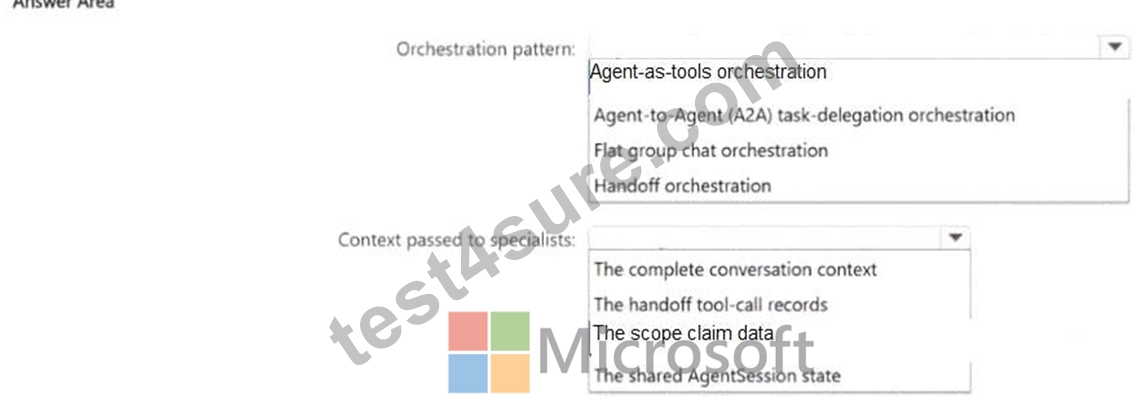
Answer:
Explanation: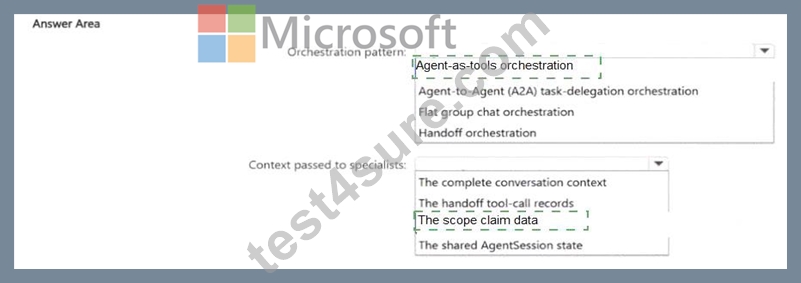
Explanation:
Orchestration pattern: Agent-as-tools; Context passed to specialists: Scoped claim data only.
The primary claims agent must retain task ownership and synthesize the final response, which is the defining property of the agents-as-tools pattern. The primary agent decides when to invoke each specialist, receives the specialist ' s result, and remains responsible for the overall conversation. Handoff orchestration would instead transfer control to another agent and therefore weaken the ownership requirement. Microsoft Agent Framework also makes it possible for the outer agent to pass only the arguments needed by the inner agent rather than sharing the entire conversation history automatically. That supports least-privilege context: each specialist receives only the claim fields required for its assigned work. Passing the whole claim or a shared transcript would unnecessarily expose data outside the specialist ' s domain. The selected combination therefore satisfies both control ownership and data minimization. The architecture should still be validated with representative end-to-end tests, but the selected component establishes the correct structural boundary first. Microsoft ' s AI-500 blueprint consistently favors explicit scopes, interfaces, and persistence or identity boundaries over prompt-only conventions.
Official Microsoft reference: Microsoft Agent Framework - Agents as tools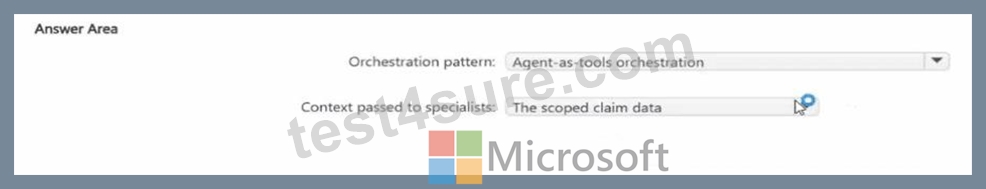
NEW QUESTION # 73
You have a multi-agent customer support solution in a Microsoft Foundry project.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in evaluators that provide 1 to-5 scores with pass/fail labels for the following metrics:
* The quality of the retrieved context
* How directly a response answers a query
Which evaluator should you use for each metric? To answer, drag the appropriate evaluators to the correct metrics. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Quality of retrieved context: Retrieval evaluator; Directness of response to query: Relevance evaluator.
The dataset contains query, context, and response but does not contain document relevance labels. Microsoft ' s Retrieval evaluator is designed for exactly that situation: it uses an LLM judge to rate how relevant the retrieved context chunks are to the query and returns a 1-to-5 score with pass/fail behavior. The Relevance evaluator operates on the final response and measures whether the answer accurately, completely, and directly addresses the query. Document Retrieval is not appropriate because it requires retrieval ground truth such as known relevant documents or qrels. Groundedness answers a different question: whether response claims are supported by the provided context. Therefore the correct mapping is Retrieval for context quality and Relevance for response directness. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators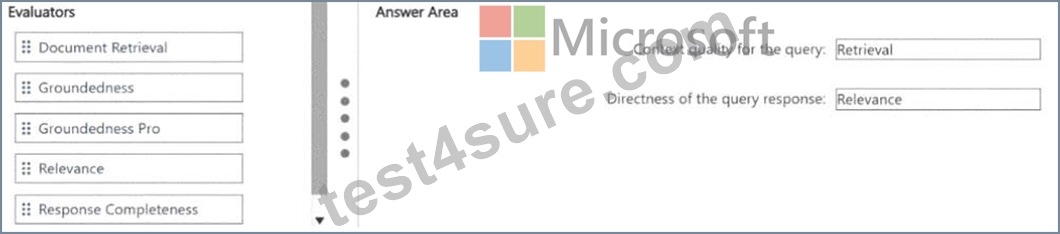
NEW QUESTION # 74
You have a Microsoft Foundry multi-agent solution that includes a orchestrator and agents named Agent1 and Agent2. The solution has the following characteristics:
* The orchestrator routes tasks to both agents.
* The agents invoice Model Context Protocol (MCP)-hosted tools.
* Agent? sends model-generated JSON parameters directly to tool endpoints.
* The agents use a shared managed identity that has contributor access to the resource group that contains the tool-backed Azure resources.
You need to implement a guardrail strategy for tool calls. The solution must meet the following requirements:
* Prevent invalid or out-of-range tool parameters from reaching the tool endpoints.
* Scope each agent ' s permissions to its assigned tools
* Limit Agent? to refund-processing tools only.
* Log tool invocations for audit purposes.
What should you do?
Answer: D
Explanation:
The solution needs deterministic validation before model-generated tool arguments reach MCP endpoints, per- agent authorization boundaries, tool scoping, and audit logging. Validating typed payload schemas at the tool boundary prevents malformed or out-of-range arguments before execution, which is stronger than validating outputs after a tool has already run. Per-agent managed identities and scoped RBAC roles reduce lateral movement and contain the impact of a compromised agent. A per-agent tool-access policy also ensures the refund-focused agent cannot invoke unrelated tools. Finally, Azure Monitor/trace logging provides an auditable record of tool invocations. A2A capability cards describe remote-agent capabilities rather than validate tool arguments. System instructions are not an authorization boundary, and shared Contributor access leaves an excessive blast radius. Option D is therefore the only answer that satisfies all four requirements at enforceable platform boundaries. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: AI-500 Study Guide - tool scopes, permission boundaries, and auditing
NEW QUESTION # 75
You need to recommend changes to decrease the Claim Approval duration without breaking any existing functionality.
What should you recommend?
Answer: B
Explanation:
Fraud-check, Policy-eligibility, and Document-summary are independent specialist activities, so running them concurrently reduces wall-clock time without changing their outputs. The Decision agent is different because the case study states that it depends on the results of those three agents. It therefore must execute only after the independent work completes. Microsoft Agent Framework ' s concurrent orchestration pattern is designed for independent participants whose results can be fanned in later, while dependency-driven work should remain ordered. Running all four agents concurrently would violate the Decision agent ' s data dependency.
Running all four sequentially would preserve correctness but add unnecessary latency. Disabling memory would also change functionality unrelated to the performance bottleneck. The optimal graph is therefore a parallel fan-out of the three independent specialists followed by a fan-in and Decision step, which preserves behavior while minimizing end-to-end claim-approval duration. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Concurrent orchestration
NEW QUESTION # 76
You have a Microsoft Foundry resource that hosts Azure OpenAI model deployments for three projects. Each project is for a different business unit. The projects share the same Foundry resource.
You need to implement a Microsoft Cost Management view that separates the shared model spend by the project The solution must meet the following requirements:
* Use cost data that can be reconciled by using Azure Cost Management.
* Minimize manual tagging.
What should you use?
Answer: D
Explanation:
When multiple projects share one Foundry resource, grouping costs only by Azure resource cannot distinguish project consumption because the resource boundary is shared. Microsoft Foundry integrates with Azure Cost Management by attributing model usage to project metadata/tags, allowing a Cost Analysis view to filter shared resource spending by project. This supports showback or chargeback without requiring administrators to manually tag every usage event. Subscription-level service filters or meter grouping identify the service or billing meter but not which of the three business-unit projects generated the usage. Therefore a Foundry-resource-scoped Cost Analysis view filtered by the project tag is the configuration that both reconciles to Azure Cost Management and minimizes manual tagging. D remains correct. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - Manage costs
NEW QUESTION # 77
......
Microsoft AI-500 study material of "Test4Sure" is available in three different formats: PDF, desktop-based practice test software, and a browser-based practice AI-500 exam questions. Designing and Implementing Multi-Agent AI Solutions (AI-500) practice tests are a great way to gauge your progress and identify weak areas for further study. Check out features of these formats.
AI-500 Braindump Free: https://www.test4sure.com/AI-500-pass4sure-vce.html