100% Pass 2026 DY0-001: High Pass-Rate Vce CompTIA DataAI Certification Exam Torrent

P.S. Free 2026 CompTIA DY0-001 dumps are available on Google Drive shared by TorrentVCE: https://drive.google.com/open?id=1pUhHt82nDfOBT5rnZBG_7YtNbXRN53_x
Now we live in a highly competitive world. If you want to find a decent job and earn a high salary you must own excellent competences and rich knowledge. Under this circumstance, owning a DY0-001 guide torrent is very important because it means you master good competences in certain areas and can handle the job well. The DY0-001 Exam Prep we provide can help you realize your dream to pass DY0-001 exam and then own a DY0-001 exam torrent easily.
| Section | Weight | Objectives |
|---|
| Topic 1: Mathematics and Statistics | 17% | - Probability and Modeling
- 1. Distributions, skewness, kurtosis
- 2. PDF, PMF, CDF, missing data handling
- Time Series and Causal Models
- 1. Forecasting and temporal modeling concepts
- Linear Algebra and Calculus
- 1. Derivatives, gradients, optimization basics
- 2. Matrix operations, eigenvalues, rank
- Statistical Methods
- 1. t-tests, chi-square tests, ANOVA
- 2. Hypothesis testing and regression metrics
- 3. ROC/AUC, AIC/BIC, confusion matrix
|
| Topic 2: Specialized Applications of Data Science | 13% | - Computer Vision
- 1. OCR, object detection, tracking
- Optimization and Advanced Methods
- 1. Constrained and unconstrained optimization
- Other AI Applications
- 1. Graph analysis and signal processing
- 2. Reinforcement learning, anomaly detection
- Natural Language Processing (NLP)
- 1. Topic modeling and applications
- 2. Tokenization, embeddings, TF-IDF
|
| Topic 3: Modeling, Analysis, and Outcomes | 24% | - Communication of Results
- 1. Visualization best practices
- 2. Avoiding misleading charts
- Exploratory Data Analysis (EDA)
- 1. Feature identification and visualization
- 2. Univariate and multivariate analysis
- Data Issues and Preparation
- 1. Missing data, outliers, sparsity
- 2. Feature engineering and transformation
- Model Development
- 1. Model selection, validation, evaluation
|
| Topic 4: Operations and Processes | 22% | - Data Engineering Concepts
- 1. Data ingestion, pipelines, streaming
- 2. Data wrangling and cleaning
- MLOps and Deployment
- 1. Model monitoring and deployment environments
- 2. CI/CD pipelines
- Data Science Lifecycle
- 1. Workflow, version control, testing
- Business Context
- 1. KPIs and requirements gathering
|
| Topic 5: Machine Learning | 24% | - Unsupervised Learning
- 1. Clustering and dimensionality reduction
- Tree-Based Models
- 1. Decision trees, random forests, boosting
- Core ML Concepts
- 1. Cross-validation and regularization
- 2. Bias-variance tradeoff
- Supervised Learning
- 1. Linear and logistic regression
- 2. KNN and Naive Bayes
- Deep Learning
- 1. Neural networks and backpropagation
- 2. Dropout and batch normalization
|
>> Vce DY0-001 Torrent <<
Vce DY0-001 Torrent - Pass Guaranteed 2026 First-grade DY0-001: Actual CompTIA DataAI Certification Exam Test
CompTIA DataAI Certification Exam Exam Questions save your study time and help you prepare in less duration. We have hundreds of most probable questions which have a chance to appear in the real CompTIA DataAI Certification Exam exam. The CompTIA DY0-001 exam questions are affordable and 365 days free updated, and you can use them without any guidance. However, in case of any trouble, our support team is always available to sort out the problems. We will provide you with the information covered in the current test and incorporate materials that originate from CompTIA DY0-001 Exam Dumps.
CompTIA DataAI Certification Exam Sample Questions (Q18-Q23):
NEW QUESTION # 18
SIMULATION
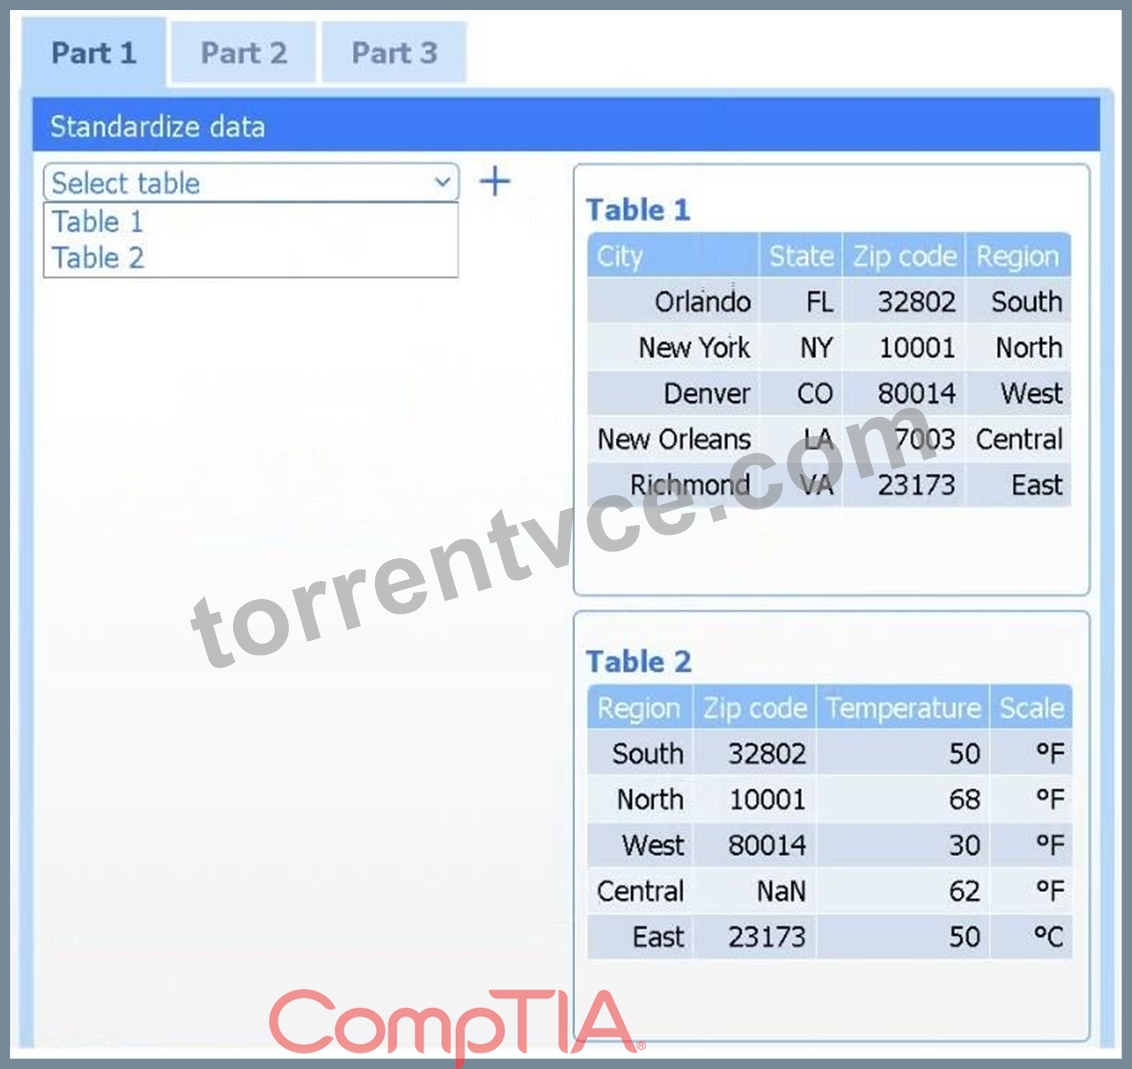
A client has gathered weather data on which regions have high temperatures. The client would like a visualization to gain a better understanding of the data.
INSTRUCTIONS
Part 1
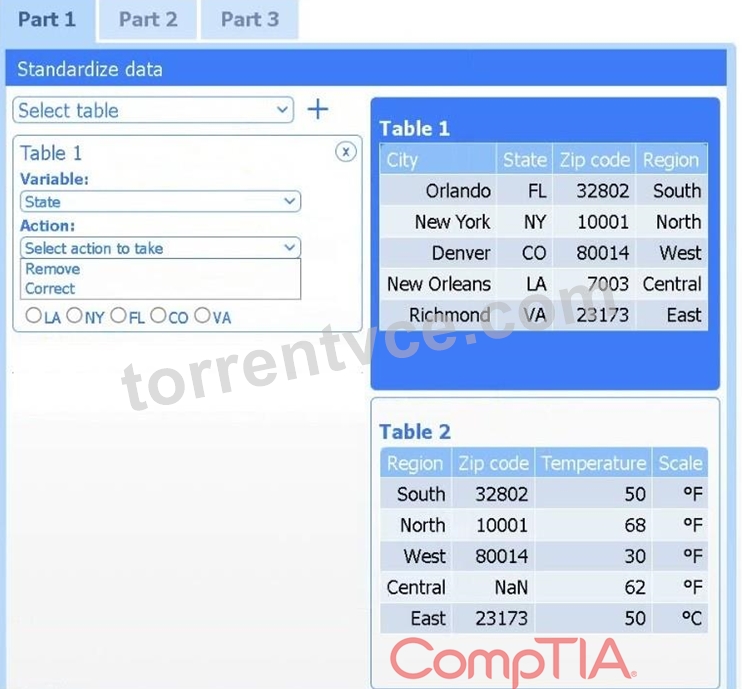
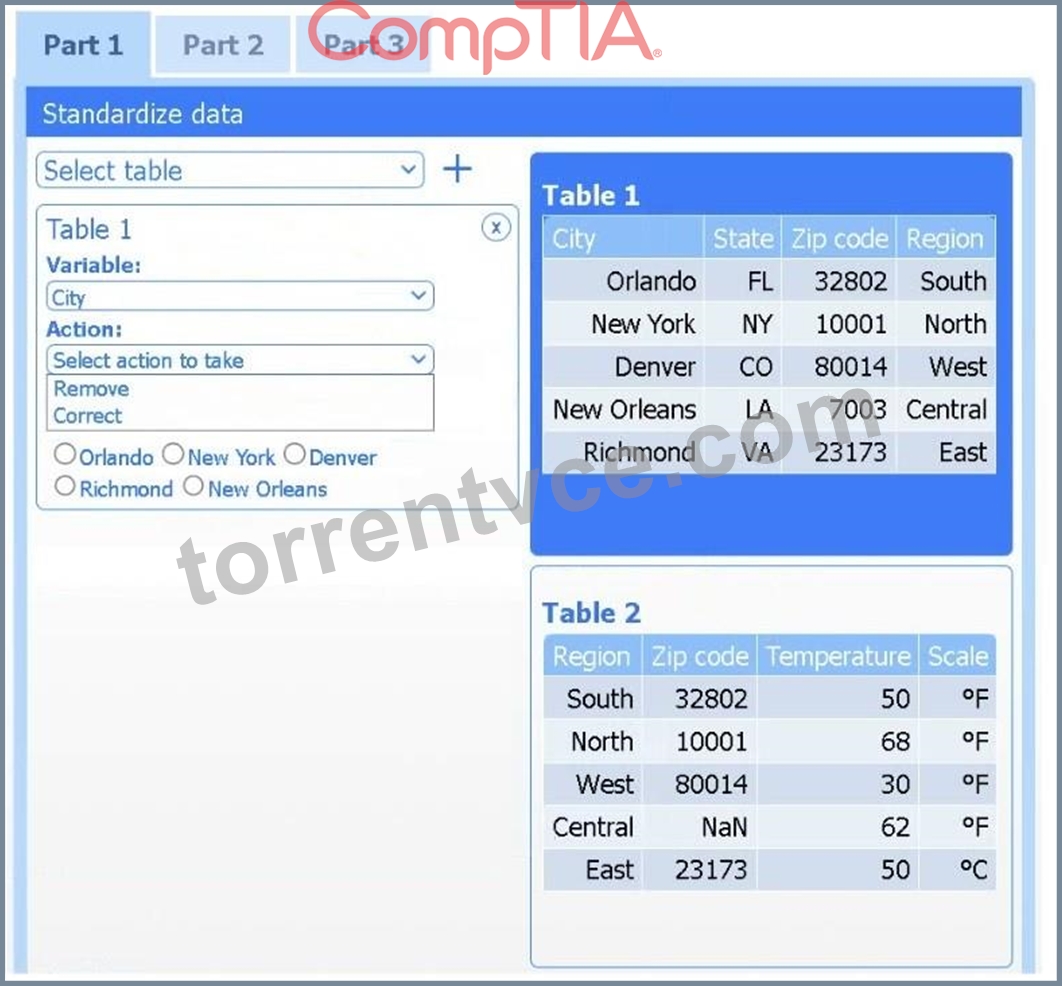
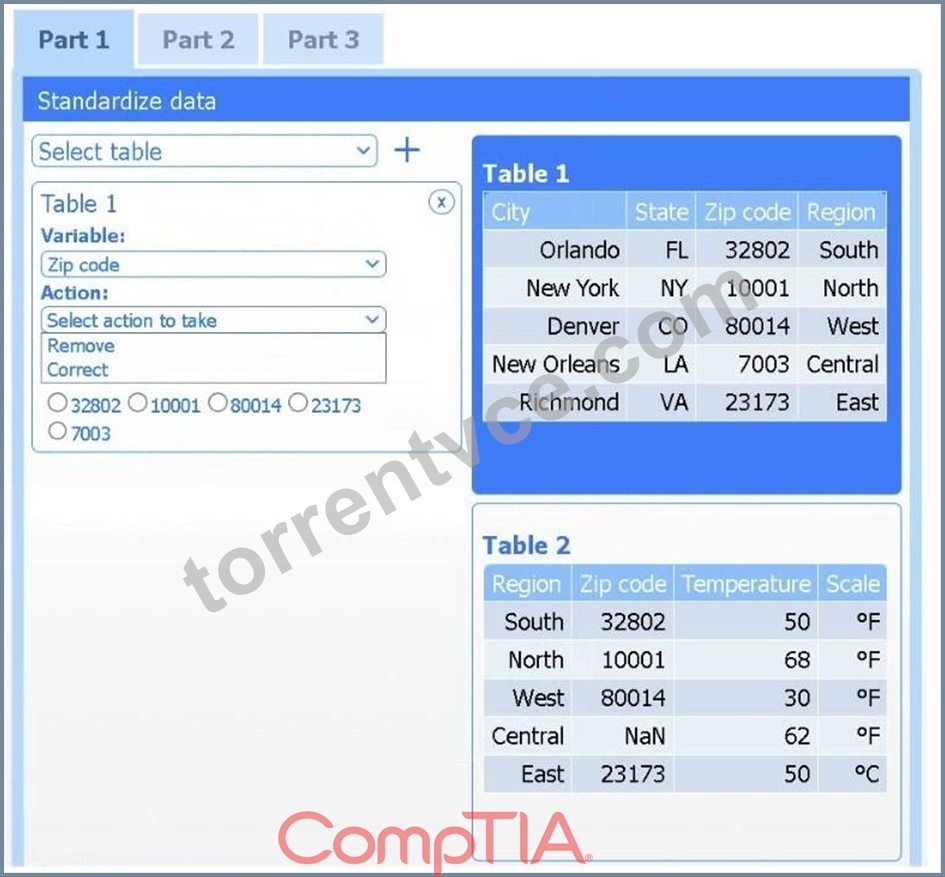
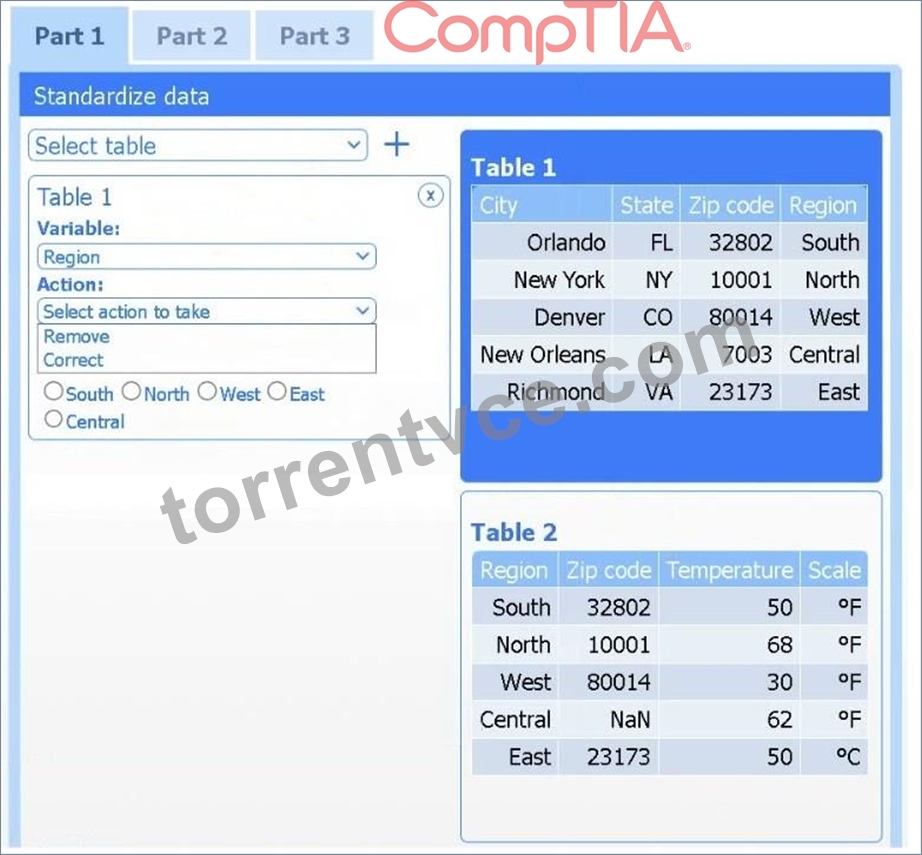
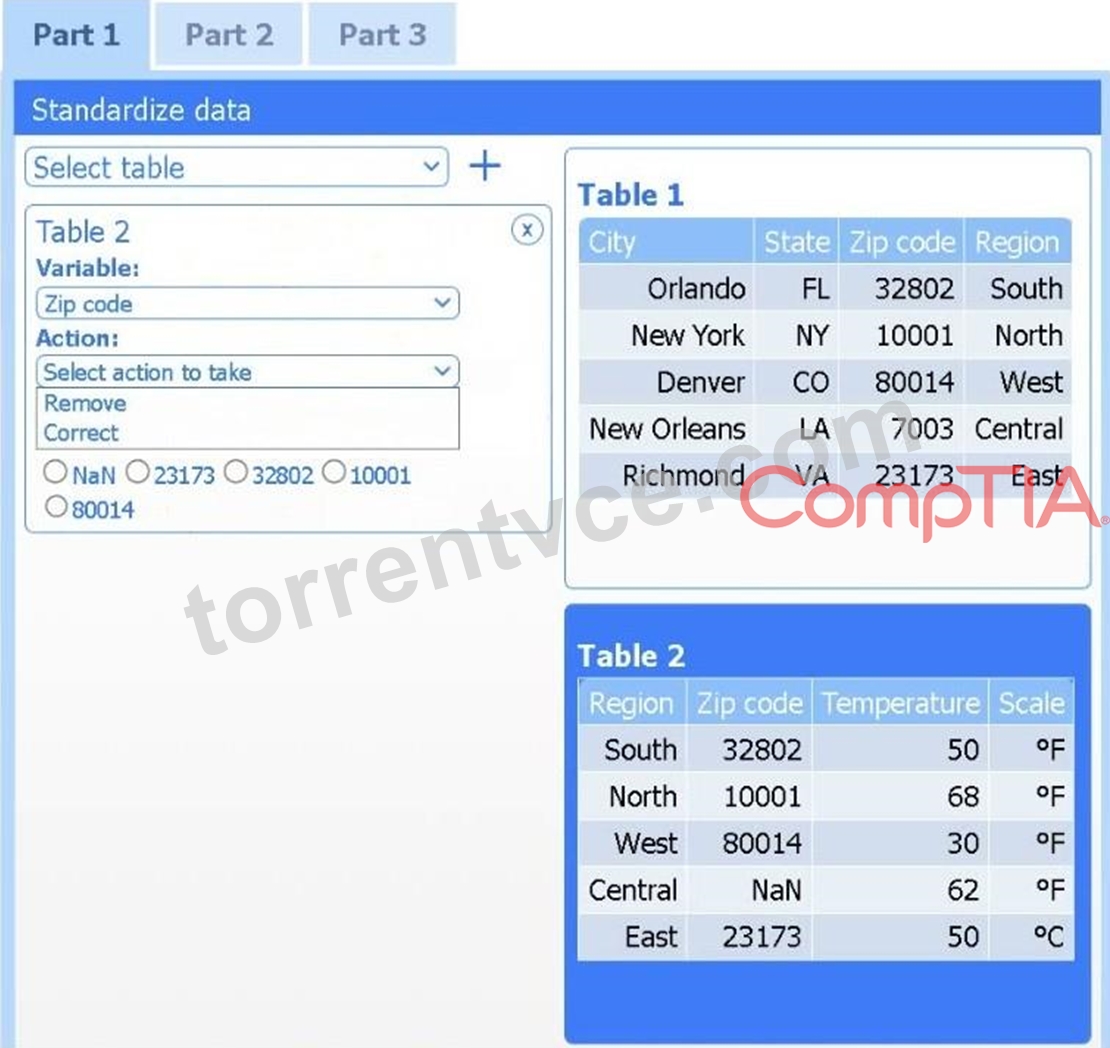
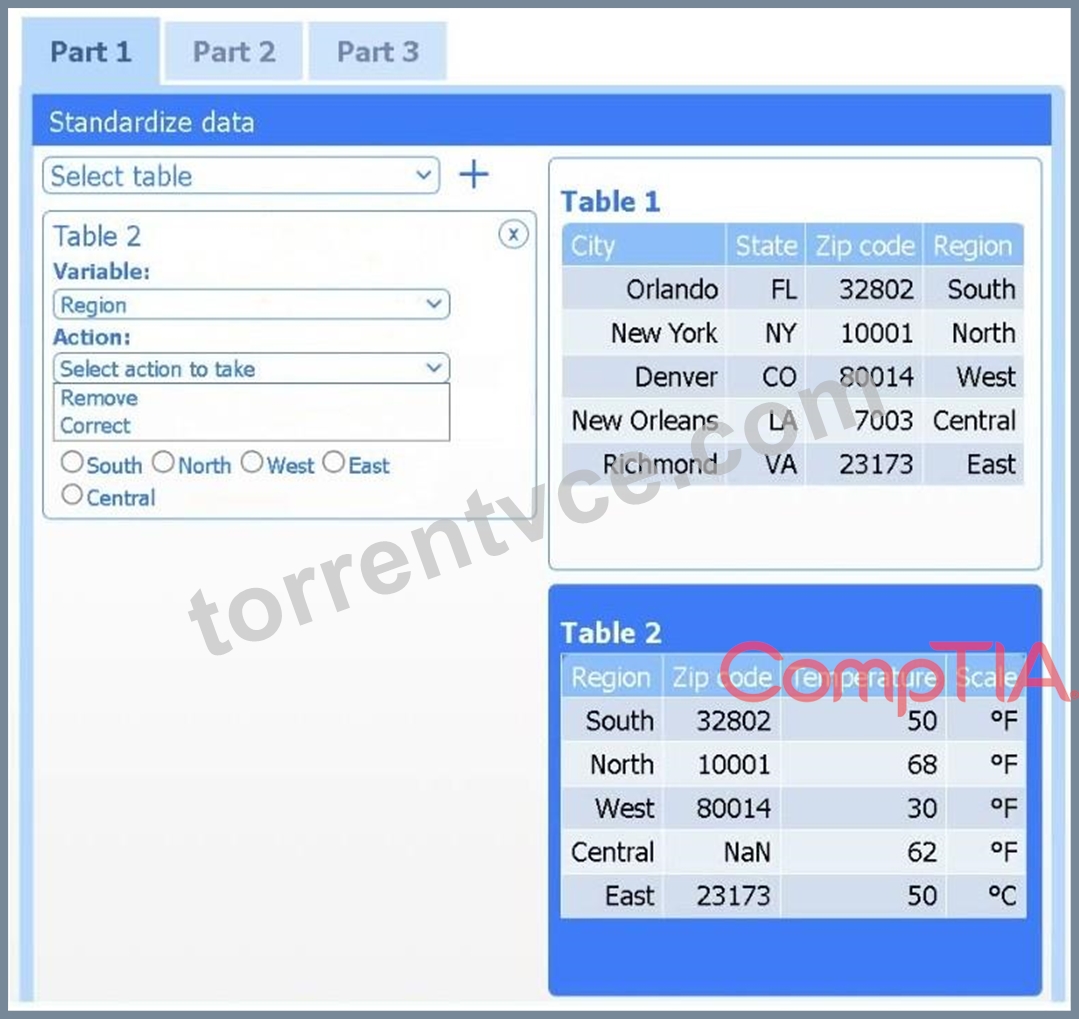
Review the charts provided and use the drop-down menu to select the most appropriate way to standardize the data.
Part 2
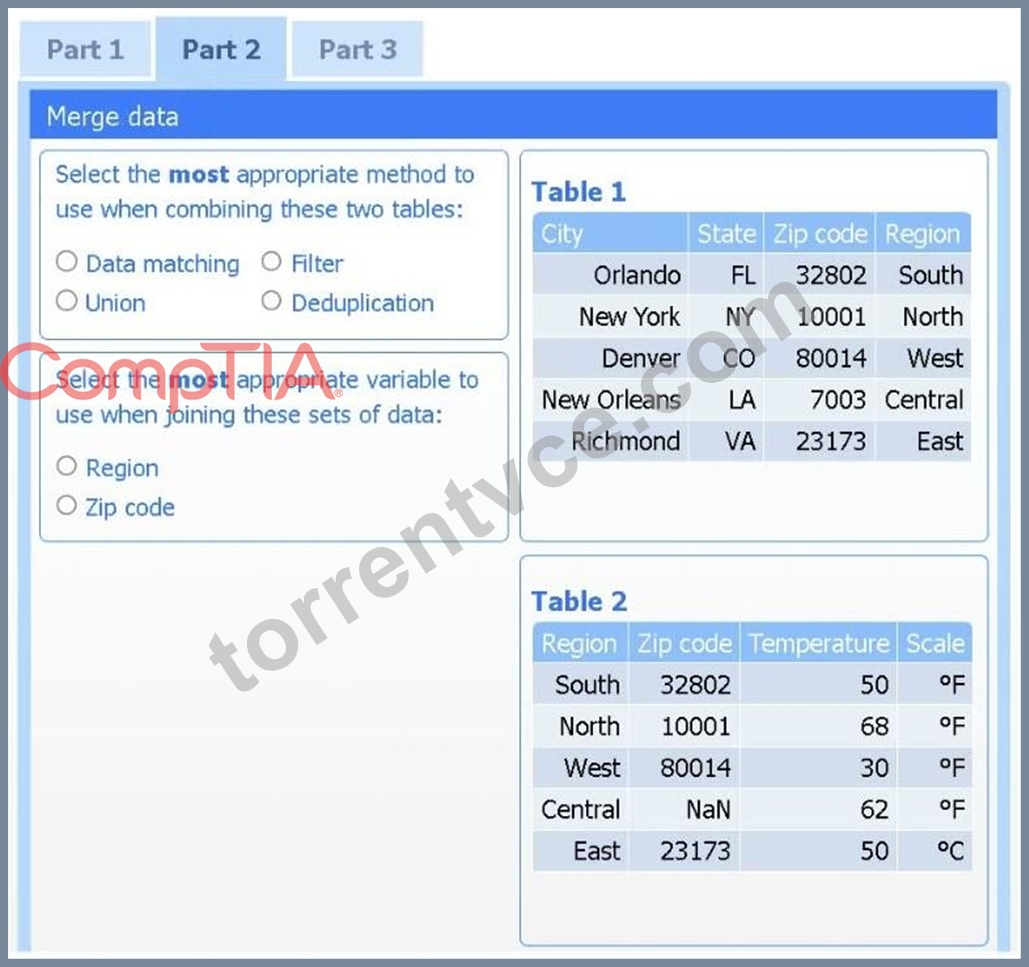
Answer the questions to determine how to create one data set.
Part 3
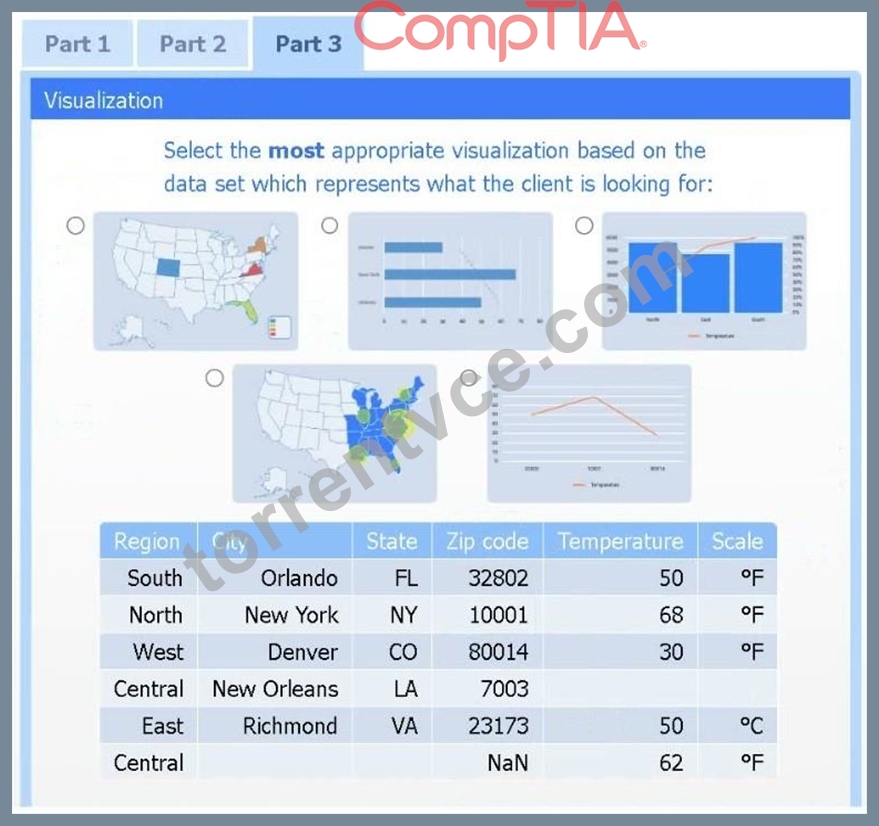
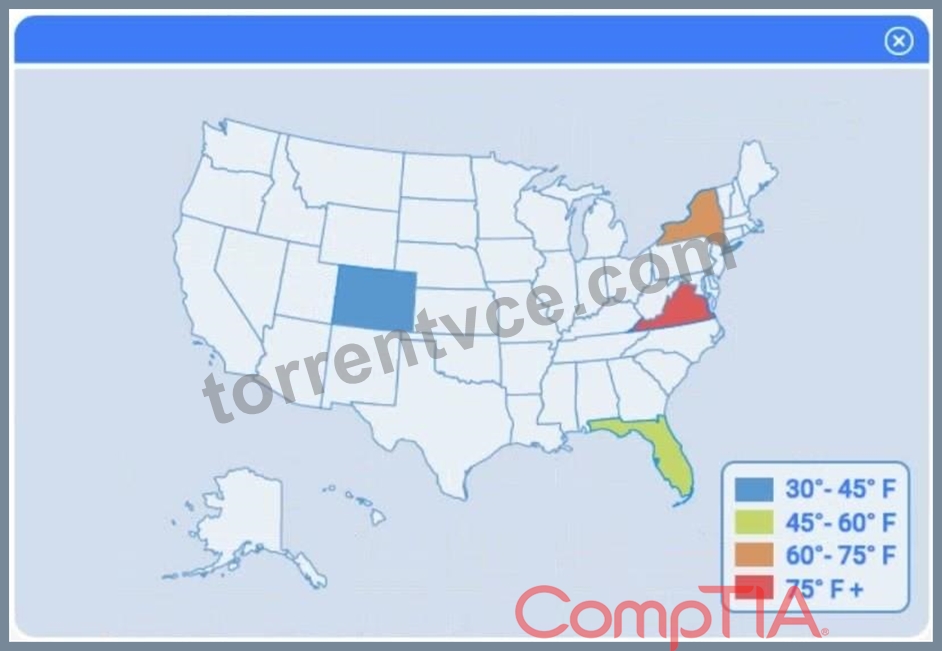
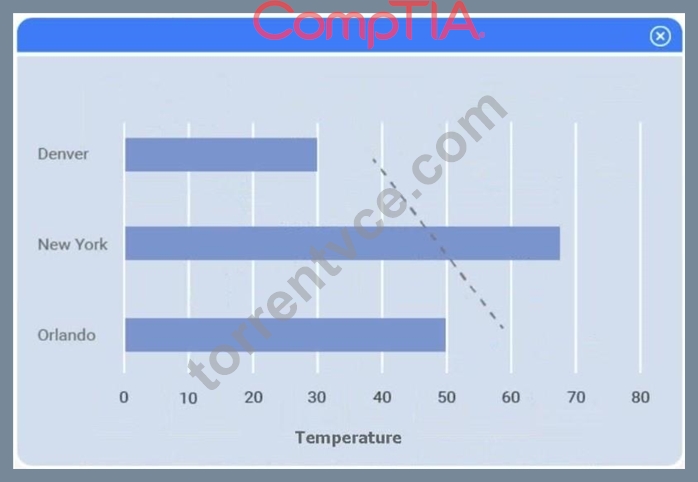
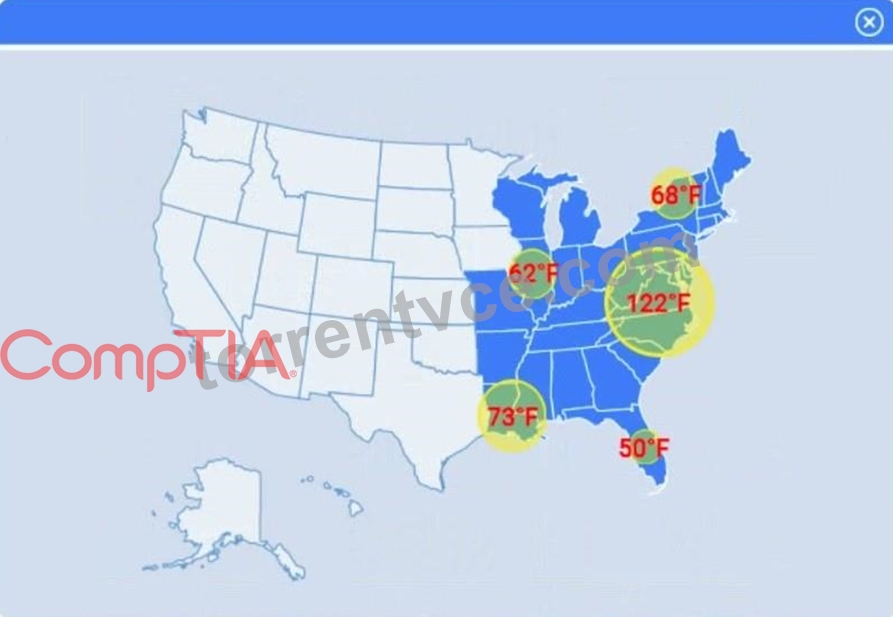
Select the most appropriate visualization based on the data set that represents what the client is looking for.
If at any time you would like to bring back the initial state of the simulation, please click the Reset All button.




Answer:
Explanation:
Part 1
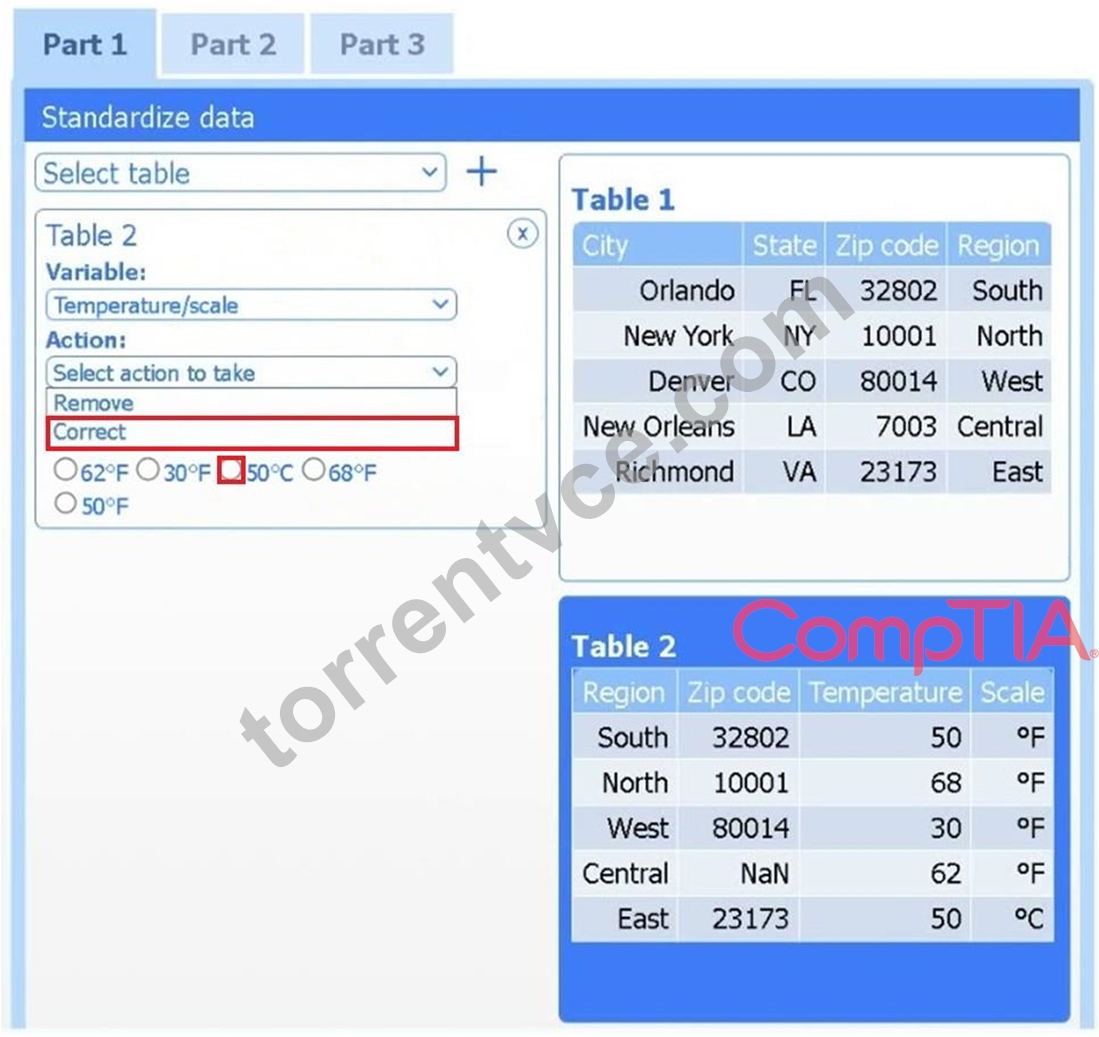
Select Table 2. Table 2 contains mixed temperature scales (°F and °C) that must be standardized before visualization.
Variable: Temperature/scale
Action: Correct
Value to correct: 50 °C
Part 2
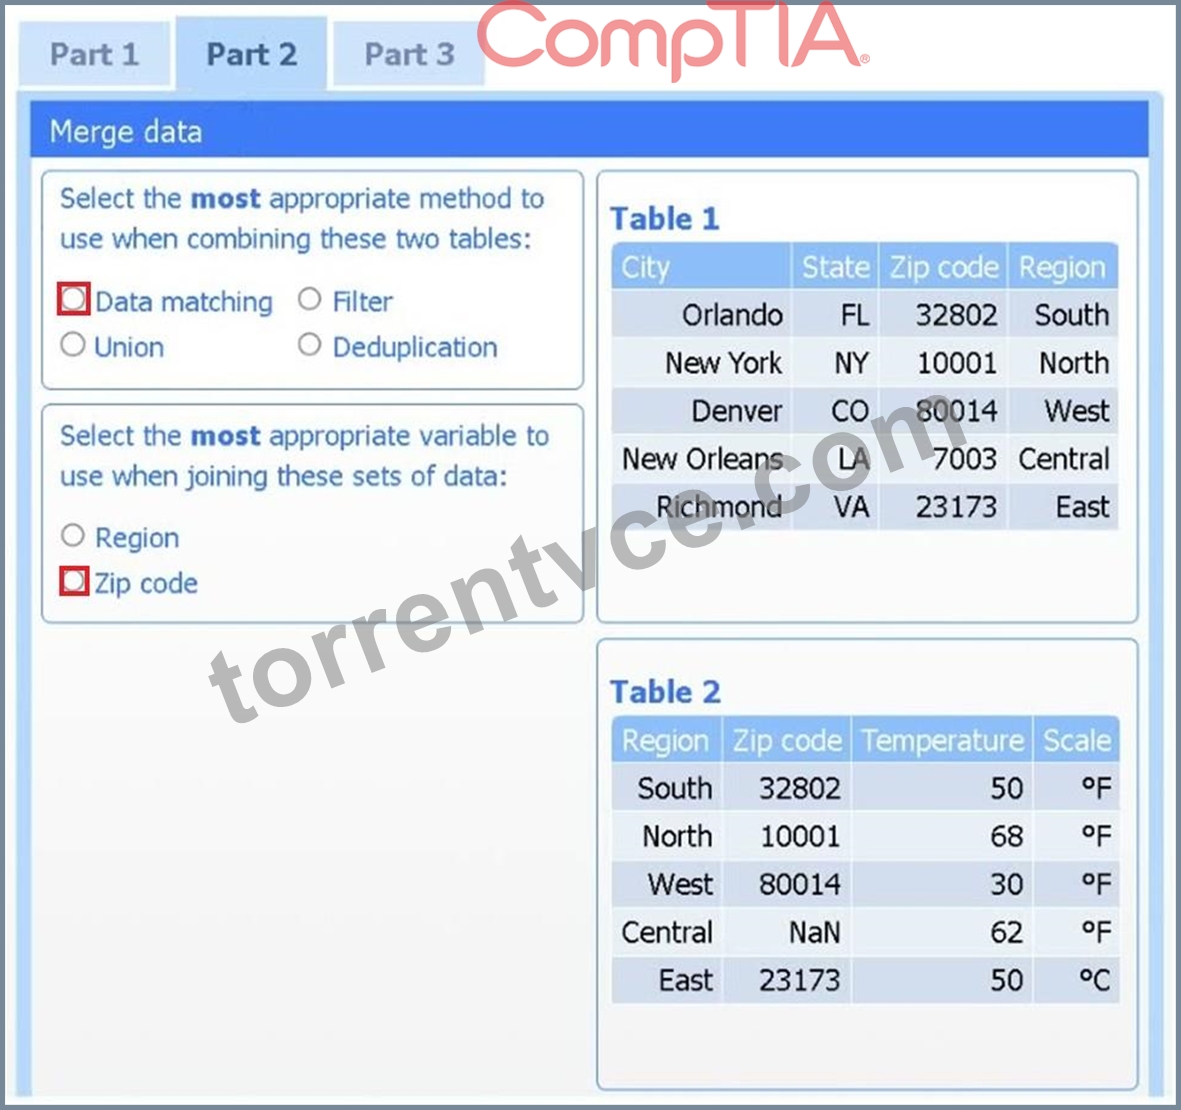
Method: Data matching
Join variable: Zip code
You need to merge the two tables by aligning matching records, which is a data-matching (join) operation, and ZIP code is the shared, uniquely identifying field linking each region's weather reading to its city.
Part 3
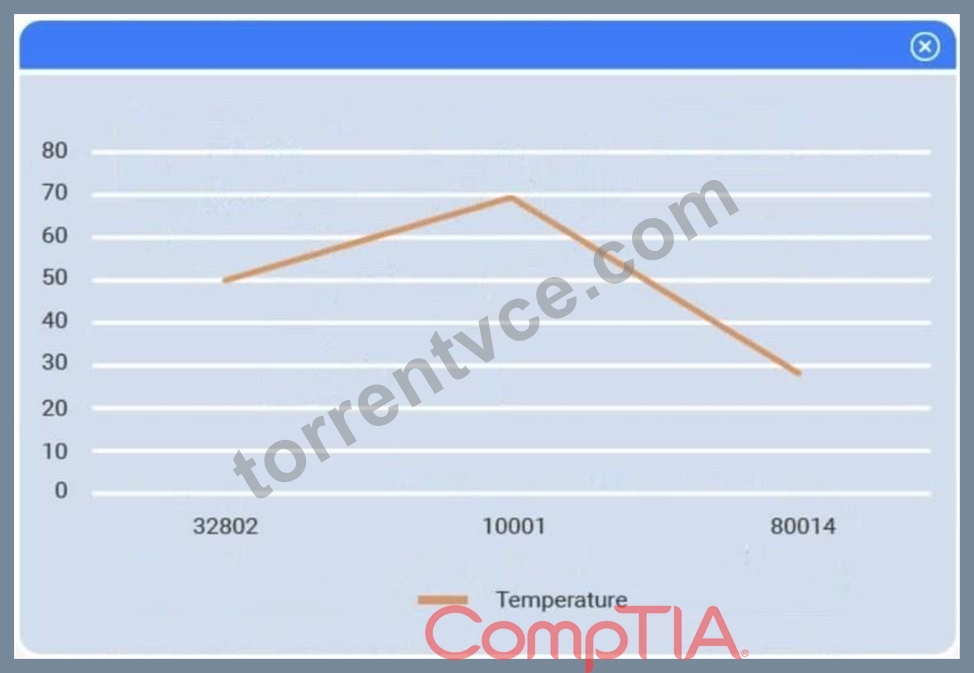
Choose the choropleth map (the first option).
A choropleth map best shows geographic variation in temperature by coloring each state (or region) according to its recorded value. This lets the client immediately see where the highest and lowest temperatures occur across the U.S. without distracting elements like bubble size or combined chart axes.

NEW QUESTION # 19
Which of the following is a key difference between KNN and k-means machine-learning techniques?
- A. KNN is used for finding centroids, while k-means is used for finding nearest neighbors.
- B. KNN performs better with longitudinal data sets, while k-means performs better with survey data sets.
- C. KNN is used for classification, while k-means is used for clustering.
- D. KNN operates exclusively on continuous data, while k-means can work with both continuous and categorical data.
Answer: C
Explanation:
# K-Nearest Neighbors (KNN) is a supervised machine learning algorithm used primarily for classification and regression. It labels a new instance by majority vote (or averaging, in regression) of its k-nearest labeled neighbors.
# k-Means is an unsupervised learning algorithm used for clustering. It partitions unlabeled data into k groups based on feature similarity, using centroids.
Thus, the key difference is in their purpose:
* KNN # Classification (Supervised)
* K-Means # Clustering (Unsupervised)
Why the other options are incorrect:
* A: Both can technically operate on continuous or categorical data (with preprocessing).
* B: This is not a meaningful or standardized distinction.
* C: This reverses the actual roles. k-means finds centroids; KNN finds nearest neighbors.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 4.1 (Classification vs. Clustering):"KNN is a supervised learning algorithm for classification tasks. K-means is an unsupervised clustering technique that groups data by proximity to centroids."
* Data Science Handbook, Chapter 5:"One key distinction: KNN uses labeled data to classify or regress; k-means uses unlabeled data to identify groupings."
-
NEW QUESTION # 20
Which of the following best describes the minimization of the residual term in a ridge linear regression?
Answer: C
Explanation:
Ridge regression extends ordinary least squares by adding an L2 penalty on the coefficients, but it still minimizes the sum of squared residuals (e²) as its loss term.
NEW QUESTION # 21
The following graphic shows the results of an unsupervised, machine-learning clustering model:
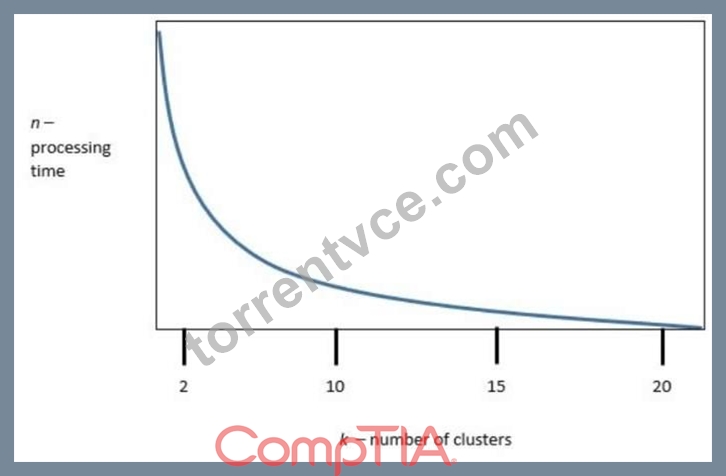
k is the number of clusters, and n is the processing time required to run the model. Which of the following is the best value of k to optimize both accuracy and processing requirements?
Answer: A
Explanation:
# The graph represents a classic "elbow curve," which is often used in clustering (e.g., k-means) to help determine the optimal number of clusters. The point where the curve starts to level off (the "elbow") reflects the best trade-off between model accuracy and processing efficiency.
In this graph, the elbow visually occurs around k = 10. Beyond that, the processing time continues to decrease, but the marginal gain in clustering quality (or drop in processing time) diminishes.
Why the other options are incorrect:
* A: k = 2 underfits the data - too few clusters.
* C & D: k = 15 or 20 provides minimal additional benefit in processing but may overcomplicate the model.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.2:"The elbow method identifies the optimal number of clusters where the rate of improvement drops significantly."
-
NEW QUESTION # 22
Which of the following modeling tools is appropriate for solving a scheduling problem?
- A. One-armed bandit
- B. Constrained optimization
- C. Gradient descent
- D. Decision tree
Answer: B
Explanation:
Scheduling problems require finding the best allocation of resources subject to constraints (e.g., time slots, resource availability), which is precisely what constrained optimization algorithms are designed to handle.
NEW QUESTION # 23
......
We are quite confident that all these CompTIA DY0-001 exam dumps feature you will not find anywhere. Just download the CompTIA DY0-001 and start this journey right now. For the well and quick DY0-001 exam dumps preparation, you can get help from CompTIA DY0-001 which will provide you with everything that you need to learn, prepare and pass the CompTIA DataAI Certification Exam (DY0-001) certification exam.
Actual DY0-001 Test: https://www.torrentvce.com/DY0-001-valid-vce-collection.html
- Top Vce DY0-001 Torrent - Unparalleled - Useful DY0-001 Materials Free Download for CompTIA DY0-001 Exam 🏇 Search for [ DY0-001 ] on ⇛ www.examcollectionpass.com ⇚ immediately to obtain a free download 🥽Reliable DY0-001 Exam Labs
- Reliable Study DY0-001 Questions 🧼 DY0-001 Certificate Exam 📲 Valid Dumps DY0-001 Questions 🥢 Search for ( DY0-001 ) and download it for free immediately on ➥ www.pdfvce.com 🡄 🦁Reliable DY0-001 Exam Labs
- 2026 Vce DY0-001 Torrent - Latest CompTIA Actual DY0-001 Test: CompTIA DataAI Certification Exam 🟨 Search for ( DY0-001 ) on ⮆ www.troytecdumps.com ⮄ immediately to obtain a free download 🍥DY0-001 New Study Notes
- DY0-001 Pdf Pass Leader 📕 Exam DY0-001 Discount 🌱 Latest DY0-001 Exam Vce 🚗 “ www.pdfvce.com ” is best website to obtain { DY0-001 } for free download 🌲New DY0-001 Braindumps Files
- Newest DY0-001 - Vce CompTIA DataAI Certification Exam Torrent ⭐ Immediately open ▛ www.vce4dumps.com ▟ and search for ➽ DY0-001 🢪 to obtain a free download 🙇Exam DY0-001 Discount
- DY0-001 Test Papers 🍇 DY0-001 Preparation Store 🧭 DY0-001 Test Guide Online ✳ Search for ➥ DY0-001 🡄 and download exam materials for free through ⮆ www.pdfvce.com ⮄ 🧣Study DY0-001 Dumps
- 100% Pass Quiz 2026 Accurate DY0-001: Vce CompTIA DataAI Certification Exam Torrent 💓 Open website ▶ www.pdfdumps.com ◀ and search for ( DY0-001 ) for free download 🍹DY0-001 New Dumps Ppt
- 100% Pass Quiz 2026 Accurate DY0-001: Vce CompTIA DataAI Certification Exam Torrent 🥣 Open website ⮆ www.pdfvce.com ⮄ and search for [ DY0-001 ] for free download 😆DY0-001 Certificate Exam
- DY0-001 Test Guide Online 🍈 Exam DY0-001 Discount 👎 DY0-001 Test Papers 📌 Go to website ▶ www.troytecdumps.com ◀ open and search for ☀ DY0-001 ️☀️ to download for free 🏬Exam DY0-001 Discount
- Exam Dumps DY0-001 Free 🛴 Exam Dumps DY0-001 Free 🎹 DY0-001 New Dumps Ppt 🚲 Open ➽ www.pdfvce.com 🢪 enter ➤ DY0-001 ⮘ and obtain a free download 🎓DY0-001 Certificate Exam
- Latest DY0-001 Braindumps Pdf 🦜 DY0-001 Exam Material 💇 DY0-001 Test Guide Online 🐝 The page for free download of ➡ DY0-001 ️⬅️ on ⇛ www.testkingpass.com ⇚ will open immediately 🏥DY0-001 Pdf Pass Leader
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026 Latest TorrentVCE DY0-001 PDF Dumps and DY0-001 Exam Engine Free Share: https://drive.google.com/open?id=1pUhHt82nDfOBT5rnZBG_7YtNbXRN53_x