BTW, DOWNLOAD part of PassSureExam AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1_qpCFmqpMEkqGE0BIyDDxPsex08KWCJe
Up to now our AI-300 real exam materials become the bible of practice material of this industry. Ten years have gone, and three versions have been made for your reference. They made the biggest contribution to the efficiency and quality of our Operationalizing Machine Learning and Generative AI Solutions practice materials, and they were popularizing the ideal of passing the exam easily and effectively. All AI-300 Guide prep is the successful outcomes of professional team.
| Section | Objectives |
|---|---|
| Topic 1: Design and implement an MLOps infrastructure | - Configure source control, CI/CD pipelines, and automation for ML workflows - Set up Azure Machine Learning workspace and compute targets - Manage environments, data stores, and model registries - Implement security, governance, and compliance for MLOps |
| Topic 2: Implement machine learning model lifecycle and operations | - Train, register, and version models using Azure Machine Learning - Deploy models to real-time and batch endpoints - Retrain, update, and manage model versions in production - Monitor model performance, data drift, and operational health |
| Topic 3: Optimize generative AI systems and model performance | - Tune prompts, system messages, and grounding strategies - Fine-tune and distill models for specific use cases - Optimize inference performance, caching, and throughput - Implement cost management and scaling strategies for GenAI workloads |
| Topic 4: Implement generative AI quality assurance and observability | - Evaluate generative AI outputs for quality, safety, and grounding - Implement logging, tracing, and telemetry for GenAI applications - Monitor latency, token usage, cost, and error rates - Conduct red teaming, adversarial testing, and content filtering |
| Topic 5: Design and implement a GenAIOps infrastructure | - Manage API keys, rate limits, and responsible AI guardrails - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search - Configure prompt orchestration, prompt flows, and agent frameworks |
Our AI-300 Exam Questions can help you pass the exam to prove your strength and increase social competitiveness. Although it is not an easy thing for somebody to pass the AI-300 exam, but our AI-300 exam torrent can help aggressive people to achieve their goals. This is the reason why we need to recognize the importance of getting the test Microsoft certification. More qualified certification for our future employment has the effect to be reckoned with, only to have enough qualification certifications to prove their ability, can we win over rivals in the social competition.
NEW QUESTION # 37
You need to isolate training workloads while remaining cost-aware to address Fabrikam Inc.'s issues, constraints, and technical requirements.
What should you implement?
Answer: D
Explanation:
Imagine a hospital analytics firm with data scientists who kick off dozens of training jobs throughout the week. During peak hours, five jobs compete for the same GPU cluster and fail or queue for hours. On quiet nights, that cluster sits completely idle, burning money. Managed compute targets with autoscaling solve both problems: the cluster scales out automatically when multiple jobs arrive simultaneously and scales back to zero when idle. Option A (single shared cluster) is exactly the resource-contention problem Fabrikam already has. Option B (fixed-size cluster) wastes money during off-peak hours. Option C (dedicated per-experiment clusters) eliminates contention but is prohibitively expensive for a cost-conscious healthcare firm.
Autoscaling managed compute is the cloud-native answer to variable workload demand.
Microsoft Learn Reference Topic: Azure Machine Learning compute targets - Configure autoscale for compute clusters
NEW QUESTION # 38
A company is standardizing generative AI development across multiple teams.
Each team requires an isolated workspace. Governance and shared connections must be centrally managed.
You need to implement a Microsoft Foundry environment structure that supports centralized governance and team isolation .
Which type of configuration should you use for each requirement? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content . NOTE: Each correct selection is worth one point.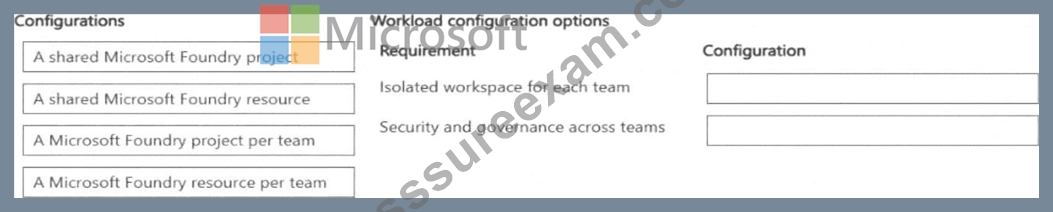
Answer:
Explanation: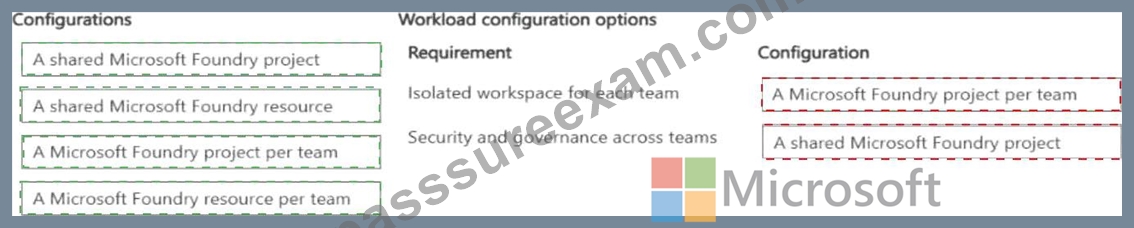
Explanation:
An Azure AI Hub is the top-level governance container in Microsoft Foundry: it holds shared connections to Azure OpenAI, Azure AI Search, Azure Storage, and other services; it defines network isolation policies; it manages billing and quota at the organizational level. Multiple teams share these resources without each team needing to configure their own connections or negotiate quota independently. An Azure AI Project sits inside the Hub and provides team-level isolation: each project has its own experiments, deployments, prompt flows, evaluations, and fine-tuning jobs, all governed by the Hub ' s shared infrastructure. Different teams get their own project with independent access controls via RBAC, while the platform team manages the shared Hub.
This pattern eliminates redundant resource configurations across teams while maintaining clear team-level boundaries - the correct structure for centralized governance with team isolation.
Microsoft Learn Reference Topic: Microsoft Azure AI Foundry hub and project architecture - Centralized governance and team isolation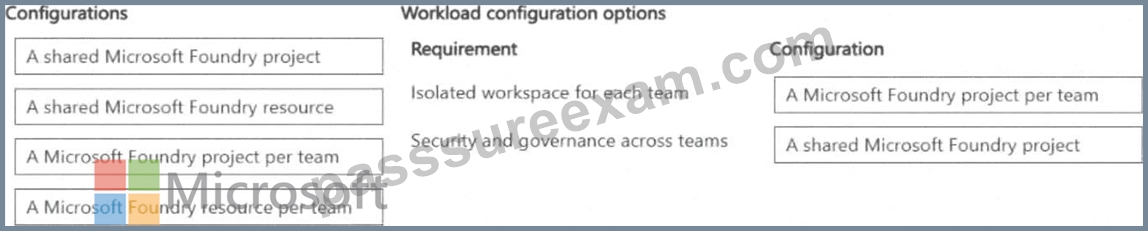
NEW QUESTION # 39
You train and register an Azure Machine Learning model
You plan to deploy the model to an online endpoint
You need to ensure that applications will be able to use the authentication method with a non-expiring artifact to access the model.
Solution:
Create a managed online endpoint with the default authentication settings. Deploy the model to the online endpoint.
Does the solution meet the goal?
Answer: B
NEW QUESTION # 40
Hotspot Question
You manage a Microsoft Foundry project.
You are developing a solution to generate content based on text and images. The solution requires the ability to manage high-volume processing and avoid disruptions to the online workloads.
You need to deploy the solution.
Which deployment type and large language model (LLM) should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.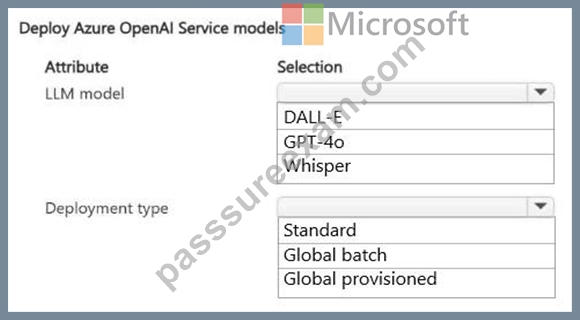
Answer:
Explanation: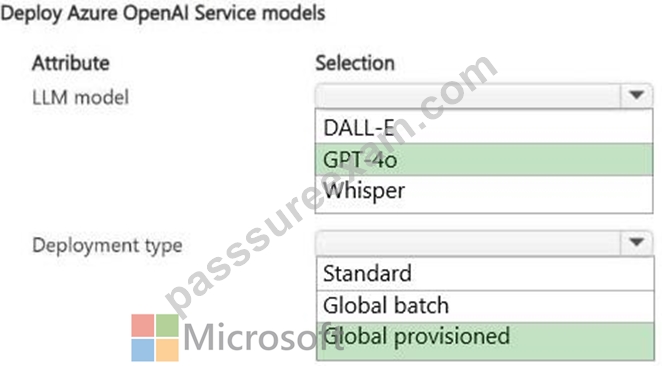
Explanation:
Using Global provisioned deployment and a GPT-4o model is an excellent, industry-standard choice for this Microsoft AI Foundry project. This approach ensures you meet your high-volume processing and text-and-image generation requirements without degrading online workloads, offering both guaranteed latency and dedicated resources.
Box 1: GPT-4o
The GPT-4o Model is highly optimized for handling both text and image input. It provides the multi-modal reasoning necessary to generate contextually accurate content based on visual and textual datasets.
Box 2: Global provisioned
Provisioned Deployment Type: Provisioned throughput allows you to allocate dedicated compute capacity (tokens per minute). This guarantees performance and is explicitly designed to handle high-volume processing without disrupting your online workloads, as you will not be sharing constrained resources.
Global vs. Regional: Global provisioned deployments decouple capacity management from specific regions, providing the highest throughput limits and automatic access to resources with predictable costs. However, if your enterprise has strict European data residency regulations, choosing a Regional Provisioned deployment in a local region ensures your traffic and data are processed entirely within the EU.
Reference:
https://learn.microsoft.com/en-us/azure/foundry/openai/concepts/provisioned-throughput
NEW QUESTION # 41
During training, pipelines occasionally fail due to schema mismatch caused by upstream data changes. You need a robust and automated solution that prevents invalid data from reaching training steps. What is the BEST approach?
Answer: A
Explanation:
A data validation component ensures that incoming data matches the expected schema before training begins. This prevents pipeline failures and avoids training on corrupted or incomplete data. Ignoring schema mismatches can introduce silent errors, making debugging difficult and compromising model quality.
NEW QUESTION # 42
......
Our AI-300 training materials are sold well all over the world, that is to say our customers are from different countries in the world, taking this into consideration, our company has employed many experienced workers to take turns to work at twenty four hours a day, seven days a week in order to provide the best after sale services on our AI-300 Exam Questions. So as long as you have any question about our AI-300 exam engine you can just feel free to contact our after sale service staffs at any time, and our AI-300 training materials will help you get your certification.
AI-300 Test Passing Score: https://www.passsureexam.com/AI-300-pass4sure-exam-dumps.html
What's more, part of that PassSureExam AI-300 dumps now are free: https://drive.google.com/open?id=1_qpCFmqpMEkqGE0BIyDDxPsex08KWCJe