Real4exams also offers the AI-200 web-based practice exam with the same characteristics as desktop simulation software but with minor differences. It is online AI-200 Certification Exam which is accessible from any location with an active internet connection. This Microsoft AI-200 Practice Exam not only works on Windows but also on Linux, Mac, Android, and iOS. Additionally, you can attempt the Microsoft AI-200 practice test through these browsers: Opera, Safari, Firefox, Chrome, MS Edge, and Internet Explorer.
| Section | Objectives |
|---|---|
| Topic 1: Connect to and consume Azure services | - Integrate Azure services
|
| Topic 2: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Topic 3: Develop containerized solutions on Azure | - Implement containerized applications
|
| Topic 4: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
In order to meet different needs for candidates, we offer you three versions for AI-200 exam cram, and you can choose the one you like. AI-200 PDF version is printable, and you can print them into hard one if you like, you can learn them anywhere and anyplace. AI-200 Soft test engine can stimulate the real exam environment, so that you can know the process of the exam, and your confidence will be strengthened. AI-200 Online Test engine support Android and iOS etc. You can have a general review since this version has testing history and performance review. All three versions have free update for one year, and the update version will be sent to you automatically.
NEW QUESTION # 100
You are implementing semantic retrieval for a chatbot.
Embeddings are already stored in Redis. However, vector similarity queries do not return matches.
You need to resolve the vector similarity search issue.
What should you do?
Answer: B
Explanation:
Creating a FLAT vector index on your embedding field will resolve the issue and allow your Redis vector similarity queries to return matches.
In Redis (using the Redis Search and Query features), vector fields cannot be queried using Vector Similarity Search (VSS) syntax until a dedicated vector index is explicitly built over them.
No Automatic Indexing: Redis does not automatically index JSON or Hash fields containing raw binary or string embeddings.
Query Failure: Without an index, VSS queries (using the KNN operator) will fail with syntax errors or return zero results because the query engine cannot parse the unindexed field.
Reference:
https://www.louisbouchard.ai/indexing-methods/
NEW QUESTION # 101
You are developing an application that uses a Python API to perform similarity queries against Azure Database for PostgreSQL. The application creates a new database connection for every request.
During peak traffic, the application intermittently fails to open new database sessions, logs indicate that the maximum number of connections have been reached.
You need to configure the connection pooling strategy to reduce connection setup overhead and maximize reuse for the high-concurrency workload.
What should you configure? To answer. select the appropriate options in the answer area NOTE: Each correct selection is worth one point.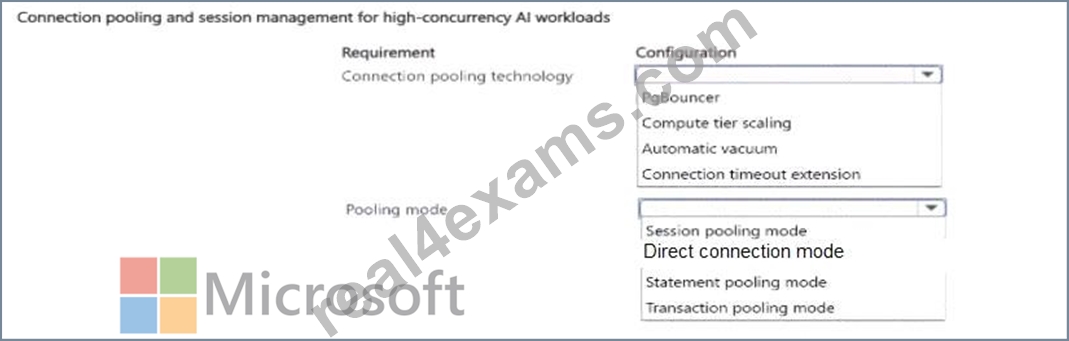
Answer:
Explanation: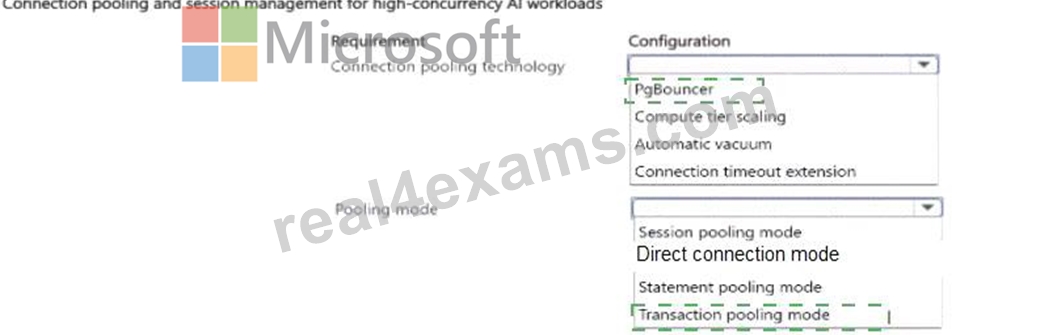
Explanation: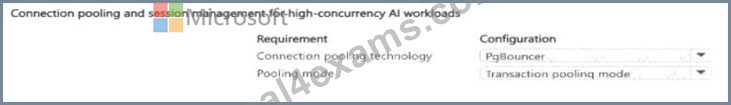
onnection pooling technology: PgBouncer. Pooling mode: Transaction pooling mode.
Detailed Explanation: Azure Database for PostgreSQL Flexible Server supports PgBouncer to reduce connection setup cost and protect the server from excessive client sessions. For a high-concurrency API whose requests do not require a server session to remain pinned between transactions, transaction pooling maximizes reuse by returning the server connection to the pool after each transaction. Session pooling holds a server connection for the lifetime of the client session and therefore provides less multiplexing under the connection-pressure scenario described.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | PgBouncer in Azure Database for PostgreSQL
NEW QUESTION # 102
You are reviewing secret access patterns used by an AI application that retrieves credentials from Key Vault.
You need to evaluate the security impact of each implementation approach.
What is the outcome of each approach? To answer, move the appropriate outcomes to the correct implementations. You may use each outcome once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.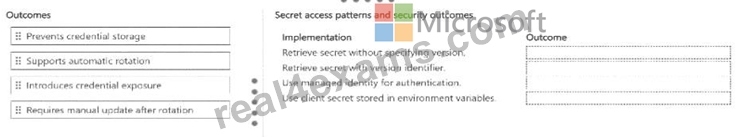
Answer:
Explanation: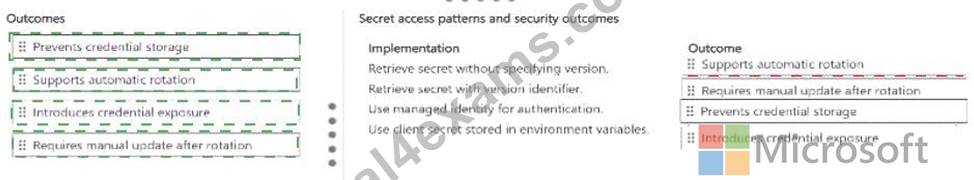
Explanation: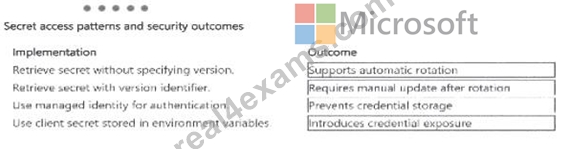
NEW QUESTION # 103
You need to configure the database resources for the Azure Database for PostgreSQL instance.
How should you complete the configuration to meet the business and technical requirements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.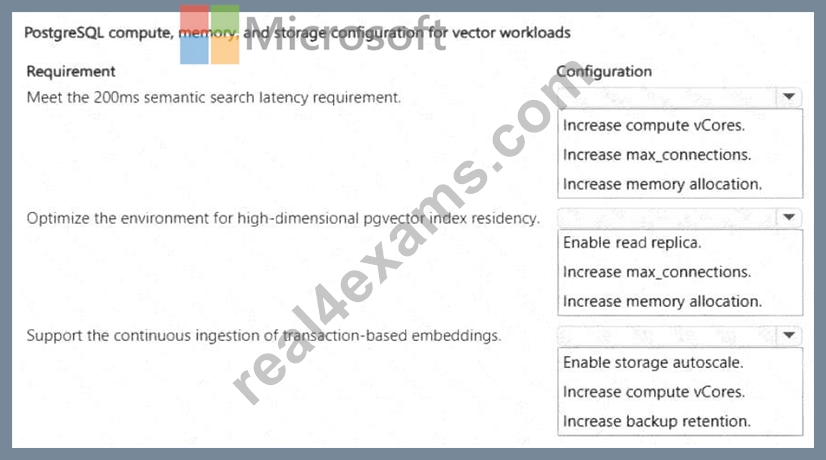
Answer:
Explanation: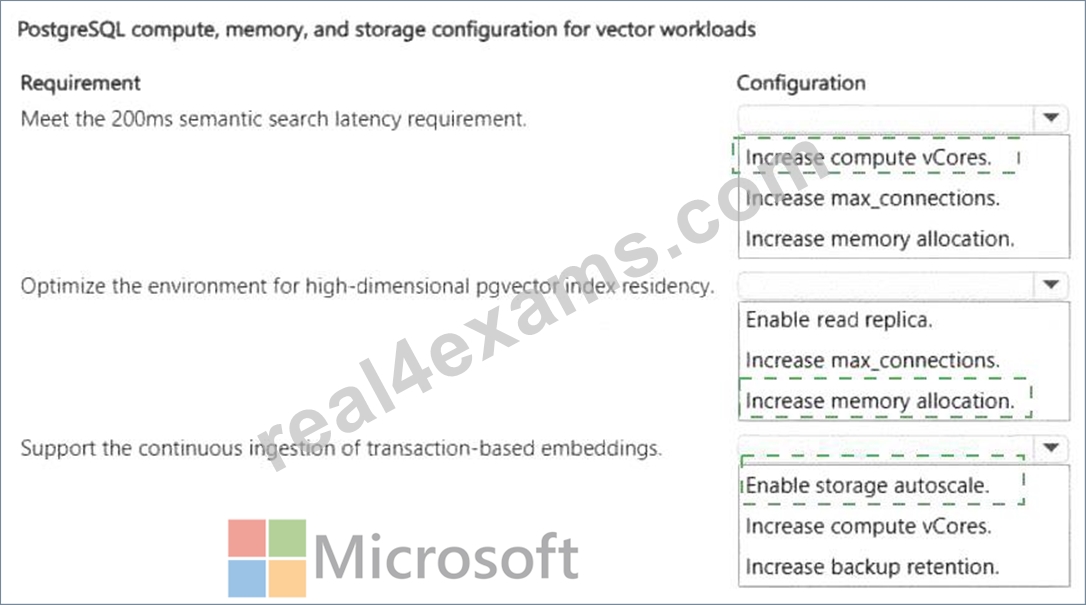
Explanation:
* Meet the 200-ms semantic search latency requirement: Increase compute vCores.
* Optimize the environment for high-dimensional pgvector index residency: Increase memory allocation.
* Support the continuous ingestion of transaction-based embeddings: Enable storage autoscale.
For the strict sub-200-ms vector-search latency target, increasing compute vCores is the appropriate choice.
Vector similarity operations are computationally intensive, and additional CPU capacity improves mathematical throughput and parallel query execution. Microsoft's pgvector guidance emphasizes query-plan optimization, ANN indexes such as HNSW, and sufficient compute resources when optimizing vector workloads.
For high-dimensional pgvector index residency , increase memory allocation . HNSW provides strong query-performance characteristics but consumes more memory than IVFFlat. Keeping frequently accessed vector index structures in memory minimizes disk access and materially improves latency. Microsoft explicitly notes that HNSW requires more memory while providing a better speed/recall tradeoff.
For the continuous ingestion of millions of embeddings, enable storage autoscale . Azure Database for PostgreSQL Flexible Server can automatically increase allocated storage as capacity approaches configured thresholds, avoiding an out-of-storage condition as data volumes grow. Microsoft recommends storage autogrow for workloads whose storage demand can increase dynamically.
Increasing max_connections does not directly improve vector computation or index residency, read replicas primarily scale reads, and backup retention does not address ingestion capacity.
Study Guide references: Azure Database for PostgreSQL Flexible Server # pgvector performance optimization; compute and memory sizing; HNSW indexing; storage autogrow.
NEW QUESTION # 104
You are implementing semantic retrieval for a chatbot.
Embeddings are already stored in Redis. However, vector similarity queries do not return matches.
You need to resolve the vector similarity search issue.
What should you do?
Answer: C
NEW QUESTION # 105
......
Real4exams is one of the leading platforms that has been helping Developing AI Cloud Solutions on Azure Exam Questions candidates for many years. Over this long time, period the Developing AI Cloud Solutions on Azure (AI-200) exam dumps helped countless Microsoft AI-200 exam questions candidates and they easily cracked their dream Developing AI Cloud Solutions on Azure (AI-200) certification exam. You can also trust Developing AI Cloud Solutions on Azure (AI-200) exam dumps and start Microsoft AI-200 exam preparation today.
AI-200 Valid Braindumps Pdf: https://www.real4exams.com/AI-200_braindumps.html