P.S. Free & New AI-300 dumps are available on Google Drive shared by Dumpkiller: https://drive.google.com/open?id=1P0ZhHqekoLnzFuua-g0N4_yYC-cZ-LyX
You can use this Microsoft AI-300 version on any operating system, and this software is accessible through any browser like Opera, Safari, Chrome, Firefox, and IE. You can easily assess yourself with the help of our AI-300 practice software, as it records all your previous results for future use.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Topic 2: Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Topic 3: Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Topic 4: Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Topic 5: Implement machine learning model lifecycle and operations | 25–30% | - Register, version, and package models
|
>> AI-300 Sample Questions Answers <<
You may doubt that how can our AI-300 exam questions be so popular and be trusted by the customers all over the world. To creat the best AI-300 study materials, our professional have been devoting all their time and efforts. They have revised and updated according to the syllabus changes and all the latest developments in theory and practice, so our AI-300 Practice Braindumps are highly relevant to what you actually need to get through the certifications tests.
NEW QUESTION # 123
A data science team plans to evaluate multiple hyperparameter values automatically while training a model in Azure Machine Learning.
The tuning process must run multiple training trials without manually modifying the training script for each run.
You need to automate hyperparameter tuning for the training job.
What should you do?
Answer: D
Explanation:
Correct:
* Create a tuning job that runs multiple trials with different parameter values To best automate hyperparameter tuning in Azure Machine Learning, you should create a Sweep Job (in SDK v2) or a HyperDrive experiment (in SDK v1).
This creates a tuning job that automatically launches multiple training trials (child runs) using your single base training script without requiring manual code modifications for each run.
Key Components to Automate the Job
To set up this job successfully using the Azure Machine Learning Python SDK v2, you will define:
Parameterized Training Script: Write your code to accept hyperparameters as command-line arguments (e.g., using Python's argparse), allowing the tuning job to pass different values to each trial.
Search Space: Define the range or specific discrete/continuous choices for the values you want to test (e.g., learning rates, batch sizes).Sampling Algorithm: Choose how Azure ML should navigate your search space. Options include Random sampling, Grid sampling (testing every possible combination), or Bayesian sampling (using previous trial results to pick the next best values).Primary Metric: Specify the performance metric your script logs (like accuracy or loss) so Azure ML knows which target to optimize.
Early Termination Policy: Optional policy (like a Bandit Policy) to automatically cancel poorly performing trials early, saving you compute time and cost.
Incorrect:
* Adjust hyperparameters after model deployment.
* Duplicate the training script for each parameter combination.
* Manually change hyperparameter values between training runs.
* Run a single training job with fixed hyperparameters.
* Select hyperparameters based only on default model settings.
Reference:
https://learn.microsoft.com/en-us/python/api/azureml-train-core/azureml.train.hyperdrive
NEW QUESTION # 124
Drag and Drop Question
You develop a Prompt flow in Microsoft Foundry project.
You plan to use variants and invoke a custom API in the flow.
You need to add tools to the flow that will implement the planned functionality. Your solution must minimize development efforts.
Which tools should you use? To answer, move the appropriate tools to the correct functionalities.
You may use each tool once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.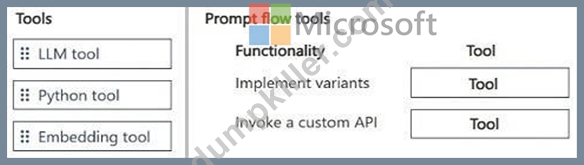
Answer:
Explanation: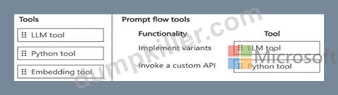
NEW QUESTION # 125
A company plans to deploy a foundation model in Microsoft Foundry.
The mode must support the following workloads:
A customer support workload used across multiple regions
A marketing workload that must remain within a specific region due to data residency requirements You need to select the deployment type.
Which deployment type should you use for each workload? To answer, move the appropriate deployment types to the correct requirements. You may use each deployment type once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content . NOTE: Each correct selection is worth one point.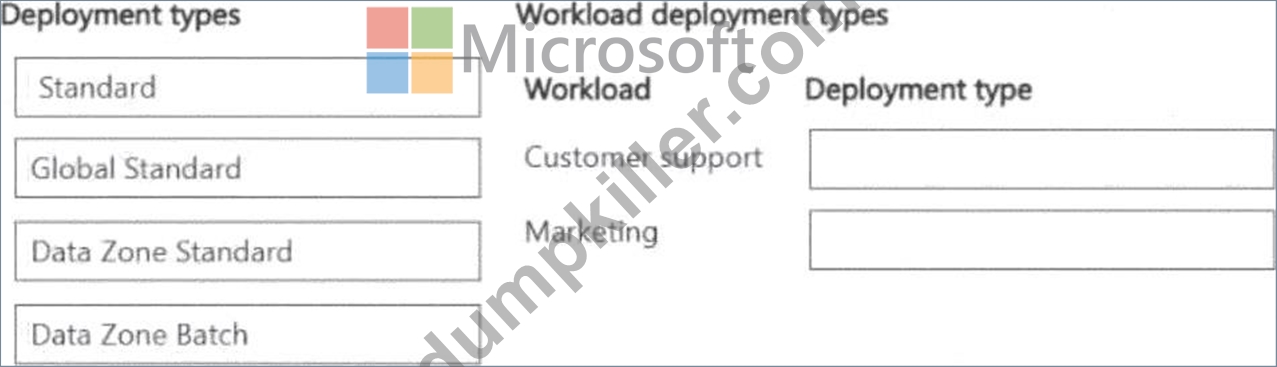
Answer:
Explanation: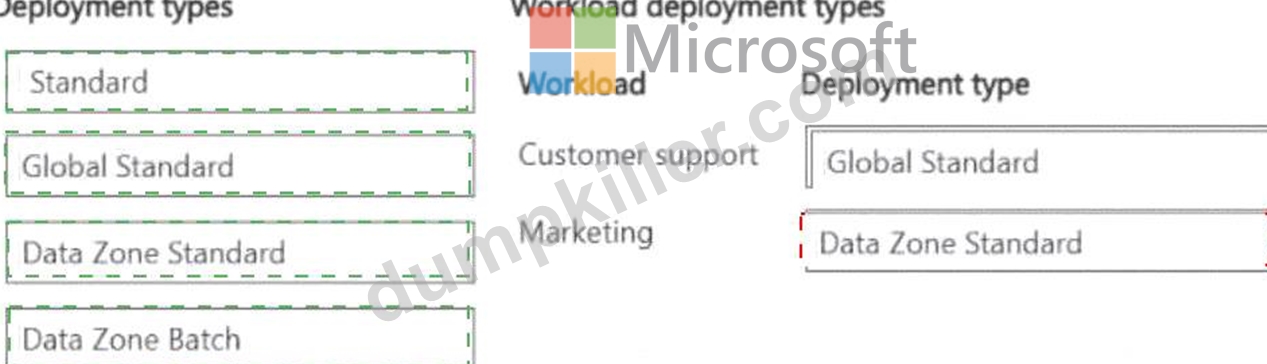
Explanation:
For a customer support workload used across multiple regions, Global Standard deployment is the right choice: it routes each request to the nearest available Azure region automatically, reducing latency globally and providing the highest throughput and availability. For a marketing workload that must remain within a specific region due to data residency requirements, a Data Zone Standard or single-region deployment ensures all compute and data processing occurs within a defined geographic boundary, satisfying GDPR and local data sovereignty rules. Microsoft Foundry ' s deployment types are designed around exactly this trade-off:
Global routing for performance-critical multi-region workloads, and Data Zone or Regional isolation for data- residency-constrained workloads. Choosing the wrong deployment type can result in either compliance violations or unnecessary latency.
Microsoft Learn Reference Topic: Model deployment options in Microsoft Foundry - Global, Data Zone, and Regional deployment types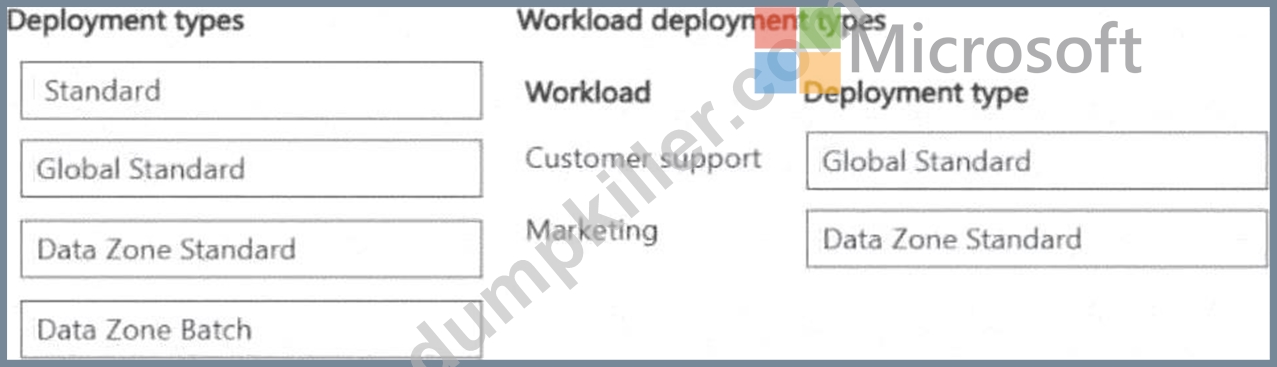
NEW QUESTION # 126
You have a deployment of an Azure OpenAI Service base model.
You plan to fine-tune the model.
You need to prepare a file that contains training data for multi-turn chat.
Which file encoding method should you use?
Answer: C
Explanation:
For preparing a multi-turn training data file for the Azure OpenAI Service, you should use UTF-8 with a Byte Order Mark (BOM) encoding.
File Format Requirements
Format: The file must be in JSON Lines (JSONL) format, where each individual line is a valid JSON object representing one training example.
Encoding: Specifically, Azure OpenAI requires the JSONL file to be encoded in UTF-8 with BOM.
Structure: For multi-turn conversations, each line must contain a messages array with multiple role ("system", "user", "assistant") and content pairs to represent the dialogue history.
Reference:
https://dev.to/icebeam7/fine-tuning-a-model-with-azure-open-ai-studio-39p7
NEW QUESTION # 127
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have an Azure Machine Learning workspace. You connect to a terminal session from the Notebooks page in Azure Machine Learning studio.
You plan to add a new Jupyter kernel that will be accessible from the same terminal session.
You need to perform the task that must be completed before you can add the new kernel.
Solution: Delete the Python 3.8 - AzureML kernel.
Does the solution meet the goal?
Answer: A
Explanation:
Correct:
* Create an environment.
Incorrect:
* Delete the Python 3.6 - AzureML kernel.
* Delete the Python 3.8 - AzureML kernel.
Note:
Before you can add a new Jupyter kernel on an Azure Machine Learning compute instance terminal, you must create a Conda environment.
Required Workflow
To officially provision and expose the new kernel to your Azure Machine Learning studio Notebooks, you need to execute the following full process from your terminal session:
Create the environment: Provision a new isolated environment (e.g., using conda create -n newenv python=3.10).
Activate the environment: Run conda activate newenv.
Install dependencies: Add the required ipykernel package using conda install ipykernel or pip install ipykernel.
Register the kernel: Bind the new environment configuration to the global Jupyter directory by running:
python -m ipykernel install --user --name newenv --display-name "My New Kernel" Reference:
https://docs.azure.cn/en-us/machine-learning/how-to-access-terminal
NEW QUESTION # 128
......
As is known to us, the high pass rate is a reflection of the high quality of AI-300 study torrent. There are more than 98 percent that passed their exam, and these people both used our AI-300 test torrent. There is no doubt that our AI-300 guide torrent has a higher pass rate than other study materials. We deeply know that the high pass rate is so important for all people, so we have been trying our best to improve our pass rate all the time. Now our pass rate has reached 99 percent. If you choose our AI-300 study torrent as your study tool and learn it carefully,
AI-300 Reliable Test Review: https://www.dumpkiller.com/AI-300_braindumps.html
DOWNLOAD the newest Dumpkiller AI-300 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1P0ZhHqekoLnzFuua-g0N4_yYC-cZ-LyX