2026 PDFExamDumps最新的Databricks-Certified-Data-Engineer-Professional PDF版考試題庫和Databricks-Certified-Data-Engineer-Professional考試問題和答案免費分享:https://drive.google.com/open?id=1sHOHHCNrlYK6l7BmqT9L-jOfY9yg_rF8
PDFExamDumps擁有一個由龐大的Databricks行業精英組成的團隊。他們都在Databricks行業中有很高的權威。他們利用專業的知識和經驗不斷地為準備參加Databricks-Certified-Data-Engineer-Professional相關認證考試的人提供培訓材料。PDFExamDumps提供的考試練習題和答案準確率很高,可以100%保證你Databricks-Certified-Data-Engineer-Professional考試一次性成功,而且還免費為你提供一年的更新服務。
| Section | Objectives |
|---|---|
| Data Ingestion and Processing | - Structured Streaming fundamentals - Batch and streaming ingestion with Auto Loader - ETL pipeline design patterns |
| Delta Lake and Data Management | - Schema evolution and enforcement - Time travel and versioning - Delta Lake transactions and ACID properties |
| Data Modeling and Transformation | - Spark SQL transformations - Performance optimization techniques - Dimensional modeling concepts |
| Databricks Lakehouse Platform Architecture | - Workspace and cluster architecture - Medallion architecture (Bronze, Silver, Gold) - Data governance concepts (Unity Catalog basics) |
| Production Pipelines and Orchestration | - Job scheduling and monitoring - Error handling and recovery strategies - Databricks Workflows |
>> Databricks-Certified-Data-Engineer-Professional考古題更新 <<
你買了PDFExamDumps的產品,我們會全力幫助你通過認證考試,而且還有免費的一年更新升級服務。如果官方改變了認證考試的大綱,我們會立即通知客戶。如果有我們的軟體有任何更新版本,都會立即推送給客戶。PDFExamDumps是可以承諾幫你成功通過你的第一次Databricks Databricks-Certified-Data-Engineer-Professional 認證考試。
問題 #231
A nightly job ingests data into a Delta Lake table using the following code: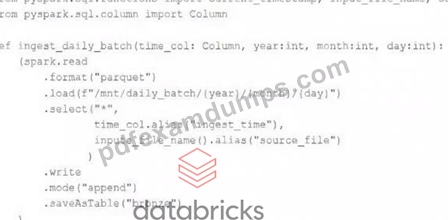
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
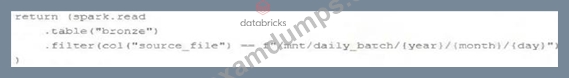
答案:A
解題說明:
https://docs.databricks.com/en/delta/delta-change-data-feed.html
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
問題 #232
A developer has successfully configured their credentials for Databricks Repos and cloned a remote Git repository. They do not have privileges to make changes to the main branch, which is the only branch currently visible in their workspace. Which approach allows this user to share their code updates without the risk of overwriting the work of their teammates?
答案:C
解題說明:
In Databricks Repos, when a user does not have privileges to make changes directly to the main branch of a cloned remote Git repository, the recommended approach is to create a new branch within the Databricks workspace. The developer can then make changes in this new branch, commit those changes, and push the new branch to the remote Git repository. This workflow allows for isolated development without affecting the main branch, enabling the developer to propose changes via a pull request from the new branch to the main branch in the remote repository. This method adheres to common Git collaboration workflows, fostering code review and collaboration while ensuring the integrity of the main branch.
問題 #233
Which statement describes the correct use of pyspark.sql.functions.broadcast?
答案:B
解題說明:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
問題 #234
A data engineering team needs to create a SQL Alert that monitors data quality across multiple columns in their customer table. They want to trigger an alert when both the percentage of customers with missing email addresses exceeds 15% AND the percentage of customers with invalid phone number formats exceeds 10%. Which SQL query pattern is appropriate for implementing this multi-column alert condition?
答案:D
解題說明:
This pattern computes independent percentage metrics for each data quality condition in a single aggregated query. By calculating the percentage of missing emails and invalid phone formats as separate columns, it enables the SQL Alert to evaluate a compound condition where both thresholds must be exceeded before triggering.
問題 #235
A new data engineer notices that a critical field was omitted from an application that writes its Kafka source to Delta Lake. This happened even though the critical field was in the Kafka source.
That field was further missing from data written to dependent, long-term storage. The retention threshold on the Kafka service is seven days. The pipeline has been in production for three months.
Which describes how Delta Lake can help to avoid data loss of this nature in the future?
答案:E
解題說明:
This is the correct answer because it describes how Delta Lake can help to avoid data loss of this nature in the future. By ingesting all raw data and metadata from Kafka to a bronze Delta table, Delta Lake creates a permanent, replayable history of the data state that can be used for recovery or reprocessing in case of errors or omissions in downstream applications or pipelines.
Delta Lake also supports schema evolution, which allows adding new columns to existing tables without affecting existing queries or pipelines. Therefore, if a critical field was omitted from an application that writes its Kafka source to Delta Lake, it can be easily added later and the data can be reprocessed from the bronze table without losing any information.
問題 #236
......
在當今這個社會,人才到處都是。在IT領域更是這樣。隨著電腦的普及,已經幾乎沒有不會使用電腦的人了。同樣在IT行業工作的你難道沒有感覺到壓力嗎?不管你的學歷有多高都不能代表你的實力。學歷只是一個敲門磚,真正能保住你地位的是你的實力。作為IT職員,你是怎麼培養自己的實力的呢?參加IT認證考試是一個不錯的選擇。既可以掌握更多的技能,又可以取得可以證明自己能力的認證資格。最近Databricks的Databricks-Certified-Data-Engineer-Professional認證考試很受歡迎,想參加嗎?
Databricks-Certified-Data-Engineer-Professional證照: https://www.pdfexamdumps.com/Databricks-Certified-Data-Engineer-Professional_valid-braindumps.html
P.S. PDFExamDumps在Google Drive上分享了免費的、最新的Databricks-Certified-Data-Engineer-Professional考試題庫:https://drive.google.com/open?id=1sHOHHCNrlYK6l7BmqT9L-jOfY9yg_rF8