2026 Latest PrepAwayETE DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=1c13qaZf9Zucoj6ri4VQ5FNG6Gp7SsD7J
If you are worried about that if you fail to pass the exam and will waste your money, if you choose us, there is no need for you to worry about this. We ensure that if you fail to pass your exam by using DP-750 exam materials of us, we will give you full refund, and no other questions will be asked. Besides, we offer you free update for one year, that is to say, there is no need for you to spend extra money on updating. The update version for DP-750 Exam Braindumps will be sent to you automatically. You just need to check your mail and change your learning methods in accordance with new changes.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Topic 2: Prepare and process data | 30-35% | - Data ingestion
|
| Topic 3: Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Topic 4: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
>> Certification DP-750 Book Torrent <<
Our PDF version of our DP-750 exam practice guide is convenient for the clients to read and supports the printing. If the clients use our PDF version they can read the PDF form conveniently and take notes. The DP-750 quiz prep can be printed onto the papers. If the clients need to take note of the important information they need they can write them on the papers to be convenient for reading or print them on the papers. The clients can read our DP-750 Study Materials in the form of PDF or on the printed papers. Thus the clients learn at any time and in any place and practice the DP-750 exam practice guide repeatedly.
NEW QUESTION # 75
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to create an external volume named Volume1 in an existing schema. Volume1 must expose files from an Azure Storage container. The solution must meet the following requirements:
* Ensure that authentication does NOT require storing credentials in Databricks
* Ensure that users can access the files, but NOT modify the files.
* Follow the principle of least privilege
Which type of authentication should you configure, and which permission should you grant to the users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.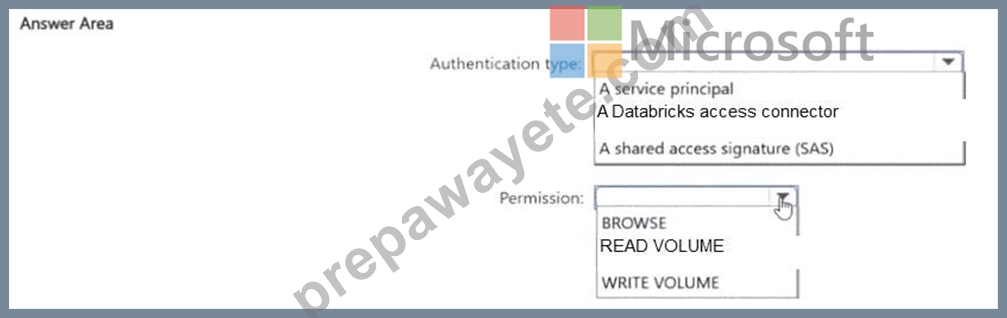
Answer:
Explanation: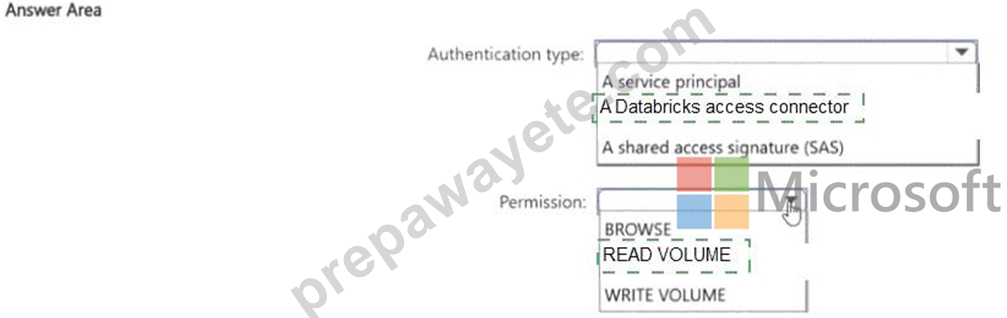
Explanation:
For authentication, a Managed Identity (via a Databricks Access Connector) is the right choice. The Access Connector wraps an Azure-managed identity so Databricks can authenticate to Azure Storage without any credentials being stored in the workspace. The cloud security team controls the identity through Azure RBAC
- there are no secrets to rotate or leak inside Databricks.
For the permission, READ FILES on the volume is exactly right. It allows users to read and list files through the volume path while blocking writes, deletes, and modifications. This is the minimum necessary access, honouring the principle of least privilege.
WRITE FILES would allow modifications, contradicting 'users can access but NOT modify.' ALL PRIVILEGES grants far more than needed. Service principals with stored client secrets would mean credentials inside Databricks, violating the 'does not require storing credentials' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/volumes
NEW QUESTION # 76
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a Lakeflow Connect pipeline and connect it to DB1. Does this meet the goal?
Answer: A
Explanation:
The correct answer is B - No.
Lakeflow Connect is an ingestion service that physically copies data from external databases into Delta tables managed by Databricks. It's designed for scenarios where you want a replicated, writable Delta copy of external data - essentially a CDC-based ingestion pipeline.
That's the opposite of what's required here. The requirement states 'the data is NOT copied into Databricks- managed storage.' Lakeflow Connect would create Delta tables in Databricks and copy DB1's data into them
- a direct violation.
Additionally, Lakeflow Connect creates Databricks-native Delta tables rather than exposing DB1's original schemas and tables as virtual objects. Analysts querying through a Lakeflow Connect pipeline are querying a replicated copy, not the live source.
For zero-copy, live query federation of an external SQL Server into Unity Catalog, Lakehouse Federation (foreign catalog) is the correct tool.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/lakeflow-connect/
NEW QUESTION # 77
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Tabid.
Table! is written by batch jobs every hour and is queried frequently by filtering two columns named Customerld and EventDate.
You expect Table1 to grow significantly over time.
The rows in Table1 are frequently updated and deleted to support compliance requests.
You need to keep query performance consistent as Table1 grows. The solution must minimize update and deletion effort.
What should you include in the solution? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.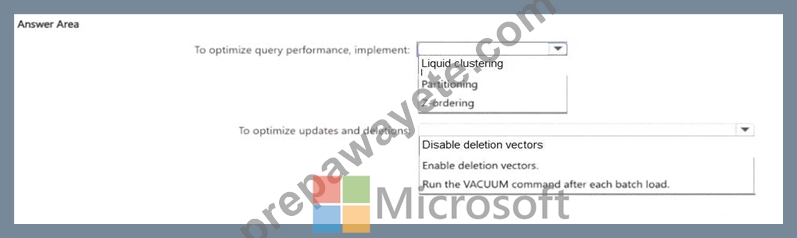
Answer:
Explanation: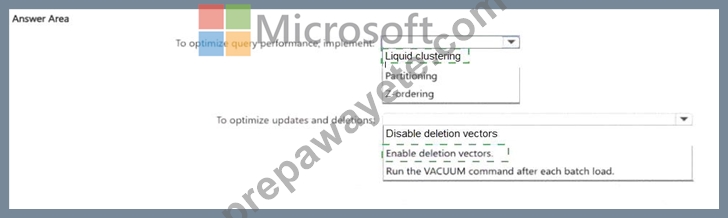
Explanation:
Two features work together to keep performance consistent and update costs low:
OPTIMIZE with ZORDER BY (CustomerId, EventDate). Z-Ordering co-locates rows with the same CustomerId and EventDate values in the same Parquet files. When a query filters on those columns, the Delta engine uses file statistics to skip files that can't possibly contain matching rows (data skipping). As the table grows, skipping scales proportionally - query time stays consistent.
Deletion Vectors (delta.enableDeletionVectors = true). When a row is updated or deleted, instead of rewriting the entire Parquet file, Delta marks the affected row in a small companion deletion vector file. This dramatically reduces write amplification for the frequent compliance-driven updates and deletions the question describes. Actual file rewrites are deferred to the next OPTIMIZE run.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/data-skipping
NEW QUESTION # 78
You need to deploy Databricks Asset Bundles to a development environment. The solution must support automated and repeatable deployments across environments.
What should you use?
Answer: B
Explanation:
The correct answer is C - the Databricks CLI.
Databricks Asset Bundles are deployed using the Databricks CLI (v0.205+) with the commands databricks bundle validate, databricks bundle deploy, and databricks bundle run. The CLI reads the databricks.yml file, resolves the target environment settings, and creates or updates all declared resources (jobs, pipelines, apps) in the workspace. This is the documented, supported deployment mechanism for DABs and integrates naturally into CI/CD pipelines.
Option A (Azure Developer CLI / azd) is a general Azure IaC tool with no native understanding of Databricks bundles. Option B (Git folders) syncs notebook and file content from a Git repository into a workspace - useful for code, but it doesn't deploy Lakeflow Jobs, SDP pipelines, or bundle configurations. Option D (Azure CLI) manages Azure infrastructure (resource groups, storage accounts, etc.) and has no native DAB deployment support.
Reference: https://learn.microsoft.com/en-us/azure/databricks/dev-tools/bundles/deploy-bundle
NEW QUESTION # 79
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1.
You need to meet the following requirements:
- Records that violate rule1 must NOT be written to Table1, but the
pipeline must continue processing valid records.
- Data engineers must be able to review expectation metrics by using
minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.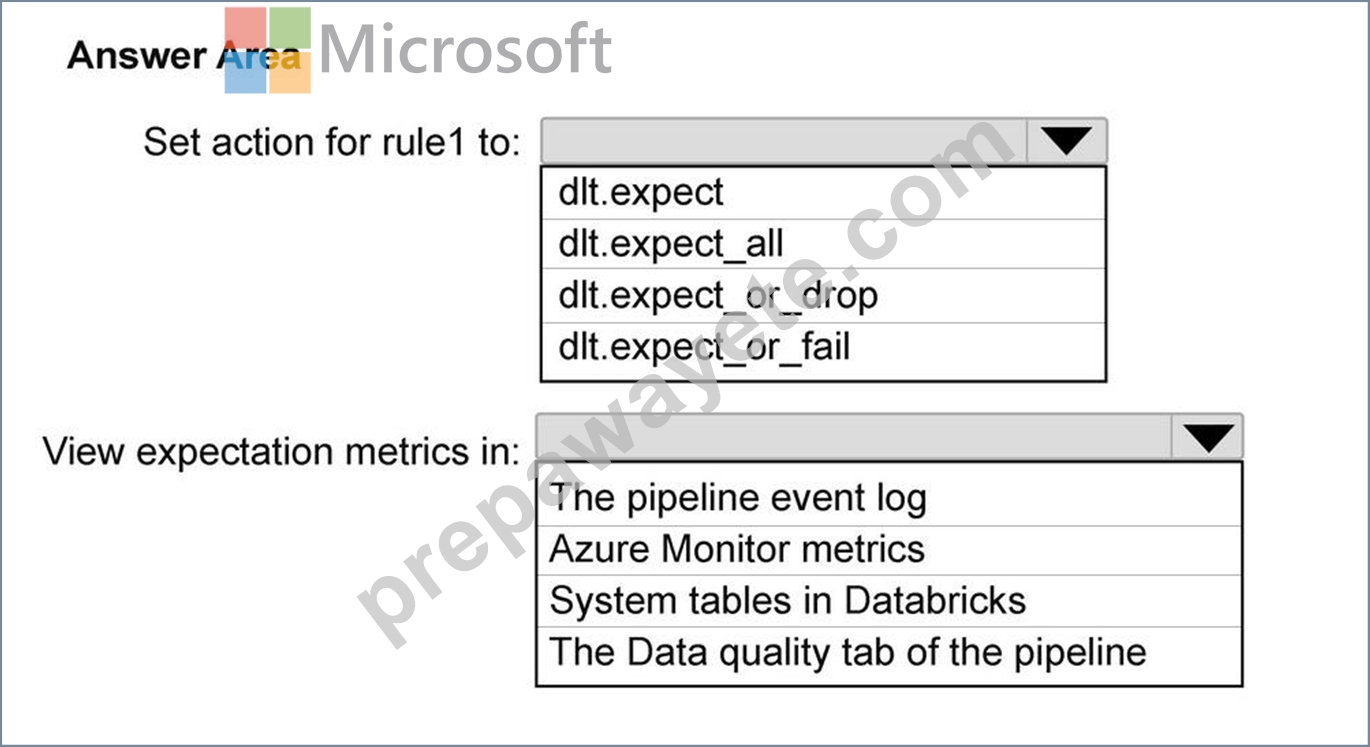
Answer:
Explanation: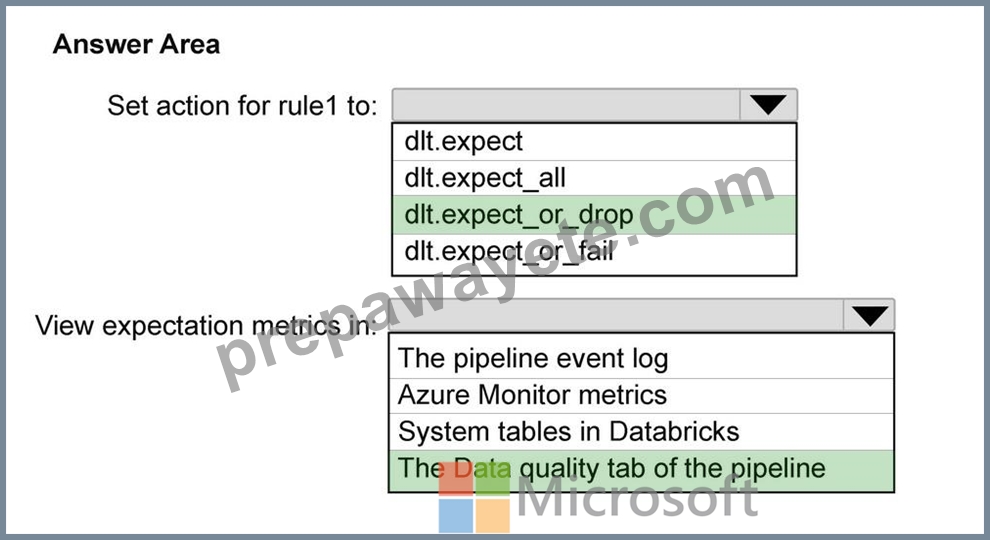
NEW QUESTION # 80
......
Our DP-750 study materials have designed three different versions for all customers to choose. The three different versions include the PDF version, the software version and the online version, they can help customers solve any questions and meet their all needs. Although the three different versions of our DP-750 Study Materials provide the same demo for all customers, they also have its particular functions to meet different the unique needs from all customers. The most important function of the online version of our DP-750 study materials is the practicality.
Printable DP-750 PDF: https://www.prepawayete.com/Microsoft/DP-750-practice-exam-dumps.html
BONUS!!! Download part of PrepAwayETE DP-750 dumps for free: https://drive.google.com/open?id=1c13qaZf9Zucoj6ri4VQ5FNG6Gp7SsD7J