Databricks-Machine-Learning-Professional試験資料 & Databricks-Machine-Learning-Professionalテスト内容

P.S.CertJukenがGoogle Driveで共有している無料の2026 Databricks Databricks-Machine-Learning-Professionalダンプ:https://drive.google.com/open?id=1286JGiNBiW8zVWdBTBWwt1DoqcHKwN-2
チャンスはいつも準備がある人のために存在しています。IT業界で就職する前に、あなたはDatabricksのDatabricks-Machine-Learning-Professional試験に合格したら、あなたに満足させる仕事を探す準備をよくしました。DatabricksのDatabricks-Machine-Learning-Professional試験に合格しがたいですが、我々CertJukenの提供するDatabricksのDatabricks-Machine-Learning-Professional試験の資料を通して多くの人は試験に合格しました。あなたはその中の一員になりたいですか。我々の商品にあなたを助けさせましょう。
Databricks Databricks-Machine-Learning-Professional Exam Overview:
| Certification Vendor: | Databricks |
|---|
| Exam Name: | Databricks Certified Machine Learning Professional |
|---|
| Exam Number: | Databricks-Machine-Learning-Professional |
|---|
| Related Certifications: | Databricks Certified Machine Learning Associate |
|---|
| Exam Price: | $200 USD |
|---|
| Passing Score: | Not publicly disclosed |
|---|
| Real Exam Qty: | Approximately 45–60 |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Exam Duration: | 120 minutes |
|---|
| Available Languages: | English |
|---|
| Exam Format: | Multiple choice, Scenario-based questions, Multiple select |
|---|
| Recommended Training: | Databricks Academy Machine Learning Training |
|---|
| Exam Registration: | Databricks Certification Portal |
|---|
| Sample Questions: | Databricks Databricks-Machine-Learning-Professional Sample Questions |
|---|
| Exam Way: | Online proctored exam (typically delivered via Databricks certification partners such as Certiverse or Pearson VUE depending on region and current program structure) |
|---|
| Pre Condition: | Recommended experience with Databricks platform and machine learning workflows; Databricks Certified Machine Learning Associate certification is often recommended but not strictly required. |
|---|
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
|---|
>> Databricks-Machine-Learning-Professional試験資料 <<
Databricks Databricks-Machine-Learning-Professionalテスト内容 & Databricks-Machine-Learning-Professional受験資料更新版
私たちは本当にお客様の貴重な意見をDatabricks-Machine-Learning-Professional試験資料の作りの考慮に入れます。おそらく、君たちは私たちのDatabricks-Machine-Learning-Professional試験資料について何も知らないかもしれません。でも、私たちのDatabricks-Machine-Learning-Professional試験資料のデモをダウンロードしてみると、全部わかるようになります。そのデモはDatabricks-Machine-Learning-Professional試験資料の一部を含めています。
Databricks Databricks-Machine-Learning-Professional 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - 各段階のモデル サービングのデプロイとエンドポイントを説明する
- 機能ドリフトやラベル ドリフトが発生する可能性があるシナリオを特定する
|
| トピック 2 | - 構造化ストリーミングではデータが順不同で到着する可能性があることを特定する
- モデル サービングがモデルのデプロイメントに 1 つの汎用クラスターをどのように使用するかを特定する
|
| トピック 3 | - 他のユースケースのソリューションとしてパフォーマンスの低いデータ ストレージを特定する
- ストリーミング展開で複雑なビジネス ロジックを処理する必要がある理由を説明する
|
| トピック 4 | - ネストされた実行を追跡するための要件を特定する
- MLflow フレーバーと MLflow フレーバーを使用する利点について説明する
|
| トピック 5 | - 更新されたモデルのパフォーマンスがより最近のデータで向上するかどうかをテストする
- 更新されたモデルを再トレーニングしてデプロイすることがドリフトの解決策となる可能性がある時期を特定する
|
| トピック 6 | - リアルタイム展開の必要性として JIT 機能の値を特定する
- すべての Webhook を一覧表示する方法と Webhook を削除する方法を説明する
|
| トピック 7 | - 概念ドリフトとそのモデル有効性への影響について説明する
- 数値特徴量ドリフトに対する簡単なソリューションとして概要統計モニタリングについて説明する
|
| トピック 8 | - 事前計算されたバッチ予測をクエリすることのライブ サービングの利点を特定する
- ETL パイプラインの一般的な処理ツールとしての構造化ストリーミングについて説明する
|
| トピック 9 | - pyfunc MLflow フレーバーを使用する利点について説明する
- MLflow を使用してパラメーター、モデル、評価メトリクスを手動でログに記録する
|
Databricks Certified Machine Learning Professional 認定 Databricks-Machine-Learning-Professional 試験問題 (Q150-Q155):
質問 # 150
A machine learning engineer has developed the following custom model class with preprocessing logic to combine two columns:
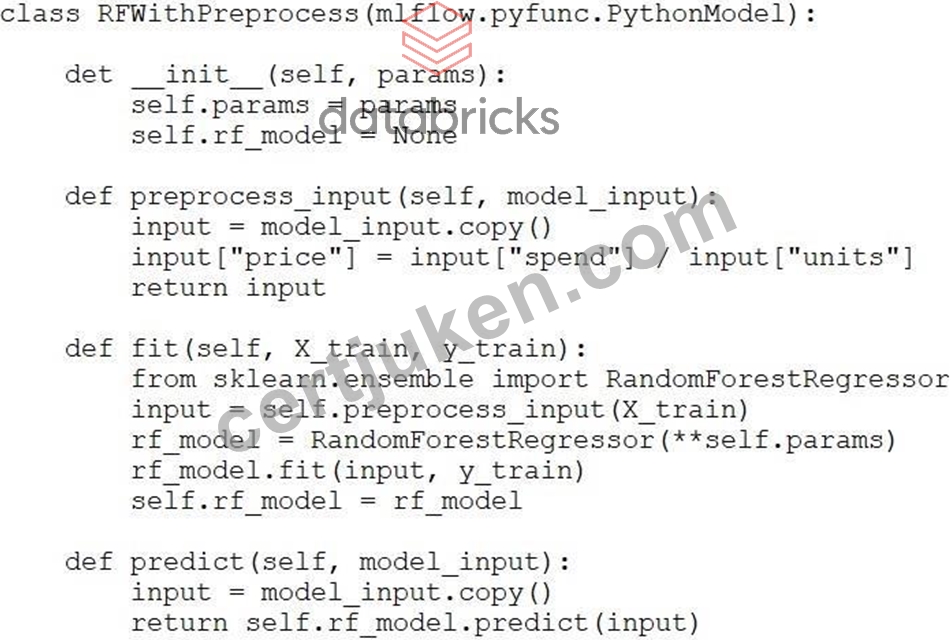
However, instances of this class are unable to compute predictions.
Which set of changes will update the class so predictions can be computed while continuing to apply the preprocessing logic?
- A. Remove the self.rf_model = rf_model line from the fit method
- B. Replace model_input.copy() with self.preprocess_input(model_input.copy()) in the preprocess_input method
- C. Replace self.rf_model.predict(input) with self.predict(input) in the predict method
- D. Replace model_input.copy() with self.preprocess_input(model_input.copy()) in the predict method
正解:D
解説:
The issue is that the predict() method does not apply the same preprocessing as the fit() method.
During training, the model uses preprocessed data (via self.preprocess_input()), but during prediction, it directly uses raw input. This mismatch causes prediction errors because the model expects preprocessed input.
By updating the predict() method to call self.preprocess_input(model_input.copy()), both training and prediction use consistent feature transformations, allowing predictions to be computed successfully.
質問 # 151
A machine learning engineer is in the process of implementing a feature drift monitoring solution.
They are planning to use the following steps:
1. Measure the distributions of each feature variable in the training
set
2. Deploy a model to production
3. Measure the distributions of each feature variable in inference
4. _______
Which action should be completed as Step #4?
- A. Measure the latency of the model's prediction time
- B. Run a statistical test to determine if there are changes in the feature variable distribution over time
- C. Obtain the observed values (actual) feature values and compare to the predicted values
- D. Retrain the model based on any new feature variables that have been added to the feature set
正解:B
解説:
The final step in a feature drift monitoring solution is to run a statistical test (e.g., Kolmogorov- Smirnov test) to determine whether the feature distributions in production have significantly diverged from those in the training set. This helps detect drift and maintain model reliability.
質問 # 152
A data scientist has developed a scikit-learn random forest model model, but they have not yet logged model with MLflow. They have created a model signature model_signature and a few example input records input_records. Which block of code can be used to log all of this information?
- A. There is no way to log a model signature.
- B. mlflow.sklearn.log_model(model, "model")
mlflow.log_signature(model_signature)
mlflow.log_input(input_records) - C.
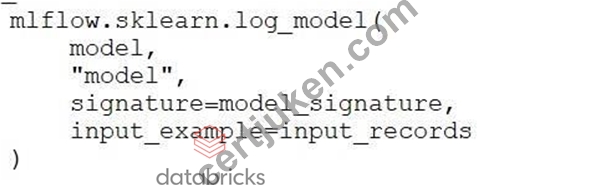
- D.
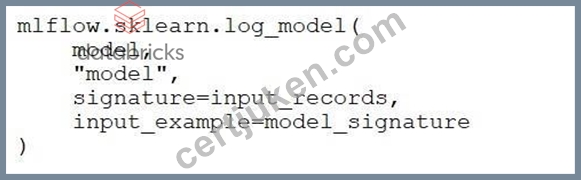
正解:C
解説:
The code block correctly uses the mlflow.sklearn.log_model() function with both signature and input_example parameters.
signature=model_signature defines the expected model input and output schema, ensuring reproducibility and validation during inference.
input_example=input_records provides a sample input that helps users understand the model's expected input format.
質問 # 153
A machine learning engineer has implemented a numeric drift monitoring solution by examining trends in the summary statistics of input variables. However, the engineer's stakeholders would like a more robust monitoring solution. Which of the following can provide a more robust drift monitoring solution for numeric feature variables?
- A. None of these can provide more robust drift monitoring than summary statistics
- B. Statistical tests
- C. Oversampling
- D. Correlations
正解:B
解説:
Statistical tests (such as the Kolmogorov-Smirnov test or Wasserstein distance) provide a more robust and quantitative method for detecting numeric feature drift compared to simple summary statistics. These tests compare the full distributions of features between datasets, making them more sensitive to subtle changes in data behavior over time.
質問 # 154
A Machine Learning Engineer has a large dataset with a customer_region column and wants to train separate models for each region, then generate predictions. They need to parallelize this group-specific model training process using Databricks and the Pandas Function API. Which approach will implement this solution?
- A. Use mapInPandas() to apply the training function across all partitions without grouping.
- B. Use groupBy("customer_region") and apply a training function with applyInPandas().
- C. Use foreachBatch() to sequentially process each region's data.
- D. Use collect() to gather all data and process regions using standard pandas groupby.
正解:B
解説:
The Pandas Function API supports parallel, group-specific processing by using groupBy on the grouping column and applyInPandas to execute a custom training function independently for each group. This enables separate models to be trained per region in parallel across the cluster, with each function invocation receiving only the data for its group.
質問 # 155
......
Databricks-Machine-Learning-Professionalテスト内容: https://www.certjuken.com/Databricks-Machine-Learning-Professional-exam.html
- Databricks-Machine-Learning-Professional試験の準備方法|検証するDatabricks-Machine-Learning-Professional試験資料試験|便利なDatabricks Certified Machine Learning Professionalテスト内容 🍲 ⇛ jp.fast2test.com ⇚は、⏩ Databricks-Machine-Learning-Professional ⏪を無料でダウンロードするのに最適なサイトですDatabricks-Machine-Learning-Professional技術試験
- 試験の準備方法-高品質なDatabricks-Machine-Learning-Professional試験資料試験-100%合格率のDatabricks-Machine-Learning-Professionalテスト内容 🤼 サイト⏩ www.goshiken.com ⏪で《 Databricks-Machine-Learning-Professional 》問題集をダウンロードDatabricks-Machine-Learning-Professional試験問題
- Databricks-Machine-Learning-Professionalソフトウエア ⏳ Databricks-Machine-Learning-Professional試験概要 🕗 Databricks-Machine-Learning-Professional試験問題 ⛽ ▶ www.passtest.jp ◀で使える無料オンライン版▶ Databricks-Machine-Learning-Professional ◀ の試験問題Databricks-Machine-Learning-Professional日本語版問題解説
- Databricks-Machine-Learning-Professionalトレーニング資料、Databricks-Machine-Learning-Professional学習資料、Databricks-Machine-Learning-Professional試験問題集 🏳 最新【 Databricks-Machine-Learning-Professional 】問題集ファイルは✔ www.goshiken.com ️✔️にて検索Databricks-Machine-Learning-Professional日本語版問題解説
- Databricks-Machine-Learning-Professional合格記 💨 Databricks-Machine-Learning-Professional無料サンプル 🎅 Databricks-Machine-Learning-Professionalトレーニング費用 🐫 ➡ www.mogiexam.com ️⬅️を開き、⇛ Databricks-Machine-Learning-Professional ⇚を入力して、無料でダウンロードしてくださいDatabricks-Machine-Learning-Professionalソフトウエア
- Databricks-Machine-Learning-Professional関連試験 🤟 Databricks-Machine-Learning-Professional日本語認定 🍚 Databricks-Machine-Learning-Professional赤本勉強 🩳 ▛ www.goshiken.com ▟から簡単に【 Databricks-Machine-Learning-Professional 】を無料でダウンロードできますDatabricks-Machine-Learning-Professional試験概要
- Databricks-Machine-Learning-Professional関連試験 🩸 Databricks-Machine-Learning-Professional専門知識内容 🚊 Databricks-Machine-Learning-Professional専門知識内容 👗 ➠ www.passtest.jp 🠰にて限定無料の➽ Databricks-Machine-Learning-Professional 🢪問題集をダウンロードせよDatabricks-Machine-Learning-Professional日本語認定
- Databricks-Machine-Learning-Professional問題無料 🚞 Databricks-Machine-Learning-Professional技術試験 🙊 Databricks-Machine-Learning-Professionalトレーニング費用 🙉 サイト✔ www.goshiken.com ️✔️で“ Databricks-Machine-Learning-Professional ”問題集をダウンロードDatabricks-Machine-Learning-Professionalトレーニング費用
- Databricks-Machine-Learning-Professional日本語版対応参考書 🌖 Databricks-Machine-Learning-Professional日本語認定 😁 Databricks-Machine-Learning-Professional赤本勉強 👜 最新【 Databricks-Machine-Learning-Professional 】問題集ファイルは▶ www.passtest.jp ◀にて検索Databricks-Machine-Learning-Professional赤本勉強
- Databricks-Machine-Learning-Professional専門知識内容 🥶 Databricks-Machine-Learning-Professional試験問題 😐 Databricks-Machine-Learning-Professional日本語版問題解説 🏯 ⏩ www.goshiken.com ⏪を入力して▷ Databricks-Machine-Learning-Professional ◁を検索し、無料でダウンロードしてくださいDatabricks-Machine-Learning-Professional技術試験
- 試験の準備方法-一番優秀なDatabricks-Machine-Learning-Professional試験資料試験-最新のDatabricks-Machine-Learning-Professionalテスト内容 ☣ URL ☀ www.jpexam.com ️☀️をコピーして開き、✔ Databricks-Machine-Learning-Professional ️✔️を検索して無料でダウンロードしてくださいDatabricks-Machine-Learning-Professional日本語版対応参考書
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
P.S. CertJukenがGoogle Driveで共有している無料かつ新しいDatabricks-Machine-Learning-Professionalダンプ:https://drive.google.com/open?id=1286JGiNBiW8zVWdBTBWwt1DoqcHKwN-2