P.S. Free 2026 Snowflake DAA-C01 dumps are available on Google Drive shared by Dumps4PDF: https://drive.google.com/open?id=1lsfcSJG2ZyVfZkzTrEXy8-PHc4xYk3jq
We assume all the responsibilities that our practice materials may bring. They are a bunch of courteous staff waiting for offering help 24/7. You can definitely contact them when getting any questions related with our DAA-C01 practice materials. If you haplessly fail the exam, we treat it as our responsibility then give you full refund and get other version of practice material for free. That is why we win a great deal of customers around the world. Especially for those time-sensitive and busy candidates, all three versions of DAA-C01 practice materials can be chosen based on your preference. Such as app version, you can learn it using your phone everywhere without the limitation of place or time.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Build and Troubleshoot Advanced SQL Queries | 20–25% | - Complex joins, subqueries, window functions - Query optimization and troubleshooting - Semi-structured data processing |
| Topic 2: Perform Predictive Analysis | 5–10% | - Forecasting and predictive modeling - Using Snowflake ML and built-in analytics |
| Topic 3: Perform Descriptive and Diagnostic Analysis | 10–15% | - Exploratory and ad-hoc analysis - Anomaly detection and root cause analysis - Statistical summarization and trend analysis |
| Topic 4: Use Built-in Functions and Create UDFs | 10–15% | - User-Defined Functions (UDFs) - Scalar, aggregate, table, system functions |
| Topic 5: Prepare and Load Data | 15–20% | - Data ingestion methods: COPY INTO, stages, Snowpipe - External tables and data validation - File formats: CSV, JSON, Parquet, Avro |
| Topic 6: Prepare and Present Data | 10–15% | - Snowsight dashboards and sharing results - Data visualization and reporting - Align outputs with business requirements |
| Topic 7: Perform Simple Data Transformations for Analysis | 15–20% | - Data cleansing, standardization, type conversion - Handling NULLs and structuring datasets - Views, materialized views, CTEs |
>> DAA-C01 Reliable Exam Review <<
When we are in some kind of learning web site, often feel dazzling, because web page design is not reasonable, put too much information all rush, it will appear desultorily. Absorbing the lessons of the DAA-C01 test prep, will be all kinds of qualification examination classify layout, at the same time on the front page of the DAA-C01 test materials have clear test module classification, so clear page design greatly convenient for the users, can let users in a very short period of time to find what they want to study, and then targeted to study. Saving the precious time users already so, also makes the DAA-C01 Quiz torrent look more rich, powerful strengthened the practicability of the products, to meet the needs of more users, to make the DAA-C01 test prep stand out in many similar products.
NEW QUESTION # 40
You are working with a Snowflake table 'ORDERS that contains order data in a VARIANT column named 'ORDER DETAILS'. The 'ORDER DETAILS column contains JSON objects with nested arrays of product information, including 'product_id', 'quantity', and 'price'. You need to calculate the total revenue for each order. Which of the following SQL snippets correctly calculates the total revenue for each order using LATERAL FLATTEN and aggregation?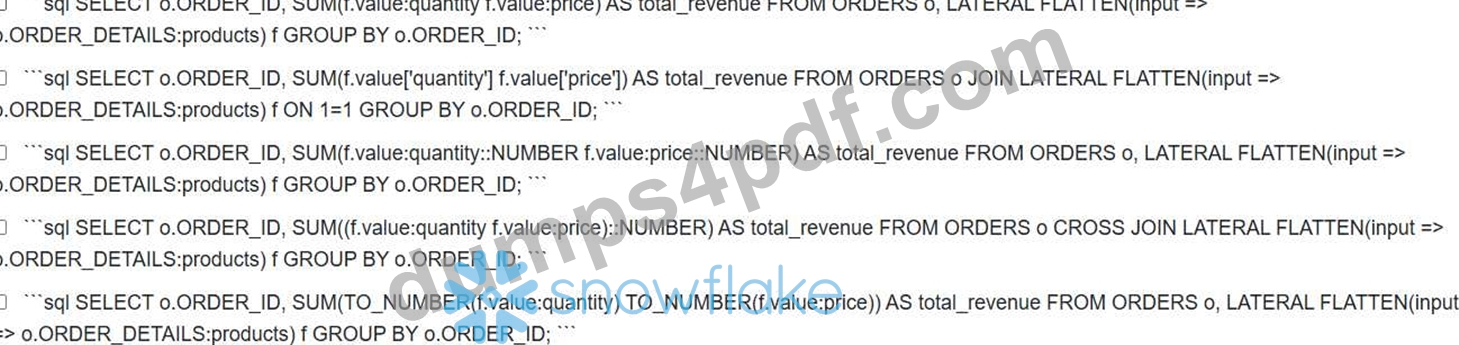
Answer: D,E
Explanation:
Snowflake requires explicit casting to numeric datatypes when performing arithmetic operations on VARIANT data. Options A and B do not cast the 'quantity' and 'price' fields to numbers, which would result in incorrect calculations. Option E uses a deprecated ' TO_NUMBER function.
NEW QUESTION # 41
How do partitioning strategies impact query performance and data storage efficiency in Snowflake?
Answer: D
Explanation:
Effective partitioning strategies enhance query performance by optimizing data retrieval and storage efficiency in Snowflake.
NEW QUESTION # 42
You are troubleshooting a slow-running query that performs a complex transformation on a large dataset using a series of CTEs. You've identified one particular CTE, , as contributing significantly to the overall execution time. Examination of the query profile reveals high spillover to local storage during the execution of this CTE. Which of the following actions could potentially reduce spillover and improve the performance of the CTE? Select all that apply.
Answer: D,E
Explanation:
Increasing the warehouse size (A) provides more memory, which directly reduces spillover. Rewriting the CTE to use smaller intermediate tables (C) reduces the memory footprint of the operation. Partitioning the tables (B) is not directly supported in Snowflake. Creating a materialized view from the CTE (D) can improve performance if the CTE's results are frequently reused, but it does not necessarily address the spillover issue directly. Reducing the 'MAX (E) would worsen spillover. Using temporary tables (E) will not necessarily impact spilling if the memory limits are still exceeded within the query runtime.
NEW QUESTION # 43
A Data Analyst needs to write a query that will return all projects from a project table and all employees from an employee table. What type of join should be used in this query?
Answer: B
Explanation:
In Data Transformation and Data Modeling, selecting the correct join type determines how the query handles unmatched records from the participating tables. The requirement here is to return all records from both the projects table and the employee table.
A FULL OUTER JOIN (often shortened to FULL JOIN) is designed specifically for this purpose. It combines the results of both a LEFT OUTER JOIN and a RIGHT OUTER JOIN. It returns:
* Rows where there is a match between the project and the employee.
* Rows from the projects table that have no matching employees (padded with NULL in the employee columns).
* Rows from the employees table that are not assigned to any projects (padded with NULL in the project columns).
Evaluating the Options:
* Option A (INNER JOIN) only returns rows where there is a match in both tables. Any projects without employees or employees without projects would be excluded.
* Option C (LEFT OUTER JOIN) would return all projects, but would exclude employees who are not assigned to a project.
* Option D (CROSS JOIN) creates a Cartesian product, matching every single employee with every single project regardless of actual relationships. This would create a massive, redundant dataset and is not what is requested.
* Option B is the 100% correct answer. It ensures total data visibility from both entities, which is often required in data quality audits or comprehensive resource allocation reporting where the analyst needs to see "unlinked" data on both sides of the relationship.
NEW QUESTION # 44
A data analyst is tasked with optimizing a daily ETL pipeline that loads data from several external sources into a Snowflake data warehouse. One of the key transformations involves joining two large tables, 'ORDERS' (millions of rows) and 'CUSTOMERS' (hundreds of thousands of rows), based on 'CUSTOMER ID. The pipeline currently uses a standard 'JOIN' operation, but the transformation step is taking longer than expected. The analyst has explored various optimization techniques, including increasing virtual warehouse size, but the performance improvement is minimal. Assuming that the 'CUSTOMER ID column is appropriately indexed (or clustered, if applicable) in both tables, and you want to minimise data movement. Which of the following approaches would yield the MOST significant performance improvement for this transformation step, considering metadata caching and data distribution?
Answer: C
Explanation:
Ensuring consistent data types and collations (D) is crucial for optimal join performance in Snowflake. When data types and collations match, Snowflake can leverage its internal optimizations more effectively, including metadata caching and efficient data access patterns. Using a 'BROADCAST JOIN' hint without considering data distribution (A) might lead to unnecessary data movement and performance degradation. 'MAP JOIN' is unavailable in Snowflake (B). Redistributing data using 'DISTRIBUTION_TYPE = HASH' (C) is generally less efficient than leveraging Snowflake's automatic optimizations. Pre-sorting data (E) is unnecessary in Snowflake as it does not guarantee data colocation in the same way that other distributed systems might.
NEW QUESTION # 45
......
For candidates who will attend an exam, some practice for it is necessary. DAA-C01 Exam Dumps of us will give you the practice you need. DAA-C01 exam dumps of us contain the knowledge point of the exam. Skilled professionals will verify the questions and answers, which will guarantee the correctness. Besides, we also offer you free update for one year after purchasing, and the update version will send to your email address automatically.
Latest DAA-C01 Test Labs: https://www.dumps4pdf.com/DAA-C01-valid-braindumps.html
What's more, part of that Dumps4PDF DAA-C01 dumps now are free: https://drive.google.com/open?id=1lsfcSJG2ZyVfZkzTrEXy8-PHc4xYk3jq