BTW, DOWNLOAD part of Exams-boost Databricks-Certified-Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1tBd1eMfmB7qv-fhuvK9g81B7EdEbfeeT
Our Databricks-Certified-Data-Engineer-Associate practice questions attract users from all over the world because they really have their own charm. No product like our Databricks-Certified-Data-Engineer-Associate study guide will seriously consider the needs of users in all aspects. From product content to system settings, we will give you what you want! Firstly, you definitely want to pass the exam for sure. Our Databricks-Certified-Data-Engineer-Associate Exam Questions are high-effective with a high pass rate as 98% to 100%. So don't hesitate, just come and buy our Databricks-Certified-Data-Engineer-Associate learning braindumps!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Governance & Quality | 11% | - Unity Catalog implementation
|
| Topic 2: Development and Ingestion | 30% | - Notebook development fundamentals
|
| Topic 3: Productionizing Data Pipelines | 18% | - Deployment and CI/CD
|
| Topic 4: Data Processing & Transformations | 31% | - Query optimization and performance
|
| Topic 5: Databricks Intelligence Platform | 10% | - Platform architecture and core concepts
|
>> Databricks-Certified-Data-Engineer-Associate Reliable Test Tutorial <<
Our online version of Databricks-Certified-Data-Engineer-Associate learning guide does not restrict the use of the device. You can use the computer or you can use the mobile phone. You can choose the device you feel convenient at any time. Once you have used our Databricks-Certified-Data-Engineer-Associate exam training in a network environment, you no longer need an internet connection the next time you use it, and you can choose to use Databricks-Certified-Data-Engineer-Associate Exam Training at your own right. Our Databricks-Certified-Data-Engineer-Associate exam training do not limit the equipment, do not worry about the network, this will reduce you many learning obstacles, as long as you want to use Databricks-Certified-Data-Engineer-Associate test guide, you can enter the learning state.
NEW QUESTION # 12
Which of the following describes a benefit of creating an external table from Parquet rather than CSV when using a CREATE TABLE AS SELECT statement?
Answer: A
Explanation:
Option C is the correct answer because Parquet files have a well-defined schema that is embedded within the data itself. This means that the data types and column names of the Parquet files are automatically detected and preserved when creating an external table from them. This also enables the use of SQL and other structured query languages to access and analyze the data. CSV files, on the other hand, do not have a schema embedded in them, and require specifying the schema explicitly or inferring it from the data when creating an external table from them. This can lead to errors or inconsistencies in the data types and column names, and also increase the processing time and complexity.
References: CREATE TABLE AS SELECT, Parquet Files, CSV Files, Parquet vs. CSV
NEW QUESTION # 13
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.
The cade block used by the data engineer is below: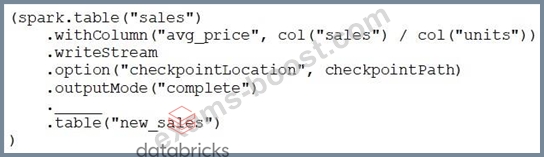
If the data engineer only wants the query to execute a micro-batch to process data every 5 seconds, which of the following lines of code should the data engineer use to fill in the blank?
Answer: E
Explanation:
The processingTime option specifies a time-based trigger interval for fixed interval micro-batches. This means that the query will execute a micro-batch to process data every 5 seconds, regardless of how much data is available. This option is suitable for near-real time processing workloads that require low latency and consistent processing frequency. The other options are either invalid syntax (A, C), default behavior (B), or experimental feature (E). References: Databricks Documentation - Configure Structured Streaming trigger intervals, Databricks Documentation - Trigger.
NEW QUESTION # 14
A data engineer has created a new database using the following command:
CREATE DATABASE IF NOT EXISTS customer360;
In which of the following locations will the customer360 database be located?
Answer: B
Explanation:
dbfs:/user/hive/warehouse Thereby showing "dbfs:/user/hive/warehouse/customer360.db The location of the customer360 database depends on the value of the spark.sql.warehouse.dir configuration property, which specifies the default location for managed databases and tables. If the property is not set, the default value is dbfs:/user/hive/warehouse. Therefore, the customer360 database will be located in dbfs:/user/hive/warehouse/customer360.db. However, if the property is set to a different value, such as dbfs:/user/hive/database, then the customer360 database will be located in dbfs:/user/hive/database/customer360.db. Thus, more information is needed to determine the correct response.
Option A is not correct, as dbfs:/user/hive/database/customer360 is not the default location for managed databases and tables, unless the spark.sql.warehouse.dir property is explicitly set to dbfs:/user/hive/database.
Option B is not correct, as dbfs:/user/hive/warehouse is the default location for the root directory of managed databases and tables, not for a specific database. The database name should be appended with .db to the directory path, such as dbfs:/user/hive/warehouse/customer360.db.
Option C is not correct, as dbfs:/user/hive/customer360 is not a valid location for a managed database, as it does not follow the directory structure specified by the spark.sql.warehouse.dir property.
References:
* Databases and Tables
* [Databricks Data Engineer Professional Exam Guide]
NEW QUESTION # 15
A data engineer has realized that they made a mistake when making a daily update to a table. They need to use Delta time travel to restore the table to a version that is 3 days old. However, when the data engineer attempts to time travel to the older version, they are unable to restore the data because the data files have been deleted.
Which of the following explains why the data files are no longer present?
Answer: B
Explanation:
Explanation
The VACUUM command in Delta Lake is used to clean up and remove unnecessary data files that are no longer needed for time travel or query purposes. When you run VACUUMwith certain retention settings, it can delete older data files, which might include versions of data that are older than the specified retention period. If the data engineer is unable to restore the table to a version that is 3 days old because the data files have been deleted, it's likely because the VACUUM command was run on the table, removing the older data files as part of data cleanup.
NEW QUESTION # 16
A data engineer has been using a Databricks SQL dashboard to monitor the cleanliness of the input data to a data analytics dashboard for a retail use case. The job has a Databricks SQL query that returns the number of store-level records where sales is equal to zero. The data engineer wants their entire team to be notified via a messaging webhook whenever this value is greater than 0.
Which of the following approaches can the data engineer use to notify their entire team via a messaging webhook whenever the number of stores with $0 in sales is greater than zero?
Answer: C
Explanation:
A webhook alert destination is a notification destination that allows Databricks to send HTTP POST requests to a third-party endpoint when an alert is triggered. This enables the data engineer to integrate Databricks alerts with their preferred messaging or collaboration platform, such as Slack, Microsoft Teams, or PagerDuty. To set up a webhook alert destination, the data engineer needs to create and configure a webhook connector in their messaging platform, and then add the webhook URL to the Databricks notification destination. After that, the data engineer can create an alert for their Databricks SQL query, and select the webhook alert destination as the notification destination. The alert can be configured with a custom condition, such as when the number of stores with $0 in sales is greater than zero, and a custom message template, such as "Alert: {number_of_stores} stores have $0 in sales". The alert can also be configured with a recurrence interval, such as every hour, to check the query result periodically. When the alert condition is met, the data engineer and their team will receive a notification via the messaging webhook, with the custom message and a link to the Databricks SQL query. The other options are either not suitable for sending notifications via a messaging webhook (A, B, E), or not suitable for sending recurring notifications . References: Databricks Documentation - Manage notification destinations, Databricks Documentation - Create alerts for Databricks SQL queries, Databricks Documentation - Configure alert conditions and messages.
NEW QUESTION # 17
......
In fact, on one side, our Databricks-Certified-Data-Engineer-Associate training braidumps can help you pass the exam and win the certification. On the othe side, i think it is even more important, that you can apply what you have learned on our Databricks-Certified-Data-Engineer-Associate Practice Guide into practices. Your speed of finishing the task will be greatly elevated. Everting will take positive changes because of our Databricks-Certified-Data-Engineer-Associate exam materials. Please cheer up for yourself.
Databricks-Certified-Data-Engineer-Associate Latest Braindumps Ebook: https://www.exams-boost.com/Databricks-Certified-Data-Engineer-Associate-valid-materials.html
BONUS!!! Download part of Exams-boost Databricks-Certified-Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1tBd1eMfmB7qv-fhuvK9g81B7EdEbfeeT